
Split to Be Slim: An Overlooked Redundancy in Vanilla Convolution
Proceedings of the Twenty-Ninth International Joint Conference on Artificial Intelligence. Main track. Pages 3195-3201.
https://doi.org/10.24963/ijcai.2020/442
Keywords
- Machine Learning: Feature Selection; Learning Sparse Models
- Machine Learning: Deep Learning: Convolutional networks
Abstract
Many effective solutions have been proposed to reduce the redundancy of models for inference acceleration. Nevertheless, common approaches mostly focus on eliminating less important filters or constructing efficient operations, while ignoring the pattern redundancy in feature maps. We reveal that many feature maps within a layer share similar but not identical patterns. However, it is difficult to identify if features with similar patterns are redundant or contain essential details. Therefore, instead of directly removing uncertain redundant features, we propose a split based convolutional operation, namely SPConv, to tolerate features with similar patterns but require less computation. Specifically, we split input feature maps into the representative part and the uncertain redundant part, where intrinsic information is extracted from the representative part through relatively heavy computation while tiny hidden details in the uncertain redundant part are processed with some light-weight operation. To recalibrate and fuse these two groups of processed features, we propose a parameters-free feature fusion module. Moreover, our SPConv is formulated to replace the vanilla convolution in a plug-and-play way. Without any bells and whistles, experimental results on benchmarks demonstrate SPConv-equipped networks consistently outperform state-of-the-art baselines in both accuracy and inference time on GPU, with FLOPs and parameters dropped sharply.
- [Chen et al., 2019a] Kai Chen, Jiaqi Wang, et al. Mmde- tection: Open mmlab detection toolbox and benchmark. CoRR, abs/1906.07155, 2019.
- [Chen et al., 2019b] Yunpeng Chen, Haoqi Fan, et al. Drop an octave: Reducing spatial redundancy in convolutional neural networks with octave convolution. In ICCV, 2019.
- [Chollet, 2017] Franc ¸ois Chollet. Xception: Deep learning with depthwise separable convolutions. In CVPR, 2017.
- [Deng et al., 2009] Jia Deng, Wei Dong, Richard Socher, Li- Jia Li, Kai Li, and Fei-Fei Li. Imagenet: A large-scale hierarchical image database. In CVPR, 2009.
- [Devlin et al., 2019] Jacob Devlin, Ming-Wei Chang, Ken- ton Lee, and Kristina Toutanova. BERT: pre-training of deep bidirectional transformers for language understand- ing. In NAACL-HLT, 2019.
- [Gao et al., 2019] Xitong Gao, Yiren Zhao, Lukasz Dudziak, Robert D. Mullins, and Cheng-Zhong Xu. Dynamic chan- nel pruning: Feature boosting and suppression. In ICLR, 2019.
- [Gao et al., 2020] Shang-Hua Gao, Ming-Ming Cheng, Kai Zhao, Xin-Yu Zhang, Ming-Hsuan Yang, and Philip Torr. Res2net: A new multi-scale backbone architecture. IEEE TPAMI, 2020.
- [Han et al., 2020] Kai Han, Yunhe Wang, Qi Tian, Jianyuan Guo, Chunjing Xu, and Chang Xu. Ghostnet: More fea- tures from cheap operations. In CVPR, 2020.
- [He et al., 2016] Kaiming He, Xiangyu Zhang, Shaoqing Ren, and Jian Sun. Deep residual learning for image recog- nition. In CVPR, 2016.
- [He et al., 2017] Kaiming He, Georgia Gkioxari, Piotr Dollár, and Ross B. Girshick. Mask R-CNN. In ICCV, 2017.
- [Howard et al., 2017] Andrew G Howard, Menglong Zhu, et al. Mobilenets: Efficient convolutional neural net- works for mobile vision applications. arXiv preprint arXiv:1704.04861, 2017.
- [Huang et al., 2017] Gao Huang, Zhuang Liu, Laurens Van Der Maaten, and Kilian Q Weinberger. Densely connected convolutional networks. In CVPR, 2017.
- [Ioffe and Szegedy, 2015] Sergey Ioffe and Christian Szegedy. Batch normalization: Accelerating deep net- work training by reducing internal covariate shift. In ICML, 2015.
- [Krizhevsky et al., 2009] Alex Krizhevsky, Geoffrey Hinton, et al. Learning multiple layers of features from tiny im- ages. Technical report, Citeseer, 2009.
- [Krizhevsky et al., 2012] Alex Krizhevsky, Ilya Sutskever, and Geoffrey E Hinton. Imagenet classification with deep convolutional neural networks. In NeurIPS, 2012.
- [LeCun et al., 1990] Yann LeCun, John S Denker, and Sara A Solla. Optimal brain damage. In NeurIPS, 1990.
- [Li et al., 2019] Xiang Li, Wenhai Wang, Xiaolin Hu, and Jian Yang. Selective kernel networks. In (CVPR), 2019.
- [Lin et al., 2014a] Min Lin, Qiang Chen, and Shuicheng Yan. Network in network. In ICLR, 2014.
- [Lin et al., 2014b] Tsung-Yi Lin, Michael Maire, Serge J. Belongie, James Hays, Pietro Perona, Deva Ramanan, Pi- otr Dollár, and C. Lawrence Zitnick. Microsoft coco: Common objects in context. In ECCV. Springer, 2014.
- [Lin et al., 2017a] Tsung-Yi Lin, Piotr Dollár, Ross Gir- shick, Kaiming He, Bharath Hariharan, and Serge Be- longie. Feature pyramid networks for object detection. In CVPR, 2017.
- [Lin et al., 2017b] Tsung-Yi Lin, Priya Goyal, Ross Gir- shick, Kaiming He, and Piotr Dollár. Focal loss for dense object detection. In ICCV, 2017.
- [Micikevicius et al., 2018] Paulius Micikevicius, Sharan Narang, Jonah Alben, Gregory F. Diamos, Erich Elsen, David García, Boris Ginsburg, Michael Houston, Oleksii Kuchaiev, Ganesh Venkatesh, and Hao Wu. Mixed precision training. In ICLR, 2018.
- [Simonyan and Zisserman, 2015] Karen Simonyan and An- drew Zisserman. Very deep convolutional networks for large-scale image recognition. In ICLR, 2015.
- [Singh et al., 2019] Pravendra Singh, Vinay Kumar Verma, Piyush Rai, and Vinay P Namboodiri. Hetconv: Heteroge- neous kernel-based convolutions for deep cnns. In CVPR, 2019.
- [Szegedy et al., 2015] Christian Szegedy, Wei Liu, Yangqing Jia, Pierre Sermanet, Scott E. Reed, Dragomir Anguelov, Dumitru Erhan, Vincent Vanhoucke, and Andrew Rabi- novich. Going deeper with convolutions. In CVPR, 2015.
- [Vanhoucke, 2014] Vincent Vanhoucke. Learning visual rep- resentations at scale. ICLR invited talk, 1, 2014.
- [Xie et al., 2017] Saining Xie, Ross Girshick, Piotr Dollár, Zhuowen Tu, and Kaiming He. Aggregated residual trans- formations for deep neural networks. In CVPR, 2017.
- [Zhang et al., 2017] Ting Zhang, Guo-Jun Qi, Bin Xiao, and Jingdong Wang. Interleaved group convolutions. In ICCV, 2017.
- [Zhang et al., 2018] Xiangyu Zhang, Xinyu Zhou, Mengx- iao Lin, and Jian Sun. Shufflenet: An extremely effi- cient convolutional neural network for mobile devices. In CVPR, 2018.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
The recent years have seen the remarkable success of deep neural networks. However, this booming accuracy comes at the cost of increasingly complex models, which contain millions of parameters and billions of FLOPs [He et al., 2016; Devlin et al., 2019]. Therefore, recent efforts try to reduce parameters and FLOPs while ensuring the model without a significant performance drop.
∗Corresponding author.
One main effort is to design an efficient convolutional operation. The popular trend recently tends to make full use of group-wise convolution (GWC) [Krizhevsky et al., 2012], depth-wise convolution (DWC) [Vanhoucke, 2014] and point-wise convolution (PWC) [Szegedy et al., 2015]. Many effective and efficient models have been produced by combining these three schemes carefully, such as MobileNet [Howard et al., 2017], Xception [Chollet, 2017], ResNeXt [Xie et al., 2017] and ShuffleNet [Zhang et al., 2018]. The idea behind these famous nets illustrates that redundancy in inter-channel connectivity can be reduced reasonably, or to say, the effect of dense vanilla convolutional kernels can be achieved with combinations of some sparse ones.
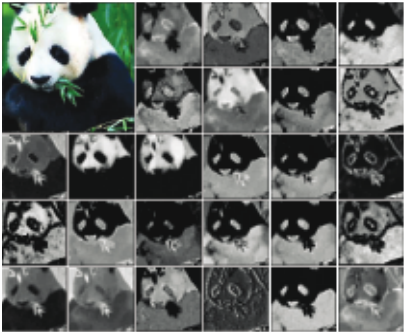
Different from the pipelines reviewed above, we take a step back and look at inputs. Visualization of the second stage's inputs of ResNet-50 is shown in Figure 1. We notice that some feature maps appear much pattern similarity. A natural thought to this phenomenon is that many feature maps are redundant and they can be deleted so that fewer filters are needed for feature extraction during training. However, it is difficult to identify how many channels are economically enough in each layer for different tasks and datasets. The widely used stereotype of 64-128-256-512-1024 channels in each layer/stage, also what we inherit for granted from classic architectures [He et al., 2016], gives a compromised answer: to be redundant rather than to be in shortage for better performance on most of the datasets. This stereotype implies it is very tough to obtain the exact number of channels. Therefore, instead of struggling with such an obstacle, we incline to tolerate the redundancy among feature maps and treat them with a more elegant method. Back to Figure 1, some of the feature maps appear very similar, which indicates the information they carry is also similar. However, in vanilla convolution, similar feature maps are convolved repetitively by different k × k × 1 kernels. Intuitively, if one model has extracted information from one feature map, it will only need to extract the difference from its similar ones.
Inspired by the idea above, in this paper, we propose a novel SPConv module to reduce the redundancy in vanilla convolution. Specifically, we split all input channels into two parts: one for the representative and the other for the redundant. Intrinsic information can be extracted from the representative part by normal k ×k kernels. Complementarily, the hidden tiny difference can be collected from the redundant part by cheap 1×1 kernels. Then we fuse these two categories of extracted information accordingly to ensure no details get lost in a parameter-free way. Moreover, we design our SPConv in a generic way and make it a plug-and-play replacement for the vanilla convolution without any other adjustment to network architectures or hyper-parameter settings. Since our SPConv tolerates the redundancy among feature maps, it is orthogonal and complementary to current methods that focus on building better CNN topology [Huang et al., 2017; Szegedy et al., 2015; Gao et al., 2020], reducing redundancy on channel [Xie et al., 2017; Howard et al., 2017] or spatial dimension [Chen et al., 2019b] and reducing redundancy in dense model parameters [Gao et al., 2019]. We can aggregate some of them reasonably to get a more lightweight model.
To the best of our knowledge, this is the first convolution/filter that adopts k × k kernels only on part of the input channels. All existing methods before, including HetConv [Singh et al., 2019] and OctConv [Chen et al., 2019b], perform expensive k × k kernels on all input channels. Without any bells and whistles, experiments on current benchmarks demonstrate that in such a novel way, not only does our SPConv reduce the redundancy in vanilla convolutional operations, but also loses little useful information. Experimental SPConv-equipped architectures consistently outperform the state-of-the-art baselines in both accuracy and GPU inference time with nearly 60%-70% of the parameters and FLOPs dropped at most, which is superior to current works that are either (much) slower on GPU or less accurate, though they have pretty good parameters and FLOPs.
In conclusion, we make the following contributions:
- We reveal an overlooked redundancy in vanilla convolution and propose to split all input channels into two parts: one for the representative contributing intrinsic information and the other for the redundant complementing different details.
- We design a plug-and-play SPConv module to replace the vanilla convolution without any adjustment, which actually outperforms state-of-the-art baselines in both accuracy and inference time with parameters and FLOPs dropped sharply.
2 RelatedWork
2.1 Efficient and Compact Model Design
There has been raising interest for researchers to create compact while accurate models since LeCun in 1990 [LeCun et al., 1990]. Inception [Szegedy et al., 2015] adopts splittransform-merge strategies and achieves low theoretical complexity with compelling accuracy. Meanwhile, some novel convolutional filters like Group-wise Convolution (GWC) [Krizhevsky et al., 2012], Depth-wise Convolution (DWC) [Vanhoucke, 2014] and Point-wise Convolution (PWC) [Lin et al., 2014a; He et al., 2016] are widely used for efficient model design. Evolved from Inception, ResNeXt [Xie et al., 2017] shares the same topology in all aggregated transformations with GWC and PWC, which reduces redundancy in inter-channel connectivity and introduces a new dimension called cardinality. To reduce connection density further, Xception [Chollet, 2017] and MobileNet [Howard et al., 2017] use DWC for spatial information extraction and PWC for channel information fusion successively. More thoroughly, ShuffleNet [Zhang et al., 2018] adopts GWC on 1x1 convolutions followed by channel shuffle operation in addition to DWC on 3x3 convolutions.
Orthogonal to channel redundancy, OctConv [Chen et al., 2019b] explores redundancy on the spatial dimension of feature maps. Except for homogeneous convolution, HetConv [Singh et al., 2019] designs heterogeneous convolutional filters where exist both 3 × 3 kernels and 1 × 1 kernels in one single filter. Then these two heterogeneous kernels in filters of a particular layer are arranged in a shifted manner. With attention models being effective, SKNet [Li et al., 2019] introduces a dynamic kernel selection mechanism based on multiple scales of input information and achieves adaptive receptive field. The common part of these efficient models above, including OctConv [Chen et al., 2019b], HetConv [Singh et al., 2019] and SKNet [Li et al., 2019], is that they apply 3×3 kernels to all input channels. However, as shown in Figure 1, many features maps appear much pattern similarity, which reveals vanilla convolutions are basically repetitive. Therefore, we propose SPConv module to alleviate this redundancy. With the idea similar to us, GhostNet [Han et al., 2020] also points out redundancy among feature maps. It uses ordinary convolution to generate some intrinsic features first, then utilizes cheap linear operation to do feature augmentation. Different from [Han et al., 2020], our SPConv ensures the model grasp every original feature, instead of features generated by the intrinsic, so that we achieve better performance.
As for inference time on GPU, nearly all efficient models above are (much) slower than baseline. Superior to them, our SPConv achieves faster inference speed than baseline.
3 Approach
In this section, we first introduce our proposed SPConv for cutting down the redundancy between feature maps, then we analyze this module in detail.
3.1 Vanilla Convolution
Let X ∈ RL×h×w , Y ∈ RM×h×w denote the input and convolved output tensors with L input channels and M output channels respectively. In general, square k ×k convolutional kernels, denoted by W ∈ RL×k×k×M , are used to convolve L input channels into M output channels for feature extraction, resulting Y = WX + b. To simplify the notation, we omit the bias term and present the discussion over a single spatial position, say k × k area that a square kernel covers. The formulation for the complete h × w feature map can be obtained easily in the same way. So a vanilla convolution can be given as equation 1:
where xi, i ∈ [1,L] is one of the L input matrixes, and Wij, i, j ∈ [1; L,M] is one of the parameters of M filters, both of which are (k × k) - dimensional. After convolution, we get M convolved outputs, denoted by yj , j ∈ [1, M].
3.2 The Representative and the Redundant
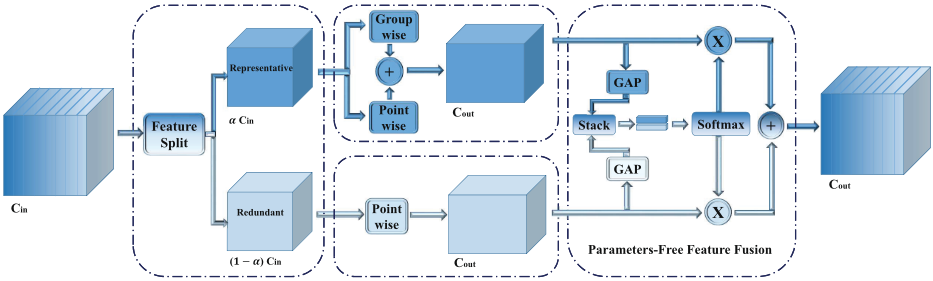
All existing filters, such as vanilla convolution, GhostConv [Han et al., 2020], OctConv [Chen et al., 2019b] and HetConv [Singh et al., 2019], perform k × k convolution on all input channels. However, as shown in Figure 1, there is intuitive pattern similarity among intermediate feature maps so that some k×k convolutions are relatively redundant. Meanwhile, there are also no two identical channels so that we can not throw away these redundant channels neither. Inspired by this idea, our SPConv splits all input channels into two main parts in a ratio of α, one for the representative applying k×k (here we adopt widely used 3 × 3) convolution to supply intrinsic information; the other for the redundant applying cheap 1×1 convolution to complement tiny hidden details as shown in the left part of Figure 2. So our initial SPConv can be given as equation 2:
where Wi,j , j ∈ [1, αL] represents parameters of 3 × 3 kernels convolving on the αL representative channels. wi,j , j ∈ [αL+1, L] stands for parameters of cheap 1×1 kernels performing on the remaining (1 - α)L redundant features with pointwise convolution. HetConv [Singh et al., 2019] also adopts this heterogeneous operation similar to us, while we share every filter with the same heterogeneous distribution instead of a shifted manner,whose fragmented kernels make computation more difficult on current hardware, so that we can achieve faster inference speed.
3.3 Further Reduction for the Representative
After splitting all input channels into two main parts, there might be redundancy among the representative part. In other words, representative channels can be divided into several parts and each part stands for one main category of features, e.g., color and textures. Thus we adopt group convolution on the representative channels to reduce redundancy further as shown in the middle part of Figure 2. We can view a group convolution as a vanilla convolution with a sparse blockdiagonal convolutional kernel, where each block corresponds to a partition of channels and there are no connections across the partitions [Zhang et al., 2017]. That means, after group convolution, we reduce redundancy among the representative part further while we also cut off the connection across channels which might be useful inevitably. We remedy this information loss by adding pointwise convolution across all representative channels. Different from the commonly used group convolution followed by pointwise convolution, we conduct both GWC and PWC on the same representative channels. Then we fuse the two resulted features by direct summation because of their same channel origin, which obtains an extra score (here we set group size as 2). So the representative part of the equation 2 can be formulated as equation 3:
Here we divide the αcL representative channels into G groups and each group zl contains (αcL/G) channels. W p ll are parameters of group convolutional kernel in the lth group.
3.4 Parameter-Free Feature FusionModule
So far, we have splitted the vanilla 3 × 3 convolution into two operations: for the representative part, we conduct direct summation fusion of 3×3 group convolution and 1×1 pointwise convolutions to countervail grouped information loss; for the redundant part, we apply 1×1 kernels to complement some tiny useful details. As a result, we get two categories of features. Because these two features originate from different input channels, a fusion method is needed to control information flow. Different from direct summation fusion as equation 2, we design a novel feature fusion module for our SPConv, without extra parameters imported and being helpful to achieve better performance. As shown in the right part of Figure 2, we use global average pooling to generate channel-wise statistics S1, S3 ∈ RC for global information embedding. By shrinking output features U through its spatial dimension, the c-th element of S can be given as equation 4:
Then we stack these two resulted S3, S1 vectors together followed by soft attention operation across channels to generate feature importance vector β ∈ Rc , γ ∈ Rc , the c-th element of which are given as follows:
Our final output Y can be obtained by fusing features U3 and U1, which are from the representative and the redundant part respectively, directed by the feature importance vector β, γ in a channel-wise manner.
In summary, the vanilla convolution Y =WX (bias term omitted) can be approximated by Y = W ′X as equation 7:
where uppercase W represents 3×3 kernels and lowercase w represents 1×1 kernels. By replacing vanilla weights W with the proposed SPConv weights W ′ , classic network architectures can obtain better performance in both accuracy and inference time on GPU with FLOPs and parameters dropped sharply as shown in section 4. Module decomposition tests of our SPConv are conducted in section 4.4.
3.5 Complexity Analysis
From equation 1, the parameters of vanilla convolution can be calculated as:
From equation 7, our SPConv has parameters of:
When we choose half of the input channels as the representative, divide the representative part into 2 groups and adopt the widely used 3x3 kernels, the amount of parameters can be reduced by 2.8 times while the model actually achieves a little better performance than vanilla convolution in both accuracy and inference speed.
4 Experiment
To show the effectiveness of the proposed SPConv, in this section, we conduct experiments with only the widely-used 3 × 3 kernels being replaced by our SPConv modules. The upgraded networks have only one global hyper-parameter α, denoting the ratio of the representative features among all input features. Although different layers/stages might require different number of representative features, we use the same α for all layers in the experiments. Carefully designing different α for different layers would find a more compact model. Meanwhile, we set group size for the representative part as 2.
Firstly, we perform small scale image classification experiments on the CIFAR-10 dataset [Krizhevsky et al., 2009] with ResNet-20 [He et al., 2016] and VGG-16 [Simonyan and Zisserman, 2015] architectures. Then we experiment a large scale 1000-class single label classification task on ImageNet-2012 [Deng et al., 2009] with ResNet-50 [He et al., 2016] architecture. To explore SPConv's generality further, we also conduct a multi-label object detection experiment on MS COCO dataset [Lin et al., 2014b]. For fair comparisons, all models in each experiment, including reimplemented baselines and SPConv-equipped models, are trained from scratch on 4 NVIDIA Tesla V100 GPUs with the default data augmentation and training strategy which are optimized for vanilla convolution and no other tricks are used. Therefore, our proposed SPConv may achieve better performance with extensive hyper-parameter searches. More ablation studies are performed on small scale CIFAR-10 dataset.
4.1 Small Scale Classfication Task VGG-16 on CIFAR-10
As we know, VGG-16 [Simonyan and Zisserman, 2015] is originally designed for 1000-label ImageNet with 13 conv layers and 3 fully-connected layers. For 10-label CIFAR, we choose its widely used variant: VGG-15 with 2 fullyconnected layers and batch normalization [Ioffe and Szegedy, 2015] equipped after each layer. Same as [Singh et al., 2019], we only replace the last 12 3 × 3 conv layers with our proposed SPConvs except the initial 3×3 conv layer and keep all other configurations unchanged. Optimization is performed using SGD with weight decay = 5e-4, batch-size = 128, initial learning rate = 0.1 which is divided by 10 every 50 epochs.
As shown in Table 1, when we set the split ratio α from 1 to 1/16 gradually, the FLOPs and parameters decrease sharply without any significant accuracy decrease. Without any bells and whistles, our proposed SPConv does a better job with only 33% of FLOPs and parameters when the split ratio is set as 1/2. That is, although fewer input channels are used for intrinsic information extraction, the model is still robust enough. That also means some input channels, or feature maps, of a conv layer are redundant and have no need to be counted into computation by expensive 3×3 kernels. Compared to related works [Singh et al., 2019; Han et al., 2020] on VGG-16, our SPConv outperforms Ghost-Conv and HetConv. We argue that, for a specific task or dataset, representative and intrinsic features count the most, while other redundant or similar features can be saved using cheap 1 × 1 kernels to complement tiny different details. To challenge more, we perform experiments on the much more compact ResNet-20 [He et al., 2016].
| CIFAR 10 - ResNet 20 | |||||
|---|---|---|---|---|---|
| Model | FLOPs | FLOPs Reduced | Params | Params Reduced | ACC@1 |
| ResNet 20-Baseline | 41.62M | - | 0.27M | - | 92% |
| SPConv-ResNet 20-α1/2 | 17.91M | 56.96% | 0.10M | 63.00% | 92.23% |
| SPConv-ResNet 20-α1/4 | 12.89M | 75.88% | 0.071M | 73.70% | 91.15% |
| CIFAR 10 - VGG 16 | |||||
| VGG 16-Baseline | 349.51M | - | 16.62M | - | 94.00% |
| Ghost-VGG 16-s2 | 158M | 45.20% | 7.7M | 53.67% | 93.70% |
| SPConv-VGG 16-α1/2 | 118.27M | 66.24% | 5.6M | 66.30% | 94.40% |
| HetConv-VGG 16-P4 | 105.98M | 69.67% | 5.17M | 68.89% | 93.92% |
| SPConv-VGG 16-α1/4 | 79.34M | 77.29% | 3.77M | 77.31% | 93.94% |
| HetConv-VGG 16-P8 | 76.89M | 78.00% | 3.54M | 78.70% | 93.86% |
| SPConv-VGG 16-α1/8 | 59.87M | 82.87% | 2.85M | 82.85% | 93.77% |
| SPConv-VGG 16-α1/16 | 55.14M | 84.22% | 2.39M | 85.62% | 93.43% |
ResNet-20 on CIFAR-10
ResNet-20 is composed of three stages of convolutional layers with each stage containing 16-32-64 filters respectively, whose features are much fewer than 64-128-256-512's VGG16. ResNet-20 contains only 0.27M parameters, about 1.6% of VGG-16, while it performs only 2% less accurate. It would be much more challenging for our SPConv to slim such a compact architecture. As settings the same as VGG-16 above, we replace all the 3×3 vanilla conv layers with our proposed SPConvs except the initial one, adopt default training strategy as [He et al., 2016] and re-implement faithfully. The results are shown in Table 1.
From Table 1, we can see the proposed SPConv slims such a compact ResNet-20 successfully and the performance is almost the same as with VGG-16 before. When we take the first half of channels (8-16-32 in each stage) for intrinsic information extraction and complement tiny different details with the remaining half of channels using 1×1 kernels, the FLOPs and the parameters drops about 60% while the slimmed model still performs a little better than the original one. To go slimmer, we set the split ratio as 1/4, which means, except the initial conv layer, only 4 channels in the first stage, 8 channels in the second stage and 16 channels in the third stage are used to extract intrinsic information. The results show that our slimmer model performs only 0.75% worse than the baseline, which is as expected. Because under such a severe condition, 3×3 kernels have not enough power to count more intrinsic features in and 1 × 1 kernels have poor ability to extract more information so that there are not enough representative and intrinsic features which are important for the model to classify the dataset correctly. To be more convincing, we also conduct large scale experiments on ImageNet with ResNet-50.
4.2 Large Scale Experiments on ImageNet
We conduct large scale experiments with ResNet-50 [He et al., 2016] on the most authoritative ImageNet. As before, we replace standard 3 × 3 kernels with the proposed SPConv except for the first 7x7 conv layer and keep all other parts unchanged. Due to limited GPU resource and training time expense, we choose NVIDIA DALI 1 project as our baseline to reimplement ResNet-50 faithfully. DALI differs in pre-processing image data on GPU for data loading acceleration and using apex [Micikevicius et al., 2018] for mixedprecision fp16/fp32 to speed up training without significant accuracy drop. With the default settings, the learning rate starts at 0.1 and decays by a factor of 10 every 30 epochs, using synchronous SGD with weight decay 1e-4, momentum 0.9 and a mini-batch of 256 to train the model from scratch for 90 epochs.
From Table 2, we can see our SPConv still performs 0.27% better than baseline when we set the split ratio as 1/2 and performs almost the same when α is set as 1/4 with FLOPs reduced about 28% and 34% separately in such a huge dataset. The reason why drop ratios of params and FLOPs there is not as high as VGG-16 or ResNet-20 above is attributed to unreplaced initial 7x7 Conv and more fully-connected-layer parameters. When we decrease α to 1/8 continuously, FLOPs and parameters drop by about 37% and the Top1-Acc is about 0.6% less accurate, which means 8-16-32-64 representative and intrinsic features in each stage have been in shortage for ResNet-50 to classify such a huge ImageNet correctly.
Inference time is tested on a single NVIDIA Tesla V100 with NVIDIA DALI as data pipelines. Batch size is set as 64. For current efficient convolution designs, though they have fewer parameters and FLOPs, most of them are at the expense of (much) lower inference speed on GPU or a little worse accuracy than baselines. Superior to them, our SPConv outperforms the baseline in both inference time and accuracy. For fair comparisons, we reimplement OctConv with standard training strategy as [He et al., 2016] and no other tricks in [Chen et al., 2019b] are used. Although the results show that Octave performs a little better than our SPConv in accuracy with fewer FLOPs, Octave requires as many parameters as the baseline. For inference time, our SPConv outperforms OctConv sharply on GPU.
4.3 Object Detection onMS COCO
To evaluate our SPConv's generalizability further, we test our SPConv on the object detection task of MS COCO [Lin et al., 2014b], using two-stage Faster R-CNN[15] and one-stage RetinaNet [Lin et al., 2017b] framework respectively with ResNet-50-FPN [He et al., 2016; Lin et al., 2017a] backbone as baseline. For fair comparisons, experiments are implemented on mmdection [Chen et al., 2019a] where we keep all other settings default except replacing vanilla 3 × 3 conv layers with our proposed SPConv (α= 12 , g=2) in ResNet-50 backbone and use pre-trained backbone parameters in section 4.3. Similar to [He et al., 2017], models are trained on the COCO trainval35k set and tested on the left 5K minival set.
1 https://github.com/NVIDIA/DALI
| ImageNet2012-ResNet50 | |||||||
| Model | FLOPs | FLOPs Reduced | Params | Params Reduced | Acc@1 | Acc@5 | Inference Time on GPU |
|---|---|---|---|---|---|---|---|
| ResNet50-Baseline | 4.14G | - | 25.56M | - | 75.91% | 92.78% | 1.32 ms |
| SPConv-ResNet50-α1/2 | 2.97G | 28.26% | 18.34M | 28.24% | 76.26% | 93.05% | 1.23 ms |
| HetConv-ResNet50-P4 | 2.85G | 30.32% | - | - | 76.16% | - | - |
| SPConv-ResNet50-α1/4 | 2.74G | 33.82% | 16.93M | 33.76% | 75.95% | 92.99% | 1.19 ms |
| SPConv-ResNet50-α1/8 | 2.62G | 36.72% | 16.22M | 36.54% | 75.40% | 92.77% | 1.17 ms |
| OctConv-ResNet50-α0.5† | 2.40G | 42.00% | 25.56M | 0.00% | 76.40% | 93.14% | 3.51 ms |
| Ghost-ResNet50-s2 | 2.20G | 46.85% | 13.0M | 49% | 75% | 92.3% | - |
| Object Detection Experiments on MS COCO | ||||||||
|---|---|---|---|---|---|---|---|---|
| Framework | Backbone (ResNet-50) | Backbone Params/FLOPs | - | AP@ IoU=0.5 | Small objects | Medium objects | Large objects | All |
| Faster-R-CNN | Vanilla | 23.51M/4.13G | AP(%) | 58.2 | 21.6 | 39.8 | 46.8 | 36.3 |
| SPConv | 16.29M/2.96G | 58.9 | 21.8 | 40.4 | 46.3 | 36.4 | ||
| Vanilla | 23.51M/4.13G | AR(%) | - | 32.7 | 55.3 | 64.5 | 51.5 | |
| SPConv | 16.29M/2.96G | - | 33.9 | 55.6 | 63.7 | 51.6 | ||
| RetinaNet | Vanilla | 23.51M/4.13G | AP(%) | 55.6 | 19.7 | 39.3 | 47 | 35.6 |
| SPConv | 16.29M/2.96G | 56.4 | 20.6 | 40.4 | 47.5 | 35.9 | ||
| Vanilla | 23.51M/4.13G | AR(%) | - | 32.9 | 56.7 | 66.9 | 52.2 | |
| SPConv | 16.29M/2.96G | - | 33.4 | 56.8 | 68.1 | 52.8 | ||
Table 3 shows the comparisons in mean average precision (mAP) and mean average recall (mAR). Our SPconvequipped Faster R-CNN and RetinaNet outperforms their baseline respectively. SPConv-equipped Faster R-CNN performs a little worse for large object, and we attribute this to our replacement of some expensive 3 × 3 kernels whose receptive field is large with cheap 1×1 kernels whose receptive field is small.
4.4 Ablation Studies
From section 3, our SPConv consists of three main parts, 1) cheap 1 × 1 convolution for the redundant channels, 2) 3 × 3 GWC + PWC for the representative features and 3) parameter-free feature fusion method. In this section, we conduct an ablation study to investigate the relative effectiveness of each part in SPConv. All ablation experiments are conducted with ResNet-20 on CIFAR-10.
Effectiveness of GWC+PWC
We adopt GWC+PWC on the representative features. To evaluate its effectiveness, we experiment with two commonly used methods . The first one is GWC followed by PWC. As show in the second line of Table 4, our GWC+PWC has about 0.4% better accuracy with fewer FLOPs. The second one is vanilla 3 × 3 convolution, which achieves the best accuracy, 0.04% better while demanding 43% more FLOPs.
Parameters-Free Feature Fusion Method
Compared with the proposed feature fusion method, we experiment with direct summation fusion. As show in the fourth line of Table 4, our parameters-free fusion method achieves 0.7% better with only 0.35M more FLOPs.
| ResNet-20 | P1 | P20 | P21 | P22 | P3 | Acc(%) | FLOPs | Params |
| ✓ | ✓ | ✓ | 92.23± 0.1 | 17.91M | 0.10M | |||
| ✓ | ✓ | ✓ | 91.84± 0.2 | 20.38M | 0.12M | |||
| ✓ | ✓ | ✓ | 92.27± 0.1 | 25.70M | 0.15M | |||
| ✓ | ✓ | 91.51± 0.2 | 17.56M | 0.10M | ||||
| ✓ | 89.43± 0.1 | 14.47M | 0.088M |
P20: Use vanilla convolution for the representative;
P21: Use GWC+PWC for the representative;
- P22: Use GWC followed by PWC for the representative;
- P3: Parameter-free feature fusion method instead of direct summation fusion.
Table 4: ablation studies on CIFAR-10 in different setups.
Count the Redundant Channels or Not
We examine our naive thought: delete the redundant channels directly, without feature fusion accordingly. As shown in the last line of Table 4, performance drops about 3%(though fewer parameters), which means redundant features contain useful tiny details and can not be deleted directly.
5 Conclusion
In this work, we revealed an overlooked pattern redundancy in vanilla convolution. To alleviate this problem, we proposed a novel SPConv module to split all input feature maps into the representative part and the uncertain redundant part. Extensive experiments on various datasets and network architectures demonstrated our SPConv's effectiveness. More importantly, it achieves faster inference speed than baseline, which is superior to existing works. Multi-label object detection experiments conducted on MS COCO proved its generality. Since our SPConv is orthogonal and complementary to the current model compression method, careful combinations of them would get a more lightweight model in the future.
@inproceedings{ijcai2020p442,
  title     = {Split to Be Slim: An Overlooked Redundancy in Vanilla Convolution},
  author    = {Zhang, Qiulin and Jiang, Zhuqing and Lu, Qishuo and Han, Jia'nan and Zeng, Zhengxin and Gao, Shanghua and Men, Aidong},
  booktitle = {Proceedings of the Twenty-Ninth International Joint Conference on
               Artificial Intelligence, {IJCAI-20}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Christian Bessiere},
  pages     = {3195--3201},
  year      = {2020},
  month     = {7},
  note      = {Main track},
  doi       = {10.24963/ijcai.2020/442},
  url       = {https://doi.org/10.24963/ijcai.2020/442},
}
TY - CPAPER TI - Split to Be Slim: An Overlooked Redundancy in Vanilla Convolution AU - Zhang, Qiulin AU - Jiang, Zhuqing AU - Lu, Qishuo AU - Han, Jia'nan AU - Zeng, Zhengxin AU - Gao, Shanghua AU - Men, Aidong T2 - Proceedings of the Twenty-Ninth International Joint Conference on Artificial Intelligence, IJCAI-20 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2020 SP - 3195 EP - 3201 DO - 10.24963/ijcai.2020/442 UR - https://doi.org/10.24963/ijcai.2020/442 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





