
TransRHS: A Representation Learning Method for Knowledge Graphs with Relation Hierarchical Structure
Proceedings of the Twenty-Ninth International Joint Conference on Artificial Intelligence. Main track. Pages 2987-2993.
https://doi.org/10.24963/ijcai.2020/413
Keywords
- Natural Language Processing: Embeddings
- Machine Learning: Knowledge-based Learning
Abstract
Representation learning of knowledge graphs aims to project both entities and relations as vectors in a continuous low-dimensional space. Relation Hierarchical Structure (RHS), which is constructed by a generalization relationship named subRelationOf between relations, can improve the overall performance of knowledge representation learning. However, most of the existing methods ignore this critical information, and a straightforward way of considering RHS may have a negative effect on the embeddings and thus reduce the model performance. In this paper, we propose a novel method named TransRHS, which is able to incorporate RHS seamlessly into the embeddings. More specifically, TransRHS encodes each relation as a vector together with a relation-specific sphere in the same space. Our TransRHS employs the relative positions among the vectors and spheres to model the subRelationOf, which embodies the inherent generalization relationships among relations. We evaluate our model on two typical tasks, i.e., link prediction and triple classification. The experimental results show that our TransRHS model significantly outperforms all baselines on both tasks, which verifies that the RHS information is significant to representation learning of knowledge graphs, and TransRHS can effectively and efficiently fuse RHS into knowledge graph embeddings.
- [Auer et al., 2007] Sören Auer, Christian Bizer, Georgi Ko- bilarov, Jens Lehmann, Richard Cyganiak, and Zachary Ives. Dbpedia: A nucleus for a web of open data. In The semantic web, pages 722-735. Springer, 2007.
- [Bollacker et al., 2008] Kurt Bollacker, Colin Evans, Praveen Paritosh, Tim Sturge, and Jamie Taylor. Freebase: a collaboratively created graph database for structuring human knowledge. In Proceedings of the 2008 ACM SIGMOD international conference on Management of data, pages 1247-1250, 2008.
- [Bordes et al., 2013] Antoine Bordes, Nicolas Usunier, Alberto Garcia-Duran, Jason Weston, and Oksana Yakhnenko. Translating embeddings for modeling multi-relational data. In Advances in neural information processing systems, pages 2787-2795, 2013.
- [Carlson et al., 2010] Andrew Carlson, Justin Betteridge, Bryan Kisiel, Burr Settles, Estevam R. Hruschka Jr., and Tom M. Mitchell. Toward an architecture for never-ending language learning. In Proceedings of the Twenty-Fourth Conference on Artificial Intelligence, 2010.
- [Guo et al., 2015] Shu Guo, Quan Wang, Bin Wang, Lihong Wang, and Li Guo. Semantically smooth knowledge graph embedding. In Proceedings of the 53rd Annual Meeting of the Association for Computational Linguistics and the 7th International Joint Conference on Natural Language Processing (Volume 1: Long Papers), pages 84-94, 2015.
- [Han et al., 2018] Xu Han, Shulin Cao, Lv Xin, Yankai Lin, Zhiyuan Liu, Maosong Sun, and Juanzi Li. Openke: An open toolkit for knowledge embedding. In Proceedings of EMNLP, 2018.
- [Hayes and Patel-Schneider, 2014] Patrick J Hayes and Pe- ter F Patel-Schneider. Rdf 1.1 semantics. W3C recommen- dation, 25:7-13, 2014.
- [Ji et al., 2015] Guoliang Ji, Shizhu He, Liheng Xu, Kang Liu, and Jun Zhao. Knowledge graph embedding via dy- namic mapping matrix. In Proceedings of the 53rd Annual Meeting of the Association for Computational Linguis- tics and the 7th International Joint Conference on Natu- ral Language Processing (Volume 1: Long Papers), pages 687-696, 2015.
- [Kazemi and Poole, 2018] Seyed Mehran Kazemi and David Poole. Simple embedding for link prediction in knowledge graphs. In Advances in neural information processing sys- tems, pages 4284-4295, 2018.
- [Lin et al., 2015a] Yankai Lin, Zhiyuan Liu, Huanbo Luan, Maosong Sun, Siwei Rao, and Song Liu. Modeling rela- tion paths for representation learning of knowledge bases. In Proceedings of EMNLP, pages 705-714, 2015.
- [Lin et al., 2015b] Yankai Lin, Zhiyuan Liu, Maosong Sun, Yang Liu, and Xuan Zhu. Learning entity and relation embeddings for knowledge graph completion. In Twenty- ninth AAAI conference on artificial intelligence, 2015.
- [Nickel et al., 2011] Maximilian Nickel, Volker Tresp, and Hans-Peter Kriegel. A three-way model for collective learning on multi-relational data. In Icml, volume 11, pages 809-816, 2011.
- [Nickel et al., 2012] Maximilian Nickel, Volker Tresp, and Hans-Peter Kriegel. Factorizing yago: scalable machine learning for linked data. In Proceedings of the 21st inter- national conference on World Wide Web, pages 271-280, 2012.
- [Nickel et al., 2016] Maximilian Nickel, Lorenzo Rosasco, and Tomaso Poggio. Holographic embeddings of knowl- edge graphs. In Thirtieth Aaai conference on artificial in- telligence, 2016.
- [Socher et al., 2013] Richard Socher, Danqi Chen, Christo- pher D Manning, and Andrew Ng. Reasoning with neu- ral tensor networks for knowledge base completion. In Advances in neural information processing systems, pages 926-934, 2013.
- [Sun et al., 2019] Zhiqing Sun, Zhi-Hong Deng, Jian-Yun Nie, and Jian Tang. Rotate: Knowledge graph embedding by relational rotation in complex space. In 7th Interna- tional Conference on Learning Representations, 2019.
- [Trouillon et al., 2016] Théo Trouillon, Johannes Welbl, Se- bastian Riedel, Éric Gaussier, and Guillaume Bouchard. Complex embeddings for simple link prediction. Interna- tional Conference on Machine Learning (ICML), 2016.
- [Wang et al., 2014a] Zhen Wang, Jianwen Zhang, Jianlin Feng, and Zheng Chen. Knowledge graph and text jointly embedding. In Proceedings of the 2014 conference on em- pirical methods in natural language processing (EMNLP), pages 1591-1601, 2014.
- [Wang et al., 2014b] Zhen Wang, Jianwen Zhang, Jianlin Feng, and Zheng Chen. Knowledge graph embedding by translating on hyperplanes. In Twenty-Eighth AAAI con- ference on artificial intelligence, 2014.
- [Wang et al., 2015] Quan Wang, Bin Wang, and Li Guo. Knowledge base completion using embeddings and rules. In Twenty-Fourth International Joint Conference on Artifi- cial Intelligence, 2015. IJCAI
- [Xie et al., 2016a] Ruobing Xie, Zhiyuan Liu, Jia Jia, Huanbo Luan, and Maosong Sun. Representation learning of knowledge graphs with entity descriptions. In Thirtieth AAAI Conference on Artificial Intelligence, 2016.
- [Xie et al., 2016b] Ruobing Xie, Zhiyuan Liu, and Maosong Sun. Representation learning of knowledge graphs with hierarchical types. In IJCAI, pages 2965-2971, 2016. IJCAI
- [Yang et al., 2015] Bishan Yang, Wen-tau Yih, Xiaodong He, Jianfeng Gao, and Li Deng. Embedding entities and relations for learning and inference in knowledge bases. In 3rd International Conference on Learning Representa- tions, 2015.
- [Zhang et al., 2018] Zhao Zhang, Fuzhen Zhuang, Meng Qu, Fen Lin, and Qing He. Knowledge graph embedding with hierarchical relation structure. In Proceedings of the 2018 Conference on Empirical Methods in Natural Language Processing, pages 3198-3207, 2018.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
With the rapid development of Artificial Intelligence (AI), Knowledge Graphs (KGs) such as Freebase [Bollacker et al., 2008], DBpedia [Auer et al., 2007], and NELL [Carlson et al., 2010], have become fundamental data sources that support the development of many AI-related applications. A typical KG is usually represented as multi-relational data with enormous triple facts in the form of (head entity, relation, tail entity), denoted as (h, r, t).
Even though the constructed KGs have millions of facts, they are still sparse graphs in contrast to common connections in the real world, and thus the existing KGs need to be completed in order to improve their quality and usability. KG completion, i.e., predicting missing facts from existing ones, has become an indispensable tool to construct a high-quality KG. Recently, an effective approach for this task is representation learning, which aims to embed a knowledge graph into a continuous vector space while preserving inherent structure of the KG. Many methods have been proposed on representation learning of KGs, among which the translation-based models are considered to be most popular.
∗Xin Wang is the corresponding author.
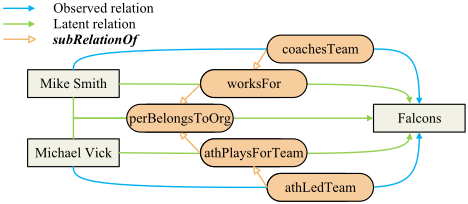
Unfortunately, the most existing translation-based representation learning methods merely focus on the structured information in triples, paying less attention to the rich information implied in RHS. [Zhang et al., 2018] suggests that relations in KGs conform to a three-layer structure, i.e., semantically similar relations can construct clusters of relations and coarse-grained relations can be further split into several fine-grained sub-relations. However, the structure mentioned in that paper is actually not a real RHS, which is simply obtained by a clustering algorithm. In addition, limiting the relation structure to three layers is not universal enough considering the complexity of relations in KGs.
To address the above issue, in this paper, we introduce a more general RHS. Figure 1 shows a KG with RHS, in which (1) the rectangles represent entities, (2) the rounded rectangles represent the relations, (3) the solid lines denote the observed facts, and (4) the dashed lines denote the latent facts, respectively. Given an observed triple (Mike Smith, coachesTeam, Falcons), then the triple (Mike Smith, worksFor, Falcons) and the triple (Mike Smith, personBelongsToOrganization, Falcons) can be logically derived according to RHS among these relations. Fusing RHS information into KG embeddings can intuitively improve the prediction ability of the model, however, in the meanwhile, it may also introduce the following influences: (1) when an existing model has been trained, a direct way of considering the RHS information will change the embeddings of relations. (2) In addition, most translation-based models satisfy h + r ≈ t, so the embeddings of entities will also be affected. These two issues will break the original model and reduce the model performance. In order to make full use of RHS while eliminating this effect as much as possible, we propose a novel and effective representation learning method for KGs named TransRHS. Our TranRHS model is elaborately designed to encode the RHS information so that this information can be seamlessly integrated into the embedding without affecting the original model. More specifically, for each triple (h, r, t), h, t ∈ Rd are learned for entities, and r ∈ Rd together with a multi-dimensional relation-specific sphere are also learned. The information in RHS is encoded into knowledge graph embeddings by using relative positions among the vectors and the spheres. Then TransRHS is optimized by minimizing the corresponding loss functions.
In summary, we highlight our key contributions as follows,
- To the best of our knowledge, we are the first to investigate the problem of representation learning of KGs with relation hierarchical structure, i.e., the subRelationOf generalization relationships among relations.
- We propose a novel representation learning method named TransRHS, which merely adds a relation-specific sphere to the representation of each relation in vector space, but is capable of fusing the information of RHS into the KG embeddings.
- The experimental results on link prediction and triple classification show that TransRHS outperforms all baselines by more than 20% and 5%, respectively, which verifies that RHS can significantly enhance the quality of knowledge graph embeddings.
2 RelatedWork
2.1 KGEmbedding with Facts
As a pioneering work of knowledge graph embedding, TransE [Bordes et al., 2013] opens a line of translation-based methods. TransE encodes both entities and relations as vectors in the same space, say Rd . Given a fact (h, r, t), the relation is interpreted as a translation vector r so that the entities h and t can be linked by r with low error, i.e., h + r ≈ t when (h, r, t) holds.
Despite its simplicity and efficiency, TransE still has drawbacks in dealing with 1-to-N, N-to-1, and N-to-N relations. For a 1-to-N relation, e.g., directorOf, TransE might learn very similar vector representations for Titanic and Avatar which are all films directed by JamesCameron, even though they are different entities.
To fix this issue of TransE, an effective strategy is to allow an entity to have distinct representations when involved in different relations. Following this general idea, TransH
[Wang et al., 2014b] models entities again as vectors, but each relation r as a hyperplane together with a translation operation on that hyperplane, enabling an entity to play distinct roles in different scenarios. Furthermore, TransR [Lin et al., 2015b] directly models entities and relations in separate entity and relation spaces, projecting entities from entity space to relation-specific space when judging the distance between entities. TransD [Ji et al., 2015] simplifies TransR by further decomposing the projection matrix into a product of vectors. RotatE [Sun et al., 2019] proposes a rotation-based translational method, which represents entities as complex vectors and relations as rotations in a complex vector space.
Another category of knowledge representation learning models is the semantic matching models which have also turned out to be effective. RESCAL [Nickel et al., 2011] associates each entity with a vector to capture its latent semantics, and each relation is represented as a matrix which models pairwise interactions between latent factors. DistMult [Yang et al., 2015] simplifies RESCAL by restricting relation matrices to diagonal matrices. However, this oversimplified model can only deal with symmetric relations that is clearly not powerful enough for general knowledge graphs. HolE [Nickel et al., 2016] combines the expressive power of RESCAL with the efficiency and simplicity of DistMult. ComplEx [Trouillon et al., 2016] extends DistMult by introducing complex-valued embeddings so as to better model asymmetric relations.
2.2 KGEmbedding withMulti-Source Information
It has been widely recognized that multi-source information including entity types, relation paths, and textual descriptions, considered as supplements for the structured information implied in triples, is significant for KG embeddings.
The type information is available in most KGs, usually represented in a type of "is-a" relations. A straightforward method [Nickel et al., 2012] to model type information is to regard the triples describing type information as ordinary triples. [Guo et al., 2015] proposed semantically smooth embedding (SSE), which requires entities of the same type to stay close to each other in the embedding space. TKRL [Xie et al., 2016b] is a translational distance model with typespecific entity projections, which can handle hierarchical entity categories and multiple category labels.
In most KGs, the textual information is another kind of common source that can be used for representation learning of KGs. KG embedding with textual information dates back to the NTN model [Socher et al., 2013], where textual information is simply used to initialize entity representations. However, this method separates textual information separately from KG facts, and hence fails to leverage interactions between them. The first joint model [Wang et al., 2014a], which aligns the given KG with an auxiliary text corpus, and then jointly conducts KG embedding and word embedding, makes better use of textual information during embedding. DKRL [Xie et al., 2016a] proposes descriptionbased representations for entities with CBOW or CNN, which is capable of modeling entities in the zero-shot scenario.
Rich information implied in relation hierarchical structure is also significant for KGs, which has been surprisingly ignored. [Lin et al., 2015a] presents PTransE, which encodes relation paths to embed both entities and relations in a lowdimensional space. [Zhang et al., 2018] proposes a threelayer structure of relations, which is merely an abstract structure obtained by gathering similar relations into clusters of relations and splitting coarse-grained relations into several finegrained sub-relations. Our RHS is a structure constructed by the generalization relationship named subRelationOf , which contains abundant semantic information. To take advantage of RHS, we propose a KG embedding model called TransRHS.
3 Our Approach
In this section, the technical details of how to take advantage of the information implied in the relation hierarchical structure are specified. First, the formal definitions of RHS and the problem formulation for representation learning of KGs with RHS are provided. Then, our method TransRHS is proposed and explained in detail. Finally, the new loss functions and the optimization method are introduced.
3.1 Relation Hierarchical Structure
Relation hierarchical structure, which implies inherent relevance among relations, is of significance for representation learning of KGs. This kind of information is usually encoded by a generalization relationship named subRelationOf between relations and stored in the form of triples. Taking the relations in Figure 1 for instance, a subRelationOf triple (athLedTeam, subRelationOf, athPlaysForTeam) indicates the semantic relevance between the relation athLedTeam and the relation athPlaysforTeam, that is, the former is a sub-relation of the latter.
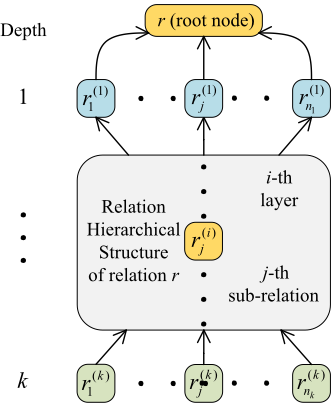
As shown in Figure 2, a typical relation hierarchical structure is tree-like. We usually use the most general relation r as the root node of the corresponding tree structure, and r(i) j represents the j-th sub-relation at the i-th layer in the relation hierarchical structure. ni denotes the total number of sub-relations in the i-th layer. For simplicity, we use r(k) to represent a sub-relation at the k-th layer. A path from the root node r to any leaf node r(k) can be formalized as P k r = {r, r(1) , r(2) , ..., r(k) }, where the subscript r of P k r denotes the root node of this tree structure and the superscript k of that denotes the total number of sub-relations in this path.
Given a knowledge graph, it can be formalized as G = (E,R, T), where E represents the entity set, R the set of relations, and T the set of triple facts. Specifically, the relation set of the KG with RHS can be further formalized as R = {sro} ∪ Rl, where Rl represents the set of relations between entities, and sro (i.e., subRelationOf) represents the generalization relationship between relations.
Therefore, the triple set T in a KG can be divided into two corresponding disjoint subsets:
- subRelationOf triple set Tr = {(r, sro, p) | r, p ∈ Rl}, where r, p are relations between entities and sro is the generalization relationship between relations, namely subRelationOf .
- Relational triple set Te = {(h, r, t) | h, t ∈ E ∧ r ∈ R}, where h, t represent head entity and tail entity, respectively, and r represents a relation between entities.
Representation learning of KGs with RHS aims to learn embeddings for entities and relations in the same space Rd . For each entity e ∈ E , we learn a low-dimensional vector e ∈ Rd . For each relation r ∈ Rl and its RHS information, we learn a low-dimensional vector r ∈ Rd together with a relation-specific sphere s. We typically use ∆ to represent the set of positive triples. A KG embedding model should satisfy the following two formulas to incorporate the RHS information, namely
- , which are essentially a realization of the rdfs5 and rdfs7 rules in the RDFS semantics, respectively [Hayes and PatelSchneider, 2014].
3.2 TransRHS
Notations are described first. Given a positive fact (h, r, t), h denotes a head entity, r represents a relation, and t denotes a tail entity. The bold letters h, r, and t denote the corresponding embeddings. ∆ denotes the set of positive triples, and ∆′ represents the set of negative triples. Therefore, we use (h, r, t) ∈ ∆ to indicate that (h, r, t) is a positive triple. TransE assumes that the score function
is low if (h, r, t) ∈ ∆, which indicates that the lower fr(h, t) is, the more probable (h, r, t) is to be a positive triple.
To take advantage of the implicit information implied in RHS, a novel method named TransRHS is proposed, where Formula (1) and Formula (2) can be explicitly embodied in embeddings. Taking Formula (1) for instance, when (r, sro, p) ∈ Tr holds, if (h, r, t) ∈ Te is a positive triple, then (h, p, t) must be a positive triple. So the embeddings should satisfy that if h + r ≈ t, then h + p ≈ t. Furthermore, fp(h, t) should be less than fr(h, t) according to the Formula (3).
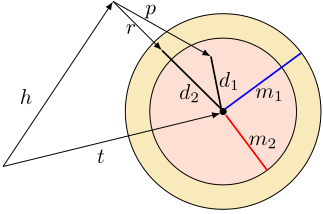
In order to encode the RHS information without increasing the complexity in both space and time, TranRHS merely introduces one more sphere for each relation compared with the TransE. For purpose of reducing the impact on the translation-based model to the minimum, TransRHS will follow the translational requirement, i.e., h + r ≈ t when (h, r, t) holds. In TransRHS, each entity e ∈ E is learned as a low-dimentional vector e ∈ Rd and each relation r ∈ Rl is encoded as a low-dimentional vector r ∈ Rd together with a relation-specific sphere. More specifically, given a pair of triples (h, r, t) ∈ Te and (r, sro, p) ∈ Tr, TransRHS learns relation p as a low-dimensional vector p ∈ Rd and its corresponding spheres s1 with radius m1. Analogously, r ∈ Rd and the sphere s2 with radius m2 are obtained for relation r. And head entity h and tail entity t are represented as lowdimensional vectors h, t ∈ Rd . The distance between the h + p and t can be defined as:
Similarly, we define the distance between h + r and t as:
The ideal embeddings in TransRHS are shown in Figure 3 and meets the following conditions:
- h+p is inside the sphere s1 ( d1 <m1 ).
- h+r is between the sphere s1 and s2 (m1 < d2 < m2 ).
- The sphere s1 is inside the sphere s2 (m1 <m2 ). The following situations still need to be optimized:
- h+p is outside the sphere s1 ( d1 >m1 ).
- h + r is outside the sphere s2 ( d2 > m2 ).
- h+ r is inside the sphere s1 ( d2 <m1 ).
- The sphere s2 is inside the sphere s1 (m1 >m2 ).
For the above conditions, we define the loss functions as:
The condition discussed above involves two layers of RHS. In fact, our model could be applied to encode the information of n-layer RHS into embeddings naturally. For the sake of illustration, we take a three-layer RHS as an example. Given a relational triple (h, r, t) and two subRelationOf triples (r, sro, p) and (p, sro, pp), the spheres s1, s2, and s3 corresponding to the relations pp, p, and r are learned respectively. Similarly, the ideal embeddings should satisfy the following conditions:
- h+pp is inside the sphere s1.
- h+p is between the sphere s1 and s2.
- h+ r is between the sphere s2 and s3.
- The sphere s1 is inside the sphere s2 which is inside the sphere s3 .
Based on the above analysis, our method is easily extended to be appropriate for encoding an n-layer RHS.
The above assumption indicates that the deeper the relation r located in the RHS, the larger the radius m of the sphere corresponding to the relation r. However, the increasing radius of the sphere will make h + r to lie farther away from t, which will conflict the basic principles of the translationbased models, i.e. h + r ≈ t. To address the above issue, we set the difference between the radii of two adjacent spheres should decrease as the depth of relations increases in RHS. We use m(i) to represent the radius of the relation at the i-th layer in RHS and design a proportional-declined weighting strategy among m(i-1), m(i), and m(i+1) as follows:
in which we set η ∈ (0.5, 1). This strategy indicates that the difference between m(i) and m(i-1) is larger than the difference between m(i) and m(i+1), which fits in our objective.
3.3 TrainingMethod
For relational triples, we use ∆ and ∆′ to denote the positive triple set and the negative triple set, respectively. Then we can define a margin-based loss function for relational triples:
where [x]+ ≜ max (0, x) and γ is the margin separating positive triples and negative triples.
| Relations | Inferences | |
|---|---|---|
| Sport | athleteLedSportsTeam athletePlaysForTeam coachesTeam personBelongsToOrganization | (x, athleteLedSportsTeam, y) ↦→ (x, athletePlaysForTeam, y) (x, athletePlaysForTeam, y) ↦→ (x, personBelongsToOrganization, y) (x, coachesTeam, y) ↦→ (x, personBelongsToOrganization, y) |
| Location | capitalCityOfCountry cityLocatedInCountry cityLocatedInState stateHasCapital stateLocatedInCountry | (x, capitalCityOfCountry, y) ↦→ (x, cityLocatedInCountry, y) (x, stateHasCapital, y) ↦→ (y, cityLocatedInState, x) |
The loss function for subRelationOf triples is defined as:
The total loss of the TransRHS model is comprised of two parts, as is shown in Equation 10,
The goal of training TransRHS is to minimize the above loss functions, and iteratively update embeddings of entities, relations, and spheres.
4 Experiments
Our method is evaluated on two typical tasks commonly used in knowledge graph embedding: link prediction [Bordes et al., 2013] and triple classification [Socher et al., 2013].
4.1 Datasets and Experiment Settings
In this research, we evaluate our models on benchmarks Sport and Location, which are introduced by [Wang et al., 2015] and extracted from NELL [Carlson et al., 2010]. The relations in Sport and Location, along with their inferences, are listed in Table 1. Table 2 gives a summary of these datasets.
Considering that in most KGs there are no negative triples which are indispensable for the experiments, the process of model training involves generating negative triples from positive triples. There are two main strategies for generating negative triples: "bern" and "unif". The former method simply obtains negative triples by randomly corrupting the positive triples. Taking a positive fact (h, r, t) for instance, a negative triple (h′ , r, t′ ) or (h, r, t′ ) is obtained by randomly sampling h′ or t′ from entity set. However, as a real KG is often far from complete, this way of randomly sampling may introduce many false negative triples into training. The latter strategy considers the mapping property of the relation, i.e., 1-to-N, N-to-1, and N-to-N, and sets different probabilities for replacing head or tail entity during corrupting triples.
TransRHS model is trained with mini-batch SGD. As for parameters, we select the batch size B among {20, 40, 80, 160} and margin γ among {0.5, 1.0, 1.5, 2.0}. We also set the dimensions of entity and relation to be the same d. For the learning rate λ, we select a fixed-rate following [Bordes et al., 2013]. The optimal configurations of our models are: B = 40, γ = 1.0, λ= 0.001.
| Dataset | |E| | |R| | #Train | #Valid | #Test |
|---|---|---|---|---|---|
| Sport | 1039 | 4 | 1349 | 358 | 358 |
| Location | 445 | 5 | 384 | 65 | 65 |
For a fair comparison, all models are trained under the same dimension d = 100. For the comparison methods, we use the open source implementations in OpenKE [Han et al., 2018] with default hyperparameters.
Compared with TransE, we merely introduce a relationspecific sphere for each relation. Therefore, the space and time complexity of TransRHS is the same as TransE, which scales linearly with the dimension d. Given a KG with n entities and m relations, the space complexity of TransRHS is O(nd +md) and the time complexity is O(d).
4.2 Link Prediction
Evaluation
Link prediction is to complete a triple (h, r, t) with h or t missing, i.e., predict t given (h, r) or predict h given (r, t). Rather than requiring one best answer, this task emphasizes more on ranking a set of candidate entities from the knowledge graph. We follow the same protocol in TransE: for each testing triple (h, r, t), we replace the tail t by every entity e ∈ E in the knowledge graph and calculate a dissimilarity score (according to the scoring function fr) on the corrupted triple (h, r, e). Ranking the scores in ascending order, we then get the rank of the original correct triple. Similarly, we can get another rank for (h, r, t) by corrupting the head h. Let rankh(h, r, t) be the ranking of (h, r, t) among all headcorrupted relations and rankt(h, r, t) denotes a similar ranking with tail corruptions.
We use two evaluation metrics: Hits@N and Mean Reciprocal Rank (MRR). MRR is the mean of the reciprocal rank:
Hits@N measures the proportion of triples in T that rank among top t after corrupting both heads and tails. The above is called the "raw" setting. Notice that if a corrupted triple exists in the knowledge graph, ranking it before the test triple will have a bad effect on the experimental results. To eliminate this factor, we remove those corrupted triples which exist in either train, valid, or test set before getting the rank of each test triple. This setting is called "filter".
| Sport | Location | |||||||||
|---|---|---|---|---|---|---|---|---|---|---|
| MRR | Hits@N(%) | MRR | Hits@N(%) | |||||||
| Model | Filter | Raw | 1 | 3 | 10 | Filter | Raw | 1 | 3 | 10 |
| TransE [Bordes et al., 2013] | 0.644 | 0.417 | 53.3 | 73.8 | 80.0 | 0.548 | 0.492 | 44.6 | 63.8 | 69.2 |
| TransH [Wang et al., 2014b] | 0.540 | 0.368 | 40.2 | 65.5 | 73.3 | 0.421 | 0.375 | 26.1 | 53.8 | 63.8 |
| TransR [Lin et al., 2015b] | 0.423 | 0.304 | 28.0 | 52.6 | 65.6 | 0.553 | 0.489 | 49.2 | 59.2 | 65.3 |
| TransD [Ji et al., 2015] | 0.443 | 0.319 | 27.2 | 57.6 | 69.5 | 0.162 | 0.144 | 10.0 | 15.3 | 24.6 |
| RotatE [Sun et al., 2019] | 0.685 | 0.441 | 61.3 | 73.8 | 80.4 | 0.402 | 0.363 | 36.1 | 40.7 | 47.6 |
| TransE-HRS [Zhang et al., 2018] | 0.661 | 0.429 | 58.5 | 70.9 | 79.4 | 0.414 | 0.380 | 36.9 | 42.3 | 49.2 |
| RESCAL [Nickel et al., 2011] | 0.071 | 0.058 | 4.0 | 7.9 | 12.2 | 0.183 | 0.166 | 7.6 | 20.0 | 40.7 |
| DistMult [Yang et al., 2015] | 0.463 | 0.341 | 39.8 | 49.1 | 58.3 | 0.346 | 0.328 | 30.7 | 35.3 | 41.3 |
| HolE [Nickel et al., 2016] | 0.269 | 0.184 | 22.4 | 26.8 | 35.4 | 0.356 | 0.330 | 33.0 | 36.1 | 39.2 |
| ComplEx [Trouillon et al., 2016] | 0.511 | 0.365 | 43.0 | 55.1 | 66.2 | 0.365 | 0.342 | 33.0 | 36.9 | 43.0 |
| SimplE [Kazemi and Poole, 2018] | 0.495 | 0.380 | 42.7 | 52.0 | 62.8 | 0.357 | 0.331 | 31.5 | 37.6 | 40.7 |
| TransRHS (unif) | 0.820 | 0.515 | 80.5 | 82.8 | 84.2 | 0.652 | 0.572 | 63.1 | 66.2 | 69.2 |
| TransRHS (bern) | 0.809 | 0.514 | 78.7 | 82.1 | 83.7 | 0.660 | 0.586 | 64.6 | 66.2 | 69.8 |
Results
The results of the link prediction are shown in Table 3. From the results, we observe that: (1) TransRHS significantly outperforms all baselines in terms of both MRR and Hits@N, which indicates that the RHS information is successfully encoded into entity and relation embeddings and could improve the representation learning of knowledge graphs. (2) The "unif" sampling trick works well for Sport and the "bern" sampling trick behaves well for Location.
4.3 Triple Classification
Evaluation
Triple classification is to determine whether a given triple (h, r, t) is correct or not, which is a binary classification task.
Negative triples are required for the evaluation of triple classification. Hence, we construct some negative triples following the same setting in [Socher et al., 2013] . There are as many true triples as negative triples in both valid and test set.
| Accuracy(%) | ||
|---|---|---|
| Model | Sport | Location |
| TransE [Bordes et al., 2013] | 89.2 | 68.4 |
| TransH [Wang et al., 2014b] | 86.8 | 73.8 |
| TransR [Lin et al., 2015b] | 85.6 | 66.9 |
| TransD [Ji et al., 2015] | 86.1 | 60.7 |
| RotatE [Sun et al., 2019] | 89.2 | 72.3 |
| TransE-HRS [Zhang et al., 2018] | 86.9 | 69.7 |
| RESCAL [Nickel et al., 2011] | 57.8 | 57.6 |
| DistMult [Yang et al., 2015] | 85.7 | 58.4 |
| HolE [Nickel et al., 2016] | 77.3 | 69.2 |
| ComplEx [Trouillon et al., 2016] | 86.3 | 74.6 |
| SimplE [Kazemi and Poole, 2018] | 86.5 | 67.6 |
| TransRHS (unif) | 89.8 | 74.8 |
| TransRHS (bern) | 90.9 | 78.4 |
The classification strategy is conducted as follows: We set different relation-specific thresholds δr for each relation. For a triple (h, r, t), if the dissimilarity score of fr(h, t) is below δr, the triple is then predicted to be positive and otherwise negative. The relation-specific thresholds δr are optimized by maximizing the classification accuracies in all triples with the corresponding r on the valid sets.
Results
We evaluate this task on both Sport and Location. Evaluation results on triple classification are shown in Table 4. From Table 4 we observe that: (1) The empirical results in triple classification demonstrate that TransRHS outperforms all baselines , which once again confirms the conclusions we obtained from link prediction and indicates that TransRHS is capable of encoding RHS information into knowledge graph embeddings. (2) "bern" sampling trick works well for both datasets.
5 Conclusion
In this paper, we propose a novel model named TransRHS for representation learning of knowledge graphs with relation hierarchical structure. More specifically, each relation in knowledge graph is encoded into a low-dimensional vector together with a relation-specific sphere in the same space. In experiments, we evaluate our model on two typical tasks including link prediction and triple classification. Experimental results show that RHS information is significant for representation learning of knowledge graphs, and TransRHS model is capable of encoding RHS information into KG embeddings.
Acknowledgements
This work is supported by the National Natural Science Foundation of China (61972275) and the Australian Research Council Linkage Project (LP180100750).
@inproceedings{ijcai2020p413,
  title     = {TransRHS: A Representation Learning Method for Knowledge Graphs with Relation Hierarchical Structure},
  author    = {Zhang, Fuxiang and Wang, Xin and Li, Zhao and Li, Jianxin},
  booktitle = {Proceedings of the Twenty-Ninth International Joint Conference on
               Artificial Intelligence, {IJCAI-20}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Christian Bessiere},
  pages     = {2987--2993},
  year      = {2020},
  month     = {7},
  note      = {Main track},
  doi       = {10.24963/ijcai.2020/413},
  url       = {https://doi.org/10.24963/ijcai.2020/413},
}
TY - CPAPER TI - TransRHS: A Representation Learning Method for Knowledge Graphs with Relation Hierarchical Structure AU - Zhang, Fuxiang AU - Wang, Xin AU - Li, Zhao AU - Li, Jianxin T2 - Proceedings of the Twenty-Ninth International Joint Conference on Artificial Intelligence, IJCAI-20 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2020 SP - 2987 EP - 2993 DO - 10.24963/ijcai.2020/413 UR - https://doi.org/10.24963/ijcai.2020/413 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





