
Exploiting the Sign of the Advantage Function to Learn Deterministic Policies in Continuous Domains
Proceedings of the Twenty-Eighth International Joint Conference on Artificial Intelligence. Main track. Pages 4496-4502.
https://doi.org/10.24963/ijcai.2019/625
Keywords
- Machine Learning: Reinforcement Learning
- Planning and Scheduling: Markov Decisions Processes
Abstract
In the context of learning deterministic policies in continuous domains, we revisit an approach, which was first proposed in Continuous Actor Critic Learning Automaton (CACLA) and later extended in Neural Fitted Actor Critic (NFAC). This approach is based on a policy update different from that of deterministic policy gradient (DPG). Previous work has observed its excellent performance empirically, but a theoretical justification is lacking. To fill this gap, we provide a theoretical explanation to motivate this unorthodox policy update by relating it to another update and making explicit the objective function of the latter. We furthermore discuss in depth the properties of these updates to get a deeper understanding of the overall approach. In addition, we extend it and propose a new trust region algorithm, Penalized NFAC (PeNFAC). Finally, we experimentally demonstrate in several classic control problems that it surpasses the state-of-the-art algorithms to learn deterministic policies.
- [Colas et al., 2018] Cédric Colas, Olivier Sigaud, and Pierre- Yves Oudeyer. GEP-PG: Decoupling Exploration and Ex- ploitation in Deep Reinforcement Learning Algorithms. In International Conference on Machine Learning, Stock- holm, Sweden, July 2018.
- [Henderson et al., 2018] Peter Henderson, Riashat Islam, Philip Bachman, Joelle Pineau, Doina Precup, and David Meger. Deep reinforcement learning that matters. In Thirty-Second AAAI Conference on Artificial Intelligence, 2018.
- [Ioffe and Szegedy, 2015] Sergey Ioffe and Christian Szegedy. Batch Normalization: Accelerating Deep Network Training by Reducing Internal Covariate Shift. arXiv preprint arXiv:1502.03167, 2015.
- [Kakade and Langford, 2002] Sham Kakade and John Lang- ford. Approximately optimal approximate reinforcement learning. In International Conference on Machine Learn- ing, volume 2, pages 267-274, 2002.
- [Kingma and Ba, 2015] Diederik P. Kingma and Jimmy L. Ba. Adam: a Method for Stochastic Optimization. Inter- national Conference on Learning Representations, pages 1-13, 2015.
- [Konda and Tsitsiklis, 1999] Vijay R. Konda and John N. Tsitsiklis. Actor-Critic Algorithms. Neural Information Processing Systems, 13:1008-1014, 1999.
- [Lillicrap et al., 2016] Timothy P. Lillicrap, Jonathan J. Hunt, Alexander Pritzel, Nicolas Heess, Tom Erez, Yu- val Tassa, David Silver, and Daan Wierstra. Continuous control with deep reinforcement learning. International Conference on Learning Representations, 2016.
- [Maatyas, 1965] Josef Maatyas. Random optimization. Au- tomation and Remote control, 26(2):246-253, 1965.
- [Mnih et al., 2015] Volodymyr Mnih, Koray Kavukcuoglu, David Silver, Andrei a Rusu, Joel Veness, Marc G. Belle- mare, Alex Graves, Martin Riedmiller, Andreas K. Fid- jeland, Georg Ostrovski, Stig Petersen, Charles Beattie, Amir Sadik, Ioannis Antonoglou, Helen King, Dharshan Kumaran, Daan Wierstra, Shane Legg, and Demis Has- sabis. Human-level control through deep reinforcement learning. Nature, 518(7540):529-533, 2015.
- [Prokhorov and Wunsch, 1997] Danil V. Prokhorov and Donald C. Wunsch. Adaptive critic designs. IEEE Trans- actions on Neural Networks, 8(5):997-1007, 1997.
- [Schulman et al., 2015] John Schulman, Sergey Levine, Michael Jordan, and Pieter Abbeel. Trust Region Pol- icy Optimization. International Conference on Machine Learning, page 16, 2015.
- [Schulman et al., 2017] John Schulman, Filip Wolski, Pra- fulla Dhariwal, Alec Radford, and Oleg Klimov. Proximal policy optimization algorithms. CoRR, abs/1707.06347, 2017.
- [Silver et al., 2014] David Silver, Guy Lever, Nicolas Heess, Thomas Degris, Daan Wierstra, and Martin Riedmiller. Deterministic Policy Gradient Algorithms. Proceedings of the 31st International Conference on Machine Learning, pages 387-395, 2014.
- [Smith, 2005] Russell Smith. Open dynamics engine. 2005.
- [Sutton et al., 1999] Richard S. Sutton, David Mcallester, Satinder Singh, and Yishay Mansour. Policy Gradient Methods for Reinforcement Learning with Function Ap- proximation. In Advances in Neural Information Process- ing Systems 12, pages 1057-1063, 1999.
- [Sutton, 1988] Richard S. Sutton. Learning to predict by the methods of temporal differences. Machine learning, 3(1):9-44, 1988.
- [Van Hasselt and Wiering, 2007] Hado Van Hasselt and Marco A. Wiering. Reinforcement learning in continuous action spaces. In Proceedings of the IEEE Symposium on Approximate Dynamic Programming and Reinforcement Learning, pages 272-279, 2007.
- [Zimmer et al., 2016] Matthieu Zimmer, Yann Boniface, and Alain Dutech. Neural Fitted Actor-Critic. In European Symposium on Artificial Neural Networks, Computational Intelligence and Machine Learning, 2016.
- [Zimmer et al., 2018] Matthieu Zimmer, Yann Boniface, and Alain Dutech. Developmental reinforcement learning through sensorimotor space enlargement. In The 8th Joint IEEE International Conference on Development and Learning and on Epigenetic Robotics, September 2018.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Model-free reinforcement learning combined with neural networks achieved several recent successes over a large range of domains [Mnih et al., 2015; Lillicrap et al., 2016; Schulman et al., 2017]. Yet those methods are still difficult to apply without any expert knowledge, lack robustness and are very sensitive to hyperparameter optimization [Henderson et al., 2018; Colas et al., 2018].
In this context, we focus in this paper on improving methods that learn deterministic policies. Such policies have three main advantages during the learning phase: 1) they usually require less interactive data because fewer parameters need to be learned, 2) their performances are less costly to estimate during testing phases because randomness only comes from the environment (as opposed to randomized policies), and 3) they are also less sensitive to the premature convergence problem, because they cannot directly control exploration. Moreover, deterministic policies are preferred in some domains (e.g., robotics), because we do not want the agent to act stochastically after the learning phase.
In continuous state and action space domains, solution methods require function approximation. Neural control architectures are excellent representations for policies because they can handle continuous domains, are easily scalable, and have a high degree of expressiveness. The weights of such neural networks are usually updated with a policy gradient method. As vanilla policy gradient suffers from high variance, it is generally implemented in an actor-critic architecture where an estimated value function helps to reduce the variance at the cost of introducing some bias [Konda and Tsitsiklis, 1999]. In this architecture, the parameters (e.g., weights of neural networks) of the policy (i.e., actor) and its value function (i.e., critic) are updated simultaneously.
The basic version of an actor-critic architecture for learning deterministic policies in continuous domains is the deterministic policy gradient (DPG) method [Silver et al., 2014]. Learning the value function is crucial but also difficult, which is why several extensions of DPG have been proposed. Deep Deterministic Policy Gradient (DDPG) [Lillicrap et al., 2016] brings batch normalization [Ioffe and Szegedy, 2015], target networks and replay buffer [Mnih et al., 2015] to DPG and is one of the most used actor-critic methods for learning continuous deterministic policies. However, it has several limitations: 1) the critic learns the state-action value function (Q function), which is difficult to estimate, 2) it relies on the fact that non-biased estimates of the gradient of the Q function are accessible, which is not the case in the model-free setting, 3) it does not use compatible functions: the policy gradient might be poorly estimated.
In this work, we focus on an alternative method that estimates the state value function (V function) instead of the Q function to learn continuous deterministic policies. Van Hasselt and Wiering [2007] were the first to propose to reinforce the policy toward an action with a positive temporal difference. They experimentally showed that using such a method, in an incremental actor-critic algorithm, called Continuous Actor Critic Learning Automaton (CACLA), provided better results than both the stochastic and the deterministic policy gradients 1 in the Mountain Car and the Acrobot environments. Zimmer et al. [2016; 2018] validated those results in higher-dimensional environments, Half-Cheetah and Humanoid in Open Dynamic Engine [Smith, 2005], and proposed several extensions with the Neural Fitted Actor Critic (NFAC) algorithm. However, no theoretical explanation for their good performance, nor a clear discussion about which objective function those methods optimize were given. Providing such an explanation would help understand better why those algorithms work well, what are their properties and limitations, and how to further improve them.
1 In their paper the deterministic policy gradient algorithm was called ADHDP [Prokhorov and Wunsch, 1997].
We first show that CACLA and NFAC can be viewed as policy gradient methods and that they are closely related to a specific form of the stochastic policy gradient (SPG) [Sutton et al., 1999]. Then we discuss some of their properties and limitations. Moreover, we extend them with trust region updates and call the new algorithm Penalized Neural Fitted Actor Critic (PeNFAC). Finally, we experimentally show that PeNFAC performs well on three high-dimensional continuous environments compared to the state-of-the-art methods.
2 Background
A continuous Markov Decision Process (MDP) [Sutton, 1988] is a tuple (S,A, T,R, T0) where S is a continuous state space, A is a continuous action space with m dimensions, T : S × A × S → [0, 1] is a transition function, R : S × A → R is a reward function, T0 is a distribution over initial states. In the model-free setting, it is assumed that the transition function T and the reward function R are unknown and can only be sampled at specific states according to the interaction between the agent and the environment.
The following notations are used: µ represents a deterministic policy and π a stochastic one. Thus, for a given state s ∈ S, µ(s) is an action, π(a|s) is the probability of sampling action a from the policy π, and π(·|s) is a distribution over the action space A. For a policy π, we denote the discounted state distribution by:
where γ ∈ [0, 1) is a discount factor and p(s|s0, t, π) is the probability of being in state s after applying policy π t timesteps from state s0. Its state value function is defined by V π (s) = Eπ [∑∞t=0 γ tR(St,At)∣∣S0 = s] where Eπ is the expectation induced by T and π, and for all t, St and At are random variables. Its action value function is given by Qπ (s, a) = Eπ [∑∞t=0 γ tR(St,At)∣∣S0 = s,A0 = a], and its advantage function by Aπ (s, a) = Qπ (s, a) - V π (s).
In reinforcement learning, the goal is to find a policy that optimizes the expectation of the discounted rewards:
Due to the continuity of the state/action spaces, this optimization problem is usually restricted to a class of parametrized policies, which we denote πθ (stochastic case) or µθ (deterministic case). To simplify notations, we may write π or µ instead of πθ or µθ. The stochastic policy gradient (SPG) in the continuous case can be written as [Sutton et al., 1999]:
The DPG is defined as [Silver et al., 2014]:
where
Policy gradient methods usually take a step according to those directions: θt+1 ← θt + α∇θJ. However, it is difficult to select a proper learning rate α to control the step size. If α is too big, the method may diverge. If it is too low, the learning will converge slowly (thus requiring more samples). To overcome this difficulty, a trust region method can be used to control the step size [Schulman et al., 2015]. Indeed, one can guarantee monotonic gradient updates by exploiting an approximation of the policy advantage function [Kakade and Langford, 2002] of ˜π with respect to π, which measures the difference of performance between the two policies:
The latter approximation holds when the two policies are close, which can be enforced by a KL divergence constraint in trust region policy optimization [Schulman et al., 2015].
3 Algorithms
In this section, we recall three related algorithms (CACLA, CAC, NFAC) that we discuss later.
3.1 Continuous Actor Critic Learning Automaton
Continuous Actor Critic Learning Automaton (CACLA) [Van Hasselt and Wiering, 2007] is an actor-critic method that learns a stochastic policy π and its estimated value function ˆ V π . We assume in this paper that CACLA uses isotropic Gaussian exploration, which implies that π can be written as follows:
where I is the identity matrix and σ > 0 possibly annealed during learning. CACLA alternates between two phases:
1) a hill climbing step in the action space using a random optimization (RO) algorithm [Maatyas, 1965],
2) a gradient-like update in the policy parameter space. RO consists in repeating the following two steps:
i) sample a new action a′ , which is executed in the environment in current state s, by adding a normally distributed noise to the current action a = µ(s),
ii) if R(s, a′ )+γ ˆ V π (s′ ) > ˆ V π (s) then a ← a′ else a does not change.
Phase 2) is based on following update:
where δ(s, a) = R(s, a) + γ ˆ V π (s′ ) - ˆ V π (s) is the temporal difference (TD) error. As the expectation of the TD error is equal to the advantage function, this update can be interpreted as follows: if an exploratory action a has a positive advantage then policy µ should be updated towards a.
Note that although CACLA executes a stochastic policy π, it can be seen as learning a deterministic policy µ. Van Hasselt and Wiering [2007] state that when learning in continuous action space, moving away from a bad action could be meaningless. Indeed, while for stochastic policies, the probability of a bad action can be decreased, for deterministic policies, moving in the action space in the opposite direction of an action with a negative advantage may not necessarily lead to better actions. Thus, CACLA's update is particularly appropriate for learning continuous deterministic policies.
3.2 Continuous Actor Critic
In our discussion, we also refer to a slightly different version of CACLA, Continuous Actor Critic (CAC) [Van Hasselt and Wiering, 2007]. The only difference between CAC and CACLA is that the update in CAC is scaled by the TD error:
Thus an action with a larger positive advantage (here, estimated by the TD error) will have a bigger impact over the global objective.
3.3 Neural Fitted Actor Critic
The Neural Fitted Actor Critic (NFAC) [Zimmer et al., 2016; Zimmer et al., 2018] algorithm is an efficient instantiation of the CACLA update, which integrates the following techniques: batch normalization, λ-returns for both the critic and the actor, and batch learning with Adam[Kingma and Ba, 2015]. In this algorithm, the update of the parameters is not done anymore at each time step, but at the end of a given number of episodes.
4 Discussions
In this section, we discuss the algorithms to provide some theoretical explanation for their good performance.
4.1 CACLA
We first explain the relationship between an algorithm based on stochastic policy gradient (SPG) and CACLA. For this discussion, we assume that SPG is applied to parametrized policies that are Gaussian policies πθ,σ (i.e., Gaussian around µθ). Then the first common feature between the two algorithms is that the distributions over states they induce during learning are the same (i.e., dπγ (s)) because they both use the same exploratory policy to interact with the environment. Moreover, SPG can be written as follows:
For CACLA, we interpret update (6) as a stochastic update in the following direction:
where H is the Heaviside function. Indeed, the inner integral is estimated using a single Monte Carlo sample during the run of CACLA.
Under this form, it is easy to see the similarity between SPG and CACLA. The constant factor 1 σ2 can be neglected because it may be integrated into the learning rate. The sign difference of the term (a - µθ(s)) is because SPG performs gradient ascent and CACLA gradient descent. So the main difference between SPG and CACLA is the replacement of Aπ (s, a) by H(Aπ (s, a)). Therefore CACLA optimizes its exploratory stochastic policy through an approximation of SPG hoping to improve the underlying deterministic policy (for a fixed state, the direction of CACLA and SPG are the same up to a scalar).
Moreover, relating CACLA's update with (8) also brings to light two main limitations. The first one concerns the inner integral over the action space which has a high variance. Therefore, we expect CACLA to be less and less data efficient in high-dimension action space (which is the main theoretical justification of DPG over SPG - see Appendix B.1). The second limitation that appears is that over one update, CACLA does not share the same exact optimal solutions as DPG or SPG. Indeed, if we define θ∗ such as ∇θJ(µθ)∣∣θ=θ∗ = 0 it is not possible to prove that (8) will also be 0 (because of the integral over the state space). It means that CACLA could decrease the performance of this local optimal solution.
4.2 CAC
Similarly, the update in CAC can be seen as a stochastic update in the following direction:
This shows that CAC is even closer to SPG than CACLA and provides a good theoretical justification of this update at a local level (not moving in potentially worst action). However, there is also a justification at a more global level.
Lemma 4.1. For a fixed state, when the exploration tends to zero, CAC maintains the sign of the DPG update with a scaled magnitude:
where g+(s, π) is a positive function between [0; 1]n with n as the number of parameters of the deterministic policy and ◦ is the Hadamard product (element-wise product).
The proof is provided in Appendix A.1. The consequence of this lemma is that, for a given state and low exploration, a local optimal solution for DPG will also be one for CAC. However it is still not the case for the overall update because of the integral over the different states. The weights given to each direction over different states are not the same in CAC and DPG. One might think that in such a case, it would be better to use DPG. However, in practice, the CAC update may in fact be more accurate when using an approximate advantage function. Indeed, there exist cases where DPG with an approximate critic might update towards a direction which could decrease the performance. For instance, when the estimated advantage ˆ A(s, µ(s)) is negative, the advantage around µ(s) is therefore known to be poorly estimated. In such a case, thanks to the Heaviside function, CAC will not perform any update for actions a in the neighborhood of µ(s) such that ˆ A(s, a) ≤ 0. However, in such a case, DPG will still perform an update according to this poorly estimated gradient.
5 Extension to Trust Region
In this section, we extend the approach to use a trust region method.
5.1 Trust Region for Deterministic Policies
We now introduce a trust region method dedicated to continuous deterministic policies. Given current deterministic policy µ, and an exploratory policy π defined from µ, the question is to find a new deterministic policy ˜µ that improves upon µ. Because a deterministic policy is usually never played in the environment outside of testing phases, a direct measure between two deterministic policies (i.e., a deterministic equivalent of Equation 4) is not directly exploitable. Instead we introduce the following measure:
Lemma 5.1. The performance J(˜µ) of a deterministic policy ˜µ can be expressed by the advantage function of another stochastic policy π built upon a deterministic policy µ as:
See Appendix A.2 for the proof. The first two quantities in the RHS of (10) are independent of ˜µ. The second one represents the difference of performance from moving from the deterministic policy µ to its stochastic version π. Because d ˜µγ would be too costly to estimate, we approximate it with the simpler quantity dπγ , as done by Schulman et al. [2015] for TRPO, a predecessor to PPO.
Theorem 5.2. Given two deterministic policies µ and ˜µ, a stochastic Gaussian policy π with mean µ(s) in state s and independent variance σ, if the transition function T is LLipschitz continuous with respect to the action from any state then:∣∣∣
The proof is available in Appendix A.3. Thus, to ensure a stable improvement at each update, we need to keep both ||µ - ˜µ||2,∞ and σ small. Note that the Lipschitz continuity condition is natural in continuous action spaces. It simply states that for a given state, actions that are close will produce similar transitions.
5.2 Practical Algorithm
To obtain a concrete and efficient algorithm, the trust region method can be combined with the previous algorithms. Its integration to NFAC with a CAC update for the actor is called Penalized Neural Fitted Actor Critic (PeNFAC).
Van Hasselt and Wiering [2007] observed that the CAC update performs worse that the CACLA update in their algorithms. In their setting where the policy and the critic are updated at each timestep, we believe this observation is explained by the use of the TD error (computed from a single sample) to estimate the advantage function. However, when using variance reduction techniques such as λ-returns and learning from a batch of interactions, or when mitigating the update with a trust region constraint, we observe that this estimation becomes better (see Figure 4). This explains why we choose a CAC update in PeNFAC.
In order to ensure that ||µ - ˜µ||2,∞ stays small over the whole state space, we approximate it with a Euclidean norm over the state visited by π. To implement this constraint, we add a regularization term to the update and automatically adapts its coefficient, for a trajectory (s0, s1, . . . , sh):
where β is a regularization coefficient. Similarly to the adaptive version of Proximal Policy Optimization (PPO) [Schulman et al., 2017], β is updated in the following way (starting from β ← 1):
- if ˆ d(µ, µold) < dtarget/1.5: β ← β/2,
- if ˆ d(µ, µold) > dtarget × 1.5: β ← β × 2,
where ˆ d(µ, µold) = 1 √mL ∑s∼π ||µold(s) - µθ(s)||2 with L being the number of gathered states. Those hyper-parameters are usually not optimized because the learning is not too sensitive to them. The essential value to adapt for the designer is dtarget. Note that the introduction of this hyperparameter mitigates the need to optimize the learning rate for the update of the policy, which is generally a much harder task.
6 Experiments
We performed two sets of experiments to answer the following questions:
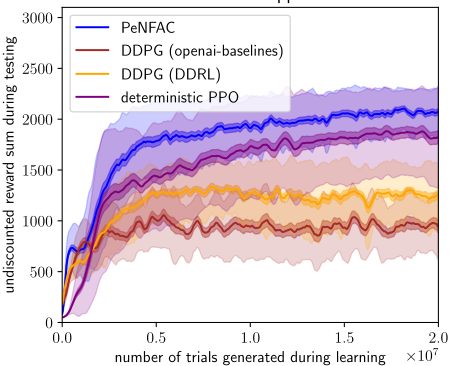
RoboschoolHopper-v1
number of trials generated during learning ×107
- How does PeNFAC compare with state-of-the-art algorithms for learning deterministic policies?
- Which components of PeNFAC contribute the most to its performance?
The experiments were performed on environments with continuous state and action spaces in a time-discretized simulation. We chose to perform the experiments on OpenAI Roboschool [Schulman et al., 2017], a free open-source software, which allows anyone to easily reproduce our experiments. In order to evaluate the performance of an algorithm, deterministic policies µ obtained during learning are evaluated at a constant interval during testing phases: policy µ is played in the environment without exploration. The interactions gathered during this evaluation are not available to any algorithms. The source code of the PeNFAC algorithm is available at github.com/matthieu637/ddrl. The hyperparameters used are reported in Appendix E as well as the considered range during the grid search.
6.1 Performance of PeNFAC
We compared the performance of PeNFAC to learn continuous deterministic policies with two state-of-the-art algorithms: PPO and DDPG. A comparison with NFAC is available in the ablation study (Section 6.2) and in Appendix C. Because PPO learns a stochastic policy, for the testing phases, we built a deterministic policy as follows µ(s) = E[a|a ∼ πθ(·, s)]. We denote this algorithm as "deterministic PPO". In Appendix D, we experimentally show that this does not penalize the comparison with PPO, as deterministic PPO provides better results than standard PPO. For PPO, we used the OpenAI Baseline implementation. To implement PeNFAC and compare it with NFAC, we use the DDRL library [Zimmer et al., 2018]. Given that DDPG is present in those two libraries, we provided the two performances for it. The OpenAI Baseline version uses an exploration in the parameter space and the DDRL version uses n-step returns.
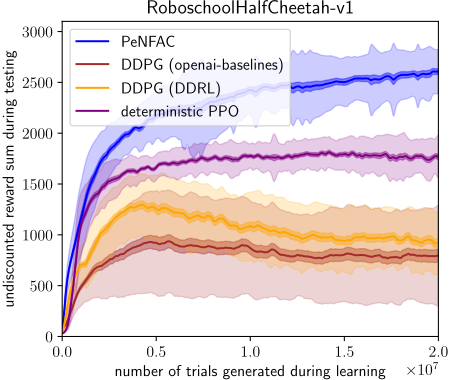
number of trials generated during learning ×107
Figure 2: Comparison of PeNFAC, DDPG and deterministic PPO over 60 different seeds for each algorithm in HalfCheetah.
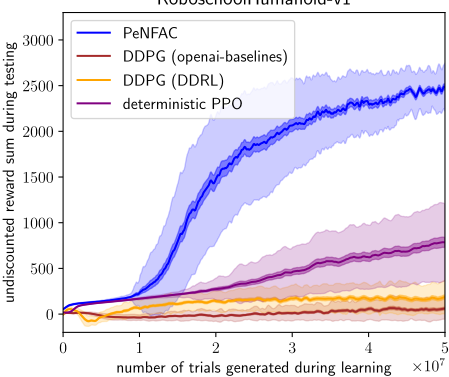
RoboschoolHumanoid-v1
number of trials generated during learning ×107
We performed learning experiments over three highdimensional domains: Hopper, HalfCheetah and Humanoid. Dimensions of S ×A are 15×3 (Hopper), 26×6 (HalfCheetah) and 44 × 17 (Humanoid).
The neural network architecture is composed of two hidden layers of 64 units for either the policy or the value function. The choice of the activation function in the hidden units was optimized for each algorithm: we found that ReLU was better for all of them except for PPO (where tanh was better). The output activation of the critic is linear and the output activation of the actor is tanh.
In Figures 1-4, the lighter shade depicts one standard deviation around the average, while the darker shade is the standard deviation divided by the square root of the number of seeds.
In Figures 1-3, PeNFAC outperforms DDPG and deterministic PPO during the testing phase. On Humanoid, even after optimizing the hyperparameters, we could not obtain the same results as those of Schulman et al. [2017]. We conjecture that this may be explained as follows: 1) the RoboschoolHumanoid moved from version 0 to 1, 2) deterministic PPO
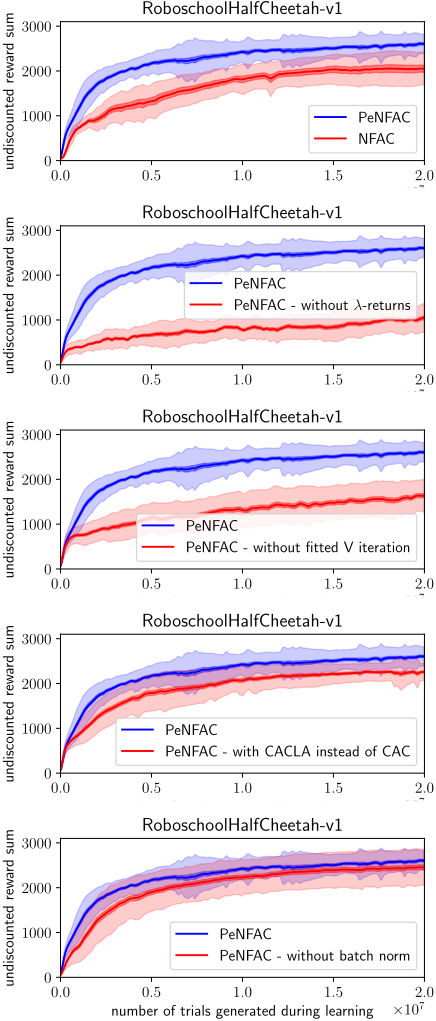
number of trials generated during learning ×107
Figure 4: Comparison of the different components (λ-returns, fitted value-iteration, CAC vs CACLA update, batch normalization) of the PeNFAC algorithm during the testing phase over the HalfCheetah environment and 60 seeds for each version.
might be less efficient than PPO, 3) neither LinearAnneal for the exploration, nor adaptive Adam step size is present in the OpenAI Baseline implementation. However, we argue that the comparison should still be fair since PeNFAC also does not use those two components. On Humanoid, we did not find a set of hyperparameters where DDPG could work correctly with both implementations.
6.2 Components of PeNFAC
In Figure 4, we present an ablation analysis in the HalfCheetah domain to understand which components of the PenFAC algorithm are the most essential to its good performance. From top to bottom plots of Figure 4, we ran PenFAC with or without trust region, with or without λ-returns, with or without fitted value iteration, with CACLA update or CAC update, and finally with or without batch normalization.
It appears that λ-returns and fitted value iteration are the most needed, while the effect of batch normalization is small and mostly helps in the beginning of the learning.
We also tried updating the actor every timestep without taking into account the sign of the advantage function (i.e., using SPG instead of CAC), but the algorithm was not able to learn at all. This also demonstrates that the CAC update is an essential component of PenFAC.
7 Conclusion
In the context of learning deterministic policies, we studied the properties of two not very well-known but efficient updates, Continuous Actor Critic Learning Automaton (CACLA) and Continuous Actor Critic (CAC). We first showed how closely they both are related to the stochastic policy gradient (SPG). We explained why they are well designed to learn continuous deterministic policies when the value function is only approximated. We also highlighted the limitations of those methods: a potential poor sample efficiency when the dimension of the action space increases and no guarantee that the underlying deterministic policy will converge toward a local optimum of J(µθ) even with a linear approximation.
In the second part, we extended Neural Fitted Actor Critic (NFAC), itself an extension of CACLA, with a trust region constraint designed for deterministic policies and proposed a new algorithm, Penalized NFAC (PeNFAC). Finally, we tried our implementation on various high-dimensional continuous environments and showed that PeNFAC performs better than DDPG and PPO to learn continuous deterministic policies.
As future work, we plan to consider off-policy learning and the combination of the updates of CAC and DPG together to ensure the convergence toward a local optimum while benefiting from the good updates of CAC.
Acknowledgments
This work has been supported in part by the program of National Natural Science Foundation of China (No. 61872238). Experiments presented in this paper were carried out using the Grid'5000 testbed, supported by a scientific interest group hosted by Inria and including CNRS, RENATER and several Universities as well as other organizations (see https://www.grid5000.fr).
@inproceedings{ijcai2019p625,
  title     = {Exploiting the Sign of the Advantage Function to Learn Deterministic Policies in Continuous Domains},
  author    = {Zimmer, Matthieu and Weng, Paul},
  booktitle = {Proceedings of the Twenty-Eighth International Joint Conference on
               Artificial Intelligence, {IJCAI-19}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Sarit Kraus},
  pages     = {4496--4502},
  year      = {2019},
  month     = {8},
  note      = {Main track},
  doi       = {10.24963/ijcai.2019/625},
  url       = {https://doi.org/10.24963/ijcai.2019/625},
}
TY - CPAPER TI - Exploiting the Sign of the Advantage Function to Learn Deterministic Policies in Continuous Domains AU - Zimmer, Matthieu AU - Weng, Paul T2 - Proceedings of the Twenty-Eighth International Joint Conference on Artificial Intelligence, IJCAI-19 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2019 SP - 4496 EP - 4502 DO - 10.24963/ijcai.2019/625 UR - https://doi.org/10.24963/ijcai.2019/625 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





