
Correlating Preferences and Attributes: Nearly Single-Crossing Profiles
Proceedings of the Twenty-Eighth International Joint Conference on Artificial Intelligence. Main track. Pages 414-420.
https://doi.org/10.24963/ijcai.2019/59
Keywords
- Agent-based and Multi-agent Systems: Computational Social Choice
- Agent-based and Multi-agent Systems: Voting
Abstract
We use social choice theory to develop correlation coefficients between ranked preferences and an ordinal attribute such as educational attainment or income level. For example, such correlations could be used to formalise statements such as "voters' preferences over parties are better explained by age than by income level". In the literature, preferences that are perfectly explained by a single-dimensional agent attribute are commonly taken to be single-crossing preferences. Thus, to quantify how well an attribute explains preferences, we can order the voters by the value of the attribute and compute how far the resulting ordered profile is from being single-crossing, for various commonly studied distance measures (Kendall tau distance, voter/alternative deletion, etc.). The goal of this paper is to evaluate the computational feasibility of this approach. To this end, we investigate the complexity of computing these distances, obtaining an essentially complete picture for the distances we consider.
- [Bartholdi III et al., 1989] John Bartholdi III, Craig A. Tovey, and Michael A. Trick. Voting schemes for which it can be difficult to tell who won the election. Social Choice and Welfare, 6(2):157-165, 1989.
- [Biedl et al., 2009] Therese C. Biedl, Franz-Josef Branden- burg, and Xiaotie Deng. On the complexity of crossings in permutations. Discrete Mathematics, 309(7):1813-1823, 2009.
- [Bredereck et al., 2016] Robert Bredereck, Jiehua Chen, and Gerhard J. Woeginger. Are there any nicely structured preference profiles nearby? Mathematical Social Sciences, 79:61-73, 2016.
- [Cohen et al., 2019] Nathann Cohen, Edith Elkind, and Foram Lakhani. Single-crossing implementation, 2019. arXiv:1906.09671.
- [Cornaz et al., 2013] Denis Cornaz, Lucie Galand, and Olivier Spanjaard. Kemeny elections with bounded single- peaked or single-crossing width. In Proceedings of the 23rd International Joint Conference on Artificial Intelligence (IJCAI), pages 76-82, 2013.
- [de Vaus, 2002] David de Vaus. Surveys in Social Research.
- Taylor & Francis, 2002. 5th edition.
- [Diestel, 2012] Reinhard Diestel. Graph Theory. Springer, 2012.
- [Downey and Fellows, 2013] Rodney G. Downey and Michael R. Fellows. Fundamentals of Parameterized Complexity. Texts in Computer Science. Springer, 2013.
- [Elkind et al., 2012] Edith Elkind, Piotr Faliszewski, and Arkadii Slinko. Clone structures in voters' preferences. In Proceedings of the 13th ACM Conference on Electronic Commerce (EC), pages 496-513. ACM, 2012.
- [Elkind et al., 2016] Edith Elkind, Martin Lackner, and Do- minik Peters. Preference restrictions in computational social choice: Recent progress. In Proceedings of the 25th Inter- national Joint Conference on Artificial Intelligence (IJCAI), pages 4062-4065, 2016. IJCAI
- [Elkind et al., 2017] Edith Elkind, Martin Lackner, and Do- minik Peters. Structured preferences. In U. Endriss, editor, Trends in Computational Social Choice, chapter 10, pages 187-207. AI Access, 2017.
- [Erdélyi et al., 2017] Gábor Erdélyi, Martin Lackner, and An- dreas Pfandler. Computational aspects of nearly single- peaked electorates. Journal of Artificial Intelligence Re- search, 58:297-337, 2017.
- [Faliszewski et al., 2014] Piotr Faliszewski, Edith Hemas- paandra, and Lane A. Hemaspaandra. The complexity of manipulative attacks in nearly single-peaked electorates. Artificial Intelligence, 207:69-99, 2014.
- [Garey et al., 1976] Michael R. Garey, David S. Johnson, and Larry J. Stockmeyer. Some simplified NP-complete graph problems. Theoretical Computer Science, 1(3):237-267, 1976.
- [Healey, 2008] Joseph F. Healey. Statistics: A Tool for Social Research. Cengage Learning, 2008. 8th edition.
- [Jaeckle et al., 2018] Florian Jaeckle, Dominik Peters, and Edith Elkind. On recognising nearly single-crossing pref- erences. In Proceedings of the 32nd AAAI Conference on Artificial Intelligence (AAAI), pages 1079-1086, 2018.
- [Mirrlees, 1971] James A Mirrlees. An exploration in the the- ory of optimum income taxation. The Review of Economic Studies, 38(2):175-208, 1971.
- [Skowron et al., 2015] Piotr Skowron, Lan Yu, Piotr Fal- iszewski, and Edith Elkind. The complexity of fully propor- tional representation for single-crossing electorates. Theo- retical Computer Science, 569:43-57, 2015.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
A key task of social science is to understand and explain people's preferences and attitudes. A psychologist might ask survey takers how much they agree with a statement on a 1-10 scale (from "disagree" to "agree"). The researcher can then compute correlations between this quantity and participants' attributes such as age, income, or educational attainment.
This way of explaining attitudes and preferences in terms of attributes has proved powerful-but it is intrinsically limited. In particular, this method cannot easily explain complex preferences that are not captured by a single numerical response. For example, suppose we want to ask participants to rank various forms of energy generation (such as coal, solar, nuclear) in terms of desirability in their country's energy mix. We might suspect people's answer to be mainly a function of their education level, or maybe of their left-right political orientation. How can we check this?
Statistics textbooks [e.g., de Vaus, 2002, p. 103] would recommend handling each energy source independently, and find the correlation between participants' education level (maybe expressed as number of school years) and the rank of the alternative in their ranking. A first complaint might be that this approach cardinalises inherently ordinal information, but there are notions of correlation for ordinal measures (e.g., Healey, 2008, Sec. 14.6; for example, take the Kendall tau distance between ordering people by education and ordering them by how they rank the alternative). A more severe problem of the approach is that it ignores the finer structure of the preferences, by considering each alternative on its own. Fundamentally, this approach only answers questions like "do more-educated people like solar more?" and not "are people's preferences over all energy sources well-explained by their education level?"
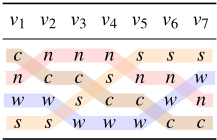
What would be a better way to answer questions of the latter type? We use the lens of social choice theory, a well-developed literature on handling preferences. While its main focus is on preference aggregation, parts of it can be repurposed for the goal of understanding preferences. This is particularly true for work concerning structured preferences, which have received much recent attention from computer scientists [Elkind et al., 2016; 2017]. Our focus in this paper is a concept called singlecrossing preferences, which goes back to work on income taxation [Mirrlees, 1971]. It turns out to be particularly relevant for our goal of "correlating" preferences and attributes.
Suppose we have obtained rankings from 7 participants over coal, nuclear, wind, and solar (c; n; w; s respectively). In Figure 1, we write these rankings as columns, and sort them left-to-right by the voter attribute. The coloured lines track the rank of each alternative and show an intriguing feature: any two of these 'trajectories' cross only once. For example, people on the left prefer wind to solar and people on the right prefer solar to wind; and a similar pattern holds for every pair of alternatives. This is the single-crossing property. In our view, this property implies that the rankings have been sorted "correctly", and it is easy to check that a single-crossing order is always unique (up to mirroring and reordering identical votes). Thus, we hold that an attribute that orders people as shown "perfectly correlates" with the preferences.
In profiles with a large number of agents, there may not exist an ordering which makes the profile single-crossing, either due to noise or due to intrinsic complexity of the preferences. Still, some orderings might be better than others, in the sense of making the profile almost single-crossing. In this paper, we propose a way to measure the quality of different orderings in terms of notions of distance to being single-crossing.
To be concrete, suppose we are given a profile of rankings which are ordered in a fixed way (e.g., sorted by an exogenously given attribute). This profile is not single-crossing. How far away is it? A natural measure is provided by the Kendall tau distance: we ask how many times we need to swap two adjacent alternatives in one of the rankings until the profile is single-crossing ("global swaps"). Instead of counting the total number of swaps, we can also count the maximum number of swaps applied to any single ranking ("local swaps"). More coarse measures can also be sensible: for example, some of the rankings may be outliers, so we can count the number of rankings that need to be deleted until the rest is single-crossing ("voter deletion"). We consider some other distances as well; the best choice of distance will depend on the context.
Compared to the traditional method of computing correlations independently for each alternative, our proposals are more combinatorial and complex. In fact, it is not clear how to compute these distance measures efficiently. While we develop an efficient algorithm to evaluate the voter deletion distance, for most other metrics we prove that evaluation is NP-hard (see Table 1). This should not be a major impediment to using our notions in practice, and we show that evaluating the swap-based metrics becomes easy (in the FPT or XP sense) if the profile in question is very close to being single-crossing.
The literature on structured preferences has introduced and studied problems similar to ours. The most popular notion of structure is single-peakedness, which assumes that the alternative space is one-dimensional. The concept of nearly single-peaked preferences was suggested by Faliszewski et al. [2014], and then a number of authors have considered the complexity of identifying preferences that are nearly singlepeaked [Erdélyi et al., 2017; Bredereck et al., 2016; Elkind et al., 2012; Cornaz et al., 2013], i.e., can be made singlepeaked by deleting a few voters or alternatives, merging small groups of similar alternatives, performing a few swaps of adjacent alternatives in voters' rankings, or partitioning voters or candidates into a few groups so that the profile is singlepeaked when restricted to one of these groups. Nearly singlecrossing preferences have also been studied [Bredereck et al., 2016; Jaeckle et al., 2018]. However, those papers focused on a setting that is crucially different: they do not fix the ordering of the rankings, so the algorithms may rearrange them arbitrarily to obtain a single-crossing profile. That regime makes sense for voting, if we are aiming to use fast winner determination algorithms that require single-crossing input [e.g., Skowron et al., 2015], but it is not relevant for our aim of quantifying the explanatory power of a given voter attribute.
For consistency with the literature on nearly structured preferences, in what follows we will use the terminology of computational social choice; for example, we refer to agents as voters. Due to space constraints, we omit some proofs.
2 Preliminaries
For an integer n, we write »n… = f1 ; : : : ; ng.
Preferences. Let A be a finite set of alternatives. A linear order v over A is a binary relation that is asymmetric, total, and transitive. We write L"A" for the set of linear orders over A. A profile P = "v1; : : : ; vn" is a list of linear orders; we write jPj = n and refer to elements of P as votes, and to elements of »n… as voters. We write a �i b when "a; b" 2 vi, i.e., when voter i prefers a to b. Let P"A" denote the set of all profiles over A. Given t profiles P1; : : : ; Pt 2 P"A", let P1+� � �+Pt be the profile obtained by concatenating P1; : : : ; Pt (in the given order); if P1 = � � � = Pt = P, we write tP for P1 + � � � + Pt . Let X � A be a subset of alternatives. For a linear order v, we write vjX = v \ "X � X", and for a profile P, we write PjX = "v1jX; : : : ; vnjX"; vjX and PjX are, respectively, the linear order and the profile obtained by restricting the alternative set to X. Given a subset I � »n…, we denote by PI the profile obtained from P by deleting all voters in »n… n I.
Single-crossing profiles. A profile P 2 P"A" is singlecrossing (in the given order) if for each pair a; b 2 A of alternatives such that a �1 b there is some i 2 »n… such that a �j b for all j 2 »i… and b �j a for all j 2 »n…n»i…. We say that a profile P is single-crossing up to a permutation if the votes in P can be permuted so that the resulting profile is singlecrossing in the given order. Given a profile P 2 P"A", jPj = n, we say that a pair of alternatives fa; bg is multi-crossing if there exist i; j; k 2 »n…, i < j < k, such that a �i b, b �j a, a �k b. Note that a profile is single-crossing in the given order if and only if no pair of alternatives is multi-crossing.
Graph-theoretic background. An undirected graph is a pair G = "A; L", where A is a set of vertices and L is a collection of size-two subsets of A, which are referred to as edges. A vertex set X � A is an independent set if for every a; b 2 X we have fa; bg < L. A mapping � : A ! »k… is a k-colouring of G if for each i 2 »k… the set fa 2 A j �"a" = ig is an independent set. A graph G = "A; L" is s-regular if for each a 2 Awe have jfe 2 L j a 2 egj = s. We denote the set of all graphs with vertex set fa1; : : : ; amg by Gm.
Parameterisedcomplexity. Apopular approach todealwith NP-complete problems is to consider their complexity as a function of certain problem parameters [see, e.g., Downey and Fellows, 2013], such as the number of alternatives or voters. Problems that admit algorithms whose running time is of the form f "p"poly"n", where p is the value of the parameter, f is a computable function, and n is the instance size, are called fixed parameter-tractable (FPT) with respect to p; these are the 'easiest' problems in the parameterised sense. A problem belongs to the complexity class XP with respect to p if it can be solved in polynomial time for each fixed value of p (it admits an algorithm with running time n f "p" for a computable function f ). Clearly, FPT� XP.
3 Pairwise Swaps
We begin with our most fine-grained distance concepts, namely, the ones that are based on swaps. Swapping a pair of adjacent alternatives is, arguably, a minimal change to a preference profile, and so it makes sense to count the number of such changes as a distance. This yields the Kendall tau distance, which counts the number of pairs of alternatives on which two linear orders disagree. This distance model is also well-motivated when voters' preferences are noisy, and this is the reason why the profile is not single-crossing. Formally, given two votes vi; vj , we define dK"vi; vj " = j�"vi; vj "j, where �"vi; vj" = ffa; bg j a �i b; b �j ag. This distance can be extended to n-voter profiles: if P = "v1; : : : ; vn" and Q = "u1; : : : ; un", we set dK"P;Q" = ˝ i2»n… dK"vi; ui". The egalitarian, or '0, variant of this distance uses the maximum number of swaps per voter: degal"P; Q" = maxi2N d"vi; ui".
| Computational problem | Recognition | Small n and parameterised |
|---|---|---|
| Alternative Deletion k-Alternative Partition Global Swaps Local Swaps Voter Deletion Contiguous Voter Partition Interleaving Voter Partition Voter Reordering | NPc (Th.6) NPc (Th.6) NPc (Th.1) NPc (Th.2) O"n 3 m 2 " (Pr.12) O"nm 2 " (Pr.12) ? O"n"logn+m 2 "" (Pr.14) | NPc for n > 4 (Th.7), in P for n = 3 (Cor.9), FPT wrt k (Pr.5) NPc for n > 4 (Th.8), in P for n = 3 (Cor.9) or k = 2 (Pr.5) FPT wrt k (Th.3) XP wrt k (Cor.4) n/a n/a XP wrt k (Th.13) n/a |
These definitions suggest the following decision problems.
Definition 1. An instance of Global Swaps (respectively, Local Swaps) problem is given by a profile P and an integer k. It is a yes-instance if and only if there exists a profile Q that is single-crossing in the given order and satisfies dK"P; Q" 6 k (respectively, degal"P;Q" 6 k).
We will show that both of these problems are NP-complete. Our proof is by reduction from the problem of computing, respectively, the Kemeny distance and the egalitarian Kemeny distance. Thus, we reduce from one voting problem to another, and this allows the proof to be short and simple.
A profile P = "v1; : : : ; vn" is unanimous if vi = vj for all i; j 2 »n…. An instance of Kemeny score (respectively, Egalitarian Kemeny score) is given by a profile P and an integer s; it is a yes-instance if there exists a unanimous profile Q with dK"P; Q" 6 s (respectively, with degal"P; Q" 6 s). Both of these problems are NP-complete [Bartholdi III et al., 1989; Biedl et al., 2009].
Theorem 1. Global Swaps is NP-complete.
Proof. This problem is clearly in NP. To prove NP-hardness, we reduce from Kemeny score. We map an instance hP; si of Kemeny score with P 2 P"A", jAj = m, to an instance htP; tsi of Global Swaps, where t = "s + 1" � m 2 � + 1.
If hP; si is a yes-instance of Kemeny score, there is a unanimous profile Q with dK"P; Q" 6 s. So tQ is unanimous and hence single-crossing in the given order, and dK"tP; tQ" 6 ts. Hence htP; tsi is a yes-instance of Global Swaps.
Conversely, suppose htP; tsi is a yes-instance of Global Swaps, and R is a profile that is single-crossing in the given order and satisfies d"tP; R" 6 ts. Split R as R1+� � �+Rt , jRj j = n for each j 2 »t…. We say that the i-th vote in R is a crossing point for alternatives a; b 2 A if the i-th voter in R prefers a to b, while the "i + 1"-st voter prefers b to a. Since R is singlecrossing in the given order, there is at most one crossing point for each pair fa; bg � A, and hence at most � m 2 � crossing points altogether. Let J = f j 2 »t… j Rj contains no crossing pointsg. Then jJj > t � � m 2 � > 1. Now, if dK"P; Rj" > s for all j 2 J, we can lower-bound dK"tP; R" as
a contradiction. Hence, dK"P; Rj" 6 s for some j 2 J. Since Rj contains no crossing points, it is unanimous, which means that we started with a yes-instance of Kemeny score. �
A similar reduction from Egalitarian Kemeny score shows that Local Swaps is also hard.
Theorem 2. Local Swaps is NP-complete.
On the positive side, Global Swaps turns out to be fixedparameter tractable with respect to the number of swaps.
Theorem 3. Global Swaps is in FPT with respect to k.
Proof. We use the bounded search tree technique. Specifically, we describe an algorithm that starts with a budget of k swaps and aims to transform P into a profile that is single-crossing in the given order. It makes some non-deterministic choices, but the number of such choices at each decision node can be bounded by a function that depends on k only; the algorithm rejects a given non-deterministic branch if it has already performed k swaps along this branch, but has not obtained a single-crossing profile yet. This algorithm can be simulated by a deterministic algorithm that explores all branches of non-determinism in order of depth-first search.
Throughout the algorithm, we label some triples "i; a; b", where i 2 »n… and a; b 2 A as fixed; intuitively, once a triple has been fixed, we cannot change the preferences of voter i over the pair fa; bg. Initially, the set of fixed triples is empty.
Given a voter i and two alternatives a; b 2 A such that a �i b, we denote by i»a; b… the set of alternatives that i ranks between a and b (including a and b). We modify voters' preferences while executing the algorithm; the set i»a; b… is defined with respect to the current preferences of voter i.
The algorithm maintains a stack of pairs of alternatives fa; bg. At the beginning of the algorithm, we push all pairs of alternatives that are multi-crossing in P onto this stack. At each stage of the algorithm we pop one pair of alternatives off the stack and change some voters' preferences so that this pair is no longer multi-crossing; the swap budget is updated to account for these changes, and we reject if we run out of budget or if it is clear that the current pair cannot be 'fixed' within the remaining budget. As a result of our changes, some new pairs of alternatives may become multi-crossing, and they are then pushed on the stack. The algorithm returns 'yes' if for some sequence of non-deterministic choices it can reach a state where at the end of a stage the stack is empty.
It remains to describe what we do once we have popped some pair fa; bg off the stack. Let r be the remaining swap budget at this point, i.e., we assume that the algorithm has already performed k � r swaps.
We say that i 2 f0g [ »n… is a crossing point for fa; bg if (1) i = 0, (2) i = n, or (3) 0 < i < n and voters i and i + 1 disagree on fa; bg, i.e., a �i b, b �i+1 a. Let "i1; : : : ; it ", i1 < � � � < it , be the ordered list of crossing points for fa; bg. For each ' 2 »t � 1…, all voters between i' + 1 and i' +1 agree on fa; bg, i.e., the list of voters can be split into t � 1 intervals, where all voters in the same interval agree on fa; bg. Note that a single swap reduces the number of intervals by at most 2 (e.g., if two intervals where all voters prefer a to b are separated by a single voter who prefers b to a, swapping b and a in the preferences of that voter merges these three intervals into one). Thus, if t � 1 � 2r > 2, we can safely reject, as a and b will necessarily remain multi-crossing after we perform r or fewer swaps. Thus, from now on we assume that t 6 2r +2 6 2k +2.
Now, we have to 'fix' the pair fa; bg so that there is at most one crossing point. To this end, we non-deterministically guess the first voter's preference over the pair fa; bg and the new crossing point i 2 »n… (i = n corresponds to the case where all voters agree on fa; bg); these two guesses completely determine all voters' preferences over fa; bg. Importantly, i need not belong to fi1; : : : ; it g, but we can limit our guesses for i to lie within an r-neighborhood of some existing crossing point for fa; bg, i.e., we will only consider values of i such that ji � i' j 6 r for some ' 2 »t…. Indeed, if ip < i < ip+1 and i�ip > r, ip+1�i > r, then, tomake i the unique crossing point, we would have to swap a and b in the preferences of all voters ip + 1 ; : : : ; i or in the preferences of all voters i + 1 ; : : : ; ip+1, i.,e., perform more than r swaps. This means that we only have to consider "2r + 1"t 6 "2k + 1""2k + 2" positions for the new crossing point; this quantity does not depend on n or m.
Let us say that a voter i is bad if her current preferences over fa; bg are different from what is implied by our guess for the crossing point and the preferences of the first voter; denote the set of all bad voters by B. Next, we would like to swap a and b in the preferences of the bad voters. There is a difficulty, however: if for some voter i 2 B alternatives a and b are not adjacent in i's current vote, i.e., if ji»a; b…j > 2, changing i's preferences over fa; bg results in preferences that are not transitive. If we want i's preferences to be a (transitive) linear order, each alternative in i»a; b… n fa; bg would have to be swapped with a or b. This means, in particular, that we can reject if ji»a; b…j > r + 2 for some bad voter i, so from now on we assume that ji»a; b…j 6 r + 2 for each i 2 B.
Now, we process the voters in B one by one. For each i 2 B we non-deterministically guess an ordering of all alternatives in i»a; b… in i's preferences; for a given voter, there are at most ji»a; b…j j 6 "r + 2"! 6 "k + 2"! options to consider. We reject our guess if (1) it does not swap a and b, or (2) the Kendall tau distance between the new vote for i and her current vote exceeds r, or (3) our guess is inconsistent with the current set of fixed triples: i.e., c �i d, "i; c; d" is a fixed triple, and we have guessed a permutation of i»a; b… where d is placed above c. Otherwise, we reorder the alternatives in i»a; b… in the ranking of voter i according to our guess, and add all triples of the form "i; c; d", c; d 2 i»a; b…, to the set of fixed triples.
Once we have processed all voters in B, the pair fa; bg is no longer multi-crossing; however, some other pairs may have become multi-crossing. Thus, once all voters in B have been processed, we scan the resulting profile and add all the newly multi-crossing pairs to the stack. This completes the description of a single stage of our algorithm.
It is immediate that our algorithm only accepts if it has identified a profile that is single-crossing in the given order and can be obtained from P by performing at most k swaps. Conversely, we only reject if each non-deterministic branch is eventually rejected, and this only happens if every choice we consider does not result in a single-crossing profile after k or fewer swaps. As we have argued that our algorithm explores all options that may possibly lead to a positive answer, this establishes correctness. For the analysis of running time, we observe that each non-deterministic branch performs at most k swaps and executes some fairly simple operations between the swaps. Further, the number of non-deterministic choices at each point is bounded by a function of k. This implies the desired bound on the running time. �
For Local Swaps, we do not know if this problem is in FPT with respect to k. However, Jaeckle et al. [2018] show that the analogue of this problem for preferences that are singlecrossing up to a permutation is in XP with respect to k. This proof can be modified to apply to our setting.
Corollary 4. Local Swaps is in XP with respect to k.
We note that (Egalitarian) Kemeny score is known to be NP-hard even for n = 4, but our reductions do not preserve the number of voters. We conjecture that Global Swaps and Local Swaps remain hard for small values of n.
4 Alternative Deletion and Partition
In this section, we consider two notions of distance to singlecrossing preferences that are based on modifying the set of alternatives. The first measure asks how many alternatives need to be deleted to make the given profile single-crossing; the second measure asks for the smallest value k such that the alternatives can be split into k groups so that restricting the voters' preferences to each group results in a profile that is single-crossing in the given order. Both of these measures have been considered in the context of profiles that are nearly single-peaked or single-crossing up to a permutation [Erdélyi et al., 2017; Bredereck et al., 2016; Jaeckle et al., 2018].
Definition 2. An instance of Alternative Deletion is given by a profile P 2 P"A" and an integer k > 1. It is a yes-instance if and only if there is a subset X � A with jXj > jAj � k such that PjX is single-crossing in the given order.
Definition 3. An instance of k-Alternative Partition is given by a profile P 2 P"A". It is a yes-instance if and only if A can be partitioned into k sets A1; : : : ; Ak so that for each j 2 »k… the profile PjAj is single-crossing in the given order.
In a companion paper [Cohen et al., 2019] we introduce a mapping between preference profiles and undirected graphs that is useful for analysing the problems we consider here. Specifically, given a profile P 2 P"A", we define its crossing graph as an undirected graph G = "A; L" such that fa; bg 2 L if and only if fa; bg is a multi-crossing pair in P. Note that P can be made single-crossing by deleting a subset of alternatives X � A if and only if X is a vertex cover of G; similarly, a partition of A into k sets such that the restriction of A to each set is single-crossing corresponds to a k-coloring of G. Since Vertex Cover is in FPT with respect to the target cover size k, and one can decide in polynomial time whether a graph is 2-colourable, we obtain the following easiness results.
Proposition 5. Alternative Deletion is in FPT with respect to k, and 2-Alternative Partition is in P.
Cohen et al. [2019] prove, conversely, that any undirected graph on m vertices is a crossing graph of a preference profile with O"m" voters. The following hardness result is a corollary.
Theorem 6 (Cohen et al., 2019). Alternative Deletion is NP-complete. k-Alternative Partition is NP-complete for k > 3.
A limitation of the technique introduced by Cohen et al. [2019] is that the construction behind Theorem 6 requires an unbounded number of voters. We strengthen Theorem 6 by showing that these problems remain hard even for a small constant number of voters, namely even for n = 4 voters.
Theorem 7. For every n > 4, Alternative Deletion remains NP-complete when restricted to instances with n voters.
Proof. We reduce from the Independent Set problem. This problem remains NP-hard for 3-regular graphs [Garey et al., 1976]; thus, in our reduction we assume that the input graph G is 3-regular. We establish hardness for n = 4; the result can be extended to any n > 4 by creating additional n � 4 copies of the last vote. Consider an instance hG; ki of Independent Set, where G = "A; L", A = fa1; : : : ; amg, L = fe1; : : : ; esg and G is 3-regular. For every edge e = fai; aj g we create two alternatives c"e; i" and c"e; j" and set C e = fc"e; i"; c"e; j"g; also, for each ai 2 A we create two alternatives di and d 0 i . For each ai 2 A, let Ci = fc"e; i" j ai 2 eg and Di = fdi; d 0 i g; note that jCi j = 3, since G is 3-regular.
We will now describe the profile P. For readability, we first explain how voters rank various groups of alternatives, and then describe their preferences within these groups.
The first two voters' rankings are of the form
the third voter's ranking is of the form
and the fourth voter's ranking is of the form
the order of alternatives within each group is described next.
For each ai 2 A all voters rank the alternatives in Di as di � d 0 i . For each e = fai; aj g 2 L with i < j, set c"e; i" �1 c"e; j", c"e; j" �2 c"e; i". Now, fix an i 2 »m… and suppose that Ci = fc"ex; i"; c"ey; i"; c"ez; i"g, where x < y < z. The third and the fourth voter rank the alternatives in Ci as c"ex; i" � c"ey; i" � c"ez; i".
In the resulting profile for each e = fai; aj g 2 L the alternatives c"e; i" and c"e; j" are multi-crossing; also, for each ai 2 A every pair fc; dg with c 2 Ci; d 2 Di is multi-crossing. No other pair of alternatives is multi-crossing.
Suppose X � A is an independent set of size s in G. Let
Then jY j = 3jXj + 2"m � jXj" = 2m + s, and PjY is singlecrossing in the given order. Conversely, suppose that there is a set of alternatives Z, jZj > 2m + s, such that PjZ is single-crossing in the given order. Let X = fai 2 A j Ci � Zg. Then X is an independent set in G: if e = fai; aj g � X for some e 2 L then C e � Z, a contradiction with PjZ being single-crossing in the given order. We will now show that jXj > s. Note that for each i 2 »m… we have Z \ Ci = � or Z \ Di = � and hence jZ \ "Ci [ Di"j 6 3 and, moreover, jZ \ "Ci [ Di"j = 3 if and only if Ci � Z, i.e., ai 2 X. We have 2m + s 6 jZj 6 3jXj + 2"m � jXj" and hence jXj > s. Thus, hG; si is a yes-instance of Independent Set if and only if hP; 2m+ si is a yes-instance of Alternative Deletion. �
The proof for alternative partition is similar.
Theorem 8. For each n > 4 and each k > 3, k-Alternative Partition remains NP-complete when restricted to instances with n voters.
Now, clearly, Alternative Partition and Alternative Deletion are easy for n = 2, as every 2-voter profile is singlecrossing. It turns out that the remaining case n = 3 is easy, too, for an interesting graph-theoretic reason: Cohen et al. [2019] prove that crossing graphs of 3-voter profiles are perfect (for a definition of perfect graphs see, e.g., Diestel, 2012). The problems of finding a vertex cover or a k-colouring are in P for perfect graphs, and so we obtain the following corollary, which shows that the hardness results in Theorems 7 and 8 are tight with respect to the number of voters.
Corollary 9 (Cohen et al., 2019). Alternative Deletion and k-Alternative Partition are polynomial-time solvable when restricted to instances with three voters.
5 Voter Deletion, Partition and Reordering
Finally, we look at distance measures that alter the set of voters.
Definition 4. An instance of Voter Deletion is given by a profile P 2 P"A", jAj = m, jPj = n, and an integer k > 1. It is a yes-instance if and only if there is a subset I � »n… with jI j > n � k such that PI is single-crossing in the given order.
Bredereck et al. [2016] give a dynamic program for the voter deletion problem aiming for single-crossing up to a permutation. The same idea works in our setting.
Proposition 10. Voter Deletion can be solved in time O"n 3 m 2 ".
We can also partition voters into several single-crossing subprofiles. We define two variants of this problem: in the first variant, each part of the partition must form a contiguous block, and in the second variant parts may interleave.
Definition 5. An instance of Contiguous Voter Partition is given by a profile P 2 P"A", jAj = m, jPj = n, and an integer k > 1. It is a yes-instance if and only if there exist k profiles P1; : : : ; Pk such that Pj is single-crossing in the given order for each j 2 »k… and P = P1 + � � � + Pk.
Definition 6. An instance of Interleaving Voter Partition is given by a profile P 2 P"A", jAj = m, jPj = n, and an integer k > 1. It is a yes-instance if and only if the set »n… can be partitioned into k sets I1; : : : ; Ik so that for each j 2 »k… the profile Pj obtained from P by removing the voters in fvi j i 2 »n… n Ij g is single-crossing in the given order.
These two problems seem different from a complexity perspective: Contiguous Voter Partition can be solved by a simple greedy algorithm, but we do not know if Interleaving Voter Partition is in P. However, the latter problem is in the class XP with respect to k. Our analysis makes use of the following simple lemma [see, e.g., Jaeckle et al., 2018, Sec. 2].
Lemma 11. Let P = "v1; : : : ; vn" 2 P"A" be a single-crossing profile. Let vn+1 be a vote in L"A". Then P + "vn+1" is single-crossing in the given order if and only if "v1; vn; vn+1" is.
Proposition 12. Contiguous Voter Partition can be solved in time O"nm 2 ".
Proof. Let P = "v1; : : : ; vn". We construct the profiles P1; : : : ; Pk greedily. Initially we set j = 1, P1 = �. We process the votes in P from left to right. When considering the vote vi, we check whether Pj + "vi" is single-crossing in the given order (this can be done in time O"m 2 " by Lemma 11). If yes, we set Pj := Pj + "vi" and otherwise we set j := j + 1, Pj = "vi". We stop once all votes have been processed, and output the number of subprofiles in our partition. We omit the proof of correctness. �
Theorem 13. Interleaving Voter Partition can be solved in time O"n 2k+3 m 2 ".
Proof. We guess k voters f1; : : : ; fk; we then check if there is an interleaving partition such that the first voter in part j is fj , for j 2 »k…. Note that there are at most n k guesses to consider. We then proceed by dynamic programming. For each i 2 »n… and '1; : : : ; 'k 2 »i… [ f?g, let A»i; '1; : : : ; 'k… = 1 if there is a partition of »i… into k pairwise disjoint sets I1; : : : ; Ik such that for each j 2 »k… it holds that PIj is single-crossing in the given order, 'j = ? if and only if fj > i, and, moreover, if fj 6 i then the first voter in Ij is fj and the last voter in Ij is 'j ; otherwise, let A»i; '1; : : : ; 'k… = 0.
For i = 1, we have A»i; '1; : : : ; 'k… = 1 if and only if there is a j 2 »k… with fj = 'j = 1, 't = ? for t 2 »k… n f jg. For i > 1 we have A»i; '1; : : : ; 'k… = 1 if and only if i = 'j for some j 2 »k… and either (1) A»i � 1; '1; : : : ; 'j�1; ?; 'j+1; : : : ; 'k… = 1 and fj = i or (2) A»i � 1; '1; : : : ; 'j�1; t; 'j+1; : : : ; 'k… = 1 for some t , ? and "vfj ; vt; v'j " is single-crossing in the given order. Here, case (1) corresponds to a partition of »i… in which i is a singleton and case (2) corresponds to a partition where i is appended to an existing part. The correctness of this expression follows from Lemma 11. For each initial guess, our dynamic program has O"n k+1 " variables, and each variable can be computed in time O"n 2 m 2 ". This implies our bound on the running time. �
Suppose we are given a profile that can be made singlecrossing by rearranging the voters according to a permutation � . Then we can measure how good the input order is by the number of voter swaps performed by � .
Definition 7. An instance of Voter Reordering is given by a profile P and an integer k. It is a yes-instance if we can perform at most k successive swaps of adjacent voters to make P single-crossing in the given order.
This problem turns out to be polynomial-time solvable.
Proposition 14. Voter Reordering can be solved in time O"nm 2 + n log n".
6 Discussion and Conclusions
We have suggested a way of correlating voters' attributes with preferences, which in formal terms is the problem of deciding whether an input profile is close to being single-crossing in the given order. Let us close the paper by discussing technical connections to previous work on almost structured preferences. As with other papers on this topic, we have focused on computational issues, and have determined the problems' complexity for most notions of closeness that have been considered in the literature. Due to space constraints, we did not analyse closeness measures that are based on collapsing similar alternatives [Elkind et al., 2012; Cornaz et al., 2013]; it can be shown that the respective decision problems admit simple polynomial-time algorithms.
From the complexity perspective, our results for the fixed voter order essentially mirror the known results for deciding if a profile is nearly single-crossing up to a permutation: e.g., alternative deletion/partition is hard and voter deletion is easy in both settings, and our hardness results for global and local swaps can easily be extended to the setting where voters can be permuted. There are, however, a few cases where we obtained a positive algorithmic result for our setting, but it is not clear how to extend it to the setting where permutations are allowed; this is the case, e.g., for our FPT algorithm for Global Swaps or our XP algorithm for Interleaving Voter Partition. On the other hand, there are no examples of problems that become computationally harder when the voter order is fixed.
In contrast, in the context of single-peaked preferences, knowing the axis reduces the complexity considerably, as shown by Erdélyi et al. [2017]. Thus, for nearly single-peaked preferences the main computational challenge is to determine the right axis, whereas the complexity of identifying nearly single-crossing preferences when the order of the voters is not known stems both from having to determine the order of voters and from figuring out the optimal modifications to the votes.
Acknowledgments
This research was supported by ERC grant ACCORD 639945 (Elkind, Peters) and a Felix Scholarship (Lakhani). We thank Martin Lackner for discussions that initiated this work.
@inproceedings{ijcai2019p59,
  title     = {Correlating Preferences and Attributes: Nearly Single-Crossing Profiles},
  author    = {Lakhani, Foram and Peters, Dominik and Elkind, Edith},
  booktitle = {Proceedings of the Twenty-Eighth International Joint Conference on
               Artificial Intelligence, {IJCAI-19}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Sarit Kraus},
  pages     = {414--420},
  year      = {2019},
  month     = {8},
  note      = {Main track},
  doi       = {10.24963/ijcai.2019/59},
  url       = {https://doi.org/10.24963/ijcai.2019/59},
}
TY - CPAPER TI - Correlating Preferences and Attributes: Nearly Single-Crossing Profiles AU - Lakhani, Foram AU - Peters, Dominik AU - Elkind, Edith T2 - Proceedings of the Twenty-Eighth International Joint Conference on Artificial Intelligence, IJCAI-19 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2019 SP - 414 EP - 420 DO - 10.24963/ijcai.2019/59 UR - https://doi.org/10.24963/ijcai.2019/59 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





