
BN-invariant Sharpness Regularizes the Training Model to Better Generalization
Proceedings of the Twenty-Eighth International Joint Conference on Artificial Intelligence. Main track. Pages 4164-4170.
https://doi.org/10.24963/ijcai.2019/578
Keywords
- Machine Learning: Deep Learning
- Machine Learning: Explainable Machine Learning
- Machine Learning: Learning Theory
Abstract
It is arguably believed that flatter minima can generalize better. However, it has been pointed out that the usual definitions of sharpness, which consider either the maxima or the integral of loss over a delta ball of parameters around minima, cannot give consistent measurement for scale invariant neural networks, e.g., networks with batch normalization layer. In this paper, we first propose a measure of sharpness, BN-Sharpness, which gives consistent value for equivalent networks under BN.
It achieves the property of scale invariance by connecting the integral diameter with the scale of parameter. Then we present a computation-efficient way to calculate the BN-sharpness approximately i.e., one dimensional integral along the "sharpest" direction. Furthermore, we use the BN-sharpness to regularize the training and design an algorithm to minimize the new regularized objective. Our algorithm achieves considerably better performance than vanilla SGD over various experiment settings.
- [Allen-Zhu et al., 2018] Zeyuan Allen-Zhu, Yuanzhi Li, and Zhao Song. A convergence theory for deep learning via over-parameterization. arXiv preprint arXiv:, 2018.
- [Boumal et al., 2017] Nicolas Boumal, Absil Pierre- Antoine, and Coralia Cartis. Global rates of convergence for nonconvex optimization on manifolds. arxiv preprint arxiv:1605.08101, 2017.
- [Chaudhari et al., 2017] Pratik Chaudhari, Anna Choroman- ska, Stefano Soatto, Yann LeCun, Carlo Baldassi, Chris- tian Borgs, Jennifer Chayes, Levent Sagun, and Riccardo Zecchina. Entropy-sgd: Biasing gradient descent into wide valleys. In ICLR'2017 arXiv:1611.01838, 2017.
- [Cho and Lee, 2018] Minhyung Cho and Jaehyung Lee. Rie- mannian approach to batch normalization. arXiv preprint arXiv:1709.09603, 2018.
- [Choromanska et al., 2015] Anna Choromanska, Mikael Henaff, Michael Mathieu, Gérard Ben Arous, and Yann LeCun. The loss surfaces of multilayer networks. In- ternational Conference on Artificial Intelligence and Statistics(AISTATS 2015), 2015.
- [De et al., 2017] Soham De, Abhay Yadav, David Jacobs, and Tom Goldstein. Automated inference with adaptive batches. International Conference on Artificial Intelli- gence and Statistics(AISTATS 2017), 2017.
- [Dinh et al., 2017] Laurent Dinh, Razvan Pascanu, Samy Bengio, and Yoshua Bengio. Sharp minima can generalize for deep nets. In ICML'2017 arXiv:1703.04933, 2017.
- [Du et al., 2018] Simon S. Du, Jason D. Lee, Haochuan Li, Liwei Wang, and Xiyu Zhai. Gradient descent finds global minima of deep neural networks. arXiv preprint arXiv:1811.03804, 2018.
- [Hoffer et al., 2017] Elad Hoffer, Itay Hubara, and Daniel Soudryn. Train longer, generalize better: closing the gen- eralization gap in large batch training of neural networks. Advances in Neural Information Processing Systems 30 (NIPS 2017), 2017.
- [Huang et al., 2017] Lei Huang, Xianglong Liu, Bo Lang, Adams Wei Yu, Yongliang Wang, and Bo Li. Orthogonal weight normalization: Solution to optimization over mul- tiple dependent stiefel manifolds in deep neural networks. arXiv preprint arXiv:1709.06079, 2017.
- [Ioffe and Szegedy, 2015] Sergey Ioffe and Christian Szegedy. Batch normalization: Accelerating deep net- work training by reducing internal covariate shift. In Proceedings of The 32nd International Conference on Machine Learning,ICML, pages 448-456, 2015.
- [Keskar et al., 2017] Nitish Shirish Keskar, Dheevatsa Mudigere, Jorge Nocedal, Mikhail Smelyanskiy, and Ping Tak Peter Tang. On large-batch training for deep learning: Generalization gap and sharp minima. In ICLR'2017 arxiv: 1609.04836, 2017.
- [Krizhevsky et al., 2012] Alex Krizhevsky, Ilya Sutskever, and Geoffrey E Hinton. Imagenet classification with deep convolutional neural networks. In Advances in neural in- formation processing systems, pages 1097-1105, 2012.
- [LeCun et al., 1998] Yann LeCun, Leon Bottou, Yoshua Bengio, and Patrick Haffner. Gradient-based learning ap- plied to document recognition. Proceedings of the IEEE, 86(11):2278 -2324, 1998.
- [Li et al., 2018] Hao Li, Zheng Xu, Gavin Taylor, Christoph Studer, and Tom Goldstein. Visualizing the loss landscape of neural nets. arxiv preprint arXiv:1712.0991, 2018.
- [McAllesterl, 1998] David A. McAllesterl. Some pac- bayesian theorems. In Proceedings of the eleventh annual conference on Computational learning theory, pages 230- 234, 1998.
- [McAllesterl, 1999] David A. McAllesterl. Pac-bayesian model averaging. In Proceedings of the eleventh annual conference on Computational learning theory, pages 164- 170, 1999.
- [McAllesterl, 2003] David A. McAllesterl. Simplified pac- bayesian margin bounds. Lecture notes in computer sci- ence, pages 203-215, 2003.
- [Neyshabur et al., 2017] Behnam Neyshabur, Srinadh Bho- janapalli, David McAllester, and Nathan Srebro. Ex- ploring generalization in deep learning. arXiv preprint arXiv:1706.08947, 2017.
- [Pierre-Antoine and Gallivan, 2006] Absil Pierre-Antoine and Kyle Gallivan. Joint diagonalization on the oblique manifold for independent component analysis. ICASSP, 2006.
- [Pierre-Antoine et al., 2009] Absil Pierre-Antoine, Robert. Mahony, and Rodolphe Sepulchre. Optimization algo- rithms on matrix manifolds. Princeton Press, 2009.
- [Simonyan and Zisserman, 2014] Karen Simonyan and An- drew Zisserman. Very deep convolutional networks for large-scale image recognition. arXiv preprint arXiv:1409.1556, 2014.
- [Wang et al., 2018] Huan Wang, Nitish Shirish Keskar, Caiming Xiong, and Richard Socher. Identifying gen- eralization properties in neural network. arXiv preprint arXiv:1809.07402, 2018.
- [Wen et al., 2018] Wei Wen, Yandan Wang, Feng Yan, Cong Xu, Chunpeng Wu, Yiran Chen, and Hai Lii. Smoothout: Smoothing out sharp minima to improve generalization in deep learning. arXiv preprint arXiv:1805.07898, 2018.
- [Wu et al., 2018] Lei Wu, Chao Ma, and Weinan E. How sgd selects the global minima in over-parameterized learning: A dynamical stability perspective. Advances in Neural In- formation Processing Systems 31 (NeurlPS 2018), 2018.
- [Yuan et al., 2018] Xiaoyong Yuan, Zheng Feng, Matthew Norton, and Xiaolin Lii. Generalized batch normalization: Towards accelerating deep neural networks. arXiv preprint arXiv:1812.03271, 2018.
- [Zhang et al., 2016] Chiyuan Zhang, Samy Bengio, Moritz Hardt, Benjamin Recht, and Oriol Vinyals. Understand- ing deep learning requires rethinking generalization. In ICLR'2017 arXiv:1611.03530, 2016.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
With the support of big data, deep learning techniques has achieved a huge success across domains. In recent years, it becomes a common sense that deep neural networks have perfect training performance. Specifically, [Zhang et al., 2016] empirically shows that the popular neural networks (NN) can always reach zero training error at the end of training process. Moreover, [Du et al., 2018] and [Allen-Zhu et al., 2018] prove that, for the neural networks with sufficient width, gradient descent converges to the global minima of the objective, under some conditions on the data generation. Thus how to find minima taht generalize well seems to be more critical in the study of deep neural network.
It's arguably believed that minima locate in a flat valley generalize better. [Neyshabur et al., 2017] employs the PAC Bayes theory [McAllesterl, 1998] and proves a generalization bound give by "expected sharpness". The conclusion gives us a new angle to discuss generalization error of a neural network. This viewpoint is also empirically confirmed by [Keskar et al., 2017] and [Li et al., 2018]. However, for neural network with scale invariant property, the definitions of sharpness become problematic.
One important case is deep neural network with batch normalization (BN) [Ioffe and Szegedy, 2015]. BN is an important component which normalize the distribution of input to each neuron in the network by mean and standard deviation of input computed over a mini-batch of training data. Batch normalization will bring a scale invariant property to neural network which will make the definition of sharpness for neural network problematic (two parameter points with same generalization error but different sharpness). Since sharpness is related to generalization, a natural question is can we develop an appropriate definition of sharpness for neural network with batch normalization? Meanwhile, can we leverage the appropriate measurement of sharpness to develop an algorithm which helps us find minima generalize better?
In this paper, we answer the two above problems positively. First, we show that the original definition of sharpness for neural network with batch normalization is ambiguous. Specifically, the original sharpness (δ-sharpness) consider the maxima of loss over a δ ball of parameters around minima with radius δ unrelated to parameter θ. However, due to the scale invariant property of neural network with batch normalization, the radius δ should scale with parameter norm θ. On the other hand, the new measurement of sharpness should be computational efficient since we want to leverage it to help us find minima generalize better. Based on the two above points, we propose a "BN-sharpness" to measure the sharpness for BN neural network. In specific, BN-Sharpness is a one dimensional integral of the loss's difference value along the "sharpest" direction in a small neighborhood while the diameter of this neighborhood is related with parameter scale. It's an intuitively thought that a minimum locate in a flat valley when the loss values in the valley are closely with each other along the steepest changing direction.
In order to find minima locate in flat valley which generalize better, we penalize the original optimization objective with BN-Sharpness. Due to the one dimensional integral structure of BN-Sharpness, we can easily acquire the "sharpest direction" by optimization on manifold [Boumal et al., 2017] as well as the gradient of BN-Sharpness.
It's empirically showed that SGD with large batch size tend to produce "sharp" minima which generalize worse [Keskar et al., 2017]. We test our algorithm on CIFAR dataset
[Krizhevsky et al., 2012], it has preferable results under large batch size compared with baselines (SGD, Entropy SGD).
1.1 RelatedWork
Sharpness is a property connected with the loss surface. [Li et al., 2018] first visualize the loss landscape of NN to describe that "sharp" minima indeed generalize worse. Such phenomenon was also empirically confirmed by [Keskar et al., 2017] and [Wu et al., 2018]. [Neyshabur et al., 2017] also gives the conclusion a theoretical interpretation.
In fact, the definition of sharpness is proved to be ambiguous for ReLU neural network [Dinh et al., 2017]. Suffering from the definition of sharpness and computational complexity, some local structured algorithms aimed to produce "flat" minima avoid exactly definition of sharpness. Entropy SGD proposed by [Chaudhari et al., 2017] is motivated by the local geometry of the energy landscape, it alters loss as accumulated "energy value" instead of single point value. [Wen et al., 2018] argues that choosing integral of a small cubic around iterate as loss function can produce a smoother loss function which will lead to a "flat" minimum. [Wang et al., 2018] sets an expected loss function to produce "flatter" minima under PAC Bayes theory. However, all of these algorithms will face a high dimensional integral.
There are lots of sharpness based algorithms to find flat minima [Chaudhari et al., 2017; Wang et al., 2018; Wen et al., 2018]. Since it's hard to compute the gradient of the original sharpness, they set optimization objective as integral of the loss function in a ball to force iterates walking into a flat valley instead of optimizing original loss function regularized by sharpness. This kind of optimization objective involves a high dimensional integral which is actually hard to be computed in practice.
For the topic of neural network with batch normalization, [Cho and Lee, 2018] and [Huang et al., 2017] give Riemannian approach to optimize neural network with batch normalization. [Yuan et al., 2018] propose a general variant of batch normalization to speed up training process. However, none of these works consider combining the sharpness with batch normalization to reduce generalization error.
1.2 Contribution
(1) We show that the generally accepted definition of sharpness: δ-sharpness [Keskar et al., 2017] is ill-posed for NN with BN. We propose a scale invariant and computational efficient "BN-Sharpness" to measure sharpness for NN with BN. (2) We present a computational efficient algorithm based on BN-Sharpness to enhance generalization ability of iterates which has preferable experimental results.
2 Background
2.1 Definitions of Sharpness
There are lots of definitions to describe sharpness [Keskar et al., 2017; Wu et al., 2018]. We focus on a widely discussed definition: δ-sharpness this paper.
Definition 2.1 (δ-Lp sharpness) Let B2(θ, δ) be an Euclidean ball centered on a minimum θ with radius δ. Then, for a non-negative valued loss function L(·) and non-negative number p, the δ-Lp sharpness will be defined as
In fact, denominator of equation (1) will close to 1 when L(θ) is small. Thus, we ignore it during discussion. We can actually prove that δ-sharpness Sδ-sharpness used in [Keskar et al., 2017] is actually δ-L∞ sharpness
2.2 Batch Normalization
We briefly revisit the batch normalization and its properties. A network with BN transforms the input value to a neuron from z = ′Tx to
We can easily verify BN(az) = BN(z) for any a > 0. Then, for a partially batch normalized neural network (Some of input values to neuron are batch normalized) with N parameter vector θ = (θ1, · · · , θN1 , θN1+1, · · · , θN)T , where θi (i = 1 · · ·N1) is parameter vector connected with batch normalized neuron and (θN1+1, · · · , θN) connect neuron without batch normalization. We can actually view the affine parameters γ, β and bias parameters of each neuron as un-batch normalized parameters. We integrate them into parameter vector θ during our latter discussion. In the latter discussion, our analysis is applied to partially batch normalized neural network if we don't give an additional illustration. Now we give the definition of scale transformation for partially batch normalized neural network.
Definition 2.2 T⃗a(·) denote scale transformation for a partially batch normalized neural network with
We see the loss function L(θ) satisfy L(θ) = L(T⃗a(θ)) for any T⃗a(·) 1 . We call this the property of scale invariant of BN. In fact, the ambiguous of sharpness is brought by such property.
3 BN-Sharpness
In this section, we give a δ-BN sharpness to measure sharpness. A well defined geometrical measurement linked with generalization error for neural network with batch normalization should be scale invariant. We start with theorem to explain why the original measurement of sharpness is inappropriate.
Theorem 3.1 Given a partially batch normalized network, δsharpness is not scale invariant.
1 For the situation of Pre-ResNet which has input BN((⃗1+θ)T z) in skip connection layer. It's not a scale invariant layer, we treat these θ as un-batch normalized parameters.
Proof 3.1 For Sδ-sharpness(·), We consider a partially batch normalized neural network, without of loss generality we assume the network has batch normalized neuron in one layer. Then we choose ⃗a as (1, · · · , a0, · · · , a0, 1, · · · , 1)T where a0 locate in the same coordinate with batch normalized parameter. For any δ > 0, we can choose
with L(T⃗a(θ)) = L(θ). Because a parameter θ with one layer zero weight matrix locate in B2(T⃗a(θ), δ) which result in maxθ′∈B2(θ,δ) (L(θ′ ) -L(θ)) is at least as high as constant function. Then, the value of Sδ-sharpness(T⃗a(θ)) is relatively large. ■
The above result reveals that the original definition of sharpness is not well defined for BN-network. Actually, we can achieve a minimum with small generalization error but infinite sharpness if we rescale the minimizer adequately close to zero for δ-sharpness. Hence, using δ-sharpness as a measurement of generalization is meaningless. We see the illposed issue of δ-sharpness suffers from the scale invariant ability of batch normalization network. Based on Theorem 3.1, we aim to derive a scale invariant sharpness.
Due to these, we present a scale invariant meanwhile computational efficient measurement: "BN-Sharpness", which is instructive for us to leverage it to find "flat" minima. Now, we give the exact definition of "BN-Sharpness".
Definition 3.1 (δ-Lp BN-Sharpness) Given a positive number δ, and a parameter point θ, and a partially batch normalized network, the δ-Lp BN-Sharpness is defined as
where φ(θ) is a set composed by v with ‖vi‖ = ‖θi‖, √∑Nj=N1+1 ‖vj‖2 = 1; i = 1, · · · ,N1.
We notice v ∈ φ(θ) has same dimension with θ. And it's decided by the parameter of a partially batch normalized network. Since v ∈ φ(θ) has identically l2 norm which is √∑N1 i=1 ‖θi‖2 + 1, we use ‖φ(θ)‖ to denote it. For simplicity, we use BN-Sharpness to substitute δ-Lp BN-Sharpness.
As we have discussed in Section 2, the Lp norm of function L(·) - L(θ) defined in B2(θ, δ) can be a measurement of sharpness (δ-sharpness is L∞ norm). The crucial problem of such Lp -sharpness is losing sight of parameter scale when choosing region diameter δ. On the other hand, it's a high dimensional integral (p < ∞) which is hard to be computed in practice let alone combining them to reduce sharpness. The two shortages are also hold when p = ∞.
We see BN-Sharpness consider the scale of batch normalized parameter. Meanwhile BN-Sharpness is an one dimensional integral along the sharpest direction v of L(θ) for each parameter component θi. It will be computational efficient especially for the gradient which we will discuss it more specifically in Section 5. By Taylor's expansion, for each parameter component θi we have
Here ∇L(θ)i represent gradient of L(·) to component parameter vector θi. The equation (6) gives an approximate calculating of the "sharpest" direction when δ is small. Precisely calculation of BN-Sharpness requires optimization on Oblique manifold which we will discuss in Section 4.
Now, we prove that BN-Sharpness is scale invariant. Hence, it's appropriate to measure sharpness for BN neural network.
Theorem 3.2 The loss function L(θ) of a DNN with batch normalization satisfies ‖L(·)‖δ,θ p = ‖L(·)‖δ,T⃗a(θ) p for any ⃗a without negative element.
Proof 3.2 For any a ̸= 0, we notice that L(θ) = L(T⃗a(θ)). Therefore for any v with v ∈ φ(θ), we have
for t ∈ [-δ, δ]. It's easily to verify that
Since
we get the conclusion.
■
Actually, we can derive a relationship between BNSharpness and generalization error. The result is based on PAC Bayesian theory [McAllesterl, 1998; 1999].
Theorem 3.3 Given a "prior" distribution P (for parameter θ) over the hypothesis that is independent of the training data, with probability at least 1 - ε, we have
where L(·) and ˆL(·) are respectively expected loss and training loss, m is the number of training data and θ is the parameter learned from training data. As long as u is an uniform distribution on any specific v ∈ δ · φ(θ).
A straightforward connection between generalization error |L(θ)- ˆL(θ)| and sharpness is nontrivial. We can only derive a perturbed generalization error |Eu[L(θ+u)]- ˆL(θ)|, where u is the perturbation variable. A small perturbation variable u will make the perturbed generalization error close to the real generalization error which involves a small δ in equation (10). We claim that the result gives a quantitatively description of generalization error based on BN-Sharpness. It's a direct corollary according to the equation (6) in McAllester [McAllesterl, 2003] and the definition of BN-Sharpness.
4 Regularizing Training with BN-Sharpness
We already have an appropriate definition of BN-Sharpness. It has also been confirmed that smaller BN-Sharpness leads to better generalization. We naturally consider leveraging it to find a flat minimum generalizes better.
Intuitively, we consider using BN-Sharpness as a regularization term tend to produce flat minima for BN neural network. We substitute the optimization problem minθ L(θ) with
An interesting phenomenon is such regularization term not only computational efficient and appropriate but also wellposed. More specifically, traditional regularization term such as l1, l2 would change the minimums set of loss function. But BN-Sharpness regularization term keeps minima of original loss function in the minimal point set of regularized loss function, while it force iterates move to a flat valley. The next theorem states that regularization term in (11) wouldn't remove minima of original loss function when δ is small.
Theorem 4.1 The minima of problem minθ L(θ) are also minima of optimization problem (11), when δ → 0 and p ≥ 1.
The optimization problem (11) is actually a multi-target programming with "accuracy target" and "flatness target". λ in (11) is actually a proportion between the two terms. Since we aim to find "flat" minima rather than "flat" point, an appropriate proportion between the two purpose is crucial.
Now, we give a computational efficient algorithm to solve the optimization problem (11). Here we simply explain our algorithm flow. We notice that the obstacle of optimization problem (11) is calculating the gradient of regularization term (‖L(θ′ )‖δ,θ p )p (BN-Sharpness). It involves two steps: First, calculating the "sharpest" direction which we need optimization on Oblique manifold; Second, computing the gradient of integral term in BN-Sharpness under the "sharpest" direction.
Now we give the complete flow of our algorithm: Algorithm 1. Then we will discuss more details about it.
In Algorithm 1, the first inner loop is calculating the "sharpest" direction which is the process of optimization on Oblique manifold. The second inner loop is general gradient descent to update parameter θ. In addition, we make an approximation to λ∇θ 1δ ∫ δ-δ ( L(θ+tv)-L(θ) δ )p dt and ∇v 1δ ∫ δ-δ ( L(θ+tv)-L(θ) δ )p dt in equation (15) and (16) to further reduce computational redundancy. We respectively denote them as h1(θ, v, δ, p, λ) and h2(θ, v, δ, p).
Algorithm 1 SGD with BN-Sharpness regularization
Input δ > 0, even number p, initialize point θ0 ∈ Rn, v0 ∈ φ(θ0 ) set to be the gradient direction like equation (6), regularization coefficient λ, iterations K1,K2 and learning rate η.
Optimization with BN-Sharpness term
k2 = 0
4.1 Searching the Sharpest Direction v
The extra computation cost comparing to vanilla SGD is the procedure of searching the "sharpest" direction v which is the second inner loop in Algorithm 1. Inspiring by equation (6), we can also choose vk ∈ φ(θk) with vik has same direction with ∇L(θk)i for each step to avoid the searching process (Iterate K1 times in Algorithm 1).
However, there is a more accurate searching procedure which is optimization on Oblique manifold. Searching v in BN-Sharpness (5) is equivalent to solving optimization problem:
This is a constrained optimization problem which can be converted to optimization on manifold. We briefly present optimization on manifold here. Detailed introduction can be referred to [Boumal et al., 2017].
Optimization on manifold converts a constrained optimization problem into an un-constraint problem while iterates locate in a manifold satisfy the constraint. Specific definition of manifold M can be found in [Pierre-Antoine et al., 2009]. Here we only consider matrix manifold i.e. a subspace of Euclidean space. Solving problem (12) needs gradient assent on manifold which produce iterates as
Here gradf(x) is Riemannian gradient which is a map from tangent space TxMof point x to manifoldM. The optimization problem (12) defined on the general Oblique manifold. We need the related formulations in Oblique manifold to process our algorithm.
Definition 4.1 (Oblique manifold) Oblique manifold is a subset of Euclidean space satisfy St(n, p) = {X ∈ Rn×p : ddiag(XT X) = Ip}, where ddiag(·) is diagonal matrix of a matrix.
Apparently, for a given θ in equation (12), v lives in a special Oblique product manifold ‖θ‖1St(n1, 1) × · · · × ‖θ‖N1 St(nN1 , 1) × St(∑Nj=N1+1 nj, 1) where ni is the dimension of parameter θi.
As we discussed, optimization on manifold requires Retrx and gradf(x). The two items on single Oblique manifold ‖θ‖St(n, 1) respectively are
where P ‖θ‖ x (·) is projection matrix of the tangent space at x. These results can be derived from the general formulas in [Pierre-Antoine et al., 2009; Pierre-Antoine and Gallivan, 2006]. Then we can generalize it to achieve the update rule in product manifold we used. The procedure is gradually update vk i according to the manifold it located [Cho and Lee, 2018].
In addition, we note that our algorithm involves ∇θ 1δ ∫ δ-δ ( L(θ+tv)-L(θ) δ )p dt (The gradient descent for parameter θ) and ∇v 1δ ∫ δ-δ ( L(θ+tv)-L(θ) δ )p dt (Searching the sharpest direction). Precise calculation of the two terms will bring some extra computational redundancy. Because L(θ) usually be a neural network, but calculating the integral term requires sampling value of L(θ + tv) and ∇L(θ + tv). Each sampling corresponds to a forward and backward process of neural network. The next proposition gives an approximation to the gradient of BN-Sharpness. It reduces the times of froward and backward process to two. In the next proposition, we aim to a specific v and suppose that v is a constant vector.
Proposition 4.1 Given δ > 0, for any v satisfy ‖v‖ = ‖φ(θ)‖, we have
when p is an even number.
Proposition 4.1 indicates the gradient respect to parameter θ can be replaced by a computational efficient term. On the other hand, we can achieve a similar result presented as
for v. The equation gives an approximation for the gradient respect to vector v locate in a product Oblique manifold.
We will use the two approximation terms to substitute the original gradients of BN-Sharpness in our algorithm. Finally, we point out that the sharpest direction vk of point θ in Algorithm 1 is produced as
5 Experiment
The previous work indicate that SGD with large batch size produces sharp minima while small batch size can avoid sharp minima itself [Keskar et al., 2017]. Therefore, in order to finding flat minima under large batch size, we use Algorithm 1 to reach such target. We consider our algorithm should have a preferable result comparing to SGD under large batch size. We should highlight that the biases gradient ∇θL (θ + p p+1 δv) and ∇θL (θ - p p+1 δv) in equation (15) are calculated by different batch data. It's a way of reducing variance which is used in Entropy SGD [Chaudhari et al., 2017].
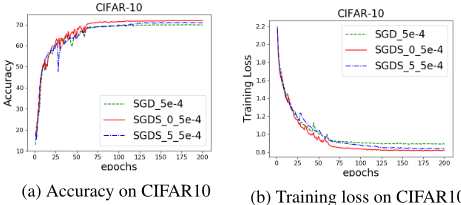
First we test the algorithm with fully batch normalized LeNet [LeCun et al., 1998] to test the performance for CIFAR10 [Krizhevsky et al., 2012]. Update rule is SGD with momentum by setting learning rate as 0.2 and decay it by a factor 0.1 respectively in epoch 60, 120, 160 and momentum parameter as 0.9. We use 10000 batch size, and 5e-4 weight decay ratio for all the three experiments.
For experiments with regularization term, we clip the gradient of BN-Sharpness by norm with factor 0.1. We use "SGDS-number-decay" to represent the algorithm regularized by BN-Sharpness iterate "number" times of searching sharpest direction and using a weight decay ratio as "decay". For example, "SGDS-5-5e-4" means iterate 5 times of searching v in 3.1 (K1=5 in Algorithm 1) and setting weight decay ratio as 5e-4. In addition, the initial point of iteration is set to be the gradient direction like in equation (6). For the experiments with regularized BN-Sharpness, we choose λ as 1e-4 which increase by a factor of 1.02 for each epoch. We set δ = 0.001, and the p is chosen as 2.
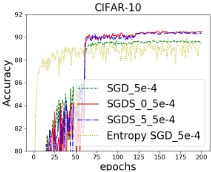
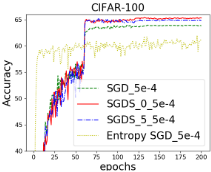
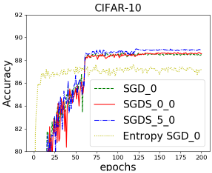
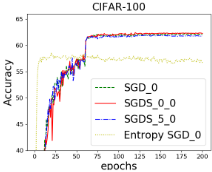
(d) Accuracy of 2048 batch size without weight decay on CIFAR100
| Algorithm | SGD-5e-4 | SGDS-0-5e-4 | SGDS-5-5e-4 | E-SGD-5e-4 |
| CIFAR10 | 91.67 | 91.78 | 91.55 | 91.03 |
| CIFAR100 | 69.33 | 69.07 | 68.53 | 67.37 |
| Algorithm | SGD | SGDS-0-0 | SGDS-5-0 | E-SGD-0 |
| CIFAR10 | 90.5 | 90.53 | 90.53 | 89.96 |
| CIFAR100 | 65.5 | 65.45 | 64.82 | 63.45 |
| Algorithm | SGD-5e-4 | SGDS-0-5e-4 | SGDS-5-5e-4 | E-SGD-5e-4 |
| CIFAR10 | 89.6 | 90.51 | 90.35 | 89.67 |
| CIFAR100 | 63.83 | 65.31 | 64.8 | 61.02 |
| Algorithm | SGD | SGDS-0-0 | SGDS-5-0 | E-SGD-0 |
| CIFAR10 | 88.5 | 88.58 | 88.9 | 87.13 |
| CIFAR100 | 62.17 | 62.25 | 61.8 | 56.68 |
Table 2: Performance of VGG with batch size as 2048.
The accuracy result is referred to Figure 1a, where the accuracy results of "SGD", "SGD with sharpness" and "SGD with sharpness iteration=5" are respectively 69.87, 71.84, 70.95. We see that our algorithm has a significant promotion on such toy example. Now we test our algorithm on a deeper network VGG11 with bath normalization [Simonyan and Zisserman, 2014]. We respectively test vanilla SGD, SGD with BN-Sharpness regularization and Entropy-SGD (represented as E-SGD) on the network. The experiments can be divided into two groups, large batch size and small batch size. The batch size we used for the two groups of experiments are respectively 128 and 2048.
For SGDS, the δ in CIFAR10 is 5e-4 and in CIFAR100 is 1e-3, learning rate is 0.2 and decay by a factor 0.1 respectively in epoch 60, 120, 160. The learning rate for SGD is 0.1
and we decay it like SGDS. Other hyper-parameters we used follow the setting in the first experiment of LeNet.
For Entropy SGD we follow the same hyper parameters in [Chaudhari et al., 2017] for experiments with 2048 batch size, except for the learning rate. We set learning rate like SGD experiments. But for experiment with 128 batch size, we turn off the drop out and use a 0.01 global learning rate. We also didn't adjust the γ accord with iteration times. These adjustments will make Entropy-SGD perform better. From the results, we conclude that SGD with small batch size can avoid "sharp" minima itself, and regularized by sharpness has little influence. Here we don't pay a lot attention to searching the sharpest direction. This is motivated by reducing computation complexity as well as balancing regularized term and loss function.
We emphasize that dividing the sharpness target and accuracy target is important. It allows us to dynamically adjust "flat" target which avoid iterates stack in a wide valley when accuracy in a low standard. Actually, if we use the same hyper parameters for Entropy SGD under batch size 128 and 2048. The training accuracy will end in a low level. Even though, Entropy SGD still perform general. We think it suffer from two aspects: First, sampling 20 points(L = 20 in Entropy SGD) for a huge model is not enough, which make it unstable. It will present a high variance result; Second, iterates tend to stack in a inaccurate point, since the loss function may be inexact (See Supplement Material).
Training model with SGD for 600 epochs (adjust learning rate by iterations) can reach the results of SGDS. It's a viewpoint for large batch size SGD: Training longer, generalize better [Hoffer et al., 2017]. However, our method can reach such result under fewer iterations.
6 Conclusion
We first prove that tradition definitions of sharpness are insufficient to describe geometrical structure of neural network with batch normalization. Based on that, we propose a scale invariant BN-Sharpness to measure the sharpness of minima. Then, we give an algorithm based on BN-Sharpness. It has computational advantage comparing to existing sharpness based algorithms.
For all algorithms in order to find "flat" minima (including our algorithm), the training purpose is finding a "flatter" minima generalize better, rather than finding a "flatter" point. Therefore, for such kind of algorithms, setting a large proportion to sharpness target will easily force iterates walk into a "flat" local minimum that generalize poor. Therefore, balancing the sharpness target and loss target is a delicate but meaningful problem.
Finally, we don't particularly discuss the combination of our algorithms with training tricks under large batch size such as [Hoffer et al., 2017], [Choromanska et al., 2015] and [De et al., 2017]. In fact, combing them together it's a very interesting topic.
@inproceedings{ijcai2019p578,
  title     = {BN-invariant Sharpness Regularizes the Training Model to Better Generalization},
  author    = {Yi, Mingyang and Zhang, Huishuai and Chen, Wei and Ma, Zhi-Ming and Liu, Tie-Yan},
  booktitle = {Proceedings of the Twenty-Eighth International Joint Conference on
               Artificial Intelligence, {IJCAI-19}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Sarit Kraus},
  pages     = {4164--4170},
  year      = {2019},
  month     = {8},
  note      = {Main track},
  doi       = {10.24963/ijcai.2019/578},
  url       = {https://doi.org/10.24963/ijcai.2019/578},
}
TY - CPAPER TI - BN-invariant Sharpness Regularizes the Training Model to Better Generalization AU - Yi, Mingyang AU - Zhang, Huishuai AU - Chen, Wei AU - Ma, Zhi-Ming AU - Liu, Tie-Yan T2 - Proceedings of the Twenty-Eighth International Joint Conference on Artificial Intelligence, IJCAI-19 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2019 SP - 4164 EP - 4170 DO - 10.24963/ijcai.2019/578 UR - https://doi.org/10.24963/ijcai.2019/578 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





