
Quadruply Stochastic Gradients for Large Scale Nonlinear Semi-Supervised AUC Optimization
Proceedings of the Twenty-Eighth International Joint Conference on Artificial Intelligence. Main track. Pages 3418-3424.
https://doi.org/10.24963/ijcai.2019/474
Keywords
- Machine Learning: Semi-Supervised Learning
- Machine Learning: Kernel Methods
- Machine Learning Applications: Big data ; Scalability
Abstract
Semi-supervised learning is pervasive in real-world applications, where only a few labeled data are available and large amounts of instances remain unlabeled. Since AUC is an important model evaluation metric in classification, directly optimizing AUC in semi-supervised learning scenario has drawn much attention in the machine learning community. Recently, it has been shown that one could find an unbiased solution for the semi-supervised AUC maximization problem without knowing the class prior distribution. However, this method is hardly scalable for nonlinear classification problems with kernels. To address this problem, in this paper, we propose a novel scalable quadruply stochastic gradient algorithm (QSG-S2AUC) for nonlinear semi-supervised AUC optimization. In each iteration of the stochastic optimization process, our method randomly samples a positive instance, a negative instance, an unlabeled instance and their random features to compute the gradient and then update the model by using this quadruply stochastic gradient to approach the optimal solution. More importantly, we prove that QSG-S2AUC can converge to the optimal solution in O(1/t), where t is the iteration number. Extensive experimental results on a variety of benchmark datasets show that QSG-S2AUC is far more efficient than the existing state-of-the-art algorithms for semi-supervised AUC maximization, while retaining the similar generalization performance.
- [Amini et al., 2008] Massih-Reza Amini, Tuong-Vinh Truong, and Cyril Goutte. A boosting algorithm for learning bipartite ranking functions with partially labeled data. 2008.
- [Dai et al., 2014] Bo Dai, Bo Xie, Niao He, Yingyu Liang, Anant Raj, Maria-Florina F Balcan, and Le Song. Scalable kernel methods via doubly stochastic gradients. In Ad- vances in Neural Information Processing Systems, pages 3041-3049, 2014.
- [Ding et al., 2017] Yi Ding, Chenghao Liu, Peilin Zhao, and Steven CH Hoi. Large scale kernel methods for online auc maximization. In 2017 IEEE International Conference on Data Mining (ICDM), pages 91-100. IEEE, 2017.
- [Drineas and Mahoney, 2005] Petros Drineas and Michael W Mahoney. On the nyström method for approximating a gram matrix for improved kernel- based learning. journal of machine learning research, 6(Dec):2153-2175, 2005.
- [du Plessis et al., 2015] Marthinus Christoffel du Plessis, Gang Niu, and Masashi Sugiyama. Class-prior estimation for learning from positive and unlabeled data. In ACML, pages 221-236, 2015.
- [Fine and Scheinberg, 2001] Shai Fine and Katya Schein- berg. Efficient svm training using low-rank kernel rep- resentations. Journal of Machine Learning Research, 2(Dec):243-264, 2001.
- [Fujino and Ueda, 2016] Akinori Fujino and Naonori Ueda. A semi-supervised auc optimization method with gener- ative models. In Data Mining (ICDM), 2016 IEEE 16th International Conference on, pages 883-888. IEEE, 2016.
- [Gao and Zhou, 2015] Wei Gao and Zhi-Hua Zhou. On the consistency of auc pairwise optimization. In IJCAI, pages 939-945, 2015. IJCAI
- [Gao et al., 2013] Wei Gao, Rong Jin, Shenghuo Zhu, and Zhi-Hua Zhou. One-pass auc optimization. In Interna- tional Conference on Machine Learning, pages 906-914, 2013.
- [Gu and Huo, 2018] Bin Gu and Zhouyuan Huo. Asyn- chronous doubly stochastic group regularized learning. In International Conference on Artificial Intelligence and Statistics (AISTATS 2018), 2018.
- [Gu et al., 2016] Bin Gu, Zhouyuan Huo, and Heng Huang. Asynchronous stochastic block coordinate descent with variance reduction. arXiv preprint arXiv:1610.09447, 2016.
- [Gu et al., 2018a] Bin Gu, Yingying Shan, Xiang Geng, and Guansheng Zheng. Accelerated asynchronous greedy co- ordinate descent algorithm for svms. In IJCAI, pages 2170-2176, 2018. IJCAI
- [Gu et al., 2018b] Bin Gu, Miao Xin, Zhouyuan Huo, and Heng Huang. Asynchronous doubly stochastic sparse ker- nel learning. In Thirty-Second AAAI Conference on Artifi- cial Intelligence, 2018.
- [Gu et al., 2018c] Bin Gu, Xiao-Tong Yuan, Songcan Chen, and Heng Huang. New incremental learning algorithm for semi-supervised support vector machine. In Proceedings of the 24th ACM SIGKDD International Conference on Knowledge Discovery & Data Mining, pages 1475-1484. ACM, 2018.
- [Hanley and McNeil, 1982] James A Hanley and Barbara J McNeil. The meaning and use of the area under a re- ceiver operating characteristic (roc) curve. Radiology, 143(1):29-36, 1982.
- [Li et al., 2017] Xiang Li, Bin Gu, Shuang Ao, Huaimin Wang, and Charles X Ling. Triply stochastic gradients on multiple kernel learning. UAI, 2017.
- [Liang, 2005] Percy Liang. Semi-supervised learning for natural language. PhD thesis, Massachusetts Institute of Technology, 2005.
- [Liu et al., 2018] Mingrui Liu, Xiaoxuan Zhang, Zaiyi Chen, Xiaoyu Wang, and Tianbao Yang. Fast stochastic auc maximization with o (1/n)-convergence rate. In Inter- national Conference on Machine Learning, pages 3195- 3203, 2018.
- [Rahimi and Recht, 2008] Ali Rahimi and Benjamin Recht. Random features for large-scale kernel machines. In Ad- vances in neural information processing systems, pages 1177-1184, 2008.
- [Rudin, 2017] Walter Rudin. Fourier analysis on groups. Courier Dover Publications, 2017.
- [Sakai et al., 2017] Tomoya Sakai, Marthinus Christoffel du Plessis, Gang Niu, and Masashi Sugiyama. Semi- supervised classification based on classification from pos- itive and unlabeled data. In Proceedings of the 34th In- ternational Conference on Machine Learning-Volume 70, pages 2998-3006. JMLR. org, 2017.
- [Sakai et al., 2018] Tomoya Sakai, Gang Niu, and Masashi Sugiyama. Semi-supervised auc optimization based on positive-unlabeled learning. Machine Learning, 107(4):767-794, 2018.
- [Sholokhov et al., 2018] Alexey Sholokhov, Md Sahidullah, and Tomi Kinnunen. Semi-supervised speech activity de- tection with an application to automatic speaker verifica- tion. Computer Speech & Language, 47:132-156, 2018.
- [Smola and Schölkopf, 2000] Alex J Smola and Bernhard Schölkopf. Sparse greedy matrix approximation for ma- chine learning. 2000.
- [Wang et al., 2010] Jun Wang, Sanjiv Kumar, and Shih-Fu Chang. Semi-supervised hashing for scalable image re- trieval. 2010.
- [Xie and Li, 2018] Zheng Xie and Ming Li. Semi-supervised auc optimization without guessing labels of unlabeled data. 2018.
- [Ying et al., 2016] Yiming Ying, Longyin Wen, and Siwei Lyu. Stochastic online auc maximization. In Advances in neural information processing systems, pages 451-459, 2016.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Semi-supervised learning addresses the problems where the available data is composed of a small size of labeled samples and a huge size of unlabeled samples. It is of immense practical interest in a wide range of applications, such as image retrieval [Wang et al., 2010], natural language processing [Liang, 2005] and speech analysis [Sholokhov et al., 2018]. Since semi-supervised learning requires less human effort and can achieve a better generalization performance, it has attracted a great deal of attention in the machine learning communities, i.e., [Gu et al., 2018c; Sakai et al., 2017; Sakai et al., 2018].
∗Contact Author
The area under the ROC curve (AUC) [Hanley and McNeil, 1982] measures the probability of a randomly drawn positive instance being ranked higher than a randomly drawn negative instance. Thus, AUC is a more effective performance measure than the accuracy in data imbalance binary classification problem. Many studies [Gao et al., 2013; Gao and Zhou, 2015] have also pointed out that optimizing AUC can achieve a better generalization performance than directly optimizing accuracy. Due to the superiority of AUC as mentioned above, a large amount of attention has been attracted to introduce AUC to semi-supervised learning.
Recently, several algorithms have been proposed to address the semi-supervised AUC optimization problem. For instance, to train a classifier, SSRankBoost [Amini et al., 2008] and OptAG [Fujino and Ueda, 2016] exploited the assumption that two samples share the same label if their distance in a metric space is small. However, this restrictive assumption may not always hold in real-world applications, and could lead to biased solutions. Sakai et al., [2018] pointed out that both unlabeled instances and labeled instances follow the same joint probability distribution and the restrictive assumption is not necessary. However, their method PNU-AUC requires to estimate the class prior which is difficult to be obtained when labeled instances are extremely small. Recently, Xie and Li, [2018] proposed that neither the class priors nor any other distributional assumption about the unlabeled data are necessary to find the unbiased solution. We summarize these algorithms in Table 1.
Nonlinear data structures widely exist in many real-world problems, and kernel method is a typical way to solve such problems. However, this approach can hardly scale to large datasets. Specifically, the kernel matrix needs O(n2d) operations to be calculated and O(n2 ) to be stored, where n denotes the number of instances and d denotes the dimensionality of the data [Gu and Huo, 2018]. However, the bottlenecks of the computational complexities become more severe for semi supervised learning because the sample size n is always very large in the semi-supervised scenario. Even worse, PNU-AUC and SAMULT [Xie and Li, 2018] need O(n3 ) operations to compute the matrix inverse. Thus, scaling up nonlinear semi-supervised AUC maximization is a challenging problem.
| Algorithm | Reference | Function model | Computational complexity | Space complexity |
|---|---|---|---|---|
| SSRankBoost | [Amini et al., 2008] | Nonlinear model | - | O(n2 ) |
| OptAG | [Fujino and Ueda, 2016] | Linear model | - | O(n2 ) |
| PNU-AUC | [Sakai et al., 2018] | Nonlinear model | O(n3 ) | O(n2 ) |
| SAMULT | [Xie and Li, 2018] | Nonlinear model | O(n3 ) | O(n2 ) |
| QSG-S2AUC | Ours | Nonlinear model | O(Dt2 ) | O(t) |
To scale up kernel-based algorithms, a large amount of methods has been proposed, i.e., asynchronous parallel algorithms [Gu et al., 2018a; Gu and Huo, 2018; Gu et al., 2016], kernel approximation [Rahimi and Recht, 2008; Smola and Sch¨olkopf, 2000]. To our knowledge, doubly stochastic gradient (DSG) [Dai et al., 2014] is the most effective method to scale up kernel-based algorithms. Specifically, DSG samples a random instance and the random features to compute the doubly stochastic gradient which is used to update the model. However, different from the standard DSG, semi-supervised learning has three sources of data, i.e., positive instances, negative instances and unlabeled datasets. In addition, optimizing AUC is a pairwise learning problem which is more complicated than the pointwise learning problem considered in the standard DSG algorithm. Therefore, the existing algorithms and theoretical analysis for DSG cannot be directly applied to non-linear semi-supervised AUC maximization.
To address this challenging problem, we introduce multiple sources of randomness. Specifically, we randomly sample a positive, a negative and an unlabeled instance in each iteration to compose a triplet of data points. Then we use the random features w.r.t these data triplets to compute the stochastic gradient. Since the stochastic gradient would then contain four sources of randomness, we denote our algorithm as quadruply stochastic semi-supervised AUC maximization (QSG-S2AUC). Theoretically, we prove that QSG-S2AUC can converge to the optimal solution at the rate of O(1/t), where t is the number of gradient iterations. Extensive experimental results on a variety of benchmark datasets show that QSG-S2AUC is far more efficient than the existing state-ofthe-art algorithms for semi-supervised AUC maximization, while retaining the similar generalization performance.
Contributions. The main contributions of this paper are summarized as follows.
- We propose an efficient nonlinear semi-supervised AUC optimization algorithm based on the DSG framework. Since semi-supervised learning contains three sources of data, we employ triplets of data points in each iteration and extend the standard DSG framework.
- We prove that QSG-S2AUC has the convergence rate of O(1/t) which is same to the one of standard SGD even though our QSG-S2AUC has four sources of randomness.
2 RelatedWorks
In this section, we give a brief review of kernel approximation and large scale AUC maximization methods respectively.
2.1 Kernel Approximation
Kernel approximation has attracted great amounts of attention to scale up kernel-based learning algorithms. The datadependent methods, such as greedy basis selection techniques [Smola and Sch¨olkopf, 2000], incomplete Cholesky decomposition [Fine and Scheinberg, 2001], Nystr¨om method [Drineas and Mahoney, 2005], utilize the given training set to compute a low-rank approximation of the kernel matrix. However, they need a large amount of training instances to achieve a better generalization. To handle this challenge, random Fourier feature (RFF) [Rahimi and Recht, 2008] directly approximates the kernel function unbiasedly with some basis functions. However, large amounts of memory are required since the number random features D need to be larger than the original features to achieve low approximation error. To further improve RFF, Dai et al., [2014] proposed DSG algorithm. It uses pseudo-random number generators to calculate the random features on-the-fly, which highly reduces the memory requirement. These methods have been widely applyed to scale up kernel-based learning algorithms, such as [Li et al., 2017; Gu et al., 2018b].
2.2 Large Scale AUCOptimization
Recently, several efforts have been devoted to scale up the AUC optimization. For example, Ying et al., [2016] formulated the AUC optimization as a convex-concave saddle point problem and proposed a stochastic online method (SOLAM) which has the time and space complexities of one datum. FSAUC [Liu et al., 2018] developed a multi-stage scheme for running primal-dual stochastic gradient method with adaptively changing parameters. FSAUC has the convergence rate of O(1/n), where n is the number of random samples. However, both SOLAM and FSAUC focus on scaling up the linear AUC optimization and are incapable of maximizing AUC in the nonlinear setting. Recently, FOAM and NOAM [Ding et al., 2017] used RFF and Nystr¨om method, respectively, to scale up the kernel based AUC optimization problem. However, as mentioned above, both methods require large amounts of memory to achieve a better generalization performance and not trivial to scale up the nonlinear semi-supervised AUC optimization problems based.
3 Preliminaries
3.1 Supervised AUCOptimization
In supervised learning, let x ∈ Rd be a d-dimensional pattern and y ∈ {+1,-1} be a class label. Let p(x, y) be the underlying joint density of (x, y). The AUC optimization is to train a classifier f that maximizes the following function.
where p+(x) = p(x|y = +1), p-(x) = p(x|y = -1) and l01(u, v) = (1 - sign(u - v))/2. Obviously, maximizing AUC is equivalent to minimizing the following PN AUC risk.
Given the positive and negative datasets as Dp = {xi}pi=1 ∼ p+(x) and Dn = {xj}nj=1 ∼ p-(x) respectively. Thus, the PN AUC risk can be rewritten as follows.
where Exp∈Dp and Exn∈Dn denote the means of Dp and Dn, respectively.
3.2 Semi-Supervised AUCOptimization
Since large amounts of instances remain unlabeled in semisupervised learning, we assume that the labeled dataset is limited while the unlabeled data can be infinite and has the underlying distribution density of p(x), where p(x) = πp+(x) + (1 - π)p-(x) and π denotes the positive class prior. Recently, Xie and Li, [2018] have shown that it is unnecessary to estimate distributional assumptions or class prior to achieve an unbiased solution for semi-supervised AUC optimization. Specifically, PU AUC risk RPU and NU AUC risk RNU are equivalent to the supervised PN AUC risk RPN risk with a linear transformation, where PU AUC risk RPU is estimated by positive and unlabeled data treated as negative data, and NU AUC risk RNU is estimated by negative and unlabeled data treated as positive data. We define RPU and RNU as follows,
where Exu∼p(x) denotes the expectation over the density p(x). PU AUC risk can be written as follows.
where x′p and x′n denotes the positive and negative instances in unlabeled dataset. Similarly, NU AUC risk RNU can be rewritten as
Then PN AUC risk RPN can be formulated as follows.
Thus, the semi-supervised AUC optimization can be formulated as follows.
where γ ∈ [0, 1] is the trade-off parameter. To reduce the risk of overfitting, we add a l2-regularizer into (8) and have the following objective for semi-supervised AUC optimization.
where λ is the regularized parameter and ‖ · ‖H denotes the norm in a reproducing kernel Hilbert space (RKHS) H.
3.3 RandomFourier Feature
In this section, we give a brief review of RFF. Assume that we have a continuous, real-valued, symmetric and shift-invariant kernel function k(x, x′ ). According to Bochner Theorem [Rudin, 2017], this kernel function is positive definite and has a nonnegative Fourier transform function as k(x, x′ ) = ∫Rd p(ω)ejωT (x-x′ )dω, where p(w) is a density function associated with k(x, x′ ). The integrand ejωT (x-x′ ) can be replaced with cosωT (x - x′ ) [Rahimi and Recht, 2008]. Then we can obtain a real-valued feature map φωi (x) = [cos(ωT i x), sin(ωT i x)]T , where ωi is randomly sampled according to the density function p(ω). We can obtain the feature map for m random features of a real-valued kernel as follows.
Obviously, φTω (x)φω(x′ ) is an unbiased estimate of k(x-x′ ).
4 Quadruply Stochastic Semi-Supervised AUC Maximization
4.1 Quadruply Stochastic Gradients
Based on the definition of the function f ∈ H, we easily obtain ∇f(x) = ∇〈f, k(x, ·)〉, and ∇‖f‖2H = ∇〈f, f〉H = 2f. Thus, the gradient of the objective (9) can be written as:
where l′1k(xp , ·) denotes the derivative of l(f(xp ), f(xn )) w.r.t. f(xp ), l′2k(xn , ·) denotes the derivative of l(f(xp ), f(xn )) w.r.t. f(xn ), l′3k(xp , ·) denotes the derivative of l(f(xp ), f(xu )) w.r.t. f(xp ), l′4k(xu , ·) denotes the derivative of l(f(xp ), f(xu )) w.r.t. f(xu ), l′5k(xu , ·) denotes the derivative of l(f(xu ), f(xn )) w.r.t. f(xu ) and l′6k(xn , ·) denotes the derivative of l(f(xu ), f(xn )) w.r.t. f(xn ).
In order to update the classifier f in a stochastic manner,we randomly sample a positive data point xp and a negative data point xn fromDp and Dn, respectively. In addition, we randomly sample an unlabeled data point xu according to the unlabeled data distribution density p(x). In each iteration, we use a triplet of these data points to compute the stochastic functional gradient of (8) as follows.
We can apply the random Fourier feature method to further approximate the stochastic functional gradient ξ(·) as follows.
Obviously, we have that ξ(·) = Eω[ζ(·)]. Thus, we can achieve the unbiased estimate of the gradient (11) by using either ξ(·) or ζ(·) as follows,
Because four randomness (i.e. xp , xn , xu and ω) are involved in ζ(·), we call the functional gradient ζ(·) as quadruply stochastic functional gradient.
Then, we first give the update rule with the stochastic gradient ξ(·) as follow,
where a i t = -ηt ∏tj=i+1 (1 - ηjλ), ηt denotes the step size and ht+1(x) denotes the function value if we use gradient ξ(·). Since ζ(·) is an unbiased estimate of ξ(·), the update rule using ζ(·) after t iterations can be written as follow,
where f1(·) = 0, and ft+1(x) denotes the function value for the input x if we use the functional gradient ζ(·).
In order to implement the update process in computer program, we rewrite the update rule as the following iterative update rules with constantly-changing coefficients {αi}ti=1 ,
4.2 QSG-S2AUCAlgorithms
In our implementation, we use pseudo-random number generators with seed i to sample random features. In each iteration, we only need to keep the seed i aligned between prediction and training. Then the prediction function f(x) can be restored much more easily. Besides, the QSG-S2AUC maintains a sequence of {αi}ti=1 at each ieration which has low memory requirement. Specifically, each iteration of the training algorithm executes the following steps.
Algorithm 1 {αi}ti=1 = QSG-S2AUC(Dp, Dn, p(x))
Input: p(ω), φω(x), l(u, v), λ.
Output: {αi}ti=1
- 1: for i = 1, ..., t do
- 2: Sample xp fromDp.
- 3: Sample xn fromDn.
- 4: Sample xu ∼ p(x).
- 5: Sample ωi ∼ p(ω) with seed i.
- 6: f(xi) = Predict(xi, {αi}i-1 j=1 ).
- 7: αi = -ηi(γ(l′1φω(xp ) + l′2φω(xn )) + (1 - γ)(l′3φω(xp ) + l′4φω(xu ) + l′5φω(xu ) + l′6φω(xn )))
- 8: αj = (1 - ηjλ)αj for j = 1, ..., i -1.
- 9: end for
Algorithm 2 f (x) =Predict(x, {αi}ti=1 )
Input: p(ω), φω(x)
Output: f(x)
- 1: Set f(x) = 0.
- 2: for i = 1, ..., t do
- 3: Sample ωi ∼ p(ω) with seed i.
- 4: f(x) = f(x) +αiφω(x)
- 5: end for
- Select Random Data Triplets: Randomly sample a positive instance, a negative instance and an unlabeled instance to compose a data triplet. In addition, we use mini-batch of these data points to achieve a better efficiency.
- Approximate the Kernel Function: Sample ωi ∼ p(ω) with random seed i to calculate the random features on-the-fly. We keep this seed aligned between prediction and training to speed up computing f(xi) = ∑ti=1 αiφω(x).
- Update Coefficients: We compute the current coefficient αi in i-th loop and then update the former coefficients αj for j = 1, · · · , i - 1 according to the update rule (15) and (16), respectively.
We summarize the algorithms for training and prediction in Algorithm 1 and 2 respectively.
5 Convergence Analysis
In this section, we prove that QSG-S2AUC converges to the optimal solution at the rate of O(1/t). We first give several assumptions which are standard in DSG [Dai et al., 2014].
Assumption 1 (Bound of kernel function). The kernel function is bounded, i.e., k(x, x′ ) ≤ κ, where κ > 0.
Assumption 2 (Bound of random feature norm). The random feature norms are bounded, i.e., |φω(x)φω(x′ )| ≤ φ.
Assumption 3 (Lipschitz continuous). The first order derivation of l(f(xp ), f(xn )) is L1-Lipschitz continuous in terms of f(xp ) and L2-Lipschitz continuous in terms of f(xn ). Similarly, the first order derivation of l(f(xp ), f(xu )) is L3-Lipschitz continuous in terms of f(xp ) and L4Lipschitz continuous in terms of f(xu ) and the first order derivation of l(f(xu ), f(xn )) is L5-Lipschitz continuous in terms of f(xu ) and L6-Lipschitz continuous in terms of f (xn ).
| Dataset | Features | Samples | Source |
|---|---|---|---|
| Codrna | 8 | 59,535 | LIBSVM |
| Ijcnn1 | 22 | 49,990 | LIBSVM |
| Susy | 18 | 5,000,000 | LIBSVM |
| Covtype | 54 | 581,012 | LIBSVM |
| Higgs | 28 | 1,100,000 | LIBSVM |
| Skin | 3 | 245,057 | LIBSVM |
| Dota2 | 116 | 92650 | UCI |
| Unclonable | 129 | 6,000,000 | UCI |
Assumption 4 (Bound of derivation). There exists M1 > 0, M2 > 0, M3 > 0, M4 > 0, M5 > 0 and M6 > 0, such that |l′1 | ≤ M1, |l′2 | ≤ M2, |l′3 | ≤ M3, |l′4 | ≤ M4, |l′5 | ≤ M5, |l′6 | ≤ M6,
We use the framework of [Dai et al., 2014] to prove that ft+1 can converge to the optimal solution f ∗ . Specifically, we use the aforementioned ht+1 as an intermediate value to decompose the difference between ft+1 and f ∗ as follows,
In other words, the total approximation error includes the error caused by approximating the kernel with random features, and the error caused by sampling random data. Finally, the boundary of the original error can be obtained by summing up the boundary of these two parts.
We first give the convergence of error due to random features and random data in Lemmas 1 and 3 respectively. All the detailed proofs are provided in our Appendix 1 .
Lemma 1 (Error due to random features) Let χ denotes the whole training set in semi-supervised learning problem. For any x ∈ χ, we have
Obviously, the upper bound B2 1,t+1 depends on the convergence of |ait |, which is given in Lemma 2.
Remark 1 According to Lemmas 1 and 2, the error caused by random features has the convergence rate of O(1/t) with proper learning rate and θλ ∈ (1, 2).
1 Appendix is available at https://drive.google.com/open?id= 16qVZGYeL7xhB4BATIMdcGkxLEyw7LIYg.
Lemma 3 (Error due to random data) Set ηt = θt , θ > 0, such that θλ ∈ (1, 2) ∪ Z+, we have
According to Lemmas 1 and 3, we can obtain the convergence rate of QSG-S2AUC in Theorem 1.
Theorem 1 (Convergence in expectation) Let χ denote the whole training set in semi-supervised learning problem. Set ηt = θt , θ > 0, such that θλ ∈ (1, 2) ∪ Z+. ∀x ∈ χ, we have
Remark 2 Theorem 1 shows that for any given x, the evaluated value of ft+1 at x will converge to that of f ∗ in terms of the Euclidean distance at the rate of O(1/t). This rate is the same as that of standard DSG even though our problem is much more complicated and has four sources of randomness.
6 Experiments
In this section, we present the experimental results on several datasets to demonstrate the effectiveness and efficiency of QSG-S2AUC.
6.1 Experimental Setup
We compare the AUC results and running time of QSGS2AUC with the state-of-the-art semi-supervised AUC maximization algorithms as summarized as follows.
- PNU-AUC: Unbiased semi-supervised AUC optimization method proposed in [Sakai et al., 2018] based on positive and unlabeled learning.
- SAMULT: The method proposed in [Xie and Li, 2018] which does not require the class prior distribution to achieve the unbiased solution.
All the experiments were ran on a PC with 56 2.2GHz cores and 80GB RAM. We implemented QSG-S2AUC and SAMULT algorithms in MATLAB. We used the MATLAB code from https://github.com/t-sakai-kure/PNU as the implementation of PNU-AUC. For all algorithms, we use the square pairwise loss l(u, v) = (1 - u + v)2 and Gaussian kernel k(x, x′ ) = exp(-σ‖x - x′ ‖2 ). The hyper-parameters (λ, σ and γ) are chosen via 5-fold cross-validation. λ and σ were searched in the region {(λ, σ)|2-3 ≤ λ ≤ 23 , 2-3 ≤ σ ≤ 23 }. The trade-off parameter γ in SAMULT and QSGS2AUC was searched from 0 to 1 at intervals of 0.1, and that in PNU-AUC was searched from -1 to 1 at intervals of 0.1. In addition, the class prior π in PNU-AUC is set to the class proportion in the whole training set, which can be estimated by [du Plessis et al., 2015]. All the results are the average of 10 trials.
6.2 Datasets
We carry out the experiments on eight large scale benchmark datasets collected from LIBSVM 2 and UCI 3 repositories. The size n of the dataset and the feature dimensionality d are summarized in Table 2. To conduct the experiments for semi-supervised learning, we randomly sample 200 labeled instances and treat the rest of the data as unlabeled. All the data features are normalized to [0, 1] in advance.
6.3 Results and Discussion
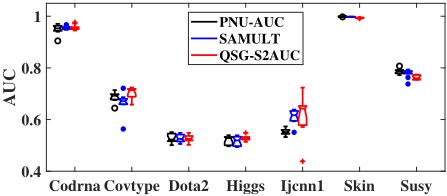
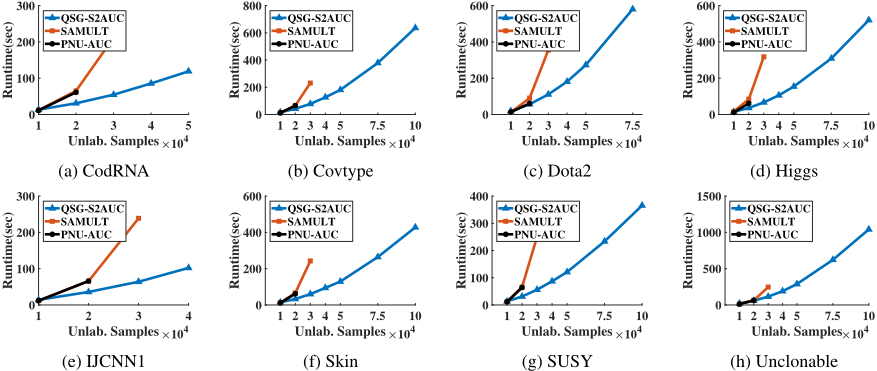
Figure 2 shows the training time of the three algorithms against different sizes of unlabeled samples on the eight benchmark datasets, where the sizes of labeled samples are fixed at 200. We can find that QSG-S2AUC is always faster than SAMULT and PNU-AUC. This is because the SAMULT and PNU-AUC need O(n3 ) operations to compute the inverse matrixes with kernel. Differently, QSG-S2AUC uses RFF to approximate the kernel function, and each time it only needs O(D) operations to calculate the random features with seed i. In addition, the low memory requirement of QSG-S2AUC allows it to do an efficient training for large scale datasets while PNU-AUC and SAMULT are out of memory. Figure 1 presents the testing AUC results of these algorithms on the eight benchmark datasets. The results show that QSGS2AUC has the similar AUC results with other methods on the most datasets, and has the highest AUC on the datasets of Covtype and Ijcnn1. Based on these results, we conclude that QSG-S2AUC is superior to other state-of-the-art algorithms in terms of efficiency and scalability, while retaining the similar generalization performance.
2 LIBSVM is available at https://www.csie.ntu.edu.tw/∼cjlin/ libsvmtools/datasets/binary/.
3 UCI is available at http://archive.ics.uci.edu/ml/datasets.html.
7 Conclusion
In this paper, we propose a novel scalable semi-supervised AUC optimization algorithm, QSG-S2AUC. Considering that semi-supervised learning contains three data sources, DSGS2AUC is designed to randomly sample one instance from each data source in each iteration. Then, their random features are generated and used to calculate a quadruply stochastic functional gradient for model update. Even though this optimization process contains multiple layers of stochastic sampling, theoretically, we prove that QSG-S2AUC has a convergence rate of O(1/t). The experimental results on various datasets also demonstrate the superiority of the proposed QSG-S2AUC.
Acknowledgments
H.H. was partially supported by U.S. NSF IIS 1836945, IIS 1836938, DBI 1836866, IIS 1845666, IIS 1852606, IIS 1838627, IIS 1837956. B.G. was partially supported by the National Natural Science Foundation of China (No: 61573191), and the Natural Science Foundation (No. BK20161534), Six talent peaks project (No. XYDXX-042) in Jiangsu Province.
@inproceedings{ijcai2019p474,
  title     = {Quadruply Stochastic Gradients for Large Scale Nonlinear Semi-Supervised AUC Optimization},
  author    = {Shi, Wanli and Gu, Bin and Li, Xiang and Geng, Xiang and Huang, Heng},
  booktitle = {Proceedings of the Twenty-Eighth International Joint Conference on
               Artificial Intelligence, {IJCAI-19}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Sarit Kraus},
  pages     = {3418--3424},
  year      = {2019},
  month     = {8},
  note      = {Main track},
  doi       = {10.24963/ijcai.2019/474},
  url       = {https://doi.org/10.24963/ijcai.2019/474},
}
TY - CPAPER TI - Quadruply Stochastic Gradients for Large Scale Nonlinear Semi-Supervised AUC Optimization AU - Shi, Wanli AU - Gu, Bin AU - Li, Xiang AU - Geng, Xiang AU - Huang, Heng T2 - Proceedings of the Twenty-Eighth International Joint Conference on Artificial Intelligence, IJCAI-19 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2019 SP - 3418 EP - 3424 DO - 10.24963/ijcai.2019/474 UR - https://doi.org/10.24963/ijcai.2019/474 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





