
Improving Information Centrality of a Node in Complex Networks by Adding Edges
Proceedings of the Twenty-Seventh International Joint Conference on Artificial Intelligence. Main track. Pages 3535-3541.
https://doi.org/10.24963/ijcai.2018/491
Keywords
- Constraints and SAT: Constraint Optimisation
- Machine Learning Applications: Networks
- Machine Learning: Data Mining
- Multidisciplinary Topics and Applications: Social Sciences
Abstract
The problem of increasing the centrality of a network node arises in many practical applications. In this paper, we study the optimization problem of maximizing the information centrality Iv of a given node v in a network with n nodes and m edges, by creating k new edges incident to v. Since Iv is the reciprocal of the sum of resistance distance Rv between v and all nodes, we alternatively consider the problem of minimizing Rv by adding k new edges linked to v. We show that the objective function is monotone and supermodular. We provide a simple greedy algorithm with an approximation factor (1 − 1/e) and O(n^3) running time. To speed up the computation, we also present an algorithm to compute (1 − 1/e − epsilon) approximate resistance distance Rv after iteratively adding k edges, the running time of which is Otilde(mk*epsilon^−2) for any epsilon > 0, where the Otilde(·) notation suppresses the poly(log n) factors. We experimentally demonstrate the effectiveness and efficiency of our proposed algorithms.
- [Avrachenkov and Litvak, 2006] K. Avrachenkov and N. Litvak. The effect of new links on Google PageRank. Stochastic Models, 22(2):319-331, 2006.
- [Avron and Toledo, 2011] H. Avron and S. Toledo. Random- ized algorithms for estimating the trace of an implicit sym- metric positive semi-definite matrix. Journal of ACM, 58(2):8:1-8:34, 2011.
- [Badanidiyuru and Vondrák, 2014] A. Badanidiyuru and J. Vondrák. Fast algorithms for maximizing submodular functions. In SODA, pages 1497-1514. SIAM, 2014.
- [Bergamini et al., 2016] E. Bergamini, M. Wegner, D. Lukarski, and H. Meyerhenke. Estimating current-flow closeness centrality with a multigrid Laplacian solver. In CSC, pages 1-12, 2016.
- [Boldi and Vigna, 2014] P. Boldi and S. Vigna. Axioms for centrality. Internet Mathematics, 10(3-4):222-262, 2014.
- [Bozzo and Franceschet, 2013] E. Bozzo and M. Franceschet. Resistance distance, closeness, and be- tweenness. Social Networks, 35(3):460-469, 2013.
- [Brandes and Fleischer, 2005] U. Brandes and D. Fleischer. Centrality measures based on current flow. In STACS, vol- ume 3404, pages 533-544. Springer-Verlag, 2005.
- [Crescenzi et al., 2015] P. Crescenzi, G. D'Angelo, L. Sev- erini, and Y. Velaj. Greedily improving our own centrality in a network. In SEA, pages 43-55. Springer, 2015.
- [Crescenzi et al., 2016] P. Crescenzi, G. D'Angelo, L. Sev- erini, and Y. Velaj. Greedily improving our own closeness centrality in a network. ACM Transactions on Knowledge Discovery from Data, 11(1):9, 2016.
- [D'Angelo et al., 2016] G. D'Angelo, L. Severini, and Y. Ve- laj. On the maximum betweenness improvement prob- lem. Electronic Notes in Theoretical Computer Science, 322:153-168, 2016.
- [Demaine and Zadimoghaddam, 2010] E. D. Demaine and M. Zadimoghaddam. Minimizing the diameter of a net- work using shortcut edges. In SWAT, pages 420-431. Springer-Verlag, 2010.
- [Doyle and Snell, 1984] P. G. Doyle and J. L. Snell. Random Walks and Electric Networks. Mathematical Association of America, 1984.
- [Hoffmann et al., 2018] C. Hoffmann, H. Molter, and M. Sorge. The parameterized complexity of centrality im- provement in networks. In SOFSEM, pages 111-124. Springer, 2018.
- [Hutchinson, 1989] M. F. Hutchinson. A stochastic estimator of the trace of the influence matrix for Laplacian smooth- ing splines. Communications in Statistics-Simulation and Computation, 18(3):1059-1076, 1989.
- [Ishakian et al., 2012] V. Ishakian, D. Erdös, E. Terzi, and A. Bestavros. A framework for the evaluation and man- agement of network centrality. In SDM, pages 427-438.
- [Izmailian et al., 2013] N. Sh Izmailian, R. Kenna, and FY Wu. The two-point resistance of a resistor network: a new formulation and application to the cobweb net- work. Journal of Physics A: Mathematical and Theoret- ical, 47(3):035003, 2013.
- [Klein and Randić, 1993] D. J Klein and M. Randić. Re- sistance distance. Journal of Mathematical Chemistry, 12(1):81-95, 1993.
- [Kunegis, 2013] J. Kunegis. Konect: the koblenz network collection. In WWW, pages 1343-1350. ACM, 2013.
- [Kyng and Sachdeva, 2016] R. Kyng and S. Sachdeva. Approximate Gaussian elimination for Laplacians-fast, sparse, and simple. In FOCS, pages 573-582. IEEE, 2016.
- [Lü et al., 2016] L Lü, D Chen, X Ren, Q Zhang, Y Zhang, and T Zhou. Vital nodes identification in complex net- works. Physics Reports, 650:1-63, 2016.
- [Meyer, 1973] C. D. Meyer, Jr. Generalized inversion of modified matrices. SIAM Journal on Applied Mathemat- ics, 24(3):315-323, 1973.
- [Meyerson and Tagiku, 2009] A. Meyerson and B. Tagiku. Minimizing average shortest path distances via shortcut edge addition. APPROX, pages 272-285. Springer-Verlag 2009.
- [Nemhauser et al., 1978] G. L. Nemhauser, L. A. Wolsey, and M. L. Fisher. An analysis of approximations for maxi- mizing submodular set functions. Mathematical Program- ming, 14(1):265-294, 1978.
- [Newman, 2005] M. E. J. Newman. A measure of between- ness centrality based on random walks. Social Networks, 27(1):39-54, 2005.
- [Newman, 2010] M. E. J. Newman. Networks: An Introduc- tion. Oxford University Press, 2010.
- [Olsen, 2010] M. Olsen. Maximizing PageRank with new backlinks. In ICAC, pages 37-48. Springer-Verlag, 2010.
- [Parotsidis et al., 2016] N. Parotsidis, E. Pitoura, and P. Tsaparas. Centrality-aware link recommendations. In WSDM, pages 503-512. ACM, 2016.
- [Peng and Spielman, 2014] R. Peng and D. A Spielman. An efficient parallel solver for SDD linear systems. In STOC, pages 333-342. ACM, 2014.
- [Plemmons, 1977] R. J. Plemmons. M-matrix characteriza- tions. I nonsingular M-matrices. Linear Algebra and its Applications, 18(2):175-188, 1977.
- [Spielman and Srivastava, 2011] D. A. Spielman and N. Sri- vastava. Graph sparsification by effective resistances. SIAM Journal of Computing, 40(6):1913-1926, 2011.
- [Stephenson and Zelen, 1989] K. Stephenson and M. Zelen. Rethinking centrality: Methods and examples. Social Net- works, 11(1):1-37, 1989.
- [White and Smyth, 2003] S. White and P. Smyth. Algo- rithms for estimating relative importance in networks. In KDD, pages 266-275. ACM, 2003.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Centrality metrics refer to indicators identifying the varying importance of nodes in complex networks [L¨u et al., 2016], which have become a powerful tool in network analysis and found wide applications in network science [Newman, 2010]. Over the past years, a great number of centrality indices and corresponding algorithms have been proposed to analyze and understand the roles of nodes in networks [White and Smyth, 2003; Boldi and Vigna, 2014]. Among various centrality indices, betweennees centrality and closeness centrality are probably the two most frequently used ones, especially in social network analysis. However, both indicators only consider the shortest paths, excluding the contributions from other longer paths. In order to overcome the drawback of these two measures, current flow closeness centrality [Brandes and Fleischer, 2005;
∗Corresponding author. This work was supported by the National Natural Science Foundation of China under Grant No. 11275049. Liren Shan was also supported by Fudan's Undergraduate Research Opportunities Program, FDUROP.
Newman, 2005] was introduced and proved to be exactly the information centrality [Stephenson and Zelen, 1989], which counts all possible paths between nodes and has a better discriminating power than betweennees centrality [Newman, 2005] and closeness centrality [Bergamini et al., 2016].
It is recognized that centrality measures have proved of great significance in complex networks. Having high centrality can have positive consequences on the node itself. In this paper, we consider the problem of adding a given number of edges incident to a designated node v so as to maximize the centrality of v. Our main motivation or justification for studying this problem is that it has several application scenarios, including airport networks [Ishakian et al., 2012], recommendation systems [Parotsidis et al., 2016], among others. For example, in airport networks, a node (airport) has the incentive to improve as much as possible its centrality (transportation capacity) by adding edges (directing flights) connecting itself and other nodes (airports) [Ishakian et al., 2012]. Another example is the link recommendation problem of recommending to a user v a given number of links from a set of candidate inexistent links incident to v in order to minimize the shortest distance from v to other nodes [Parotsidis et al., 2016].
The problem of maximizing the centrality of a specific target node through adding edges incident to it has been widely studied. For examples, some authors have studied the problem of creating k edges linked to a node v so that the centrality value for v with respect to concerned centrality measures is maximized, e.g., betweenness centrality [Crescenzi et al., 2015; D'Angelo et al., 2016; Crescenzi et al., 2016; Hoffmann et al., 2018] and closeness centrality [Crescenzi et al., 2015; Hoffmann et al., 2018]. Similar optimization problems for a predefined node v were also addressed for other node centrality metrics, including average shortest distance between v and remaining nodes [Meyerson and Tagiku, 2009; Parotsidis et al., 2016], largest distance from v to other nodes [Demaine and Zadimoghaddam, 2010], PageRank [Avrachenkov and Litvak, 2006; Olsen, 2010], and the number of different paths containing v [Ishakian et al., 2012]. However, previous works do not consider improving information centrality of a node by adding new edges linked to it, despite the fact that it can better distinguish different nodes, compared with betweennees [Newman, 2005] and closeness centrality [Bergamini et al., 2016].
In this paper, we study the following problem: Given a graph with n nodes and m edges, how to create k new edges incident to a designated node v, so that the information centrality Iv of v is maximized. Since Iv equals the reciprocal of the sum of resistance distance Rv between v and all nodes, we reduce the problem to minimizing Rv by introducing k edges connecting v. We demonstrate that the optimization function is monotone and supermodular. To minimize resistance distance Rv, we present two greedy approximation algorithms by iteratively introducing k edges one by one. The former is a (1- 1e )-approximation algorithm with O(n3 ) time complexity, while the latter is a (1- 1e - ϵ)- approximation algorithm with ˜O(mkϵ-2 ) time complexity, where the ˜O(·) notation hides poly(logn) factors. We test the performance of our algorithms on several model and real networks, which substantially increase information centrality score of a given node and outperform several other adding edge strategies.
2 Preliminary
Consider a connected undirected weighted network G = (V,E,w) where V is the set of nodes, E ⊆ V × V is the set of edges, and w : E → R+ is the edge weight function. We use wmax to denote the maximum edge weight. Let n = |V | denote the number of nodes and m = |E| denote the number of edges. For a pair of adjacent nodes u and v, we write u ∼ v to denote (u, v) ∈ E. The Laplacian matrix of G is the symmetric matrix L = D - A, where A is the weighted adjacency matrix of the graph and D is the degree diagonal matrix.
Let ei denote the ith standard basis vector, and bu,v = eu - ev. We fix an arbitrary orientation for all edges in G. For each edge e ∈ E, we define be = bu,v, where u and v are head and tail of e, respectively. It is easy to verify that L = ∑e∈E w(e)beb ⊤e , where w(e)beb ⊤e is the Laplacian of e. L is singular and positive semidefinite. Its pseudoinverse L† is (L+ 1n J )-1 - 1n J, where J is the matrix with all entries being ones.
For network G = (V, E, w), the resistance distance [Klein and Randi´c, 1993] between two nodes u, v is Ruv = b ⊤u,v L†bu,v. The resistance distance Rv of a node v is the sum of resistance distances between v and all nodes in V , that is, Rv = ∑u∈V Ruv, which can be expressed in terms of the entries of L† as [Bozzo and Franceschet, 2013]
Let Lv denote the submatrix of Laplacian L, which is obtained from L by deleting the row and column corresponding to node v. For a connected graph G, Lv is invertible for any node v, and the resistance distance Ruv between v and another node u is equal to (L-1 v )uu [Izmailian et al., 2013]. Thus, we have
The resistance distance Rv can be used as a measure of the efficiency for node v in transmitting information to other nodes, and is closely related to information centrality introduced by Stephenson and Zelen to measure the importance of nodes in social networks [Stephenson and Zelen, 1989]. The information Iuv transmitted between u and v is defined as
where B = L+J . The information centrality Iv of node v is the harmonic mean of Iuv over all nodes u [Stephenson and Zelen, 1989].
Definition 2.1 For a connected graph G = (V,E,w), the information centrality Iv of a node v ∈ V is defined as
It was shown [Brandes and Fleischer, 2005] that
We continue to introduce some useful notations and tools for the convenience of description for our algorithms, including ϵ-approximation and supermodular function.
Let a, b ≥ 0 be two nonnegative scalars. We say a is an ϵ-approximation [Peng and Spielman, 2014] of b if exp(-ϵ) a ≤ b ≤ exp(ϵ) a. Hereafter, we use a ≈ϵ b to represent that a is an ϵ-approximation of b.
Let X be a finite set, and 2X be the set of all subsets of X. Let f : 2X → R be a set function on X. For any subsets S ⊂ T ⊂ X and any element a ∈ X \ T, we say function f(·) is supermodular if it satisfies f(S) - f(S ∪ {a}) ≥ f(T) - f(T ∪ {a}). A function f(·) is submodular if -f(·) is supermodular. A set function f : 2X → R is called monotone decreasing if for any subsets S ⊂ T ⊂ X, f(S) > f(T ) holds.
3 ProblemFormulation
For a connected undirected weighted network G(V,E,w), given a set S of weighted edges not in E, we use G + S to denote the network augmented by adding the edges in S to G, i.e. G+S = (V,E ∪ S,w′ ), where w′ : E ∪ S →R+ is the new weight function. Let L(S) denote the Laplacian matrix for G+S. Note that the information centrality of a node depends on the graph topology. If we augment a graph by adding a set of edges S, the information centrality of a node will change. Moreover, adding edges incident to some node v can only increase its information centrality [Doyle and Snell, 1984].
Assume that there is a set of nonexistent edges incident to a particular node v, each with a given weight. We denote this candidate edge set as Ev. Consider choosing a subset S of k edges from the candidate set Ev to augment the network so that the information centrality of node v is maximized. Let Iv(S) denote the information centrality of the node v in augmented network. We define the following set function optimization problem:
Since the information centrality Iv of a node v is proportional to the reciprocal of Rv, the optimization problem (4) is equivalent to the following problem:
where Rv(S) is the resistance distance of v in the augmented network G + S.
4 Supermodularity of Objective Function
Let 2Ev denote all subsets of Ev. Then the resistance distance of node v in the augmented network can be represented as a set function Rv : 2Ev → R. To provide effective algorithms for the above-defined problems, we next prove that the resistance distance of v is a supermodular function.
Rayleigh's monotonicity law [Doyle and Snell, 1984] shows that the resistance distance between any pair of nodes can only decrease when edges are added. Then, we have the following theorem.
Theorem 4.1 Rv(S) is a monotonically decreasing function of the set of edges S. That is, for any subsets S ⊂ T ⊂ Ev,
We then prove the supermodularity of the objective function Rv (S).
Theorem 4.2 Rv(S) is supermodular. For any set S ⊂ T ⊂ Ev and any edge e ∈ Ev \ T ,
Proof. Suppose that edge e connects two nodes u and v, then L(S ∪ {e})v = L(S)v + w(e)Euu, where Euu is a square matrix with the uth diagonal entry being one, and all other entries being zeros. By (2), it suffices to prove that
Since S is a subset of T , L(T )v = L(S)v +P, where P is a nonnegative diagonal matrix. For simplicity, in the following proof, we use M to denote matrix L(S)v. Then, we only need to prove
Define function f(t), t ∈ [0,∞), as
Then, the above inequality holds if f(t) takes the minimum value at t = 0. We next show that f(t) is an increasing function by proving df(t) dt ≥ 0. Using the matrix derivative formula
we can differentiate function f(t) as
Let N = M + tEuu, and let Q be a nonnegative diagonal matrix with exactly one positive diagonal entry Qhh > 0 and all other entries being zeros. We now prove that N -1 ij ≥ (N + Q)-1 ij for 1 ≤ i, j ≤ n- 1. Using Sherman-Morrison formula [Meyer, 1973], we have
Since N is an M-matrix, every entry of N -1 is positive [Plemmons, 1977], it is the same with every entry of N -1ehe ⊤h N -1 . In addition, the denominator 1 + Qhhe ⊤h N -1eh is also positive, because N is positive definite. Therefore, N -1 - (N +Q)-1 is a positive matrix, the entries of which are all greater than zero.
By repeatedly applying the above process, we conclude that N -1 ≥ (N +P)-1 is a positive matrix. Thus,
which completes the proof. ✷
5 Simple Greedy Algorithm
Theorems 4.1 and 4.2 indicate that the objective function (5) is monotone and supermodular. Thus, a simple greedy algorithm is sufficient to approximate problem (5) with provable optimality bounds. In the greedy algorithm, the augmented edge set S is initially empty. Then k edges are iteratively added to the augmented edge set from the set Ev of candidate edges. At each iteration, an edge ei in the candidate edge set is selected to maximize Rv(S) -Rv(S ∪ {ei}). The algorithm terminates when |S| = k.
According to (1), the effective resistance Rv is equal to nL†vv +Tr(L† ). A naive algorithm requires O(k|Ev|n3 ) time complexity, which is prohibitively expense. Below we show that the computation cost can be reduced to O(n3 ) by using Sherman-Morrison formula [Meyer, 1973].
Lemma 5.1 For a connected weighted graph G = (V, E, w) with weighted Laplacian matrix L, let e be a nonexistent edge with given weight w(e) connecting node v. Then,
For a candidate edge not added to S, let R∆v (e) = Rv(S)- Rv(S∪{e}). Lemma 5.1 and (1) lead to the following result.
Lemma 5.2 Let G = (V,E,w) be a connected weighted graph with weighted Laplacian matrix L. Let e ̸∈ E be a candidate edge with given weight w(e) incident to node v. Then,
Lemma 5.2 yields a simple greedy algorithm EXACTSM(G, v,Ev, k), as outlined in Algorithm 1. The first step of this algorithm is to compute the pseudoinverse of L, the time complexity of which is O(n3 ) time. Then this algorithm works in k rounds, each involving operations of computations and updates with time complexity O(n2 ). Thus, the total running time of Algorithm 1 is O(n3 ).
Algorithm 1: EXACTSM(G, v, Ev, k)
Input : A connected graph G; a node v ∈ V ; a candidate edge set Ev; an integer k ≤ |Ev| Output : A subset of S ⊂ Ev and |S| = k 1 Initialize solution S = ∅ 2 Compute L† 3 for i = 1 to k do 4 Compute R∆v (e) for each e ∈ Ev \ S 5 Select ei s.t. ei ← argmaxe∈Ev\SR∆v (e) 6 Update solution S ←S ∪ {ei} 7 Update the graph G←G(V,E ∪ {ei}) 8 Update L† ←L† - w(ei)L† bei b ⊤ei L† 1+w(ei)b ⊤ei L† bei 9 return SMoreover, due to the result in [Nemhauser et al., 1978], Algorithm 1 is able to achieve a (1 - 1e ) approximation factor, as given in the following theorem.
Theorem 5.3 The set S returned by Algorithm 1 satisfies
where S∗ is the optimal solution to (5), i.e.,
6 Fast Greedy Algorithm
Although Algorithm 1 is faster than the naive algorithm, it is still computationally infeasible for large networks, since it involves the computation of the pseudoinverse for L. In this section, in order to avoid inverting the matrix L, we give an efficient approximation algorithm, which achieves a (1- 1e - ϵ) approximation factor of optimal solution to problem (5) in time ˜O(kmϵ-2 ).
6.1 Approximating R∆v (e)
In order to solve problem (5), one need to compute the key quantity R∆v (e) in (6). Here, we provide an efficient algorithm to approximate R∆v (e) properly.
We first consider the denominator in (6). Assume that the new added edge e connects nodes u and v. Note that the term re = b ⊤e L†be in the denominator is in fact the resistance distance Ruv between u and v in the network excluding e. It can be computed by the following approximation algorithm [Spielman and Srivastava, 2011].
Lemma 6.1 Let G = (V,E,w) be a weighted connected graph. There is an algorithm APPROXIER(G,Ev, ϵ) that returns an estimate ˆ re of re for all e ∈ Ev in ˜O(mϵ-2 ) time. With probability at least 1 - 1/n, ˆ re ≈ϵ re holds for all e ∈ Ev.
For the numerator of (6), it includes two terms, (L†beb ⊤e L†)vv and Tr (L†beb ⊤e L†). The first term can be calculated by (L†beb ⊤e L†)vv = e ⊤v L†beb ⊤e L†ev. The second term is the trace of an implicit matrix which can be approximated by Hutchinson's Monte-Carlo method [Hutchinson, 1989]. By generating M independent random ±1 vectors x1, x2, · · · , xM ∈ Rn (i.e., independent Bernoulli entries), 1M ∑Mi=1 x ⊤i Axi can be used to estimate the trace of matrix A. Since E [x ⊤i Axi ] = Tr (A), by the law of large numbers, 1M ∑Mi=1 x ⊤i Axi should be close to Tr (A) when M is large. The following lemma [Avron and Toledo, 2011] provides a good estimation of Tr (A).
Lemma 6.2 Let A be a positive semidefinite matrix with rank rank(A). Let x1, . . . , xM be independent random ±1 vectors. Let ϵ, δ be scalars such that 0 < ϵ ≤ 1/2 and 0 < δ < 1. For any M ≥ 24ϵ-2 ln(2rank(A)/δ), the following statement holds with probability at least 1 - δ:
Thus, we have reduced the estimation of the numerator of (6) to the calculation of the quadratic form of L†beb ⊤e L† . If we directly compute the quadratic form, we must first evaluate L† , the time complexity is high. To avoid inverting L, we will utilize the nearly-linear time solver for Laplacian systems from [Kyng and Sachdeva, 2016], whose performance can be characterized in the following lemma.
Lemma 6.3 The algorithm y = LAPLSOLVE(L, z , ϵ) takes a Laplacian matrix L of a graph G with n nodes and m edges, a vector z ∈ Rn and a scalar ϵ > 0 as input, and returns a vector y ∈ Rn such that with probability 1 - 1/poly(n) the following statement holds:
where ‖x‖L = √x ⊤Lx. The algorithm runs in expected time ˜O(m).
Lemmas 6.1, 6.2 and 6.3 result in the following algorithm VREFFCOMP(G, v,Ev, ϵ) for computing R∆v (e) for all e ∈ Ev, as depicted in Algorithm 2. The algorithm has a total running time ˜O(mϵ-2 ), and returns a set of pairs {(e, ˆR∆v (e))|e ∈ Ev}, satisfying that R∆v (e) ≈ϵ ˆR∆v (e) for all e ∈ Ev.
Algorithm 2: VREFFCOMP(G, v, Ev, ϵ) Input : A graph G; a node v ∈ V ; a candidate edge set Ev; a real number 0 ≤ ϵ ≤ 1/2 Output : {(e, ˆR∆v (e))|e ∈ Ev} 1 Let z1, . . . , zM be independent random±1 vectors, where M = ⌈432ϵ-2 ln(2n)⌉. 2 for i = 1 toM do 3 y i ← LAPLSOLVE(L, z i, 1 72 ϵn-8w-4 max) 4 for each e ∈ Ev do 5 Compute ti(e) def = y ⊤i beb ⊤e y i 6 x ← LAPLSOLVE(L, ev, 1 72 ϵn-9w-4 max) 7 for each e ∈ Ev do 8 Compute α(e) def = x ⊤beb ⊤e x 9 ˆ re ← APPROXIER(G, ϵ/3) nα(e)+ 1M M∑i ti (e) 1+w(e)ˆ re for each e6.2 Fast Algorithm for Objective Function
By using Algorithm 2 to approximate R∆v (e), we give a fast greedy algorithm APPROXISM(G, v,Ev, k, ϵ) for solving problem (5), as outlined in Algorithm 3.
Algorithm 3: APPROXISM(G, v, Ev, k, ϵ)
Input : A graph G; a node v ∈ V ; a candidate edge set Ev; an integer k ≤ |Ev|; a real number 0 ≤ ϵ ≤ 1/2 Output : S: a subset of Ev and |S| = k 1 Initialize solution S = ∅ 2 for i = 1 to k do 3 {e, ˆR∆v (e)|e ∈ Ev\S} ← VREFFCOMP(G, v,Ev\S, 3ϵ). 4 Select ei s.t. ei ← argmaxe∈Ev\S ˆR∆v (e) 5 Update solution S ←S ∪ {ei} 6 Update the graph G←G(V,E ∪ {ei})7 return S
Algorithm 3 works in k rounds (Lines 2-6). In every round, the call of VREFFCOMP and updates take time ˜O(mϵ-2 ). Then, the total running time of Algorithm 3 is ˜O(kmϵ-2 ). The following theorem shows that the output ˆ S of Algorithm 3 gives a (1- 1e - ϵ) approximate solution to problem (5).
Theorem 6.4 For any 0 < ϵ ≤ 1/2, the set ˆ S returned by the greedy algorithm above satisfies
where S∗ is the optimal solution to problem (5), i.e.,
We omit the proof, since it is similar to that in [Badanidiyuru and Vondr´ak, 2014].
| Network | n | m | n′ | m′ |
|---|---|---|---|---|
| BA network | 50 | 94 | 50 | 94 |
| WS network | 50 | 100 | 50 | 100 |
| Zachary karate club | 34 | 78 | 34 | 78 |
| Windsufers | 43 | 336 | 43 | 336 |
| Jazz musicians | 198 | 2742 | 195 | 1814 |
| Virgili | 1,133 | 5,451 | 1,133 | 5,451 |
| Euroroad | 1,174 | 1,417 | 1,039 | 1,305 |
| Hamster full | 2,426 | 16,631 | 2,000 | 16,098 |
| 2,888 | 2,981 | 2,888 | 2,981 | |
| Powergrid | 4,941 | 6,594 | 4,941 | 6,594 |
| ca-GrQc | 5,242 | 14,496 | 4,158 | 13,422 |
| ca-HepPh | 12,008 | 118,521 | 11,204 | 117,619 |
| com-DBLP | 317,080 | 1,049,866 | 317,080 | 1,049,866 |
| roadNet-TX | 1,379,917 | 1,921,660 | 1,351,137 | 1,879,201 |
7 Experiments
In this section, we experimentally evaluate the effectiveness and efficiency of our two greedy algorithms on some model and real networks. All algorithms in our experiments are implemented in Julia. In our algorithms, we use the LAPLSOLVE [Kyng and Sachdeva, 2016], the implementation (in Julia) of which is available on website 1 . All experiments were conducted on a machine with 4.2 GHz Intel i77700 CPU and 32G RAM.
We execute our experiments on two popular model networks, Barab´asi-Albert (BA) network and Watts-Strogatz (WS) network, and a large connection of realistic networks from KONECT [Kunegis, 2013] and SNAP 2 . Table 1 provides the information of these networks, where real-world networks are shown in increasing size of the number of nodes in original networks.
7.1 Effectiveness of Greedy Algorithms
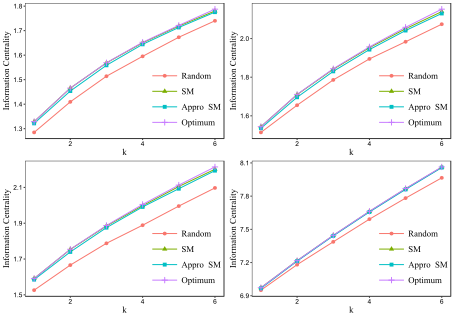
To show the effectiveness of our algorithms, we compare the results of our algorithms with the optimum solutions on two small model networks, BA network and WS network, and two small real-world networks, Zachary karate club network and Windsufers contact network. Since these networks are small, we are able to compute the optimal edge set.
For each network, we randomly choose 20 target nodes. For each target node v, the candidate edge set is composed of all nonexistent edges incident to it with unit weight w = 1. And for each designated k = 1, 2, · · · , 6, we add k edges linked to v and other k non-neighboring nodes of v. We then compute the average information centrality of the 20 target nodes for each k. Also, we compute the solutions for the random scheme, by adding k edges from randomly selected k non-neighboring nodes. The results are reported in Figure 1. We observe that there is little difference between the solutions of our greedy algorithms and the optimal solutions, since their approximation ratio is always greater than 0.98, which is far better than the theoretical guarantees. Moreover, our greedy schemes outperform the random scheme in these four networks.
1 https://github.com/danspielman/Laplacians.jl
2 https://snap.stanford.edu
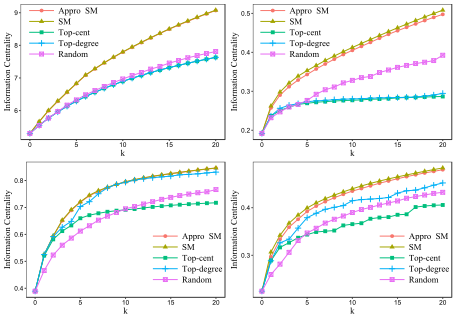
To further demonstrate the effectiveness of our algorithms, we compare the results of our methods with the random scheme and other two baseline schemes, Top-degree and Top-cent, on four other real-world networks. In Top-degree scheme, the added edges are simply the k edges connecting target node v and its nonadjacent nodes with the highest degree in the original network; while in Top-cent scheme, the added edges are simply those k edges connecting target node v and its nonadjacent nodes with the largest information centrality in the original network.
Since the results may vary depending on the initial information centrality of the target node v, for each of the four real networks, we select 10 different target nodes at random. For each target node, we first compute its original information centrality and increase it by adding up to k = 20 new edges, using our two greedy algorithms and the three baselines. Then, we compute and record the information centrality of the target node after insertion of every edge. Finally, we compute the average information centrality of all the 10 target nodes for each k = 1, 2, . . . , 20, which is plotted in Figure 2. We observe that for all the four real-world networks our greedy algorithms outperform the three baselines.
7.2 Efficiency Comparison of Greedy Algorithms
Although both of our greedy algorithms are effective, we will show that their efficiency greatly differs. To this end, we compare the efficiency of the greedy algorithms on several realworld networks. For each network, we choose stochastically 20 target nodes, for each of which, we create k = 10 new edges incident to it to maximize its information centrality according to Algorithms 1 and 3. We compute the average information centrality of 10 target nodes for each network and record the average running times. In Table 2 we provide the results of average information centrality and average running time of our greedy algorithms. We observe that APPROXISM algorithm are faster than EXACTSM algorithm, especially for large networks, while their final information centrality score are close. More interestingly, APPROXISM applies to massive networks. For example, for com-DBLP and roadNet-TX
| Network | Time (seconds) | Information centrality | ||||
|---|---|---|---|---|---|---|
| ASM | ESM | Ratio | ASM | ESM | Ratio | |
| Virgili | 1.3996 | 0.9172 | 1.5259 | 2.5005 | 2.5037 | 0.9987 |
| Euroroad | 0.6563 | 0.7593 | 0.8643 | 0.4003 | 0.4069 | 0.9838 |
| Hamster full | 3.0785 | 4.8528 | 0.6344 | 2.9904 | 2.9944 | 0.9987 |
| 1.7151 | 12.9203 | 0.1327 | 0.7937 | 0.7947 | 0.9987 | |
| Powergrid | 5.8727 | 58.3359 | 0.1006 | 0.4327 | 0.4369 | 0.9904 |
| ca-GrQc | 5.3023 | 34.0228 | 0.1558 | 1.2118 | 1.2136 | 0.9985 |
| ca-HepPh | 28.7462 | 620.4557 | 0.0463 | 2.2569 | 2.2592 | 0.9990 |
| com-DBLP | 697.1835 | - | - | 1.1327 | - | - |
| roadNet-TX | 1569.5059 | - | - | 0.0556 | - | - |
networks, APPROXISM computes their information centrality in half an hour, while APPROXISM fails due to its high time complexity.
8 Conclusions
In this paper, we considered the problem of maximizing the information centrality of a designated node v by adding k new edges incident to it. This problem is equivalent to minimizing the resistance distance Rv of node v. We proposed two approximation algorithms for computing Rv when k edges are repeatedly inserted in a greedy way. The first one gives a (1 - 1e ) approximation of the optimum in time O(n3 ). While the second one returns a (1 - 1e - ϵ) approximation in time ˜O(mkϵ-2 ). Since the considered problem has never been addressed before, we have no other algorithms to compare with, but compare our algorithms with potential alternative algorithms. Extensive experimental results on model and realistic networks show that our algorithms can often compute an approximate optimal solution. Particularly, our second algorithm can achieve a good approximate solution very quickly, making it applicable to massive networks.
@inproceedings{ijcai2018p491,
  title     = {Improving Information Centrality of a Node in Complex Networks by Adding Edges},
  author    = {Shan, Liren and Yi, Yuhao and Zhang, Zhongzhi},
  booktitle = {Proceedings of the Twenty-Seventh International Joint Conference on
               Artificial Intelligence, {IJCAI-18}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Jérôme Lang},
  pages     = {3535--3541},
  year      = {2018},
  month     = {7},
  note      = {Main track},
  doi       = {10.24963/ijcai.2018/491},
  url       = {https://doi.org/10.24963/ijcai.2018/491},
}
TY - CPAPER TI - Improving Information Centrality of a Node in Complex Networks by Adding Edges AU - Shan, Liren AU - Yi, Yuhao AU - Zhang, Zhongzhi T2 - Proceedings of the Twenty-Seventh International Joint Conference on Artificial Intelligence, IJCAI-18 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2018 SP - 3535 EP - 3541 DO - 10.24963/ijcai.2018/491 UR - https://doi.org/10.24963/ijcai.2018/491 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





