
Differential Equations for Modeling Asynchronous Algorithms
Proceedings of the Twenty-Seventh International Joint Conference on Artificial Intelligence. Main track. Pages 2220-2226.
https://doi.org/10.24963/ijcai.2018/307
Keywords
- Machine Learning: Learning Theory
- Machine Learning: Machine Learning
Abstract
Asynchronous stochastic gradient descent (ASGD) is a popular parallel optimization algorithm in machine learning. Most theoretical analysis on ASGD take a discrete view and prove upper bounds for their convergence rates. However, the discrete view has its intrinsic limitations: there is no characterizationof the optimization path and the proof techniques are induction-based and thus usually complicated. Inspired by the recent successful adoptions of stochastic differential equations (SDE) to the theoretical analysis of SGD, in this paper, we study the continuous approximation of ASGD by using stochastic differential delay equations (SDDE). We introduce the approximation method and study the approximation error. Then we conduct theoretical analysis on the convergence rate of ASGD algorithm based on the continuous approximation.There are two methods: moment estimation and energy function minimization can be used to analyzethe convergence rates. Moment estimation depends on the specific form of the loss function, while energy function minimization only leverages the convex property of the loss function, and does not depend on its specific form. In addition to the convergence analysis, the continuous view also helps us derive better convergence rates. All of this clearly shows the advantage of taking the continuous view in gradient descent algorithms.
- [Agarwal and Duchi, 2011] Alekh Agarwal and John C Duchi. Distributed delayed stochastic optimization. In Ad- vances in Neural Information Processing Systems, pages 873-881, 2011.
- [Balles et al., 2017] Lukas Balles, Javier Romero, and Philipp Hennig. Coupling adaptive batch sizes with learn- ing rates. Conference on Uncertainty in Artificial Intelli- gence, 2017.
- [Bao et al., 2014] Jianhai Bao, George Yin, and Chenggui Yuan. Ergodicity for functional stochastic differential e- quations and applications. Nonlinear Analysis: Theory, Methods & Applications, 98:66-82, 2014.
- [Bao et al., 2016] Jianhai Bao, George Yin, and Chenggui Yuan. Asymptotic analysis for functional stochastic dif- ferential equations, 2016.
- [Dean et al., 2012] Jeffrey Dean, Greg Corrado, Rajat Mon- ga, Kai Chen, Matthieu Devin, Mark Mao, Andrew Senior, Paul Tucker, Ke Yang, Quoc V Le, et al. Large scale dis- tributed deep networks. In Advances in neural information processing systems, pages 1223-1231, 2012.
- [Durrett, 2010] Rick Durrett. Probability: theory and exam- ples. Cambridge university press, 2010.
- [Johnson and Zhang, 2013] Rie Johnson and Tong Zhang. Accelerating stochastic gradient descent using predictive variance reduction. In Advances in Neural Information Processing Systems, pages 315-323, 2013.
- [Krichene et al., 2015] W Krichene, Am Bayen, and Pl Bartlett. Accelerated mirror descent in continuous and discrete time. pages 2845-2853, 2015.
- [Langford et al., 2009] John Langford, Alex J Smola, and Martin Zinkevich. Slow learners are fast. Advances in Neural Information Processing Systems, 22:2331-2339, 2009.
- [Li et al., 2016] Chris Junchi Li, Zhaoran Wang, and Han Li- u. Online ica: Understanding global dynamics of non- convex optimization via diffusion processes. In Advances in Neural Information Processing Systems, pages 4961- 4969, 2016.
- [Li et al., 2017] Qianxiao Li, Cheng Tai, and Weinan E. S- tochastic modified equations and adaptive stochastic gra- dient algorithms. In Proceedings of the 34th Internation- al Conference on Machine Learning, pages 2101-2110, 2017.
- [Lian et al., 2015] Xiangru Lian, Yijun Huang, Yuncheng Li, and Ji Liu. Asynchronous parallel stochastic gradien- t for nonconvex optimization. In International Conference on Neural Information Processing Systems, pages 2737- 2745, 2015.
- [Mandt et al., 2016] Stephan Mandt, Matthew D Hoffman, and David M Blei. A variational analysis of stochastic gradient algorithms. In Proceedings of The 33rd Interna- tional Conference on Machine Learning, pages 354-363, 2016.
- [Mao, 2007] Xuerong Mao. Stochastic differential equations and applications. Elsevier, 2007.
- [Raginsky and Bouvrie, 2012] Maxim Raginsky and J Bou- vrie. Continuous-time stochastic mirror descent on a network: Variance reduction, consensus, convergence. 23(1):6793-6800, 2012.
- [Rakhlin et al., 2011] Alexander Rakhlin, Ohad Shamir, and Karthik Sridharan. Making gradient descent optimal for strongly convex stochastic optimization. arXiv preprint arXiv:1109.5647, 2011.
- [Recht et al., 2011] Benjamin Recht, Christopher Re, Stephen Wright, and Feng Niu. Hogwild: A lock-free approach to parallelizing stochastic gradient descent. In Advances in Neural Information Processing Systems, pages 693-701, 2011.
- [Su et al., 2014] Weijie Su, Stephen Boyd, and Emmanuel Candes. A differential equation for modeling nesterov's accelerated gradient method: theory and insights. In Ad- vances in Neural Information Processing Systems, pages 2510-2518, 2014.
- [Uhlenbeck and Ornstein, 1930] George E Uhlenbeck and Leonard S Ornstein. On the theory of the brownian mo- tion. Physical review, 36(5):823, 1930.
- [Wibisono et al., 2016] Andre Wibisono, Ashia C Wilson, and Michael I Jordan. A variational perspective on acceler- ated methods in optimization. Proceedings of the National Academy of Sciences, page 201614734, 2016.
- [Yang et al., 2017] Lin F. Yang, R. Arora, V. Braverman, and Tuo Zhao. The physical systems behind optimization al- gorithms. 2017.
- [Zhang et al., 2015] Sixin Zhang, Anna E Choromanska, and Yann LeCun. Deep learning with elastic averaging sgd. In Advances in Neural Information Processing Systems, pages 685-693, 2015.
- [Zheng et al., 2017] Shuxin Zheng, Qi Meng, Taifeng Wang, Wei Chen, Nenghai Yu, Zhi-Ming Ma, and Tie-Yan Li- u. Asynchronous stochastic gradient descent with delay compensation. In International Conference on Machine Learning, pages 4120-4129, 2017.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Asynchronous stochastic gradient descent (ASGD) is a popular parallel optimization algorithm in machine learning [Langford et al., 2009; Agarwal and Duchi, 2011; Recht et al., 2011; Lian et al., 2015; Zhang et al., 2015]. It has been broadly used in solving deep neural network and received many successes in practice recently, which significantly reduce the communication overhead by avoiding idleness. The main issue with asynchronous algorithms lies on using delayed stochastic gradient information. Suppose {(a1, b1), · · · , (ai, bi), · · · , (an, bn)} is the training data set, where the input vector ai ∈ Rd and the output bi ∈ R. Supervised machine learning algorithms aim to minimize the empirical risk, i.e.,
∗This work was done when the authors were visiting Microsoft Research Asia.
where fi(x) = l(x; ai, bi) is the loss of model x for the training instance (ai, bi). ASGD uses multiple threads or local workers to calculate the gradient of the loss function using a mini-batch of training instances. Then the local worker push the gradient to a master and pull the latest parameter from the master. The master uses the received gradient to update the parameter x. Because there is no synchronization between the local workers, the gradient which the master received may be a delayed information for the parameter [Agarwal and Duchi, 2011; Recht et al., 2011; Lian et al., 2015]. The update rule for ASGD at iteration k can be described as:
where ηk is the learning rate, gMk (b, xk-lk ) is the stochastic gradient calculated using the minibatch Mk with minibatch size b, lk ≥ 0 denotes the stochastic delay. In general, it assumes that lk, ∀k or Elk is upper bounded [Agarwal and Duchi, 2011; Lian et al., 2015].
The delayed information will influence the convergence rate of the optimization algorithms. Theoretical analyses have been conducted on ASGD for various problem settings, mostly from a discrete view, in which the convergence rate is proved by induction for the sequence of iterative of the optimization algorithm. Then they compare it with the convergence rate of sequential stochastic gradient descent to get the speedup condition. For example, [Recht et al., 2011] shows that for convex problem, if the training data is sparse enough, ASGD can achieve linear speedup. [Lian et al., 2015] shows that for nonconvex problems, if the delay is upper bounded by the stochastic sampling variance, ASGD can achieve linear speedup.
However, the discrete view has its intrinsic limitations. (1) It cannot provide an explicit characterization of the optimization path, thus lacks insights about the optimization process. (2) The proofs of optimization algorithms are usually induction-based and somehow unavoidably complicated.
In recent years, researchers study the dynamics of optimization algorithms by taking a continuous view. They derive the corresponding differential equations of the existing discrete-time optimization methods by regarding the optimization rule as the numerical solution of a differential equation. Many works [Raginsky and Bouvrie, 2012; Wibisono et al., 2016; Su et al., 2014; Li et al., 2016; Yang et al., 2017; Mandt et al., 2016; Krichene et al., 2015] study sequential optimization algorithms using continuous view from various aspects. For example, [Raginsky and Bouvrie, 2012] used the continuous time analysis to study mirror descent algorithm. In [Wibisono et al., 2016] and [Su et al., 2014], some accelerated methods were studied by the continuous techniques such as second-order ordinary differential equations. In [Li et al., 2017], the authors developed the method of stochastic modified equations (SME), in which stochastic gradient algorithms are approximated in the weak sense by continuous-time SDE. These works provide a clearer understanding of the dynamic optimization process than the previous works that only take the discrete view, thus have the potential in addressing the aforementioned limitations of the discrete view. However, most of the above works are focusing on sequential algorithms, and using continuous techniques to study asynchronous algorithms has not been studied yet.
Inspired by these works, in this paper, we study the continuous approximation of asynchronous stochastic gradient descent. First, we propose a procedure to approximate asynchronous stochastic gradient based algorithms by using stochastic differential delay equations. Then we analyze the approximation error and show that the approximation error is related to the number of iteration K and mini-batch size b.
Second, within this approximation, we study the convergence rates by using continuous techniques and show the following results. (1) For the linear regression problem which is solved by SGD with constant learning rate, we can attain full information of the optimization path, including the first and second-order moments. (2) For SDDEs, although it is hard to obtain full information, we can still analyze the optimization path by using moment estimation and energy function minimization. Moment estimation depends on the specific form of the loss function but has nothing to do with its convexity property, whereas energy function minimization leverages the convexity property but does not depend on its specific form. (3) By using these two techniques, in addition to characterizing the optimization path, we also get the convergence rates of optimization algorithms, with a much simpler proof than that from discrete view. Specifically, we prove a tighter convergence rate for ASGD than the other existing results [Zheng et al., 2017; Recht et al., 2011].
All of these results clearly demonstrate the advantages of taking the continuous view in analyzing ASGD algorithm.
2 Backgrounds
In this section, we briefly review the basic settings of asynchronous stochastic gradient descent algorithm, and introduce the stochastic differential delay equations.
2.1 Basic Settings of ASGD
Asynchronous Stochastic Gradient Descent is an efficient parallel algorithm. Local workers or threads do not need to wait for others to do synchronization, thus the model is updated faster compared with the synchronous SGD. ASGD updates the parameter using a delayed gradient and has been proved achieving linear or sub-linear speedup under certain conditions such as the training data are sparse or the delay can be upper bounded [Agarwal and Duchi, 2011; Recht et al., 2011; Lian et al., 2015]. In this paper, we consider the update rule of ASGD under the consistent read setting [Lian et al., 2015]. Let Mk be the index of a mini-batch with size b and ηk be the learning rate for k-th iteration. We denote gMk (b, xk) = 1b ∑i∈Mk ∇fi(xk) as the averaged gradient calculated by a mini-batch. The update rule of ASGD is
where lk is a random delay satisfying 0 ≤ lk ≤ l. 1 Sequential SGD is a special case of ASGD with lk = 0, ∀k.
2.2 Stochastic Differential Delay Equation
Stochastic differential delay equation (SDDE) for a ddimensional continuous process X = (X(t))t≥0 is a natural generalization of stochastic differential equation (SDE) by allowing the coefficients depending on values in the past, which has been studied by researchers [Mao, 2007; Bao et al., 2016]. We consider the following form:
where Xt = {X(t - θ(t)) : 0 ≤ θ(t) ≤ τ} is the segment (or the functional solution), θ(t) is a random variable describing the random delay and τ is its upper bound. The symbol B(t) denotes r-dimensional Brownian motion [Durrett, 2010]. Denote by C([-τ, 0];Rd ) the family of continuous functions ξ from [-τ, 0] to Rd with the norm ∥ξ∥ = sups∈[-τ,0]∥ξ(s)∥. Then Xt is regarded as a C([-τ, 0];Rd )-valued stochastic process. The vector g1 ∈ Rd and the matrix g2 ∈ Rd ×Rr are appropriate functions. For the sake of simplicity, we consider the case of d = r in this paper. SDE can be regarded as a special case of SDDE with θ(t) = 0, ∀t.
3 Continuous Approximation of Asynchronous Optimization Methods
In this section, we first propose the continuous approximation of ASGD by using SDDE and describe the approximation procedure in detail. Then we analyze the approximation error for the continuous approximation of ASGD.
First, we introduce some notations. We relate the discrete iterations with continuous stochastic process by introducing the ansatz xk ≈ X(kδ) where X(t) : R+ ∪ {0} → Rd is a continuous function of t. Given t ∈ [0, T ], we have T = δK, where K is the total number of discrete iterations and δ is the interval to do discretization of X(t) which we call the time step. The discrete index of iterations and continuous index of time have the relation: X(t + δ) ≈ x(t+δ)/δ := xk+1, X(t) ≈ xt/δ := xk. We define the covariance matrix of ∇fi(xk) as
Since gMk (b, xk) is a sum of b i.i.d random vectors ∇fi(xk), then the covariance matrix of gMk (b, xk) is Σ(xk) b [Balles et al., 2017; Li et al., 2017].
1 ASGD under inconsistent read setting will be studied as the future work.
3.1 Asynchronous Gradient Methods
Most existing approximations are built for sequential algorithms [Li et al., 2017; Mandt et al., 2016], while asynchronous gradient methods are widely used due to its efficiency in utilizing multiple computational nodes [Recht et al., 2011; Agarwal and Duchi, 2011; Dean et al., 2012; Zhang et al., 2015; Zheng et al., 2017]. Therefore, in this section, we describe how to approximate the update rule of ASGD using SDDEs.
Consider the following asynchronous gradient methods
where η is a deterministic learning rate and uk ∈ [0, 1] is an adjustment function of k. The symbol lk denotes the random delay and gMk (b, xk-lk ) denotes the delayed information such as delayed gradient.
We first give the following proposition (Theorem 3.9.6, [Durrett, 2010], [Balles et al., 2017]), on which our transformation and approximation error analysis are based.
Proposition 3.1 The ∇F(xk-lk )-gMk (b, xk-lk ) converges weakly to a multivariate normal distribution with mean ⃗0 and covariance matrix Σ(xk-lk )/b.
Moreover, we assume positive definiteness and a square root decomposition of the covariance matrix of Σ(xk-lk )/b, i.e.,
Let zks be i.i.d random vectors which follow standard normal distribution N(⃗0, Id×d). Thus, we can use σ(xk-lk )zk to approximate the noise term (by Central Limit Theorem). Therefore, the above equation can be approximated by
Choosing a precision δ, we can view the Eq.(5) as an EulerMaruyama approximation of the following SDDE [Mao, 2007]:
where θ(t) = lkδ. We assume that 0 ≤ lk ≤ l and denote τ := lδ. In the following, we give several possible choices for the time step under different cases. (a) For ASGD with constant learning rate η = η0 and uk = 1, we choose the δ = η0. (b) For decreasing learning rate η = η0 and uk = 1k , we have U(t) = δt . We can choose any precision. (c) For η = η0 and uk = 1 √k , since U(t) = √δ √t , we choose δ = η0.
In summary, we used SDDE to approximate ASGD through Eq.(4), Eq.(5) and Eq.(6). Many asynchronous gradient methods can be represented by Eq.(4), such as ASGD, asynchronous SVRG, etc.
Using above similar technique, Nesterov's accelerated and momentum stochastic gradient methods can be transformed into two stage SDEs. Besides, the continuous approximation can be described by a second-order SDE. We omit the explicit transform because it is not the main case which will be studied in this paper. For more details, it can be referred in [Su et al., 2014; Li et al., 2017].
3.2 Approximation Error
In this subsection, we study the approximation error between X(tk), produced by the continuous process and xk which is produced by the discrete process. We applied Central Limit Theorem and Euler-Maruyama approximation of stochastic delay differential equation in analyzing approximation error. Now we give the following Theorem 3.2-3.4 and proof sketches, which show the approximation error between the update produced by ASGD (Eq.(4)) and its corresponding SDDE (Eq.(6)) in different cases.
Theorem 3.2 Assume that ∇F (x) is L-Lipschitz continuous, and b is the mini-batch size. Consider delay lk with upper bound l and uk = 1 for k = 1, . . . ,K. If we consider ASGD with δ = η, η = 1K and ηL(l + 1) ≤ 1, we have
where C1, C2 are constants.
Proof sketch: (1) For SDDE with U(t) = 1, the EulerMaruyama scheme with δ = η is
where B(tk+1) - B(tk) is usually modeled by √ηzk. It is well-known that the Euler-Maruyama scheme is strongly convergent with order 12 . According to (Theorem 5.5.5 [Mao, 2007]), we have E(∥X(tk) - ˜xk∥) ≤ ˜ C1η3/2 (k + l)e2(ηk)2 . Let η = 1K , we can obtain
(2) Next, let us consider the relationship between xk+1 and ˜xk+1. By the central limit theorem (CLT), we can get that ∇F(xk-lk )-gMk (b, xk-lk ) converges to σ(xk-lk )zk in distribution with the increasing minibatch size b. Assume that ∇F(xk) is L-Lipschitz continuous and using Theorem 3.4.9 in [Durrett, 2010], the gap between their distribution functions goes to zero at rate b- 1 2 . Since ASGD uses a delayed gradient, it will cause the mismatch between xk and gMk (b, xk-lk ) when we expand the series. We have
Denote E∥η[σ(˜xk-lk )zk - ∇F(xk-lk ) + gMk (b, xk-lk )]∥ as Φ(k), then we have
where tr(Σ) denotes the trace of the matrix and we derived the last step by simple matrix computations.
Denote ηΦ √b = supks=0Φ(s) as an upper bound. Let Ak = E∥xk - ˜xk∥ and A0 = 0. We consider a probability qj is assumed for each lk = j, j = 0, 1, · · · , l. 2 Taking expectation and using upper bound, it becomes
Thus we have Ak ≤ ηL ∑l+1 j=1 (A1-j + · · · + Ak-j) + k ηΦ √b ≤ ηL(l + 1)(A0 + A1 + · · · + Ak-1) + k ηΦ √b , where A0 = 0, A1 = ηL(l + 1)A0 + ηΦ √b . Using this recursion, we obtain
where we used integration approximation. In the last step, we assumed that ηL(l +1) ≤ 1 and used ηL(l+1) 2 ≤ ηL(l+1)-
(ηL(l+1))2
2 ≤ ln(1+ ηL(l +1)). Let η = 1K , we have
where C1,C2 are constants. □
If we consider the upper bound l = 0, ASGD reduces to SGD. We give the following corollary.
Corollary 3.3 Assume that ∇F(x) is L-Lipschitz continuous, and b is the mini-batch size. Consider delay lk with upper bound l = 0 and uk = 1 for k = 1, . . . ,K. The SGD with δ = η, η = 1K and ηL ≤ 1, we have
where C1, C2 are constants.
The above theorem just assumes that the delay can be upper bounded. If we further assume that the randomness of the delay can be neglected, for example, a cyclic delayed update architecture [Agarwal and Duchi, 2011], the results can be improved. In this case, we give the following theorem.
Theorem 3.4 Assume that ∇F (x) is L-Lipschitz continuous, and b is the mini-batch size. Consider delay lk = l and uk = 1 for k = 1, . . . , K. If we consider ASGD with δ = η, η = 1K and ηLl ≤ 1, we have
where C3, C4 are constants.
2 It should be noted that for k ≤ l, the random delay lk only take values from the set {0, 1, · · · , k}.
Proof sketch: The analysis between X(tk) and ˜xk follows from the proof of Theorem 3.2. We analyze the relationship between xk and ˜xk. Using the above inequality and A0 = 0, we can get
Furthermore, we have the following recursion relation:
Using that Al + · · · + A1 ≤ 2(1+ηL)l
Assume that ηLl ≤ 1 and using ηLl 2 ≤ ln(1+ηLl), we obtain
Let η = 1K , now we have the following bound
where C3, C4 are constants. □
The Lipschitzs coefficient is relatively a small constant. For example, we have L ≤ 1 and L ≤ 0.25 for linear regression and logistic regression, respectively. Theorem 3.2 shows that the approximation error of ASGD will be small if the number of iterations K and the minibatch size b are large. The delay l has influence on the two parts. This is consistent with the intuition that delay will cause mismatch of the updates. From Theorem 3.4, when the delay equals to a constant, its approximation error is similar to that of SGD since l does not have influence on the part of eL √b .
4 Convergence Analysis: Techniques and Examples
In this section, we show some techniques using SDDE for convergence analysis. Firstly, we introduce the measure for convergence analysis. Taking SDE as a simple example, for fixed t, the SDE becomes an ODE after taking expectation of X(t). We can get the optimum x∗ by taking limits limt→∞ EX(t). Secondly, we can calculate E(X(t) - x∗ ) and E||X(t) - EX(t)||2 for each fixed t. Combining them we can get the convergence of E||X(t) - x∗ ||2 .
Usually, SDEs can be classified into two cases: analytic solution case and non-analytic solution case. An example of SDE with analytic solution is linear regression solved by SGD with constant learning rate. The objective function is F(x) = 1 2n ∥Ax - B∥2 , with A = (aT1 , . . . , aTn )T and B = (b1, . . . , bn)T , x ∈ Rd , ai ∈ Rd and bi ∈ R. Denote ˜ A = 1n AT A. The solution of its SDE is an OrnsteinUhlenbeck process [Uhlenbeck and Ornstein, 1930]:
We can calculate the moments directly, i.e.,
From the above results, we can get many insights about the dynamics of SGD, such as the oscillation of the sample path which has been discussed in [Li et al., 2017].
However, SDDEs are more difficult to obtain analytic solution. For non-analytic solution case, it is hard to calculate the exact moments of X(t) - x∗ , we can use two methods to estimate them to achieve the convergence for ASGD: moment estimation and energy function minimization.
4.1 Moment Estimation
We show the moment estimation technique by taking linear regression as an example. It can also be used for nonconvex loss functions. Before showing the details, we need to guarantee the existence and uniqueness of the solutions for SDDEs. Uniform Lipschitz condition and linear growth condition are two conditions to guarantee the existence and uniqueness of the solutions for SDDE [Mao, 2007]. We should see that these two conditions have no direct relation with convexity. For our continuous approximation, we do not care the explicit form of σ(X(t - θ(t))) (except for variance reduced techniques are involved such as SVRG [Johnson and Zhang, 2013]) and just assume that it has an upper bound thus it is a constant about X(t-θ(t)). In this case, the diffusion term satisfies linear growth and Lipschitz conditions. We just need to check whether -∇F (X(t-θ(t))) satisfies the two conditions.
We use Theorem 5.2.2 in [Mao, 2007] to guarantee the existence and uniqueness of the solution to SDDE. We consider the ASGD with constant learning rate η for the linear regression. The corresponding SDDE is
where θ(t) ∈ [0, τ]. Here we consider θ(t) = τ and τ is its upper bound. Following the techniques in [Bao et al., 2016; 2014], we can bound the first and second moments and give the following theorem.
Theorem 4.1 Define V = sup{Re(β) : β ∈ C, det(βId×d + ˜ Ae-βτ ) = 0}. For any given training error ϵ, let η = ϵ τ 2 . If V < 0, then for λ ∈ (0, -V ), the convergence rate for ASGD for linear regression Eq.(7) by using moment estimation is
where C5 and C6 are constants. 3
3 The coefficients are related to the root of characteristic function of the SDDE.
Proof sketch: Through some lengthy derivation [Bao et al., 2016], we have ∥E(X(t)) - x∗ ∥ ≤ a1e-λt and E∥X(t) - EX(t)∥2 ≤ a2(1 - e-2λt ) where the coefficient a1 is cλ∥˜ ξ∥ + cλ∥˜ ξ∥∥ ˜ A∥(eλτ - 1) 1λ , a2 is c2λ E∥√ησ∥2 2λ and x∗ = ˜ A-1 ˜B. Moreover, we can obtain
Thus by putting a1 and a2 in it , we have
Putting η = ϵ τ 2 in the above equation, we can get
Discussion: We compare the results with the existing convergence rates of ASGD under consistent read setting. If we don't assume the data are sparse, the number of iterations is no less than O( τϵ ) to achieve E∥xk - x∗ ∥2 ≤ ϵ [Zheng et al., 2017]. Another well-known theoretical result is O( log(1/ϵ) ϵ · τ 2 ) if we let the sparse coefficients be 1 and set η = ϵ τ 2 [Recht et al., 2011] 4 . Theorem 4.1 shows that we need e-2λ(t-τ) ≤ ϵ in order to make E∥X(t) - x∗ ∥2 ≤ O(ϵ). Thus we need t ≥ O(τ + log (1/ϵ) 2λ ), which is in common faster than the previous two results O( τϵ ) and O( log (1/ϵ) ϵ · τ 2 ).
4.2 Energy FunctionMinimization
In this section, we show the energy function minimization. This technique has been explored in many works [Su et al., 2014; Krichene et al., 2015; Wibisono et al., 2016]. Firstly, we need to define proper energy function for corresponding differential equation. Energy function is related to the measure which is used for the convergence rate of optimization, such as ∥X(t) - x∗ ∥2 , F(X(t)) - F(x∗ ) and the expected convergence rate for the optimization algorithms. Suppose that we use ASGD to minimize a strongly convex loss function. We can define the energy function for SDDE as E(t) = t-1 2 ∥X(t) - x∗ ∥2 - (δ+1)(H+2L2D2 τ) ln t 2µ2 and calculate dEE(t) by using Itˆo formula. If dEE(t) ≤ 0, we can get EE(t) is a decreasing function about t. Then the convergence rate for SDDE is obtained by using EE(t) ≤ E(t0). Thus, the design for energy function aims to make dEE(t) ≤ 0. Theorem 4.2 shows the convergence rate for SDDE.
Theorem 4.2 For any F ∈ F∞ with smooth coefficient L, let X(t) be the unique global solution to (6) with initial conditions X(s) = ξ(s), s ∈ [-τ, 0] and X(t) ∈ d(x0,D), ∀t. Assume that F(x) is strongly convex about x and ηk = 1 µk . Let H be a constant which satisfies H ≥ E(Tr(σσT )) + 2µLD2 . For any t > 1,
4 Please notice that the theoretical analysis in [Recht et al., 2011] is proved under consistent read setting.
Proof sketch: For strongly convex case, ηk is set as ηk = 1 µk . Then we have η = 1 and U(t) = δ
where H ≥ E(Tr(σσT )) + 2µLD2 . Using Itˆo formula and taking expectation, we can get
The first equality comes from Itˆo formula. The first inequality applied the positiveness of 1 2µ2 t2 ETr(σσT ) and strongly convex assumption. Therefore, we have
where τ is the upper bound of θ(t). □
When we consider the special case of τ = 0, ASGD algorithm reduces to SGD algorithm. We can similarly define an energy function E(t) = t-1 2 ∥X(t) -x∗ ∥2 - (δ+1)H ln t 2µ2 and we give the following corollary.
Corollary 4.3 For any F ∈ F∞ with smooth coefficient L, let X(t) be the unique global solution to
with initial conditions X(1) = x0 and X(t) ∈ d(x0,D), ∀t. Assume that F(x) is strongly convex about x and ηk = 1 µk . Let H ≥ E(T r(σσT )) + 2µLD2 . For any t > 1,
Discussions: Since the approximation error is relatively small, the convergence rate of SDDE can be approximated as the result of ASGD. (1) We prove a tighter convergence rate for ASGD than the other existing results. The result in Theorem 4.2 is no slower than the convergence rate O(τ/ϵ) [Zheng et al., 2017]. If 2L2D2 τ ≤ H, the negative influence of τ can be neglected, which means that it is comparable with the serial SGD and it can achieve linear speedup. Compared with the results in [Recht et al., 2011], the speedup condition does not rely on the sparsity condition. If the stochastic variance E(Tr(σσT )) is large, the condition 2L2D2 τ ≤ H is easier to be satisfied, which is consistent to the results for non-convex case studied in [Lian et al., 2015].
(2) Corollary 4.3 shows that E∥xk - x∗ ∥2 ≤ (δ+1)H ln(δk) (δk-1)µ2 since t = δk. It is comparable with the existing convergence rate of 4H kµ2 [Rakhlin et al., 2011] under the same setting.
5 Experiments
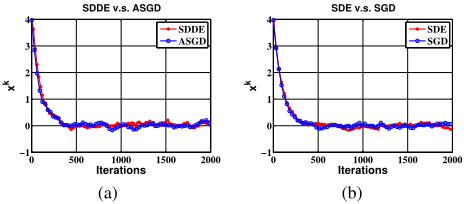
In this section, we take F(x) = 12 (x + 1)2 + 1 2 (x - 1)2 as a simple example. We compared the discrete optimization algorithms with the Euler-Maruyama schemes of stochastic differential equations.
For optimization iteration and Euler-Maruyama scheme, the learning rate is set to be η = 0.005. We run the experiments within 2000 iterations. The figures include ASGD (resp. SGD) path and a sample path for SDDE (resp. SDE) approximation. First, we analyzed SDDE for ASGD algorithm. The time interval of the SDDE is [0, T] where T = ηK and K is the total number of ASGD iterations. For SDDE, we set the initial function as ξ(θ) = 4 for any θ ∈ [-τ, 0]. For ASGD, we assume a constant delay as l = 10 and let X(0) = 4. Since the delay l = 10, we run the SGD during the first ten steps and ASGD iterations are used from ten steps on. It is observed that the two paths are close. Second, from Fig.1(b) we can see that the SDE approximation and SGD iteration are well matched.
6 Conclusions
In this paper, we studied the continuous approximation of asynchronous stochastic gradient descent algorithm. We analyzed the approximation error and conducted theoretical analyses on the convergence rates of asynchronous stochastic gradient decent algorithms by continuous methods: moment estimation and energy function minimization. From the aspect of continuous view, we cannot only obtain existing results by the discrete view, but also get new results. For applications of this view, it can also be referred at [Mandt et al., 2016; Li et al., 2016]. To the best of our knowledge, we firstly give a continuous description to asynchronous stochastic gradient descent, and proved a tighter bound. In the future, we will apply this unified continuous view to analyze more optimization algorithms in more tasks.
Acknowledgements
We would like to thank Liping Li and Jianhai Bao for their helpful discussions and suggestions. Zhi-Ming Ma was partially supported by National Center for Mathematics and Interdisciplinary Sciences of Chinese Academy of Sciences.
@inproceedings{ijcai2018p307,
  title     = {Differential Equations for Modeling Asynchronous Algorithms},
  author    = {He, Li and Meng, Qi and Chen, Wei and Ma, Zhi-Ming and Liu, Tie-Yan},
  booktitle = {Proceedings of the Twenty-Seventh International Joint Conference on
               Artificial Intelligence, {IJCAI-18}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Jérôme Lang},
  pages     = {2220--2226},
  year      = {2018},
  month     = {7},
  note      = {Main track},
  doi       = {10.24963/ijcai.2018/307},
  url       = {https://doi.org/10.24963/ijcai.2018/307},
}
TY - CPAPER TI - Differential Equations for Modeling Asynchronous Algorithms AU - He, Li AU - Meng, Qi AU - Chen, Wei AU - Ma, Zhi-Ming AU - Liu, Tie-Yan T2 - Proceedings of the Twenty-Seventh International Joint Conference on Artificial Intelligence, IJCAI-18 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2018 SP - 2220 EP - 2226 DO - 10.24963/ijcai.2018/307 UR - https://doi.org/10.24963/ijcai.2018/307 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





