
A Multi-task Learning Approach for Image Captioning
Proceedings of the Twenty-Seventh International Joint Conference on Artificial Intelligence. Main track. Pages 1205-1211.
https://doi.org/10.24963/ijcai.2018/168
Keywords
- Humans and AI: Cognitive Modeling
- Machine Learning: Transfer, Adaptation, Multi-task Learning
- Computer Vision: Language and Vision
Abstract
In this paper, we propose a Multi-task Learning Approach for Image Captioning (MLAIC ), motivated by the fact that humans have no difficulty performing such task because they possess capabilities of multiple domains. Specifically, MLAIC consists of three key components: (i) A multi-object classification model that learns rich category-aware image representations using a CNN image encoder; (ii) A syntax generation model that learns better syntax-aware LSTM based decoder; (iii) An image captioning model that generates image descriptions in text, sharing its CNN encoder and LSTM decoder with the object classification task and the syntax generation task, respectively. In particular, the image captioning model can benefit from the additional object categorization and syntax knowledge. To verify the effectiveness of our approach, we conduct extensive experiments on MS-COCO dataset. The experimental results demonstrate that our model achieves impressive results compared to other strong competitors.
- [Anderson et al., 2017] Peter Anderson, Xiaodong He, Chris Buehler, Damien Teney, Mark Johnson, Stephen Gould, and Lei Zhang. Bottom-up and top-down attention for im- age captioning and vqa. arXiv preprint arXiv:1707.07998, 2017.
- [Bernardi et al., 2016] Raffaella Bernardi, Ruket Cakici, Desmond Elliott, Aykut Erdem, Erkut Erdem, Nazli Ikizler-Cinbis, Frank Keller, Adrian Muscat, and Barbara Plank. Automatic description generation from images: A survey of models, datasets, and evaluation measures. JAIR, 55:409-442, 2016.
- [Caruana, 1998] Rich Caruana. Multitask learning. In Learning to learn, pages 95-133. Springer, 1998.
- [Chen et al., 2017] Long Chen, Hanwang Zhang, Jun Xiao, Liqiang Nie, Jian Shao, Wei Liu, and Tat-Seng Chua. Sca- cnn: Spatial and channel-wise attention in convolutional networks for image captioning. In CVPR, 2017.
- [Gu et al., 2017a] Jiuxiang Gu, Jianfei Cai, Gang Wang, and Tsuhan Chen. Stack-captioning: Coarse-to-fine learning for image captioning. arXiv preprint arXiv:1709.03376, 2017.
- [Gu et al., 2017b] Jiuxiang Gu, Gang Wang, Jianfei Cai, and Tsuhan Chen. An empirical study of language cnn for im- age captioning. In ICCV, 2017.
- [He et al., 2016] Kaiming He, Xiangyu Zhang, Shaoqing Ren, and Jian Sun. Deep residual learning for image recog- nition. In CVPR, pages 770-778, 2016.
- [Karpathy and Fei-Fei, 2015] Andrej Karpathy and Li Fei- Fei. Deep visual-semantic alignments for generating im- age descriptions. In CVPR, pages 3128-3137, 2015.
- [Li et al., 2017] Yuncheng Li, Yale Song, and Jiebo Luo. Im- proving pairwise ranking for multi-label image classifica- tion. arXiv preprint arXiv:1704.03135, 2017.
- [Lin et al., 2014] Tsung-Yi Lin, Michael Maire, Serge Be- longie, James Hays, Pietro Perona, Deva Ramanan, Pi- otr Dollár, and C Lawrence Zitnick. Microsoft coco: Common objects in context. In ECCV, pages 740-755. Springer, 2014.
- [Liu et al., 2016] Siqi Liu, Zhenhai Zhu, Ning Ye, Sergio Guadarrama, and Kevin Murphy. Optimization of image description metrics using policy gradient methods. arXiv preprint arXiv:1612.00370, 2016.
- [Lu et al., 2016] Jiasen Lu, Caiming Xiong, Devi Parikh, and Richard Socher. Knowing when to look: Adaptive attention via a visual sentinel for image captioning. arXiv preprint arXiv:1612.01887, 2016.
- [Nadejde et al., 2017] Maria Nadejde, Siva Reddy, Rico Sennrich, Tomasz Dwojak, Marcin Junczys-Dowmunt, Philipp Koehn, and Alexandra Birch. Predicting target language ccg supertags improves neural machine transla- tion. In Proceedings of the Second Conference on Machine Translation, pages 68-79, 2017.
- [Pasunuru and Bansal, 2017] Ramakanth Pasunuru and Mo- hit Bansal. Multi-task video captioning with video and entailment generation. arXiv preprint arXiv:1704.07489, 2017.
- [Pu et al., 2016] Yunchen Pu, Zhe Gan, Ricardo Henao, Xin Yuan, Chunyuan Li, Andrew Stevens, and Lawrence Carin. Variational autoencoder for deep learning of im- ages, labels and captions. In NIPS, pages 2352-2360, 2016.
- [Rennie et al., 2016] Steven J Rennie, Etienne Marcheret, Youssef Mroueh, Jarret Ross, and Vaibhava Goel. Self- critical sequence training for image captioning. arXiv preprint arXiv:1612.00563, 2016.
- [Russakovsky et al., 2015] Olga Russakovsky, Jia Deng, Hao Su, Jonathan Krause, Sanjeev Satheesh, Sean Ma, Zhiheng Huang, Andrej Karpathy, Aditya Khosla, Michael Bernstein, et al. Imagenet large scale visual recognition challenge. IJCV, 115(3):211-252, 2015.
- [Vedantam et al., 2015] Ramakrishna Vedantam, C Lawrence Zitnick, and Devi Parikh. Cider: Consensus- based image description evaluation. In CVPR, pages 4566-4575, 2015.
- [Venugopalan et al., 2016] Subhashini Venugopalan, Lisa Anne Hendricks, Raymond Mooney, and Kate Saenko. Improving lstm-based video description with linguistic knowledge mined from text. In arXiv preprint arXiv:1604.01729, 2016.
- [Vinyals et al., 2015] Oriol Vinyals, Alexander Toshev, Samy Bengio, and Dumitru Erhan. Show and tell: A neu- ral image caption generator. In CVPR, pages 3156-3164, 2015.
- [Vinyals et al., 2017] Oriol Vinyals, Alexander Toshev, Samy Bengio, and Dumitru Erhan. Show and tell: Lessons learned from the 2015 mscoco image captioning chal- lenge. TPAMI, 39(4):652-663, 2017.
- [Williams, 1992] Ronald J Williams. Simple statistical gradient-following algorithms for connectionist reinforce- ment learning. Machine Learning, 8:229-256, 1992.
- [Wu et al., 2016] Qi Wu, Chunhua Shen, Lingqiao Liu, An- thony Dick, and Anton van den Hengel. What value do ex- plicit high level concepts have in vision to language prob- lems? In CVPR, pages 203-212, 2016.
- [Xu et al., 2015] Kelvin Xu, Jimmy Ba, Ryan Kiros, Kyunghyun Cho, Aaron Courville, Ruslan Salakhudinov, Rich Zemel, and Yoshua Bengio. Show, attend and tell: Neural image caption generation with visual attention. In ICML, pages 2048-2057, 2015.
- [Zhao et al., 2017] Wei Zhao, Wei Xu, Min Yang, Jianbo Ye, Zhou Zhao, Yabing Feng, and Yu Qiao. Dual learning for cross-domain image captioning. In CIKM, pages 29-38, 2017.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Humans have the remarkable capability to describe an image verbally because they are naturally multi-task intelligent agents. Humans have developed those skills since childhood by not only learning to perform a single task, but rather adapting to comprehend the complex outer world via multi-channel perceptions and communications. They are trained in fact by performing multiple relevant tasks together to develop a comprehensive set of skills to understand and describe a scenario. If one desires to create a machine intelligence imitating such a comprehensive skill set of human, studying all relevant tasks that contribute its development is quite a necessary step.
In this paper, we are motivated by the fact that a cognitive AI is by nature multi-tasking and develop a computerized image captioning agent that can also perform a few other related tasks. Image captioning, as to generate a sentence describing the salient aspects of an image, is a fundamental task in computer vision and natural language processing [Bernardi et al.,
∗Min Yang is corresponding author (min.yang@siat.ac.cn)
1 Codes are publicly available at https://goo.gl/iZtCBB.
w/o syntax: a man holding a tennis ball with a tennis ball.
w/o object: a man holding a tennis ball.
Our Model: a man hitting a tennis ball with a tennis racket.
a suitcase filled with lots of items and. a suitcase filled with lots of items. a suitcase filled with lots of items on a bed.
Table 1: Examples of captions that fail to respect to syntax structure and missing salient object "bed" and "racket".
2016]. In recent years, it is often approached with supervised learning framework by collecting human generated examples and developing models that base on matching the generated text to those collected annotations. We suppose such learning frameworks are theoretically of limited success in two dimensions. First, the model created from the collected data can only comprehend the complexity of the problem subject to the degree of complexities of presented examples. Since the dataset is more or less a finite collection, the presented complexities should be limited. Second, the loss function used in numerically optimizing the model is often not sensitive to certain aspects of the structured output that have not been emphasized in the conventional evaluation metric of image captioning, such as object categories and syntax of generated sentences. In fact, we show that exposing the learning framework with more relevant data and objectives can be helpful in both dimensions.
Multi-task learning is hardly a new idea for machine learning, but often remains as a non-trivial step for building empirically successful systems. We argue that it is essentially the case for creating an effective image captioning system. In an ablation study of our models (see Table 1), a model which is unaware of the sentence syntax could generate a broken sentence for describing a picture; a model which does not recognize all presented objects could generate a descriptive sentence missing a salient object in the picture. Yet, an improved system whose components have been co-trained with multiple related tasks could generate a more satisfied sentence for accurately and correctly describing a picture. Based on this observation, we believe a multi-task learning framework helps to improve an image captioning system in dimensions that have not been quantitatively measured in conventional evaluation metrics.
Our system exploits the recent successes of the encoderdecoder framework to generate image captions [Karpathy and Fei-Fei, 2015; Vinyals et al., 2015]. The common idea of this framework is to use a convolutional neural network (CNN) as an encoder to extract features representing the visual understandings of an input image and then feed the feature vector to a recurrent neural network (RNN) based decoder so as to generate image captions. Sharing this standard framework with other related approaches, we in this paper propose additional regularizations using multi-task learning. Firstly, our CNN encoder is regularized with the co-training to perform an additional task of multi-object classification. Secondly, our RNN decoder is also regularized with the co-training to perform another task of syntax annotation [Nadejde et al., 2017]. The purpose of co-training is not to achieve the best performance on these auxiliary tasks, but rather to compensate for the missing regularization requirement of image captions in the standard framework.
We summarize our main contributions as follows:
- We propose MLAIC, a multi-task learning system to jointly train the task of image captioning and two other related tasks: multi-object classification and syntax generation. The auxiliary tasks help to enhance the CNN encoder and the RNN decoder in the image captioning model. Specifically,
- Multi-object classification co-trained with image captioning intends to learn an object-rich image encoder and improves the quality of locating contextual information of an image.
- The variations of style and wording of captions with respect to different object categories are explored under controlled experimental settings.
- The RNN decoder is capable to leverage word-level syntax to generate high-quality captions from language modeling perspective. It alleviates the issues of incomplete sentences and duplicated words.
- The experimental results show that MLAIC achieves outstanding performance on the widely used MSCOCO dataset according to both the offline Karpathy test spilt and the online server evaluation.
2 RelatedWork
Generating text descriptions from images is a challenging problem. Bernardi et al. [2016] provided a detailed review of most existing approaches, the benchmark datasets, and the evaluation measures for image captioning.
Recent advances in deep neural networks have substantially improved the performance of image captioning task. A typical image captioning strategy is to combine CNN and RNN [Karpathy and Fei-Fei, 2015; Vinyals et al., 2015], where CNN is used to extract the compact representational vector of a whole image, and RNN is used to construct the language model operated on the representation vectors to generate captions. Visual attention has been proven as an effective way to improve the basic encoder-decoder framework. For example, Xu et al. [2015] introduced an attention-based model that automatically learn where to attend when generating image descriptions. The attention is modeled as spatial probabilities that re-weight the feature map of the last convolutional layer in the CNN. Chen et al. [2017] dynamically modulated the sentence generation context in multi-layer feature maps, encoding where (i.e., attentive spatial locations at multiple layers) and what (i.e., attentive channels) the visual attention was.
There have been increasing interests in integrating the encoder-decoder framework and reinforcement learning paradigms for image captioning [Liu et al., 2016; Rennie et al., 2016; Zhao et al., 2017]. For example, Liu et al. [2016] employed policy gradient (PG) method to directly optimize a linear combination of SPICE and CIDEr metrics, where the SPICE score ensured the captions were semantically faithful to the image, and CIDEr score ensured the captions are syntactically fluent. Rennie et al. [2016] proposed a self-critical sequence training (SCST) method by employing the popular REINFORCE algorithm.
Multi-task learning is a useful learning paradigm to improve the supervision and the generalization performance of a task by jointly training it with related tasks [Caruana, 1998]. Venugopalan et al. [2016] explored linguistic improvements to the video caption decoder by fusing it with external language models. Pasunuru and Bansal [2017] improved video captioning by sharing knowledge with two related directedgeneration tasks: a temporally-directed unsupervised video prediction task and a logically-directed language entailment generation task.
Our model differs from the above approaches. We perform image captioning by multi-task learning, which shares knowledge with three related tasks: multi-label classification, image captioning, syntax generation, so that we can improve the performance of both the CNN encoder and LSTM decoder.
3 Our Model
Given an image x, for the object classification, we have yo = {yo 1 , yo 2 , ..., yoC } denoting the object vector of each image, where yo i = 1 if object i is annotated in this image; otherwise yo i = 0, C is the number of object categories. For image captioning, we have yw = {yw 1 , yw 2 , ..., yw T } denoting the image description given image x, where T is the length of sequence. For syntax generation, we have ys = {ys 1 , ys 2 , ..., ysT } denoting the Combinatory Category Gramma (CCG) supertag sequence with respect to the corresponding caption of image x. We use Ww, Ws and Wo to denote the vocabularies of captions, annotated CCG supertags and object categories, respectively.
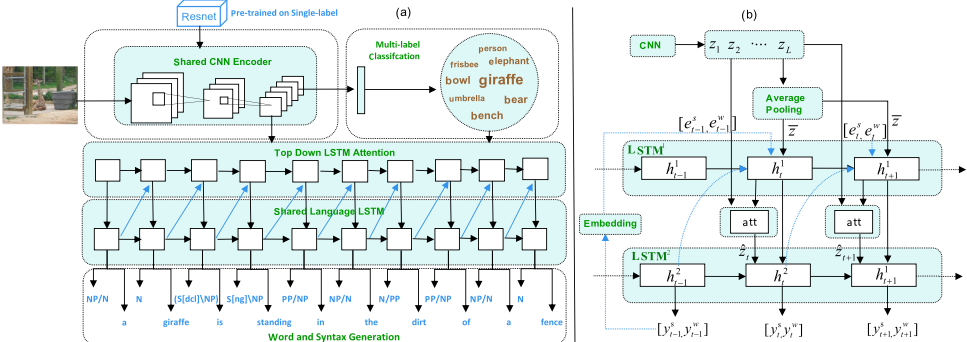
Our model MLAIC, whose framework is illustrated in Figure 1, jointly trains the image captioning task with two related tasks: the object classification and the syntax generation. The object classifier shares its CNN encoder with the encoder of image captioning task. All object labels are encoded into lowdimensional distributed embeddings and treated as extra input to LSTM decoder, helping the LSTM decoder focus on different aspects of the images with respect to the object labels. The syntax generation task shares its LSTM decoder with the decoder of image captioning, which predicts words and syntax by training the shared LSTM decoder in a similar fashion as is done in [Nadejde et al., 2017]. Next, we elaborate the three tasks in details.
3.1 Shared CNN Encoder
We use the ResNet-101 [He et al., 2016] pre-trained on ImageNet [Russakovsky et al., 2015] as our CNN encoder to encode the input image x into L vectors, each of which is a D-dimensional vector corresponding to the features extracted at different locations of the image. These vectors are referred to as annotation vectors.
We also introduce zfc to represent object probability of image x calculated by fully connected layer: zfc = FC(z). Following the work of [Xu et al., 2015], we extract feature vectors on the lower convolutional layer rather than use the fully connected layer. In this way, the decoder can selectively attend to certain parts of an image by weighting a subset of the feature vectors. In our experiments, we use the 14 × 14 × 2048 feature map in ResNet-101. That said, our LSTM decoder operates on the flattened 196×2048 (i.e. L×D) representations. The shared CNN encoder is then fine-tuned with both image captioning and multi-object classification tasks.
3.2 Shared LSTMDecoder
The image captioning task shares its LSTM decoder with the decoder of syntax generation task. Following [Anderson et al., 2017], the decoder consists of two stacked LSTM networks. The first LSTM layer (denoted as LSTM(1) ) is characterized as a top-down visual attention model, while the second LSTM layer (denoted as LSTM(2) ) is a language model. The attention model takes input as the concatenation of the previous output of the language LSTM (i.e., h(2) t-1 ), the meanpooled image feature ¯ z = 1L ∑i zi, the word embedding of the previously generated word (i.e., ewt-1 ), and its syntax embedding (i.e., est-1 ):
where x(1) t is the input of LSTM(1) at time step t. The hidden state of attention LSTM at time step t is then computed by:
Given the output of the attention LSTM h(1) = {h(1) 1 , h(1) 2 , . . . , h(1) T }, where T is the length of the sequence, we compute the attended image feature ˆ z, which is then used as the input to the language LSTM. The attended image feature ˆ z makes sure that every time step of the decoder can get full information of the context. We calculate ˆ zt when we decode the t-th word by
Here, the attention weight αt,i for the i-th annotation of CNN encoder is computed by
where σ is a feed-forward neural network, which maps a vector to a real-valued score. This attention weights αt,i models the alignment between the image content at location i and the output word at position t.
We use the LSTM language model to produce a caption (or a CCG supertag sequence) by generating one word (or CCG supertag) at every time step, which takes as input the concatenation of the output of the attention LSTM (h(1) t ) and the attended image feature ( ˆ zt), given by:
where x(2) t is the input of LSTM(2) .
The hidden state of the language model LSTM at time t is then computed by
Finally, the generation probabilities of the t-th word and the t-th CCG supertag are given by
where U w , U s , bw and bs are the parameters to be learned.
Incorporating Object Label Embeddings To explore the variations of caption styles for images of different objects, we integrate the object label embeddings in the LSTM decoder. A forgetting gate is introduced to determine when the object label information contributes, which is computed by ft = sigmoid (h(2) t-1 , zfc). Then the biased word generation probability is given as:
where W is transformation matrix to project object label into word embedding space. IWo (·) is the indicator vector denoting whether candidate word w is in the vocabulary Wo of object categories.
3.3 Multi-task Learning
Our MLAIC model consists of three subtasks, each has its own training objective. For the object classification subtask, the model minimizes the multi-label margin loss function following the work of [Li et al., 2017]:
where θ is the set of parameters, zfc j denotes the probability that image x contains object j, wj is the weight indicating the frequency of occurrence of object j in the image, b is a hyper-parameter that determines the margin, commonly set to 1.0.
For the syntax generation and image captioning subtasks, we employ the minimum negative log-likelihood estimation:
For the purpose of improving shared CNN encoder and LSTM decoder, we train these three related tasks simultaneously. The joint multi-task objective function is minimized by:
For comparison with recent work [Rennie et al., 2016], we also optimize directly for CIDEr [Vedantam et al., 2015] using policy gradient algorithm, and minimize the negative expected rewards:J word
where r(.) is CIDEr score function. According to the policy gradient theorem [Williams, 1992], we compute the gradient of the expected reward with respect to parameters as:
After pre-training the proposed model by minimizing the negative log-likelihood with multi-task using Eq.13, we switch the model to further minimize a mixed training objective, integrating the reinforcement learning objective Jrl with the original multi-task loss.
where β is a hyper-parameter, and we set β = 0.005.
4 Experimental Setup
4.1 Dataset
In our experiment, we use the widely used MSCOCO 2014 image captions [Karpathy and Fei-Fei, 2015] as our dataset, which consists of totally 82,783 training, 40,504 validation, and 40,775 testing images, each of which has 5 ground truth captions. For the off-line testing, we adopt the commonly used Karpathy split [Karpathy and Fei-Fei, 2015], which uses 113,287 images for training, and 5,000 images for validation and testing, respectively. For the on-line server evaluation, our model is trained on 118,287 images and validated on 5,000 images.
For multi-label object classification, we use the MSCOCO detection dataset [Lin et al., 2014], which consists of 500,000 object instances from 80 different object categories. It contains the same images and shares the same data split with MSCOCO 2014 image captions dataset [Karpathy and FeiFei, 2015].
For syntax generation, following the work of [Nadejde et al., 2017], the captions of training data is annotated with CCG supertags by using EasySRL 2 , where each word has a corresponding dependency label of supertags.
4.2 Baseline Methods
In the experiments, we compare our model with stateof-the-art methods, and several recent strong competitors are included below: Adaptive [Lu et al., 2016], SCST: Att2in/Att2all [Rennie et al., 2016], TopDown: ResNet/UpDown [Anderson et al., 2017], StackCap [Gu et al., 2017a]. In the experiments, we use the same parameter settings as in the original papers.
4.3 Implementation Details
We first pre-train our model on the training data with crossentropy cost, and use Adam optimizer with an initial learning rate 5× 10⁻⁴ and a momentum parameter of 0.9 to optimize the parameters. After that, we run the proposed RL-based approach on the just trained model, which is directly optimized for the CIDEr metric. During this stage, we use Adam optimizer with learning rate 5×10⁻⁵ . We set λ1=0.2, λ2=0.7, λ3=0.1. We set the number of hidden units in TopDown attention LSTM (LSTM(1) ) to 1,000, the number of hidden units in language model LSTM (LSTM(2) ) to 512, the size of the input word embedding to 512, and the size of the CCG supertag embedding to 100. During the decoding stage, we use a beam size of 5 to generate captions.
2 https://github.com/uwnlp/EasySRL
| BLEU-1 | BLEU-2 | BLEU-3 | BLEU-4 | METEOR | ROUGE | CIDEr | |
|---|---|---|---|---|---|---|---|
| Soft-Attention [Xu et al., 2015] | 70.7 | 49.2 | 34.4 | 24.3 | 23.9 | - | - |
| Hard-Attention [Xu et al., 2015] | 71.8 | 50.4 | 35.7 | 25.0 | 23.0 | - | - |
| VAE [Pu et al., 2016] | 72.0 | 52.0 | 37.0 | 28.0 | 24.0 | - | 90.0 |
| Google NICv2 [Vinyals et al., 2017] | - | - | - | 32.1 | 25.7 | - | 99.8 |
| Attributes-CNN+RNN [Wu et al., 2016] | 74.0 | 56.0 | 42.0 | 31.0 | 26.0 | - | 94.0 |
| CNNL+RNN [Gu et al., 2017b] | 72.3 | 55.3 | 41.3 | 30.6 | 26.0 | - | 94.0 |
| PG-SPIDEr-TAG [Liu et al., 2016] | 75.4 | 59.1 | 44.5 | 33.2 | 25.7 | 55.0 | 101.3 |
| Adaptive [Lu et al., 2016] | 74.2 | 58.0 | 43.9 | 33.2 | 26.6 | 54.9 | 108.5 |
| SCST:Att2in [Rennie et al., 2016] | 76.9 | 60.2 | 45.1 | 33.3 | 26.3 | 55.3 | 111.4 |
| SCST:Att2all [Rennie et al., 2016] | 77.4 | 60.9 | 46.0 | 34.1 | 26.7 | 55.7 | 114.0 |
| TopDown:ResNet [Anderson et al., 2017] | 76.6 | 59.9 | 45.4 | 34.0 | 26.5 | 54.9 | 111.1 |
| TopDown:Up-Down [Anderson et al., 2017] | 79.8 | 63.4 | 48.4 | 36.3 | 27.7 | 56.9 | 120.1 |
| StackCap [Gu et al., 2017a] | 78.4 | 62.5 | 47.9 | 36.1 | 27.4 | 56.9 | 120.4 |
| MLAIC (ours) | 80.7 | 63.9 | 49.0 | 36.9 | 27.7 | 57.5 | 119.1 |
| BLEU-1 | BLEU-2 | BLEU-3 | BLEU-4 | METEOR | ROUGE | CIDEr | ||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| c5 | c40 | c5 | c40 | c5 | c40 | c5 | c40 | c5 | c40 | c5 | c40 | c5 | c40 | |
| Google NIC | 71.3 | 89.5 | 54.2 | 80.2 | 40.7 | 69.4 | 30.9 | 58.7 | 25.4 | 34.6 | 53.0 | 68.2 | 94.3 | 94.6 |
| Hard-Attention | 70.5 | 88.1 | 52.8 | 77.9 | 38.3 | 65.8 | 27.7 | 53.7 | 24.1 | 32.2 | 51.6 | 65.4 | 86.5 | 89.3 |
| PG-SPIDEr-TAG | 75.1 | 91.6 | 59.1 | 84.2 | 44.5 | 73.8 | 33.1 | 62.4 | 25.5 | 33.9 | 55.1 | 69.4 | 104.2 | 107.1 |
| Adaptive (Ens.5) | 74.8 | 92.0 | 58.4 | 84.5 | 44.4 | 74.4 | 33.6 | 63.7 | 26.4 | 35.9 | 55.0 | 70.5 | 104.2 | 105.9 |
| Stack-Cap (Single) | 77.8 | 93.2 | 61.6 | 86.1 | 46.8 | 76.0 | 34.9 | 64.6 | 27.0 | 35.6 | 56.2 | 70.6 | 114.8 | 118.3 |
| SCST:Att2in (Ens.4) | 78.1 | 93.1 | 61.9 | 86.0 | 47.0 | 75.9 | 35.2 | 64.5 | 27.0 | 35.5 | 56.3 | 70.7 | 114.7 | 116.7 |
| TopDown:Up-Down (Ens.4) | 80.2 | 95.2 | 64.1 | 88.8 | 49.1 | 79.4 | 36.9 | 68.5 | 27.6 | 36.7 | 57.1 | 72.4 | 117.9 | 120.5 |
| MLAIC (Single) | 80.3 | 94.4 | 63.4 | 87.3 | 48.3 | 77.4 | 36.0 | 66.1 | 27.4 | 36.1 | 57.0 | 71.8 | 113.9 | 116.4 |
| Cross-entropy | CIDEr-optimization | |||||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| B-1 | B-2 | B-3 | B-4 | METEOR | ROUGE | CIDEr | B-1 | B-2 | B-3 | B-4 | METEOR | ROUGE | CIDEr | |
| MLAIC | 76.2 | 59.7 | 46.1 | 35.7 | 27.0 | 55.6 | 109.8 | 80.7 | 63.9 | 49.0 | 36.9 | 27.7 | 57.5 | 119.1 |
| w/o multi-label | 74.6 | 58.3 | 44.8 | 34.5 | 26.8 | 55.3 | 107.7 | 77.2 | 61.1 | 46.1 | 34.5 | 26.9 | 56.5 | 115.7 |
| w/o syntax | 75.8 | 59.2 | 45.7 | 35.5 | 26.9 | 55.5 | 109.2 | 80.1 | 63.5 | 48.7 | 36.4 | 27.4 | 57.1 | 118.5 |
4.4 EvaluationMetrics
To quantitatively evaluate our image captioning method, we follow previous work to use BLEU-N (N=1,2,3,4), METEOR, ROUGE, CIDEr scores for comparison. All these metrics measure the consistency between n-gram occurrences in generated captions and ground-truth captions, where this consistency is weighted by n-gram saliency and rarity.
5 Experimental Result
In this section, we compare our model with the competitors quantitatively and qualitatively.
5.1 Quantitative Evaluation
Offline Evaluation The experimental results onMSCOCO with Karpathy test split are summarized in Table 2. We observe that MLAIC substantially and consistently outperforms the existing methods by a noticeable margin on most of the evaluation metrics. In particular, our model successfully yields better scores of all evaluation metrics compared to the TopDown model which utilizes the same basic CNN-LSTM backbone as ours. Our model benefits from the fact that both the CNN encoder and the LSTM decoder are improved by jointly learning the image captioning with the object classification and the syntax generation tasks.
Online Evaluation Table 3 reports the performance of our single model on the official MSCOCO evaluation server 3 . The previous top performers on the leaderboard (as of December 7, 2017) are also demonstrated. Our model achieves better or competitive performance compared to the state-ofthe-art competitors (both single and ensemble models).
Ablation Study For the purpose of analyzing the effectiveness of different components of our model for image captioning, in this section, we report the ablation test of our model by discarding the multi-label object classification task (w/o object) or the syntax generation task (w/o syntax), respectively.
3 https://competitions.codalab.org/competitions/3221
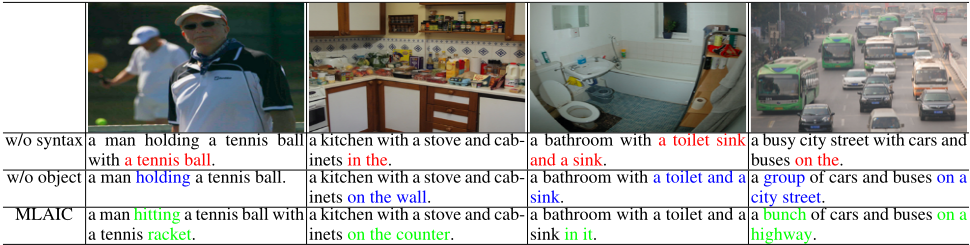
| w/o syntax a | man holding a tennis with a tennis ball. | ball a kitchen with a stove and cab- inets in the. | a bathroom with a toilet and a sink. | sink a busy city street with cars and buses on the. |
|---|---|---|---|---|
| w/o object | a man holding a tennis ball. | a kitchenwith a stove and cab- inets on the wall. | a bathroom with a toilet and a sink. | a group of cars and buses on a city street. |
| MLAIC | aman hitting a tennis ball with a tennis racket. | a kitchen with a stove and cab- inets on the counter. | a bathroom with a toilet and sink in it. | a a bunch of cars and buses on a highway. |
| Captions: CCG: | a NP/N | giraffe N | is (S[dcl]\NP)/(S[ng]\NP) | standing (S[ng]\NP)/PP | in PP/NP | the NP/N | dirt N/PP | of PP/NP | a NP/N | fence N |
|---|---|---|---|---|---|---|---|---|---|---|
| Captions: CCG: | a NP/N | suitcase N | filled (S[pss]\NP)/PP | with PP/NP | lots N/PP | of PP/NP | items N | on (S\NP)\(S\NP)/NP | a NP/N | bed N |
In order to investigate the performance of the policy gradient update, we also report the results of our multi-task learning model with policy gradient update (i.e., CIDEr-optimization) or with cross-entropy optimization, respectively.
The results are demonstrated in Table 4. Generally, both tasks contribute, and the multi-label object classification task contributes most. This is within our expectation since the object classification task helps the CNN encoder learn better image representations. In addition, the proposed model utilizes the classification results (label embeddings) to produce captions of different styles and wording with respect to different object categories. While the improvement of integrating syntax generation is relatively limited. This may be because that the issue of the incomplete sentence has little effect on the evaluation metrics of image captions. As shown in Table 5, the sentences generated by w/o syntax model are incomplete but achieve high scores in terms of the evaluation metrics. It is no surprise that combining both tasks achieves the best performance for all evaluation metrics. The main advantage comes from its capability of sharing knowledge of image captioning with two related tasks and learning better encoder and decoder representations simultaneously. We can also observe that the model with policy gradient update substantially outperforms the model with cross-entropy by a noticeable margin on all the evaluation metrics. The is because that the policy gradient update is able to bypass the exposure bias and non-differentiable evaluation metrics issue, and maximize long-term reward in caption generation.
5.2 Qualitative Evaluation
To evaluate the proposed model qualitatively, we show some generated image descriptions in Table 5. It is easy to see that MLAIC can generate reasonably relevant and plausible sentences. For example, the sentences "a man hitting a tennis ball with a tennis racket" and "a bunch of cars and buses on a highway" created by MLAIC are more precise in describing the content of the images. By comparing the results of w/o syntax and MLAIC, we reveal that the syntax generation task is able to help the LSTM decoder to alleviate the issues of generating duplicate words and incomplete sentences. On the other hand, the object classification task makes the CNN encoder be able to recognize the existence of objects, and help the LSTM decoder produce captions of different styles and generate novel words with respect to different object categories.
The performance of the syntax generation task is also improved by the multi-task learning mechanism. We provide some qualitative examples of image captions and the corresponding CCG supertags in Table 6 to evaluate the syntax generation model. From Table 6 we observe that the generated CCG supertag sequences are reasonable and consistent with the corresponding images captions. For example, the supertag (S[dcl]\NP)/(S[ng]\NP) for the verb "is" in the first caption implicates that a present participle is expected if the next word is verb. While the supertag (S\NP)\(S\NP)/NP for "on" implies that a noun phrase will be generated in the next. Our model can predict the high-quality CCG supertags, and help the image captioning alleviate the problem of generating duplicate words and incomplete sentence.
6 Conclusion
We proposed a novel multi-task learning method to improve image captioning by jointly training the image captioning with two related auxiliary tasks: object classification and syntax generation. The object classification helped learn better image representations and improved the performance of visual attention, and the syntax generation helped alleviate the problem of generating incomplete sentences and duplicate words. To verify the effectiveness of our approach, we conducted extensive experiments on widely used MSCOCO dataset. The experimental results demonstrated that our model achieved impressive results compared to other strong competitors.
@inproceedings{ijcai2018p168,
  title     = {A Multi-task Learning Approach for Image Captioning},
  author    = {Zhao, Wei and Wang, Benyou and Ye, Jianbo and Yang, Min and Zhao, Zhou and Luo, Ruotian and Qiao, Yu},
  booktitle = {Proceedings of the Twenty-Seventh International Joint Conference on
               Artificial Intelligence, {IJCAI-18}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Jérôme Lang},
  pages     = {1205--1211},
  year      = {2018},
  month     = {7},
  note      = {Main track},
  doi       = {10.24963/ijcai.2018/168},
  url       = {https://doi.org/10.24963/ijcai.2018/168},
}
TY - CPAPER TI - A Multi-task Learning Approach for Image Captioning AU - Zhao, Wei AU - Wang, Benyou AU - Ye, Jianbo AU - Yang, Min AU - Zhao, Zhou AU - Luo, Ruotian AU - Qiao, Yu T2 - Proceedings of the Twenty-Seventh International Joint Conference on Artificial Intelligence, IJCAI-18 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2018 SP - 1205 EP - 1211 DO - 10.24963/ijcai.2018/168 UR - https://doi.org/10.24963/ijcai.2018/168 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





