
Multi-modal Circulant Fusion for Video-to-Language and Backward
Proceedings of the Twenty-Seventh International Joint Conference on Artificial Intelligence. Main track. Pages 1029-1035.
https://doi.org/10.24963/ijcai.2018/143
Keywords
- Computer Vision: Video: Events, Activities and Surveillance
- Computer Vision: Language and Vision
- Computer Vision: Recognition: Detection, Categorization, Indexing, Matching, Retrieval, Semantic Interpretation
Abstract
Multi-modal fusion has been widely involved in focuses of the modern artificial intelligence research, e.g., from visual content to languages and backward. Common-used multi-modal fusion methods mainly include element-wise product, element-wise sum, or even simply concatenation between different types of features, which are somewhat straightforward but lack in-depth analysis. Recent studies have shown fully exploiting interactions among elements of multi-modal features will lead to a further performance gain. In this paper, we put forward a new approach of multi-modal fusion, namely Multi-modal Circulant Fusion (MCF). Particularly, after reshaping feature vectors into circulant matrices, we define two types of interaction operations between vectors and matrices. As each row of the circulant matrix shifts one elements, with newly-defined interaction operations, we almost explore all possible interactions between vectors of different modalities. Moreover, as only regular operations are involved and defined a priori, MCF avoids increasing parameters or computational costs for multi-modal fusion. We evaluate MCF with tasks of video captioning and temporal activity localization via language (TALL). Experiments on MSVD and MSRVTT show our method obtains the state-of-the-art for video captioning. For TALL, by plugging into MCF, we achieve a performance gain of roughly 4.2% on TACoS.
- [Ballas et al., 2016] Nicolas Ballas, Li Yao, Chris Pal, and Aaron Courville. Delving deeper into convolutional net- works for learning video representations. ICLR, 2016.
- [Baraldi et al., 2017] Lorenzo Baraldi, Costantino Grana, and Rita Cucchiara. Hierarchical boundary-aware neural encoder for video captioning. CVPR, 2017.
- [Chen and Dolan, 2011] David L Chen and William B Dolan. Collecting highly parallel data for paraphrase eval- uation. In ACL, pages 190-200, 2011.
- [Chen et al., 2017] Liang-Chieh Chen, George Papandreou, Iasonas Kokkinos, Kevin Murphy, and Alan L Yuille. Deeplab: Semantic image segmentation with deep convo- lutional nets, atrous convolution, and fully connected crfs. TPAMI, 2017.
- [Fukui et al., 2016] Akira Fukui, Dong Huk Park, Daylen Yang, Anna Rohrbach, Trevor Darrell, and Marcus Rohrbach. Multimodal compact bilinear pooling for vi- sual question answering and visual grounding. In EMNLP, pages 457-468, 2016.
- [Gao et al., 2017] Jiyang Gao, Chen Sun, Zhenheng Yang, and Ram Nevatia. Tall: Temporal activity localization via language query. In ICCV, Oct 2017.
- [He et al., 2016] Kaiming He, Xiangyu Zhang, Shaoqing Ren, and Jian Sun. Deep residual learning for image recog- nition. In CVPR, June 2016.
- [Karpathy and Fei-Fei, 2015] Andrej Karpathy and Li Fei- Fei. Deep visual-semantic alignments for generating im- age descriptions. In CVPR, pages 3128-3137, 2015.
- [Kiros et al., 2015] Ryan Kiros, Yukun Zhu, Ruslan R Salakhutdinov, Richard Zemel, Raquel Urtasun, Antonio Torralba, and Sanja Fidler. Skip-thought vectors. In NIPS, pages 3294-3302. 2015.
- [Li et al., 2017] Xuelong Li, Bin Zhao, and Xiaoqiang Lu. Mam-rnn: Multi-level attention model based rnn for video captioning. In IJCAI, 2017. IJCAI
- [Pan et al., 2016a] Pingbo Pan, Zhongwen Xu, Yi Yang, Fei Wu, and Yueting Zhuang. Hierarchical recurrent neural encoder for video representation with application to cap- tioning. In CVPR, pages 1029-1038, 2016.
- [Pan et al., 2016b] Yingwei Pan, Tao Mei, Ting Yao, Houqiang Li, and Yong Rui. Jointly modeling embedding and translation to bridge video and language. In CVPR, pages 4594-4602, 2016.
- [Peng et al., 2018] Yuxin Peng, Jinwei Qi, Xin Huang, and Yuxin Yuan. Ccl: Cross-modal correlation learning with multigrained fusion by hierarchical network. IEEE Trans- actions on Multimedia, 20(2):405-420, 2018.
- [Regneri et al., 2013] Michaela Regneri, Marcus Rohrbach, Dominikus Wetzel, Stefan Thater, Bernt Schiele, and Man- fred Pinkal. Grounding action descriptions in videos. TACL, 1:25-36, 2013.
- [Song et al., 2017] Jingkuan Song, Zhao Guo, Lianli Gao, Wu Liu, Dongxiang Zhang, and Heng Tao Shen. Hier- archical lstm with adjusted temporal attention for video captioning. arXiv preprint arXiv:1706.01231, 2017. IJCAI
- [Szegedy et al., 2015] Christian Szegedy, Wei Liu, Yangqing Jia, Pierre Sermanet, Scott Reed, Dragomir Anguelov, Dumitru Erhan, Vincent Vanhoucke, and Andrew Rabi- novich. Going deeper with convolutions. In CVPR, pages 1-9, 2015.
- [Tenenbaum and Freeman, 1997] Joshua B Tenenbaum and William T Freeman. Separating style and content. In NIPS, pages 662-668, 1997.
- [Venugopalan et al., 2014] Subhashini Venugopalan, Hui- juan Xu, Jeff Donahue, Marcus Rohrbach, Raymond Mooney, and Kate Saenko. Translating videos to natural language using deep recurrent neural networks. NAACL, 2014.
- [Venugopalan et al., 2015] Subhashini Venugopalan, Mar- cus Rohrbach, Jeffrey Donahue, Raymond Mooney, Trevor Darrell, and Kate Saenko. Sequence to sequence- video to text. In ICCV, pages 4534-4542, 2015.
- [Xu et al., 2016] Jun Xu, Tao Mei, Ting Yao, and Yong Rui. Msr-vtt: A large video description dataset for bridging video and language. In CVPR, pages 5288-5296, 2016.
- [Xu et al., 2017] Jun Xu, Ting Yao, Yongdong Zhang, and Tao Mei. Learning multimodal attention lstm networks for video captioning. In ACM MM, pages 537-545. ACM, 2017.
- [Yang et al., 2017] Ziwei Yang, Yahong Han, and Zheng Wang. Catching the temporal regions-of-interest for video captioning. In Proceedings of the 2017 ACM on Multime- dia Conference, pages 146-153. ACM, 2017.
- [Yao et al., 2015] Li Yao, Atousa Torabi, Kyunghyun Cho, Nicolas Ballas, Christopher Pal, Hugo Larochelle, and Aaron Courville. Describing videos by exploiting tempo- ral structure. In ICCV, pages 4507-4515, 2015.
- [Yu et al., 2016] Haonan Yu, Jiang Wang, Zhiheng Huang, Yi Yang, and Wei Xu. Video paragraph captioning using hierarchical recurrent neural networks. In CVPR, pages 4584-4593, 2016.
- [Yu et al., 2017] Zhou Yu, Jun Yu, Jianping Fan, and Dacheng Tao. Multi-modal factorized bilinear pooling with co-attention learning for visual question answering. In ICCV, Oct 2017.
- [Zhang et al., 2016] Yuting Zhang, Kibok Lee, and Honglak Lee. Augmenting supervised neural networks with unsu- pervised objectives for large-scale image classification. In ICML, pages 612-621, 2016.
- [Zhang et al., 2018] Hanwang Zhang, Yulei Niu, and Shih- Fu Chang. Grounding referring expressions in images by variational context. In CVPR, 2018.
- [Zhu et al., 2017] Linchao Zhu, Zhongwen Xu, and Yi Yang. Bidirectional multirate reconstruction for temporal model- ing in videos. In CVPR, July 2017.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Multi-modal data are widely involved in recent focuses on artificial intelligence research, e.g., visual to languages [Yao et al., 2015] and the backward of visual localization via language queries [Gao et al., 2017]. Though many efforts have been made towards feature learning of images and texts, e.g., via convolutional neural networks (CNN) [He et al., 2016] and recurrent neural networks (RNN) [Kiros et al., 2015], respectively, in-depth analysis of multi-modal fusion has been unintentionally ignored. Common-used or somewhat straightforward multi-modal fusion methods mainly in-
(d) Multi-modal Circulant Fusion (MCF)
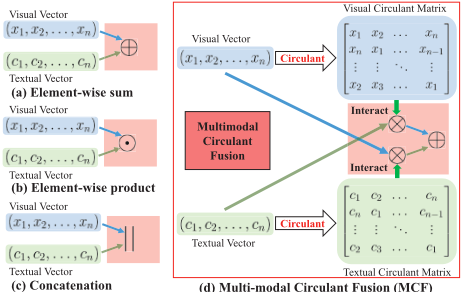
Figure 1: Different ways of multi-modal fusion. (a), (b), and (c) indicate three common fusion methods. (d) is the proposed multimodal circulant fusion (MCF) method. '⊕' denotes element-wise sum. '⊙' denotes element-wise product. '||' denotes concatenation. '⊗' denotes multiplication operation.
clude element-wise sum (Fig. 1 (a)), element-wise product (Fig. 1 (b)), or even simply concatenation (Fig. 1 (c)) between different types of features [Fukui et al., 2016; Yu et al., 2017]. As feature vectors of different modalities lie in different feature spaces, interactions or correlations might not just exist among corresponding dimensions of multi-modal vectors. Besides no interactions with concatenation, element-wise sum or product only partially explores interactions or correlations among multi-modal features, which may burden the fusion performance.
Recent studies [Fukui et al., 2016; Yu et al., 2017] have shown fully exploiting interactions among elements of multimodal features will lead to a further performance gain. Authors in [Fukui et al., 2016; Yu et al., 2017] develop multimodal bilinear pooling to capture pairwise interactions between multi-modal feature dimensions. As bilinear pooling defines p parameterized projection matrices, where p is the dimension of the output fused features, additional huge number of parameters are introduced into the model. Although count sketch [Fukui et al., 2016] or matrix factorization [Yu et al., 2017] were employed to shrink projection matrices, more computational costs were introduced again. Moreover, empirical studies in [Fukui et al., 2016] show that the performance gain from multi-modal fusion is guaranteed only when the dimension p of the output fused features is high, which means there still needs a large number of parameterized projection matrices. Therefore, if we skipped the parameterized projection matrices and defined a fully-interacted module of multi-modal fusion a priori, e.g., constituted with only regular operations like element-wise sum or product, we expect to get a good fusion performance with fewer parameters or lower computational costs.
In this paper, we propose a new module of Multi-modal Circulant Fusion (MCF) to fully exploit interactions among multi-modal features. In Fig. 1 (d) we show the main idea of MCF by taking the fusion of visual and textual vectors as an example. In particular, after reshaping visual or textual vectors into circulant matrices, respectively, we define two types of interaction operations between original feature vectors and the reshaped circulant matrices. Finally, we use element-wise sum to obtain the joint representation of these two cross-fused vectors. As each row of the circulant matrix shifts one elements, with newly-defined interaction operations, we almost explore all possible interactions between vectors of different modalities. Note that, as only regular operations are involved in the MCF and the proposed MCF is defined a priori, we avoid introducing new parameters or increasing computational costs for multi-modal fusion.
In the experiments, we extensively evaluate the proposed MCF with tasks of video captioning and temporal activity localization via language (TALL) [Gao et al., 2017]. Experimental results on MSVD [Chen and Dolan, 2011] and MSRVTT [Chen and Dolan, 2011] show that our method could obtain the state-of-the-art performance of video captioning. For TALL, by plugging into the MCF, we achieve a performance improvement of roughly 4.2% on TACoS [Regneri et al., 2013].
2 RelatedWorks
As the original bilinear method [Tenenbaum and Freeman, 1997] needs a huge number of parameters and is not applied into a multi-modal task [Peng et al., 2018; Zhang et al., 2018], the method MCB [Fukui et al., 2016] uses the count sketch to reduce the number of parameters of bilinear pooling and employs bilinear pooling to solve multi-modal fusion. However, MCB always outputs a high-dimensional fused feature which increases computational cost of following processes. Whereas the work in [Yu et al., 2017] proposes a bilinear pooling method based on matrix factorization to combine multi-modal features.
Recent advances in video captioning mainly follow the encoding-decoding framework and generate captions via RNN [Zhu et al., 2017; Yang et al., 2017]. Though strengths in representation ability, CNN has not been well exploited in video captioning. In this paper, we propose a coarse-tofine multi-stage convolutional network which includes a MCF and many convolutional decoders that generate finer video descriptions. In order to reduce the risk of vanishing gradients, inspired by the work [Zhang et al., 2016], we enforce intermediate supervisions for each stage. Experimental results on MSVD and MSRVTT show the effectiveness of our method.
As a backward direction of video captioning, Temporal Ac-
(a) Multi-modal Circulant Fusion (MCF)
(b) The detail of Interaction in MCF
Figure 2: The flowchart of Multimodal Circulant Fusion (MCF).
tivity Localization via Language (TALL) [Gao et al., 2017] is given a temporally untrimmed video and a natural language query, and then determines the start and end moments for the described activity inside the video. By plugging MCF into the architecture of [Gao et al., 2017], we obtain a performance improvement owing to a better multi-modal fusion.
3 Multi-modal Circulant Fusion
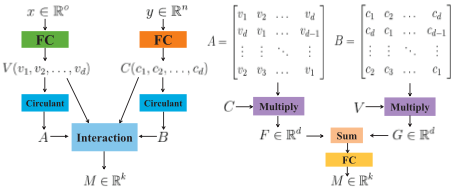
The detailed procedures of MCF are illustrated in Fig. 2. Given two feature vectors in different modalities, e.g., the visual features x ∈ Ro and the textual features y ∈ Rn , to reduce computational cost, we first utilize two projection matrix W1 ∈ Rd×o and W2 ∈ Rd×n (d ≤ min(o, n)) to project the two input features to a lower dimensional space.
where W T 1 andW T 2 are the transpose of W1 andW2. Then we use the projection vector V ∈ Rd and C ∈ Rd to construct circulant matrix A ∈ Rd×d and B ∈ Rd×d .
where circ(b) denotes converting b to a circulant matrix.
In order to make elements in projection vector and circulant matrix fully interact, we explore two different multiplication operations. The first is shown in Eq. (3) and uses matrix multiplication between circulant matrix and projection vector.
The second is to have projection vector and each row vector of circulant matrix do element-wise product. The procedures are shown as follows:
where ai ∈ Rd and bi ∈ Rd are row vector of circulant matrix A and B. ⊙ denotes operation of element-wise product. It is noted that we do not introduce new parameters in the multiplication operation.
Finally, through a projection matrix W3 ∈ Rd×k , we convert the element-wise sum vector of F ∈ Rd and G ∈ Rd to target vector M ∈ Rk .
4 MCF for Video Captioning
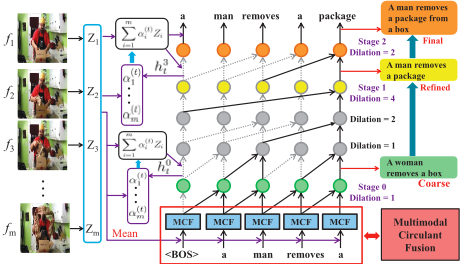
In this section, we develop a new framework for video captioning, in which we construct convolutional encoder and decoder for video-to-language translation. Note that, in the decoder, we take MCF as a base layer for coarse decoding, stacked on which with layered dilations for refined and final decoding. Thus we construct a Multi-stage Decoder with MCF.
4.1 Convolutional Encoding Network
Feature Extraction. We use pre-trained convolutional networks to extract feature for each of the m video frames, which results in a vector Xi ∈ Rq for the i-th frame.
Discriminative Enhancing. Given two consecutive frame features Xi and Xi+1 (i = 0, 2, · · · ), we first compute interframe differences diff. Then by a ReLU operation, we add the positive values of diff to Xi+1 and the absolute value of negative values in diff to Xi. Thus, we enlarge the discrimination gap between Xi and Xi+1.
where i = 0, 2, · · · . Vi ∈ Rq is the enhancing result of Xi. Reconstruction Network. In this work, we construct a reconstruction network to learn a compact representation Zi for each video frame. The procedures are shown as follows:
where i = 0, 1, · · · . WE ∈ R1×q×r denotes convolutional filter and r ≤ q, bE ∈ Rr and bD ∈ Rq are the bias parameters. Zi ∈ Rr is the learned compact representation. WD ∈ R1×r×q is the reconstruction filter and Ri ∈ Rq denotes reconstruction result. Lrecon denotes reconstruction loss between Ri and Xi and || · ||2 denotes an ℓ2-norm. ∗ denotes a convolutional operator.
4.2 Multi-stage Convolutional Decoder withMCF
As introduced above, we stack many dilated convolutional layers [Chen et al., 2017] to form a coarse-to-fine multi-stage decoder (Fig. 3). In the following, we denote by ˆ Y j = { ˆ Y j 0 , ..., ˆ Y j T-1 } the predicted word sequence of the j-th stage of decoder, where j ∈ {0, ...,Nf} and (Nf + 1) is the number of stages. We denote by Y = {Y0, ..., YT-1} the target word sequence, where T denotes sequence length. Note that we treat the initial stage j = 0 as coarse decoder and above stages as refined decoders. [a, b] represents the concatenation of a and b. And '⊙' is an element-wise product operation, '∗' denotes a convolutional operator. Z = {Z0,Z1, · · · }. The σ(·) is a sigmoid function.
MCF as a Coarse Decoder. In the bottom stage (j = 0), we use one dilated convolutional layer to learn a coarse decoder. At each time step t ∈ [0, T - 1], the input to coarse decoder consists of previous target word Yt-1 and mean vector Zmean of encoding output Z. As the inputs are two different modalities, we first use MCF to obtain the joint representation M 0 t . The operation of coarse decoder can be described as follows:
where H0 t = [M 0 t-1 , M 0 t ]. MCF(a, b) represents using MCF to fuse a and b. w0 f and w0 g denote convolutional filters on the 0th layer. b0f and b0g denote bias on the 0th layer.
Refined Decoder. In this paper, our refined decoder consists of two stages. The first stage contains three dilated convolutional layers. And the second stage only includes one dilated convolutional layer which stacks on top of first stage. We take prediction of the second stage as final description.
For the first refined decoder, we first use the output h0t of coarse decoder to compute visual attention ϕ0t (Z). The operation of first layer in this refined decoder is shown as follows:
where w1 is learnable filter to convert the channel of concatenated representation. w1 f and w1 g denote convolutional filters on the 1th layer. b1f and b1g denote bias on the 1th layer.
Then, operations of the next two layers in first refined decoder are shown as follows:
where rl represents dilated rate of the layer l. hl-1 t denotes the output of (l -1)-th layer at time step t. wlf and wlg denote convolutional filters on the layer l. blf and blg are bias.
For the second refined decoder, the procedures can be described as follows:
where L denotes the number of layers of first refined stage. hLt denotes the output of layer L at time step t. wL+1 f and wL+1 g denote convolutional filters of layer L + 1. bL+1 f and bL+1 g are bias. ϕ1t (Z) represents attention computed by hLt .
In this section, we use the method [Yao et al., 2015] to compute attention (Fig. 3). Besides, based on different size of filter and dilated rate, we use different number of zero vectors to pad the input of each layer.
Finally, the t-th generated word ˆ Y 1 t of the first refined stage and ˆ Y 2 t of the second refined stage are computed as follows:
where wp and bp are learnable projection matrix and bias. Training Loss. For each stage j, we employ a cross-entropy (XE) loss.
where Yt is the ground-truth word at time t, θ0:j are parameters up to the j-th stage decoder, and pθ0:j (Yt|Y0:t-1,Z) is the output probability of word Yt given by the previous word Y0:t-1 and encoding output Z.
The training loss Ltrain is computed as follows:
where λj , β1, and β2 are hyber-parameters.
5 MCF for TALL
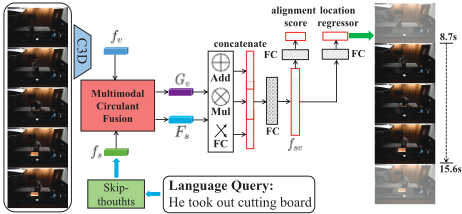
For temporal activity localization via language query, we plug MCF into the architecture of work [Gao et al., 2017]. Concretely, we first feed visual feature fv and textual feature fs into MCF (Fig. 4). For MCF, after obtaining F ∈ Rd and G ∈ Rd by Eq. (4), we use a projection matrix WM ∈ Rd×k to convert F and G to Fs ∈ Rk and Gv ∈ Rk .
The following operations are same as that of the work [Gao et al., 2017].
6 Evaluation on Video Captioning
We evaluate the benefit of MCF on two video captioning datasets. All results all evaluated by metrics of BLEU, METEOR, and CIDEr [Yao et al., 2015].
6.1 Dataset and Implementation Details
Datasets. MSVD [Chen and Dolan, 2011] contains 1,970 video clips. We use 1,200 clips for training, 100 clips for validation, and 670 clips for testing. MSRVTT [Xu et al., 2016] contains 10,000 video clips. We use 6,513 clips for training, 497 clips for validation, and 2,990 clips for testing.
Video Processing. For the MSVD dataset, we select 40 frames from each video and feed them into GoogLeNet [Szegedy et al., 2015] to extract a 1,024 dimensional representation. For the MSRVTT dataset, we select 20 frames from each video and feed them into GoogLeNet and ResNet152 [He et al., 2016] to extract 1,024 and 2,048 dimensional representation, respectively.
Encoding Network. In the encoder, we set the channel r (in Eq. (9)) of the encoding temporal output Zi to 512.
Decoding Network. For the multi-stage decoder, we use five dilated layers with dilated rate 1, 1, 2, 4 and 2. The number of filter channel is set to 512, 256, 256, 512 and 512, respectively. The width of filter is set to 2. For MCF, we set W1 ∈ R256×512 , W2 ∈ R256×512 (in Eq. (1)) and W3 ∈ R256×512 .
Training Details. The vocabulary size is 12,596 for MSVD and 23,308 for MSRVTT, respectively. We use Adam optimizer with an initial learning rate of 1 × 10⁻³ . We empirically set β1 and β2 to 0.9 and 0.1, respectively. And λ0, λ1
and λ2 are set to 0.2, 0.2, and 0.6, respectively. Note that we do not conduct beam search in testing.
6.2 Experimental Results
MSVD Dataset. On MSVD dataset, we compare our method with other methods. The results are shown in Table 1.
It can be seen that our method outperforms all above methods on the metric of METEOR and CIDEr. Particularly, for the work [Song et al., 2017], they use multi-layer LSTM as the decoder. Our convolutional sequential decoder outperforms the performance of hLSTMmat [Song et al., 2017]. This shows that our method is effective.
| Method | BLEU@4 | METEOR | CIDEr |
|---|---|---|---|
| S2VT [Venugopalan et al., 2015] | - | 29.20 | - |
| C3D+LSTM-E [Pan et al., 2016b] | 41.70 | 29.90 | - |
| VGG+p-RNN [Yu et al., 2016] | 44.30 | 31.10 | 62.10 |
| Tempor-attention [Yao et al., 2015] | 41.92 | 29.60 | 51.67 |
| G+Bi-GRU-RCN1 [Ballas et al., 2016] | 48.42 | 31.70 | 65.38 |
| G+HRNE [Pan et al., 2016a] | 43.80 | 33.10 | - |
| MAMRNN [Li et al., 2017] | 41.40 | 32.20 | 53.90 |
| Boundary [Baraldi et al., 2017] | 42.50 | 32.40 | 63.50 |
| G+hLSTMmat [Song et al., 2017] | 48.50 | 31.90 | - |
| G+MVRM [Zhu et al., 2017] | 49.45 | 33.39 | 75.45 |
| G+MCNN+MCF-element-wise product | 45.65 | 33.56 | 73.86 |
| G+MCNN+MCF-matrix multiply | 46.46 | 33.72 | 75.46 |
MSRVTT dataset. On MSRVTT dataset, we compare our method with representative methods. Results are shown in Table 2. Compared with all above methods which use a single kind of visual feature as input, our method obtains the best performance on METEOR and CIDEr metric. Besides, compared with the work [Xu et al., 2017] which uses many kinds of features as input, our method outperforms its performance. This shows that the performance of our method on a single kind of visual feature is valid.
Ablation Analysis. We respectively use bilinear pooling [Fukui et al., 2016], concatenation, element-wise sum and element-wise product to replace MCF used in our multi-stage CNN and keep other components of multi-stage CNN and their parameter settings unchanged. The output dimension of bilinear pooling is set to 512. The results are shown in Table 3. On MSVD and MSRVTT dataset, we can see that MCF outperforms all above fusion methods on the metric of METEOR and CIDEr. This shows that based on our convolutional architecture, MCF is effective for video captioning. Besides, through Table 1 and Table 2, we find that for our method, using matrix multiplication in MCF outperforms the performance of using element-wise product.
| Method | BLEU@4 | METEOR | CIDEr |
|---|---|---|---|
| MA-LSTM [Xu et al., 2017] | 36.5 | 26.5 | 41.0 |
| G+LSTM [Venugopalan et al., 2014] | 34.6 | 24.6 | - |
| C3D+SA [Yao et al., 2015] | 36.1 | 25.7 | - |
| R+S2VT [Venugopalan et al., 2015] | 31.4 | 25.7 | 35.2 |
| R+hLSTMat [Song et al., 2017] | 38.3 | 26.3 | - |
| G+MCNN+MCF-matrix multiply | 36.1 | 26.4 | 39.2 |
| R+MCNN+MCF-matrix multiply | 38.1 | 27.2 | 42.1 |
| R+MCNN+MCF-element-wise product | 37.7 | 27.1 | 41.3 |
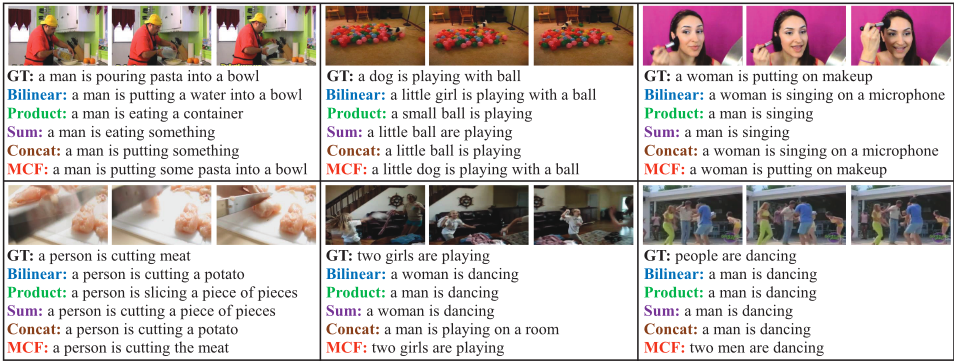
In Fig. 5, we show some video captioning examples generated by multi-stage CNN which uses different fusion method. We can see that the captions generated by multi-stage CNN using MCF are better than that generated by multi-stage CNN using other fusion methods. Particularly, taking the first and third results as examples, our method successfully identifies 'pasta' and 'makeup', while are better than above fusion
Query: The person gets out a fork.
methods. This also demonstrates that based on our architecture, MCF is an effective fusion method for video captioning.
| Fusion Method (dataset) | BLEU@4 | METEOR | CIDEr |
|---|---|---|---|
| Element-wise sum (MSVD)+G | 47.13 | 32.71 | 71.20 |
| Element-wise product (MSVD)+G | 46.21 | 32.67 | 71.92 |
| Concatenation (MSVD)+G | 45.25 | 32.90 | 70.64 |
| Bilinear Pooling (MSVD)+G | 43.61 | 32.46 | 71.11 |
| MCF-matrix multiply (MSVD)+G | 46.46 | 33.72 | 75.46 |
| Element-wise sum (MSRVTT)+R | 37.5 | 26.4 | 40.0 |
| Element-wise product (MSRVTT)+R | 36.8 | 26.6 | 39.3 |
| Concatenation (MSRVTT)+R | 36.2 | 26.3 | 39.9 |
| Bilinear Pooling (MSRVTT)+R | 37.5 | 26.7 | 40.9 |
| MCF-matrix multiply (MSRVTT)+R | 38.1 | 27.2 | 42.1 |
7 Evaluation on TALL
7.1 Dataset and Implementation Details
We evaluate the benefit of MCF on TACoS dataset [Regneri et al., 2013]. This dataset contains 127 videos. Each video includes two type of annotations. The first is activity labels with temporal location (start and end frame). The second is language descriptions. In total, there are 17,344 pairs of sentence and video clips. We split it in 50% for training, 25% for validation and 25% for test. In experiment, we set W1 ∈ R96×1024 , W2 ∈ R96×1024 (in Eq. (1)), and WM ∈ R96×1024 (in Eq. (17)). All other parameter settings are same as those of the work [Gao et al., 2017].
7.2 Experimental Results
Evaluation Metric. We employ the metric used by [Regneri
et al., 2013; Gao et al., 2017] to compute 'R@n, IoU=m'.
Comparison with other methods. We compare our method with other methods on TACoS and report the result for IoU ∈ {0.1, 0.3, 0.5} and Recall@{1, 5}. The results are shown in Table 4. 'Random', 'Verb' and 'Verb+Obj' are used by work [Gao et al., 2017] to make contrast. 'VSA-RNN' and
'VST-STV' [Karpathy and Fei-Fei, 2015] leverage images and their descriptions to learn about their correspondences. 'CTRL-p' and 'CTRL-np' denote using parameterized and non-parameterized regression loss to train CTRL [Gao et al., 2017]. And we use element-wise product in MCF.
It can be seen from Table 4 that our method outperforms all above methods on most metrics. Particularly, our method achieves a relative improvement of 4.2% on the metric R@5 with IoU=0.1. This shows that MCF is an effective fusion method for this task.
| Method | R@1 IoU=0.5 | R@1 IoU=0.3 | R@1 IoU=0.1 | R@5 IoU=0.5 | R@5 IoU=0.3 | R@5 IoU=0.1 |
|---|---|---|---|---|---|---|
| Random | 0.83 | 1.81 | 3.28 | 3.57 | 7.03 | 15.09 |
| Verb | 1.62 | 2.62 | 6.71 | 3.72 | 6.36 | 11.87 |
| Verb+Obj | 8.25 | 11.24 | 14.69 | 16.46 | 21.50 | 26.60 |
| VSA-RNN | 4.78 | 6.91 | 8.84 | 9.10 | 13.90 | 19.05 |
| VSA-STV | 7.56 | 10.77 | 15.01 | 15.50 | 23.92 | 32.82 |
| CTRL-p | 11.85 | 17.59 | 23.71 | 23.05 | 33.19 | 47.51 |
| CTRL-np | 13.30 | 18.32 | 24.32 | 25.42 | 36.69 | 48.73 |
| CTRL+MCF-m | 13.05 | 17.08 | 23.16 | 25.74 | 35.62 | 48.86 |
| CTRL+MCF-p | 12.53 | 18.64 | 25.84 | 24.73 | 37.13 | 52.96 |
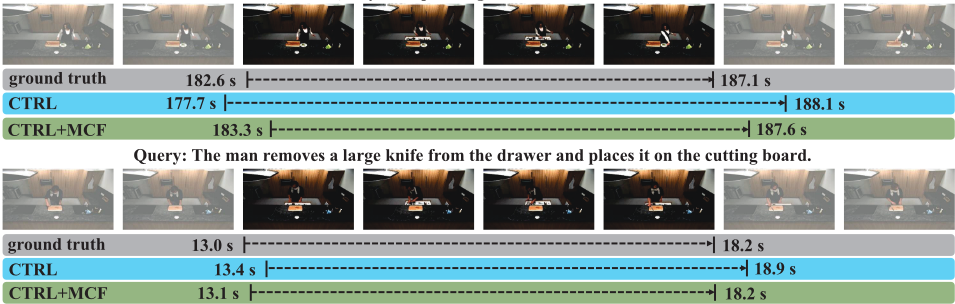
In Fig. 6, we show some examples about TALL task. Particularly, taking the second result as example, our method accurately determines the start and end time for the query which includes two actions.
8 Conclusion
In this paper, we propose the Multi-modal Circulant Fusion (MCF) to combine visual and text representations. We test the MCF on video captioning and TALL tasks. Experimental results on three datasets demonstrate the effectiveness of our method.
Acknowledgments
This work was supported by the NSFC (under Grant U1509206, 61472276, U1736219).
@inproceedings{ijcai2018p143,
  title     = {Multi-modal Circulant Fusion for Video-to-Language and Backward},
  author    = {Wu, Aming and Han, Yahong},
  booktitle = {Proceedings of the Twenty-Seventh International Joint Conference on
               Artificial Intelligence, {IJCAI-18}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Jérôme Lang},
  pages     = {1029--1035},
  year      = {2018},
  month     = {7},
  note      = {Main track},
  doi       = {10.24963/ijcai.2018/143},
  url       = {https://doi.org/10.24963/ijcai.2018/143},
}
TY - CPAPER TI - Multi-modal Circulant Fusion for Video-to-Language and Backward AU - Wu, Aming AU - Han, Yahong T2 - Proceedings of the Twenty-Seventh International Joint Conference on Artificial Intelligence, IJCAI-18 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2018 SP - 1029 EP - 1035 DO - 10.24963/ijcai.2018/143 UR - https://doi.org/10.24963/ijcai.2018/143 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





