
No Time to Observe: Adaptive Influence Maximization with Partial Feedback
Proceedings of the Twenty-Sixth International Joint Conference on Artificial Intelligence. Main track. Pages 3908-3914.
https://doi.org/10.24963/ijcai.2017/546
Keywords
- Planning and Scheduling: Planning with Incomplete information
- Multidisciplinary Topics and Applications: AI and Social Sciences
Abstract
Although influence maximization problem has been extensively studied over the past ten years, majority of existing work adopt one of the following models: full-feedback model or zero-feedback model. In the zero-feedback model, we have to commit the seed users all at once in advance, this strategy is also known as non-adaptive policy. In the full-feedback model, we select one seed at a time and wait until the diffusion completes, before selecting the next seed. Full-feedback model has better performance but potentially huge delay, zero-feedback model has zero delay but poorer performance since it does not utilize the observation that may be made during the seeding process. To fill the gap between these two models, we propose partial-feedback model, which allows us to select a seed at any intermediate stage. We develop a novel alpha-greedy policy that achieves a bounded approximation ratio.
- [Badanidiyuru et al., 2016] Ashwinkumar Badanidiyuru, Christos Papadimitriou, Aviad Rubinstein, Lior Seeman, and Yaron Singer. Locally adaptive optimization: adap- tive seeding for monotone submodular functions. In Proceedings of the Twenty-Seventh Annual ACM-SIAM Symposium on Discrete Algorithms, pages 414-429.
- [Chen et al., 2009] Wei Chen, Yajun Wang, and Siyu Yang. Efficient influence maximization in social networks. In Proceedings of the 15th ACM SIGKDD international con- ference on Knowledge discovery and data mining, pages 199-208. ACM, 2009.
- [Chen et al., 2010] Wei Chen, Chi Wang, and Yajun Wang. Scalable influence maximization for prevalent viral mar- keting in large-scale social networks. In Proceedings of the 16th ACM SIGKDD international conference on Knowl- edge discovery and data mining, pages 1029-1038. ACM, 2010.
- [Chen et al., 2013] Wei Chen, Laks VS Lakshmanan, and Carlos Castillo. Information and influence propagation in social networks. Synthesis Lectures on Data Management, 5(4):1-177, 2013.
- [Cohen et al., 2014] Edith Cohen, Daniel Delling, Thomas Pajor, and Renato F Werneck. Sketch-based influence maximization and computation: Scaling up with guar- antees. In Proceedings of the 23rd ACM International Conference on Conference on Information and Knowledge Management, pages 629-638. ACM, 2014.
- [Domingos and Richardson, 2001] Pedro Domingos and Matt Richardson. Mining the network value of customers. In Proceedings of the seventh ACM SIGKDD international conference on Knowledge discovery and data mining, pages 57-66. ACM, 2001.
- [Golovin and Krause, 2011] Daniel Golovin and Andreas Krause. Adaptive submodularity: Theory and applications in active learning and stochastic optimization. Journal of Artificial Intelligence Research, pages 427-486, 2011.
- [Jung et al., 2012] Kyomin Jung, Wooram Heo, and Wei Chen. Irie: Scalable and robust influence maximization in social networks. In Data Mining (ICDM), 2012 IEEE 12th International Conference on, pages 918-923. IEEE, 2012.
- [Kempe et al., 2003] David Kempe, Jon Kleinberg, and Éva Tardos. Maximizing the spread of influence through a so- cial network. In Proceedings of the ninth ACM SIGKDD international conference on Knowledge discovery and da- ta mining, pages 137-146. ACM, 2003.
- [Leskovec et al., 2007] Jure Leskovec, Andreas Krause, Car- los Guestrin, Christos Faloutsos, Jeanne VanBriesen, and Natalie Glance. Cost-effective outbreak detection in net- works. In Proceedings of the 13th ACM SIGKDD interna- tional conference on Knowledge discovery and data min- ing, pages 420-429. ACM, 2007.
- [Tang and Yuan, 2016] Shaojie Tang and Jing Yuan. Opti- mizing ad allocation in social advertising. In Proceedings of the 25th ACM International on Conference on Infor- mation and Knowledge Management, pages 1383-1392. ACM, 2016.
- [Tang et al., 2011] Shaojie Tang, Jing Yuan, Xufei Mao, Xiang-Yang Li, Wei Chen, and Guojun Dai. Relationship classification in large scale online social networks and its impact on information propagation. In INFOCOM, 2011 Proceedings IEEE, pages 2291-2299. IEEE, 2011.
- [Tang et al., 2015] Youze Tang, Yanchen Shi, and Xiaokui Xiao. Influence maximization in near-linear time: A mar- tingale approach. In Proceedings of the 2015 ACM SIG- MOD International Conference on Management of Data, pages 1539-1554. ACM, 2015.
- [Tong et al., 2016] Guangmo Tong, Weili Wu, Shaojie Tang, and Ding-Zhu Du. Adaptive influence maximization in dy- namic social networks. IEEE/ACM Transactions on Net- working, 2016.
- [Yuan and Tang, 2017] Jing Yuan and Shaojie Tang. Adap- tive discount allocation in social networks. In Proceedings of the eighteenth ACM international symposium on Mobile ad hoc networking and computing. ACM, 2017.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Since the seminal work of [Domingos and Richardson, 2001], the influence maximization problem has attracted tremendous attention in recent years. This problem is first formalized and studied by [Kempe et al., 2003] as a discrete optimization problem. They study this problem under several diffusion models including independent cascade model and linear threshold model. They demonstrate that the influence maximization problem under both models are NP-hard, however, the objective function is monotone and submodular. Due to these nice properties, they propose an elegant greedy algorithm with constant approximation ratio. Since then, considerable work [Chen et al., 2013; Leskovec et al., 2007; Cohen et al., 2014; Chen et al., 2010; 2009; Tang et al., 2011; Tang and Yuan, 2016; Tong et al., 2016; Yuan and Tang, 2017] has been devoted to this topic and its variants.
However, majority of existing work fall into one of the following categories: full-feedback model [Golovin and Krause, 2011] or zero-feedback model [Kempe et al., 2003]. In the zero-feedback model, we have to commit the seed users all at once in advance, this strategy is also known as non-adaptive policy. In the full-feedback model, we select one seed at a
Shaojie Tang
Naveen Jindal School of Management University of Texas at Dallas shaojie.tang@utdallas.edu
time and wait until the diffusion completes, before selecting the next seed, this policy is also known as adaptive policy. Adaptive policy has better performance in terms of expected cascade because of its adaptivity, e.g, it allows us to adaptively choose the next seed after observing the actual spread resulting from previously selected seeds. However, the viral marketing in reality is often time-critical, implying that it is impractical, sometimes impossible, to collect the full status of the actual spread before selecting the next seed.
To fill this gap, we propose a generalized feedback model, called partial-feedback model, that captures the tradeoff between performance and delay. We adopt independent cascade model (IC) [Kempe et al., 2003], which is one of the most commonly used models, to model the diffusion dynamics in a social network. Unfortunately, we show that the objective under partial-feedback model and IC is not adaptive submodular, implying that existing results on adaptive submodular maximization does not apply to our model directly. To overcome this challenge, we develop a novel α-greedy policy, that, for the first time, achieves bounded approximation ratio under partial-feedback model. One nice feature of α-greedy policy is that we can balance the delay/performance tradeoff by adjusting the value of α. In particular, larger (resp. smaller) α implies better (resp. poorer) performance and longer (resp. shorter) delay.
2 RelatedWork
In [Domingos and Richardson, 2001], they show that data mining can be used to determine potential seed users in viral market. Since then, there is a rich body of works that has been devoted to viral marketing problem. Most of existing works on this topic can be classified into two categories. The first category is non-adaptive influence maximization: we must find a set of influential customers all at once in advance subject to a budget constraint. Kempe et al. [Kempe et al., 2003] first formalized and studied this problem under two diffusion models, namely Independent Cascade model and Linear Threshold model. [Chen et al., 2013; Leskovec et al., 2007; Cohen et al., 2014; Chen et al., 2010; 2009] study influence maximization problem under various extended models. The second category is adaptive influence maximization, which is closely related to adaptive/stochastic submodular maximization [Golovin and Krause, 2011; Badanidiyuru et al., 2016; Tong et al., 2016; Yuan and Tang, 2017]. Existing studies mainly adopt full-feedback model, assuming that we can observe the full status of the previous cascade before selecting the next seed. We relax this assumption by incorporating partial-feedback and develop a novel α-greedy adaptive policy that achieves the first bounded approximation ratio.
3 NetworkModel and Diffusion Process
3.1 Independent Cascade Model
A social network is modeled as a directed graph G = (V, E), where V is a set of n nodes and E is a set of social ties. We adopt independent cascade model [Kempe et al., 2003] to model the diffusion dynamics in a social network. Each node v ∈ V is associated with a cost cv, each edge (u, v) in the graph is associated with a propagation probability puv, which is the probability that node u independently influences node v in the next slot after u is influenced. The expected cascade of U, which is the expected number of influenced nodes given seed set U, is denoted as I(U).
3.2 The FeedbackModel
Based on independent cascade model, we next introduce the concept of full diffusion realization [Golovin and Krause, 2011].
Definition 1 (Full Diffusion Realization) For every edge (u, v) ∈ E, it is either in "live" state or in "blocked" state (describing whether the propagation through (u, v) is a success or not). We represent the state of the diffusion stage using function ψF : E → [0, 1], called diffusion realization.
Majority of existing work adopt one of the following feedback models: zero-feedback model or full-feedback model.
Zero-feedback Model: During the seeding process, we can not observe anything about the resulting spread of adoption. Since there is no benefit in "waiting", we can simply commit the seeds all at once in advance. This model is equivalent to traditional non-adaptive model which has been well studied in the literature [Kempe et al., 2003].
Full-feedback Model: We select one seed at a time and wait until the diffusion completes, before selecting the next seed, this policy is also known as adaptive policy. In particular, after selecting a seed u, we can observe the status of all edges existing v, where v is any node that is reachable from u via live edges in ψF . For this model, [Golovin and Krause, 2011] introduced the concept of adaptive submodularity and proposed a Greedy algorithm has a (1 - 1/e) approximation guarantee.
As discussed in Section 1, full-feedback (resp. zerofeedback) model has better (resp. poorer) performance but potentially huge (resp. small) delay. To fill the gap between these two models, we propose partial-feedback model, which generalizes the previous two models by allowing us to select the next seed at any intermediate stage. In particular, we restrict our attention to the following model:
Definition 2 (Partial-feedbackModel) Consider any seed u, after u has been activated for d slots, we can observe the status of all edges existing v, where v is any node that is reachable from u within d - 1 hops via live edges. Then based on the partial feedback collected so far, we can choose to stop observing at any slot and proceeds to selecting the next seed.
4 ProblemFormulation
Under the partial-feedback model, we perform the decision process in a sequential manner where the decision made in each round is depending on the current observation of the network diffusion and the remaining budget. Consider any seed u which has been activated for d slots, we are able to observe the status (live or dead) of all edges exiting v, for all nodes v reachable from u within d - 1 hops via live edges under ψF . The union of such observations from all previously activated seeds can be represented by a partial realization ψ ⊆ ψF . We define our adaptive policy π : ψ → v, which is a function from the current "observation" ψ to v, determining which seed to pick next given ψ.
Assume there is a known prior probability distribution p(ψF ) := P[Ψ = ψF ] over diffusion realizations. Given a realization ψF , let SψF denote all seeds picked by π under ψF , and c(SψF ) = ∑v∈SψF cv denote the total cost of SψF . The expected cascade of a policy π is
where I(SψF |ψF ) denotes the cascade of SψF under realization ψF , e.g., all nodes that are reachable from SψF under ψF . The goal of the adaptive influence maximization problem is to find a policy π such that
We first show that the objective is not adaptive submodular under partial feedback model. The concept of adaptive submodularity is a generalization of submodularity to adaptive policies: we say a function f is adaptive submodular if adding an element e to a realization ψ increases f at least as much as adding e to a superset of ψ. Since the Myopic Feedback model proposed in [Golovin and Krause, 2011] is a special case of our partial-feedback model, we borrow the same counter example from their work to prove the following lemma.
Theorem 1 [Golovin and Krause, 2011] The objective f under partial-feedback model is not adaptive submodular.
5 Adaptive Influence Maximization with Partial Feedback
First of all, we want to emphasize the difference between "round" and "slot". One round corresponds to one execution of our algorithm, while one slot corresponds to one step of information propagation.
5.1 α-Greedy Policy under UniformCost
We first study the case with uniform cost, e.g., ∀v ∈ V : cv = 1. Since each node has the same cost, the budget constraint is reduced to cardinality constraint, e.g., the number of seeds that can selected is upper bounded by B. We next propose an adaptive greedy policy with bounded approximation ratio.
Policy Description
Our greedy policy πu (Algorithm 1) is performed in a sequential greedy manner as follows: After observing the partial diffusion realization, we choose to either wait one slot or select the next seed that maximizes the expected marginal benefit. This process iterates until the budget is used up.
Suppose we have made observations ψ[r] at round r, let pv(S; ψ[r]) denote the activation probability of v given seeds S and observation ψ[r], and let f(S; ψ[r]) = ∑v∈V pv(S; ψ[r]) denote the expected cascade under the same setting. Define O[r] as the set of nodes whose activation probability is zero at round r. Except for the first round, we wait until the following condition is satisfied, before selecting the next seed:
where α ∈ [0, 1] is a control parameter and | · | is the size of a set. This condition can be interpreted as follows: the average activation probability of all nodes with non-zero activation probability is sufficiently high. Note that this condition can always be satisfied in at most D slots, where D is the diameter of the social network. We use α to control the tradeoff of delay and performance. In particular, a larger α indicates longer delay but better performance. For example, if we set α = 1, our model becomes full-feedback model, that is, we must wait until every node is either in active state or nonactive state, before selecting the next seed. On the other hand, if we set α = 0, our model is reduced to zero-feedback model, implying that we can select all seeds in advance.
We use ∆(v; ψ[r]) = f ({v}∪S; ψ[r])-f (S; ψ[r]) to denote the expected marginal benefit of v given existing seeds S and partial realization ψ[r]. It was worth noting that we may select multiple seeds in one slot as long as Condition (1) holds, thus one slot may contain multiple rounds.
Algorithm 1 α-Greedy Policy: πu
Input: 0 ≤ α ≤ 1. Output: S. 1: S = ∅; r = 0; 2: select v = argmaxu∈V \S ∆(u; ψ[r]); 3: S ←S ∪ {v}; B ←B -1; 4: while B ≥ 0 do 5: r ← r +1; 6: if f(S;ψ[r]) |V \O[r]| ≥ α then 7: select v = arg maxu∈V \S ∆(u; ψ[r]); 8: S ← S ∪ {v}; B ← B - 1; 9: else 10: wait one slot; update ψ[r]; 11: return SPerformance Analysis
Let πu [r] denote the level-r-truncation of πu obtained by running until it terminates or until round r. In the rest of this paper, we assume that the i-th seed is selected at round ri. For brevity, we will assume without loss of generality that O = O[ri]. Let f O (S; ψ[ri]) = ∑v∈O pv(S; ψ[ri]) denote the expected cascade in O given seeds S and observation ψ[ri]. We use π∗ to denote the optimal adaptive policy. In the rest of this paper, let f(π; ψ) (resp. f O (π; ψ)) denote the expected cascade of π in V (resp. in O) under realization ψ. In order to prove the main theorem (Theorem 2), we first prove two preparatory lemmas (Lemma 1 and Lemma 2).
Lemma 1 For any 1 ≤ i ≤ B and 0 < α ≤ 1, we have
Proof: Assume ψ′ and ψ are two partial realizations satisfying ψ′ ⊇ ψ, let S ′ and S denote the seeds selected under ψ′ and ψ, satisfying S ′ ⊇ S. Since the activation probability of v is zero, then based on similar proof of Theorem 8.1 in [Golovin and Krause, 2011], we can prove the following ∀v ∈ O, ∀z ∈ V : pv(S ∪ {z}; ψ) - pv(S; ψ) ≥ pv(S ′ ∪ {z}; ψ′ ) - pv(S ′ ; ψ′ ).
Eq. (2) implies that function f O (·) is submodular. Let argmaxz∈V [f O (S ∪ {z}; ψ[ri]) - f O (S; ψ[ri])] denote the largest marginal gain from O at round ri. Since πu selects the node that maximizes the entire marginal gain f(πu [ri] ; ψ[ri]) - f(πu [ri+1] ; ψ[ri ]), thus we have f(πu [ri+1] ; ψ[ri]) - f(πu [ri] ; ψ[ri]) ≥ argmaxz∈V [f O (S ∪ {z}; ψ[ri]) - f O (S; ψ[ri])] ≥ 1B (f O (π∗ ; ψ[ri ]) - f O (πu [ri] ; ψ[ri])). Based on Eq. (2), the second inequality follows the standard analysis of submodular maximization. □
Now we are ready to prove the performance bound of πu .
Theorem 2 The expected cascade of πu is bounded by f (πu ) ≥ α(1 - e- 1α )f (π∗ ).
E[ 1B (f(π∗ ; ψ[ri]) - f(πu [ri] ; ψ[ri])/α)] = 1B ∆i. The first inequality is due to Lemma 2, and the second inequality is due to Lemma 1. It follows that ∆i+1 ≤ (1 - 1 αB )∆i . Hence ∆B ≤ (1 - 1 αB )B ∆0 ≤ e- 1α∆0. It follows that f(π∗ ) - f(πu [rB] )/α ≤ e- 1α∆0 = e- 1α f(π∗ ). Hence f (πu ) = f (πu [rB] ) ≥ α(1 - e- 1α )f (π∗ ). □
As a corollary of Theorem 2, we can prove that the approximation ratio of our greedy policy under full-feedback setting is (1 - e-1 ).
Another interesting finding is that for sufficiently small α, Condition (1) is always true regardless of the observation ψ. Our policy under this setting becomes non-adaptive, implying that we can select all B seeds in advance without observing any partial realization. It is also worth noting that select the seed at a later slot never worsens the result.
Implications of our results. One immediate implication of Theorem 2 is that given a desired approximation ratio, we can decide an appropriate slot to select the next seed. Another implication is that given any level of partial feedback, which can be quantified using α, we can evaluate the performance of the greedy selection strategy in terms of approximation ratio.
5.2 α-Greedy Policy under Non-UniformCost Policy Description
We next study the case with non-uniform cost. The previous adaptive policy can be naturally modified to handle non-uniform item costs by replacing its selection rule by: v = argmaxu∈V \S ∆(u;ψ[r] ) cu . The detailed description of our greedy policy with non-uniform cost, called πnu , is listed in Algorithm 2.
Algorithm 2 α-Greedy Policy with non-uniform cost: πnu
Input: 0 ≤ α ≤ 1. Output: S. 1: S = ∅; r = 0; 2: select v = argmaxu∈V \S ∆(u;ψ[r] ) cu ; 3: S ←S ∪ {v}; B ←B - cv; 4: while B ≥ 0 do 5: r ← r +1; 6: if f(S;ψ[r]) |V \O[r]| ≥ α then 7: select v = arg maxu∈V \S ∆(u;ψ[r] ) cu ; 8: if B - cv < 0 then 9: break; 10: else 11: S ← S ∪ {v}; B ← B - cv; 12: else 13: wait one slot; update ψ[r]; 14: return SPerformance Analysis
We first provide the following two preparatory lemmas. Their proofs are similar to the proofs of Lemma 1 and Lemma 2.
Lemma 3 Assume πnu terminates with l seeds, for any 1 ≤ i ≤ l, we have f(π∗ ; ψ[ri]) - f(πnu [ri] ; ψ[ri])/α ≤ f O (π∗ ; ψ[ri ]) - f O (πnu [ri ] ; ψ[ri ]).
Lemma 4 Let ci+1 denote the cost of the (i + 1)-th seed selected by πnu , we have f(πnu [ri+1] ; ψ[ri]) - f (πnu [ri] ; ψ[ri]) ≥ ci+1 B (f O (π∗ ; ψ[ri ]) - f O (πnu [ri ] ; ψ[ri ])).
Theorem 4 Let c = maxv∈V cv, the expected cascade of πnu is bounded by f (πnu ) ≥ α(1 - e- 1α B-c B )f(π∗ ).
Since our policy runs until the budget has been exhausted, we have ∑li=1 ci ≥ B - c. It follows that f(πnu [rl] ) ≥ α(1 - B-c
Based on πnu , we next provide an enhanced greedy policy πenhanced with constant approximation ratio. πenhanced (Algorithm 3) randomly picks one from the following two candidate solutions with equal probability: The first candidate solution contains a single node v∗ which can maximize the expected cascade: v∗ = argmaxv∈V I({v}); the second candidate solution is computed by the greedy policy πnu .
Algorithm 3 Enhanced Greedy Policy πenhanced
- 1: Randomly pick one from the following two strategies with equal probability: return {v∗ } or run πnu ;
Theorem 5 The expected cascade of πenhanced is bounded
Proof: Assume πnu terminates after selecting l seeds, let cl+1 denote the cost of the first node that can not be selected due to the budget constraint, we have f(πnu ) + I({v∗ }) ≥ α(1 - e- 1α ∑l+1 i=1 ci B )f(π∗ ) ≥ α(1 - e- 1α )f(π∗ ). The first inequality is due to the adaptive submodularity of I(·) and Eq. (4), and the second inequality is because ∑l+1 i=1 ci ≥ B. Then
□As a corollary of Theorem 5, we can prove that the approximation ratio of πenhanced under full-feedback and nonuniform cost setting is (1 - e-1 )/2.
Corollary 6 Under full-feedback model, i.e., α = 1, we have f(πenhanced ) ≥ (1-e-1 ) 2 f(π∗ ).
6 Incorporating Inaccurate Estimation
So far we suppose that the following two assumptions hold: 1. We can find argmaxu∈V \S ∆O[r] (u; ψ[r]) in polynomial time. 2. We can verify Condition (1) in each round in polynomial time. However, since computing the exact value of f(S; ψ) is #P-hard [Chen et al., 2010], the above assumptions may not always hold trivially. Fortunately, an approximate estimation of f (S; ψ) can be computed through Reverse Influence Sampling [Tang et al., 2015]. This motivates us to investigate the performance of α-Greedy Policy under inaccurate estimation of f(S; ψ). We first introduce the definition of ϵ-approximate estimation.
Definition 3 [ϵ-approximate Estimation] Denote by ˜ f (S|ψ) (resp. f(S; ψ)) the estimated (resp. actual) influence given S and ψ. Under ϵ-approximate estimation, we have for any ψ and S: ˜ f (S|ψ) ∈ [(1 - ϵ)f (S; ψ), (1 + ϵ)f (S; ψ)].
Uniform Cost. We first provide an approximate version of Lemma 1 and Lemma 2.
Lemma 5 Consider πu under ϵ-approximate estimation, for any 1 ≤ i ≤ B, we have f(π∗ ; ψ[ri]) - f(πu [ri] ; ψ[ri])(1 + ϵ)/α ≤ f O (π∗ ; ψ[ri]) - f O (πu [ri ] ; ψ[ri ]).
Proof: Notice that at round ri when the i-th seed has been selected, we have ˜ f (S;ψ[ri ] ) |V \O| ≥ α. Since ˜ f(S; ψ[ri]) ∈ [(1 - ϵ)f(S; ψ[ri]), (1 + ϵ)f(S; ψ[ri])], we have f(S;ψ[ri]) |V \O| ≥ α/(1+ϵ). It follows that f(π∗ ; ψ[ri])-f(πu [ri] ; ψ[ri])/ α 1+ϵ ≤ 0. Then f(π∗ ; ψ[ri])-f(πu [ri] ; ψ[ri])/ α 1+ϵ ≤ f O (π∗ ; ψ[ri])- f O (πu [ri] ; ψ[ri]). □
Lemma 6 Consider πu under ϵ-approximate estimation, we have f(πu [ri+1] ; ψ[ri]) - f(πu [ri] ; ψ[ri]) ≥ 1-ϵ (1+ϵ)B (f O (π∗ ; ψ[ri ]) - f O (πu [ri] ; ψ[ri])) - 2ϵ 1+ϵ n.
Proof: We first prove that in any round r under ϵ-approximate estimation, we can find a node v : ∆O[r] (v|ψ[r]) ≥ 1-ϵ 1+ϵ ∆O[r] (u∗ |ψ[r]) - 2ϵ 1+ϵ n where u∗ = argmaxu∈V ∆O[r] (u|ψ[r]). Let ˜∆O[r] (v|ψ[r]) denote the estimated marginal benefit of v, based on Definition 3, we have ˜ f (πu [r] ; ψ[r]) + ˜∆O[r] (v|ψ[r]) ≤ (1 + ϵ)(f (πu [r] ; ψ[r]) + ∆O[r] (v|ψ[r])) and (1 - ϵ)(f(πu [r] ; ψ[r]) + ∆O[r] (u∗ |ψ[r])) ≤ ˜ f (πu [r] ; ψ[r]) + ˜∆O[r] (u∗ |ψ[r]). Together with ˜∆O[r] (v|ψ[r])) ≥ ˜∆O[r] (u∗ |ψ[r])) (due to greedy selection), we have ∆O[r] (v|ψ[r]) ≥ 1-ϵ 1+ϵ ∆O[r] (u∗ |ψ[r]) - 2ϵ 1+ϵ f (πu [r] ; ψ[r]) ≥ 1-ϵ 1+ϵ ∆O[r] (u∗ |ψ[r])- 2ϵ 1+ϵ n where the second inequality is due to f(πu [r] ; ψ[r]) ≤ n.
Then based on similar proof of Lemma 2, we have f(πu [ri+1] ; ψ[ri]) - f(πu [ri] ; ψ[ri]) ≥ 1-ϵ 1+ϵ 1B (f O (π∗ ; ψ[ri ]) - f O (πu [ri] ; ψ[ri])) - 2ϵ 1+ϵ n. □
Theorem 7 The expected cascade of πu under ϵapproximate estimation is bounded by
Non-Uniform Cost. We next provide the approximation ratio of πenhanced under ϵ-approximate estimation for the case with non-uniform cost. Without loss of generality, we assume ∀v ∈ V : cv ≥ 1.
Lemma 7 Consider πnu under ϵ-approximate estimation, for any 1 ≤ i ≤ B, we have f(π∗ ; ψ[ri]) - f(πnu [ri] ; ψ[ri])(1 + ϵ)/α ≤ f O (π∗ ; ψ[ri]) - f O (πnu [ri ] ; ψ[ri ]).
The scheme of the proof is the same as in Lemma 5.
Lemma 8 Let ci+1 denote the cost of the (i + 1)-th seed selected by πnu under ϵ-approximate estimation, we have f(πnu [ri+1] ; ψ[ri]) - f(πnu [ri] ; ψ[ri]) ≥ 1-ϵ 1+ϵ ci+1 B (f O (π∗ ; ψ[ri ]) - f O (πnu [ri] ; ψ[ri]))- 2ϵ 1+ϵ ( ci+1 c +1)n where c = minv∈V cv.
Proof: Let u∗ = argmaxu∈V ∆(u;ψ[r] ) cu . We first prove that at each round r, we can find a v such that ∆(v;ψ[r]) cv ≥ 1-ϵ 1+ϵ ∆(u∗ ;ψ[r] ) cu∗ - 2ϵ 1+ϵ ( 1c + 1 cv )n. Based on Definition 3, we have ˜ f (πu [r] ;ψ[r] )+ ˜∆O[r] (v|ψ[r] ) [r] ;ψ[r] )+∆O[r] (v|ψ[r] ))
□Theorem 8 The expected cascade of πnu under ϵapproximate estimation is bounded by
α
Proof: Let ∆i = f(π∗ ) - f(πnu [ri] )/ α 1+ϵ , we have α 1+ϵ (∆i - ∆i+1) = f(πnu [ri+1] ) - f(πnu [ri] ) ≥ E[ 1-ϵ 1+ϵ ci+1 B (f O (π∗ ; ψ[ri ]) - f O (πnu [ri] ; ψ[ri])) - 2ϵ 1+ϵ ( ci+1 c + 1)n] ≥ E[ 1-ϵ 1+ϵ ci+1 B (f(π∗ ; ψ[ri]) - f(π[ri]; ψ[ri])/ α 1+ϵ )] - 2ϵ 1+ϵ ( ci+1 c + 1)n ≥ 1-ϵ 1+ϵ ci+1 B ∆i - 2ϵ 1+ϵ ( ci+1 c + 1)n. The first inequality is due to Lemma 8 and the second inequality is due to Lemma 7. It follows that ∆i+1 ≤ (1 - (1-ϵ)ci+1 αB )∆i + 2ϵ α ( ci+1 c + 1)n. Hence, assume πnu terminates with selecting l seeds under budget B, we have ∆l ≤ [∏li=1 (1- (1-ϵ)ci αB )]∆0++ 2ϵ α ( 1c +1)nB ≤ e- 1-ϵ ∑li=1 ci B ∆0 + 2ϵ α ( 1c + 1)nB. Hence
Since our policy runs until the budget has been exhausted, we have ∑li=1 ci ≥ B-c. It follows that f(πnu [rl] ) ≥ α 1+ϵ (1e- 1-ϵ α B-c B )f(π∗ ) - 2ϵ 1+ϵ ( 1c + 1)nB. □
Theorem 9 The expected cascade of πenhanced under ϵapproximate estimation is bounded by f(πenhanced ) ≥ 12 1-ϵ 1+ϵ [ α 1+ϵ (1 - e- 1-ϵ α )f(π∗ ) - 2ϵ 1+ϵ ( 1c + 1)nB].
The proof is similar to the proof of Theorem 5, the only difference is that the first candidate solution can only achieve 1-ϵ 1+ϵ maxv∈V I({v}) and the second candidate solution can achieve the bound derived in Theorem 8.
7 Experimental Evaluation
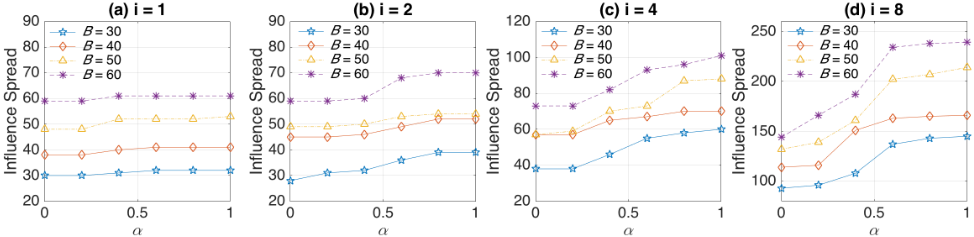
We conduct extensive experiments on a real benchmark social networks: NetHEPT to examine the effectiveness and efficiency of the partial adaptive seeding algorithms. We set the propagation probability of each directed edge randomly from i × {0.01, 0.001} as in [Jung et al., 2012]. We vary the value of i and examine how it affects the quality of the solutions. We adjust the value of control parameter α in range [0, 1].
Figure 1 shows the influence spread yielded by the proposed enhanced greedy policy on the NetHEPT dataset, as α ranges from 0 to 1 with a step of 0.2. The x-axis corresponds to the value of the control parameter α and the y-axis holds the size of the influence spread achieved. We test the scenario with varying edge propagation probability distributions as discussed above. In particular, each edge is randomly assigned a propagation probability from i × {0.01, 0.001}. We adjust the value of i from 1 to 8 and Figure 1(a)-(d) shows the comparison of the influence spread under i = 1, i = 2, i = 4, i = 8, respectively. In this set of experiments, the budget B ranges from 30 to 60. The cost of each node is randomly assigned from [1, 10]. As expected, a higher budget leads to a larger influence spread.
We observe that when i takes a smaller value, take i = 1 as an example, the advantage of performing adaptive seeding with partial feedback is not obvious since the improvement over influence spread does not increase much as α increases. The reason behind this is that a smaller i indicates a lower probability for the edges to be alive, resulting in a lower uncertainty about the status of the edges. In this case observations gained from partial feedback may not help much since with high probability the estimation of influence spread based on sampling technique matches the real propagation. As shown in Figure 1, the advantage of taking adaptive seeding based on partial feedback becomes obvious as i increases. We observe that when i ≥ 2, a much larger influence spread can be achieved based on partial feedback (α > 0) compared to zero feedback scenario (α = 0). For example, when i = 4 with budget of 50, while the influence spread based on zero feedback leads to a size of 57, the spread achieves a size of 87 based on partial feedback (α = 0.8), a 52.6% increase.
We also observe that a smaller α can lead to a significant improvement on influence spread with a higher edge propagation probability. For example, as shown in Figure 1, when i = 2, a 10% improvement can be achieved with α = 0.6. When i = 4, a 20% improvement can be achieved with α = 0.4. This implies that given a social graph with moderate edge propagation probability, it is worth to leverage the partial observation of diffusion realization, since adaptive seeding based on partial feedback leads to a significant improvement over the size of influence spread.
8 Conclusion
To the best of our knowledge, we are the first to systematically study the problem of influence maximization problem with partial feedback. Under independent cascade model, which is one of the most commonly used models in literature, we present a novel greedy algorithm with bounded approximation ratio. We also extend our results to incorporate inaccurate estimations.
@inproceedings{ijcai2017p546,
  title     = {No Time to Observe: Adaptive Influence Maximization with Partial Feedback},
  author    = {Yuan, Jing and Tang, Shaojie},
  booktitle = {Proceedings of the Twenty-Sixth International Joint Conference on
               Artificial Intelligence, {IJCAI-17}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Carles Sierra},
  pages     = {3908--3914},
  year      = {2017},
  month     = {8},
  note      = {Main track},
  doi       = {10.24963/ijcai.2017/546},
  url       = {https://doi.org/10.24963/ijcai.2017/546},
}
TY - CPAPER TI - No Time to Observe: Adaptive Influence Maximization with Partial Feedback AU - Yuan, Jing AU - Tang, Shaojie T2 - Proceedings of the Twenty-Sixth International Joint Conference on Artificial Intelligence, IJCAI-17 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2017 SP - 3908 EP - 3914 DO - 10.24963/ijcai.2017/546 UR - https://doi.org/10.24963/ijcai.2017/546 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





