
Bernoulli Rank-1 Bandits for Click Feedback
Proceedings of the Twenty-Sixth International Joint Conference on Artificial Intelligence. Main track. Pages 2001-2007.
https://doi.org/10.24963/ijcai.2017/278
Keywords
- Machine Learning: Learning Preferences or Rankings
- Machine Learning: Structured Learning
- Multidisciplinary Topics and Applications: Personalization and User Modeling
- Machine Learning: Online Learning
Abstract
The probability that a user will click a search result depends both on its relevance and its position on the results page. The position based model explains this behavior by ascribing to every item an attraction probability, and to every position an examination probability. To be clicked, a result must be both attractive and examined. The probabilities of an item-position pair being clicked thus form the entries of a rank-1 matrix. We propose the learning problem of a Bernoulli rank-1 bandit where at each step, the learning agent chooses a pair of row and column arms, and receives the product of their Bernoulli-distributed values as a reward. This is a special case of the stochastic rank-1 bandit problem considered in recent work that proposed an elimination based algorithm Rank1Elim, and showed that Rank1Elim's regret scales linearly with the number of rows and columns on "benign" instances. These are the instances where the minimum of the average row and column rewards mu is bounded away from zero. The issue with Rank1Elim is that it fails to be competitive with straightforward bandit strategies as mu tends to 0. In this paper we propose Rank1ElimKL, which replaces the crude confidence intervals of Rank1Elim with confidence intervals based on Kullback-Leibler (KL) divergences. With the help of a novel result concerning the scaling of KL divergences we prove that with this change, our algorithm will be competitive no matter the value of mu. Experiments with synthetic data confirm that on benign instances the performance of Rank1ElimKL is significantly better than that of even Rank1Elim. Similarly, experiments with models derived from real-data confirm that the improvements are significant across the board, regardless of whether the data is benign or not.
- [Auer and Ortner, 2010] Peter Auer and Ronald Ortner. UCB revisited: Improved regret bounds for the stochas- tic multi-armed bandit problem. Periodica Mathematica Hungarica, 61(1-2):55-65, 2010.
- [Auer et al., 2002] Peter Auer, Nicolo Cesa-Bianchi, and Paul Fischer. Finite-time analysis of the multiarmed bandit problem. Machine Learning, 47:235-256, 2002.
- [Chuklin et al., 2015] Aleksandr Chuklin, Ilya Markov, and Maarten de Rijke. Click Models for Web Search. Morgan & Claypool Publishers, 2015.
- [Combes et al., 2015] Richard Combes, Stefan Magureanu, Alexandre Proutiere, and Cyrille Laroche. Learning to rank: Regret lower bounds and efficient algorithms. In Proceedings of the 2015 ACM SIGMETRICS International Conference on Measurement and Modeling of Computer Systems, 2015.
- [Craswell et al., 2008] Nick Craswell, Onno Zoeter, Michael Taylor, and Bill Ramsey. An experimental comparison of click position-bias models. In Proceedings of the 1st ACM International Conference on Web Search and Data Min- ing, pages 87-94, 2008.
- [Garivier and Cappe, 2011] Aurelien Garivier and Olivier Cappe. The KL-UCB algorithm for bounded stochastic bandits and beyond. In Proceeding of the 24th Annual Conference on Learning Theory, pages 359-376, 2011.
- [Gentile et al., 2014] Claudio Gentile, Shuai Li, and Gio- vanni Zappella. Online clustering of bandits. In Pro- ceedings of the 31st International Conference on Machine Learning, pages 757-765, 2014.
- [Katariya et al., 2016] Sumeet Katariya, Branislav Kveton, Csaba Szepesvari, and Zheng Wen. DCM bandits: Learn- ing to rank with multiple clicks. In Proceedings of the 33rd International Conference on Machine Learning, 2016.
- [Katariya et al., 2017] Sumeet Katariya, Branislav Kveton, Csaba Szepesvari, Claire Vernade, and Zheng Wen. Stochastic rank-1 bandits. In AISTATS, 2017.
- [Kawale et al., 2015] Jaya Kawale, Hung Bui, Branislav Kveton, Long Tran-Thanh, and Sanjay Chawla. Efficient Thompson sampling for online matrix-factorization rec- ommendation. In Advances in Neural Information Pro- cessing Systems 28, pages 1297-1305, 2015.
- [Kveton et al., 2015a] Branislav Kveton, Csaba Szepesvari, Zheng Wen, and Azin Ashkan. Cascading bandits: Learn- ing to rank in the cascade model. In Proceedings of the 32nd International Conference on Machine Learning, 2015.
- [Kveton et al., 2015b] Branislav Kveton, Zheng Wen, Azin Ashkan, and Csaba Szepesvari. Combinatorial cascading bandits. In Advances in Neural Information Processing Systems 28, pages 1450-1458, 2015.
- [Lagree et al., 2016] Paul Lagree, Claire Vernade, and Olivier Cappe. Multiple-play bandits in the position-based model. CoRR, abs/1606.02448, 2016.
- [Li et al., 2016] Shuai Li, Baoxiang Wang, Shengyu Zhang, and Wei Chen. Contextual combinatorial cascading ban- dits. In Proceedings of the 33rd International Conference on Machine Learning, pages 1245-1253, 2016.
- [Maillard and Mannor, 2014] Odalric-Ambrym Maillard and Shie Mannor. Latent bandits. In Proceedings of the 31st International Conference on Machine Learning, pages 136-144, 2014.
- [Markov, 2014] Ilya Markov. Pyclick -click models for web search. https://github.com/markovi/PyClick, 2014. Link
- [Richardson et al., 2007] Matthew Richardson, Ewa Domi- nowska, and Robert Ragno. Predicting clicks: Estimating the click-through rate for new ads. In Proceedings of the 16th International Conference on World Wide Web, pages 521-530, 2007.
- [Sen et al., 2017] Rajat Sen, Karthikeyan Shanmugam, Mu- rat Kocaoglu, Alexandros G Dimakis, and Sanjay Shakkottai. Contextual bandits with latent confounders: An nmf approach. In AISTATS, 2017.
- [Thompson, 1933] William. R. Thompson. On the likelihood that one unknown probability exceeds another in view of the evidence of two samples. Biometrika, 25(3-4):285- 294, 1933.
- [Yandex, 2013] Yandex personalized web search chal- lenge. https://www.kaggle.com/c/yandex-personalized- web-search-challenge, 2013. Link
- [Zhao et al., 2013] Xiaoxue Zhao, Weinan Zhang, and Jun Wang. Interactive collaborative filtering. In Proceedings of the 22nd ACM International Conference on Information and Knowledge Management, pages 1411-1420, 2013.
- [Zong et al., 2016] Shi Zong, Hao Ni, Kenny Sung, Nan Rosemary Ke, Zheng Wen, and Branislav Kveton. Cascading bandits for large-scale recommendation prob- lems. In Proceedings of the 32nd Conference on Uncer- tainty in Artificial Intelligence, 2016.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
When deciding which search results to present, click logs are of particular interest. A fundamental problem in click data is position bias. The probability of an element being clicked depends not only on its relevance, but also on its position on the results page. The position-based model (PBM), first proposed by Richardson et al. [2007] and then formalized by Craswell et al. [2008], models this behavior by associating with each item a probability of being attractive, and with each position a probability of being examined. To be clicked, a result must be both attractive and examined. Given click logs, the attraction and examination probabilities can be learned using the maximum-likelihood estimation (MLE) or the expectationmaximization (EM) algorithms [Chuklin et al., 2015].
An online learning model for this problem is proposed in Katariya et al. [2017], called stochastic rank-1 bandit. The objective of the learning agent is to learn the most rewarding item and position, which is the maximum entry of a rank-1 matrix. At time t, the agent chooses a pair of row and column arms, and receives the product of their values as a reward. The goal of the agent is to maximize its expected cumulative reward, or equivalently to minimize its expected cumulative regret with respect to the optimal solution, the most rewarding pair of row and column arms. This learning problem is challenging because when the agent receives the reward of zero, it could mean either that the item was unattractive, or the position was not examined, or both.
Katariya et al. [2017] also proposed an elimination algorithm, Rank1Elim, whose regret is O((K + L)µ-2∆-1 logn), where K is the number of rows, L is the number of columns, ∆ is the minimum of the row and column gaps, and µ is the minimum of the average row and column rewards. When µ is bounded away from zero, the regret scales linearly with K + L, while it scales inversely with ∆. This is a significant improvement over using a standard bandit algorithm that (disregarding the problem structure) would treat item-position pairs as unrelated arms and would achieve a regret of O(KL∆-1 logn). The issue is that as µ gets small, the regret bound worsens significantly. As we verify in Section 5, this indeed happens on models derived from some real-world problems. To illustrate the severity of this problem, consider as an example where K = L, and the row and column rewards are Bernoulli distributed. Let the mean reward of row 1 and column 1 be ∆, and the mean reward of all other rows and columns be 0. We refer to this setting as a "needle in a haystack", because there is a single rewarding entry out of K2 entries. For this setting, µ = ∆/K, and consequently the regret of Rank1Elim is O(µ-2∆-1K logn) = O(K3 logn). However, a naive bandit algorithm that ignores the rank-1 structure and treats each row-column pair as unrelated arms has O(K2 log n) regret. 1 While a naive bandit algorithm is unable to exploit the rank-1 structure when µ is large, Rank1Elim is unable to keep up with a naive algorithm when µ is small. Our goal in this paper is to design an algorithm that performs well across all rank-1 problem instances regardless of their parameters.
In this paper we propose that this improvement can be achieved by replacing the "UCB1 confidence intervals" used by Rank1Elim by strictly tighter confidence intervals based on Kullback-Leibler (KL) divergences. This leads to our algorithm that we call Rank1ElimKL. Based on the work of Garivier and Cappe [2011], we expect this change to lead to an improved behavior, especially for extreme instances, as µ → 0. Indeed, in this paper we show that KL divergences enjoy a peculiar "scaling". In particular, thanks to this improvement, for the "needle in a haystack" problem discussed above the regret of Rank1ElimKL becomes O(K2 log n).
Our contributions are as follows. First, we propose a Bernoulli rank-1 bandit, which is a special class of a stochastic rank-1 bandit where the rewards are Bernoulli distributed. Second, we modify Rank1Elim for solving the Bernoulli rank-1 bandit, which we call Rank1ElimKL, to use KL-UCB intervals. Third, we derive a O((K + L) (µγ∆)-1 log n) gap-dependent upper bound on the n-step regret of Rank1ElimKL, where K, L,∆ and µ are as above, while γ = max{µ, 1-pmax} with pmax being the maximum of the row and column rewards; effectively replacing the µ-2 term of the previous regret bound of Rank1Elim with (µγ)-1 . It follows that the new bound is an unilateral improvement over the previous one and is a strict improvement when µ < 1 - pmax, which is expected to happen quite often in practical problems. For the "needle in a haystack" problem, the new bound essentially matches that of the naive bandit algorithm, while never worsening the bound of Rank1Elim. Our final contribution is the experimental validation of Rank1ElimKL, on both synthetic and real-world problems. The experiments indicate that Rank1ElimKL outperforms several baselines across almost all problem instances.
We denote random variables by boldface letters and define [n] = {1, . . . , n}. For any sets A and B, we denote by AB the set of all vectors whose entries are indexed by B and take values from A. We let d(p, q) = p log pq + (1 - p) log 1-p 1-q denote the KL divergence between the Bernoulli distributions with means p, q ∈ [0, 1]. As usual, the formula for d(p, q) is defined through its continuous extension as p, q approach the boundaries of [0, 1].
2 Setting
The setting of the Bernoulli rank-1 bandit is the same as that of the stochastic rank-1 bandit [Katariya et al., 2017], with the additional requirement that the row and column rewards are Bernoulli distributed. We state the setting for completeness, and borrow the notation from Katariya et al. [2017] for the ease of comparison.
1 Alternatively, the worst-case regret bound for Rank1Elim becomes O(Kn2/3 logn), while that of for a naive bandit algorithm with a naive bound is O(Kn1/2 log n).
An instance of our learning problem is defined by a tuple (K, L, PU, PV), where K is the number of rows, L is the number of columns, PU is a distribution over {0, 1}K from which the row rewards are drawn, and PV is a distribution over {0, 1}L from which the column rewards are drawn.
Let the row and column rewards be
In particular, ut and vt are drawn independently at any time t. At time t, the learning agent chooses a row index it ∈ [K] and a column index jt ∈ [L], and observes ut(it)v(jt) as its reward. The indices it and jt chosen by the learning agent are allowed to depend only on the history of the agent up to time t.
Let the time horizon be n. The goal of the agent is to maximize its expected cumulative reward in n steps. This is equivalent to minimizing the expected cumulative regret in n steps
where R(it, jt, ut, vt) = ut(i∗ )vt(j ∗ ) - ut(it)vt(jt) is the instantaneous stochastic regret of the agent at time t, and
is the optimal solution in hindsight of knowing PU and PV.
3 Rank1ElimKL Algorithm
The pseudocode of our algorithm, Rank1ElimKL, is in Algorithm 1. As noted earlier this algorithm is based on Rank1Elim [Katariya et al., 2017] with the difference that we replace their confidence intervals with KL-based confidence intervals. For the reader's benefit, we explain the full algorithm.
Rank1ElimKL is an elimination algorithm that operates in stages, where the elimination is conducted with KL-UCB confidence intervals. The lengths of the stages quadruple from one stage to the next, and the algorithm is designed such that at the end of stage ℓ, it eliminates with high probability any row and column whose gap scaled by a problem dependent constant is at least ˜∆ℓ = 2-ℓ . We denote the remaining rows and columns in stage ℓ by Iℓ and Jℓ, respectively.
Every stage has an exploration phase and an exploitation phase. During row-exploration in stage ℓ (lines 12-16), every remaining row is played with a randomly chosen remaining column,
In the exploitation phase, we construct high-probability KL-UCB [Garivier and Cappe, 2011] confidence intervals [LU ℓ (i), UU ℓ (i)] for row i ∈ Iℓ, and confidence intervals [LV ℓ (j), UV ℓ (j)] for column j ∈ Jℓ. As noted earlier, this is where we depart from Rank1Elim. The elimination uses row iℓ and column jℓ, where
Algorithm 1 Rank1ElimKL for Bernoulli rank-1 bandits.
- 1: // Initialization
- 2: t ← 1, ˜∆0 ← 1, n-1 ← 0
- 3: CU 0 ← 0K,L, CV 0 ← 0K,L // Zero matrix with K rows and L columns
- 4: hU 0 ← (1, . . . ,K), hV 0 ← (1, . . . , L)
5:
- 6: for ℓ = 0, 1, . . . do
9:
- 10: // Row and column exploration
- 11: for nℓ - nℓ-1 times do
- 12: Choose uniformly at random column j ∈ [L]
- 13: j ← hV ℓ (j)
17: Choose uniformly at random row i ∈ [K]
- 18: i ← hU ℓ (i)
- 19:
20:
21:
22:
23:
- // UCBs and LCBs on the expected rewards of all remaining rows and columns with divergence constraint δℓ ← log n + 3 log log n
We eliminate any row i and column j such that
We also track the remaining rows and columns in stage ℓ by hU ℓ and hV ℓ , respectively. When row i is eliminated by row iℓ, we set hU ℓ (i) = iℓ. If row iℓ is eliminated by row iℓ′ at a later stage ℓ′ > ℓ, we update hU ℓ (i) = iℓ′ . This is analogous for columns. The remaining rows Iℓ and columns Jℓ can be then defined as the unique values in hU ℓ and hV ℓ , respectively. The maps hU ℓ and hV ℓ help to guarantee that the row and column means are non-decreasing.
The KL-UCB confidence intervals in Rank1ElimKL can be found by solving a one-dimensional convex optimization problem for every row (lines 27-28) and column (lines 3132). They can be found efficiently using binary search because the Kullback-Leibler divergence d(x, q) is convex in q as q moves away from x in either direction. The KL-UCB confidence intervals need to be computed only once per stage. Hence, Rank1ElimKL has to solve at most K + L convex optimization problems per stage, and hence (K + L) logn problems overall.
4 Analysis
In this section, we derive a gap-dependent upper bound on the n-step regret of Rank1ElimKL. The hardness of our learning problem is measured by two kinds of metrics. The first kind are gaps. The gaps of row i ∈ [K] and column j ∈ [L] are defined as∆U i = ¯u(i∗ ) - ¯u(i) , ∆V j = ¯ v(j ∗ ) - ¯ v(j) , (1)
respectively; and the minimum row and column gaps are de-
respectively. Roughly speaking, the smaller the gaps, the harder the problem. This inverse dependence on gaps is tight [Katariya et al., 2017].
The second kind of metrics are the extremal parameters
The first metric, µ, is the minimum of the average of entries of ¯u and ¯ v. This quantity appears in our analysis due to the averaging character of Rank1ElimKL. The smaller the value of µ, the larger the regret. The second metric, pmax, is the maximum entry in ¯u and ¯ v. As we shall see the regret scales inversely with
Note that if µ → 0 and pmax → 1 at the same time, then the row and columns gaps must also approach one. With this we are ready to state our main result.
Theorem 1. Let C = 6e + 82 and n ≥ 5. Then the expected n-step regret of Rank1ElimKL is bounded as
where
The difference from the main result of Katariya et al. [2017] is that the first term in our bound scales with 1/(µγ) instead of 1/µ2 . Since µ ≤ γ and in fact often µ ≪ γ, this is a significant improvement. We validate this empirically in the next section.
Due to the lack of space, we only provide a sketch of the proof of Theorem 1. At a high level, it follows the steps of the proof of Katariya et al. [2017]. Focusing on the source of the improvement, we first state and prove a new lemma, which allows us to replace one 1/µ in the regret bound with 1/γ. Recall from Section 1 that d denotes the KL divergence between Bernoulli random variables with means p, q ∈ [0, 1].
Lemma 1. Let c, p, q ∈ [0, 1]. Then
In particular,
Proof. The proof of (6) is based on differentiation. The first two derivatives of d(cp, cq) with respect to q are
and the first two derivatives of cd(p, q) with respect to q are
The second derivatives show that both d(cp, cq) and cd(p, q) are convex in q for any p. The minima are at q = p.
We fix p and c, and prove (6) for any q. The upper bound is derived as follows. Since
when x = p, the upper bound holds if cd(p, x) increases faster than d(cp, cx) for any p < x ≤ q, and if cd(p, x) decreases faster than d(cp, cx) for any q ≤ x < p. This follows from the definitions of ∂ ∂x d(cp, cx) and ∂ ∂x [cd(p, x)]. In particular, both derivatives have the same sign for any x, and 1/(1 - cx) ≤ 1/(1 - x) for x ∈ [min {p, q} , max {p, q}].
The lower bound is derived as follows. Note that the ratio of ∂ ∂x [cd(p, x)] and ∂ ∂x d(cp, cx) is bounded from above as
for any x ∈ [min{p, q} ,max{p, q}]. Therefore, we get a lower bound on d(cp, cq) when we multiply cd(p, q) by 1 - max {p, q}.
To prove (7) note that by Pinsker's inequality, for any p, q, d(p, q) ≥ 2(p-q)2 . Hence, on one hand, d(cp, cq) ≥ 2c2 (pq)2 . On the other hand, we have from (6) that d(cp, cq) ≥ 2c(1 - max{p, q})(p - q)2 . Taking the maximum of the right-hand sides in these two equations gives (7).
Proof sketch of Theorem 1. We proceed along the lines of Katariya et al. [2017]. The key step in their analysis is the upper bound on the expected n-step regret of any suboptimal row i ∈ [K]. This bound is proved as follows. First, Katariya et al. [2017] show that row i is eliminated with a high probability after O((µ∆U i )-2 log n) observations, for any column elimination strategy. Then they argue that the amortized per-observation regret before the elimination is O(∆U i ). Therefore, the maximum regret due to row i is O(µ-2 (∆U i )-1 log n). The expected n-step regret of any suboptimal column j ∈ [L] is bounded analogously.
We modify the above argument as follows. Roughly speaking, due to the KL-UCB confidence interval, a suboptimal row i is eliminated with a high probability after
observations. Therefore, the expected n-step regret due to exploring row i is
Now we apply (7) of Lemma 1 to get that the regret is
The regret of any suboptimal column j ∈ [L] is bounded analogously.
5 Experiments
We conduct two experiments. In Section 5.1, we compare our algorithm to other algorithms in the literature on a synthetic problem. In Section 5.2, we evaluate the same algorithms on click models that are trained on a real-world dataset.
5.1 Comparison to Alternative Algorithms
Following Katariya et al. [2017], we consider the "needle in a haystack" class of problems, where only one item is attractive and one position is examined. We recall the problem here. The i-th entry of ut, ut(i), and the j-th entry of vt, vt(j), are independent Bernoulli variables with means
for some (pU, pV) ∈ [0, 1]2 and gaps (∆U, ∆V) ∈ (0, 1-pU]× (0, 1 - pV]. Note that arm (1, 1) is optimal with an expected reward of (pU +∆U)(pV +∆V).
The goal of this experiment is to compare Rank1ElimKL with five other algorithms from the literature and validate that its regret scales linearly with K and L, which implies that it exploits the problem structure. In this experiment, we set pU =pV =0.25,∆U =∆V =0.5,andK =L,sothatµ= (1-1/K)0.25+0.75/K=0.25+0.5/K,1-pmax =0.25, andγ=µ=0.25+0.5/K.
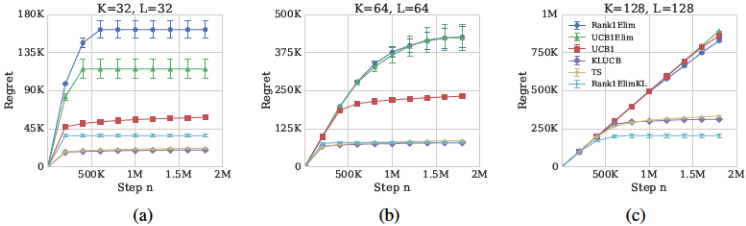
InadditiontocomparingtoRank1Elim,wealsocompare toUCB1Elim[AuerandOrtner,2010],UCB1[Aueretal., 2002],KL-UCB[GarivierandCappe,2011],andThompson sampling[Thompson,1933].UCB1ischosenasabaseline asithasbeenusedbyKatariyaetal.[2017]intheirexperiments.UCB1Elimusesaneliminationapproachsimilarto Rank1ElimandRank1ElimKL.KL-UCBissimilartoUCB1, butitusesKL-UCBconfidenceintervals.Thompsonsampling (TS)isaBayesianalgorithmthatmaximizestheexpectedrewardwithrespecttoarandomlydrawnbelief.
Figure1showsthen-stepregretofthealgorithmsdescribedaboveasafunctionoftimenforK = L,thelatterofwhichdoublesfromoneplottothenext. WeobservethattheregretofRank1ElimKLflattensinallthree problems,whichindicatesthatRank1ElimKLlearnstheoptimalarm. WealsoseethattheregretofRank1ElimKLdoublesasK andLdouble,indicatingthatourboundinTheorem1hastherightscalinginK+L,andthatthealgorithm leveragestheproblemstructure. Ontheotherhand,theregretofUCB1,UCB1Elim,KL-UCBandTSquadrupleswhenK andLdouble,confirmingthattheirregretisΩ(KL). Next, weobservethatwhileKL-UCBandTShavesmallerregret thanRank1ElimKLwhenK andLaresmall,the(K +L)- scalingofRank1ElimKLenablesittooutperformthesealgorithmsforlargeK andL(Figure1c). Finally,notethat Rank1ElimKLoutperformsRank1Eliminallthreeexperiments,confirmingtheimportanceoftighterconfidenceintervals.Itisworthnotingthatµ=γforthisproblem,andhence µ 2 = µγ. AccordingtoTheorem1,Rank1ElimKLshould notperformbetterthanRank1Elim. Yetitis4timesbetter asseeninFigure1a.Thissuggeststhatourupperboundis loose.
5.2 ModelsBasedonReal-WorldData
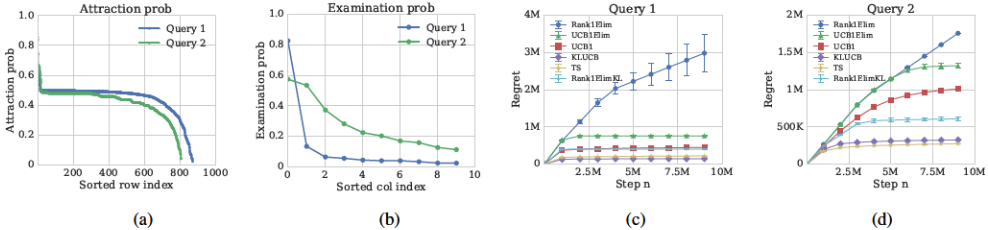
Inthisexperiment,wecompareRank1ElimKLtootheralgorithmsonclickmodelsthataretrainedontheYandexdataset [Yandex,2013],ananonymizedsearchlogof35Msearchsessions. Eachsessioncontainsaquery,thelistofdisplayed documentsatpositions1to10,andtheclicksonthosedocuments. Weselect20mostfrequentqueriesfromthedataset, andestimatetheparametersofthePBMmodelusingtheEM algorithm[Markov,2014;Chuklinetal.,2015].
Toillustrateourlearnedmodels,weplottheparameters oftwoqueries,Queries1and2.Figure2ashowsthesorted attractionprobabilitiesofitemsinthequeries,andFigure2b showsthesortedexaminationprobabilitiesofthepositions. Query1hasL=871itemsandQuery2hasL=807items. K =10isthenumberofdocumentsdisplayedperquery. Weillustratetheperformanceonthesequeriesbecausethey differnotablyintheirµ(3)andpmax (4),sowecanstudythe performanceofouralgorithmindifferentreal-worldsettings. Figure2canddshowtheregretofallalgorithmsonQueries 1and2,respectively.
Wefirstnotethat KL-UCBandTSdobetterthan Rank1ElimKLonbothqueries. AsseeninSection5.1, Rank1ElimKLisexpectedtoimproveoverthesebaselinesfor largeK andL,whichisnotthecasehere. Withrespectto otheralgorithms,weseethatRank1ElimKLissignificantly betterthanRank1ElimandUCB1Elimandnoworsethan UCB1onQuery1,whileforQuery2,Rank1ElimKLissuperiortoallofthem.Notethatpmax =0.85inQuery1ishigher thanpmax =0.66inQuery2.Also,µ=0.13inQuery1is lowerthanµ=0.28inQuery2. From(5),γ=0.15in Query1,whichislowerthanγ=0.34inQuery2.Ourupperbound(Theorem1)ontheregretofRank1ElimKLscales asO((µγ) -1 ),andsoweexpectRank1ElimKLtoperform betteronQuery2.Ourresultsconfirmthisexpectation.
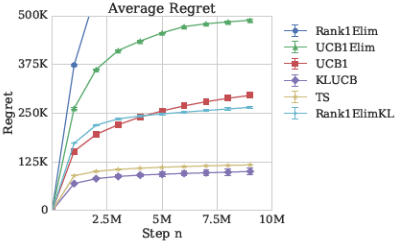
InFigure3,weplottheaverageregretoverall20queries, wherethestandarderroriscomputedbyrepeatingthisprocedure5times.Rank1ElimKLhasthelowestregretofall algorithmsexceptforKL-UCBandTS.Itsregretis10.9percentlowerthanthatofUCB1,and79percentlowerthanthat ofRank1Elim.Thisisexpected.Somereal-worldinstances haveabenignrank-1structurelikeQuery2,whileothersdo not,likeQuery1. Hence,weseeareductionintheaveragegainsofRank1ElimKLoverUCB1inFigure3ascomparedtoFigure2d.ThehighregretofRank1Elim,whichis alsodesignedtoexploittheproblemstructure,showsthatit ismoresensitivetounfavorablerank-1structures.Thus,the goodnewsisthatRank1ElimKLimprovesonthislimitation ofRank1Elim. However,KL-UCBandTSperformbetteron average,andwebelievethisisduetothefact14outofour 20querieshaveL <200,andhenceKL < 2000.Thisis inlinewiththeresultsofSection5.1,whichsuggestthatthe advantageofRank1ElimKLoverKL-UCBandTSwill"kick in"onlyformuchlargervaluesofKandL.
6 RelatedWork
Ouralgorithmisbasedon Rank1Elimof Katariyaet al.[2017].ThemaindifferenceisthatwereplacetheconfidenceintervalsofRank1Elim,whicharebasedonsubgaussiantailinequalities,withconfidenceintervalsbasedonKL divergences.Asdiscussedbeforehand,thisresultsinanunilateralimprovementoftheirregretbound. Thenewalgorithmisstillabletoexploittheproblemstructureofbenign instances,whileitsregretiscontrolledonprobleminstances thatare"hard"forRank1Elim.Asdemonstratedintheprevioussection,thenewalgorithmisalsoa majorpractical improvementoverRank1Elim,whileitremainscompetitive withalternativesonhardinstances.
Severalotherpapersstudiedbanditswherethepayoffis givenbyalowrankmatrix. Zhaoetal.[2013]proposed abanditalgorithmforlow-rank matrixcompletion, which approximatestheposterioroverlatentitemfeaturesbya singlepoint. Theauthorsdonotanalyzethisalgorithm. Kawaleetal.[2015]proposedabanditalgorithmforlowrankmatrixcompletionusingThompsonsamplingwithRaoBlackwellization.Theyanalyzeavariantoftheiralgorithm whosen-stepregretforrank-1matricesisO((1/∆ 2 )logn). Thisissuboptimalcomparedtoouralgorithm. Maillardet al.[2014]studiedabanditproblemwherethearmsarepartitionedintolatentgroups.Inthiswork,wedonotmakeany suchassumptions,butourresultsarelimitedtorank1.Gentileetal.[2014]proposedanalgorithmthatclustersusers basedontheirpreferences,undertheassumptionthatthefeaturesofitemsareknown.Senetal.[2017]proposedanalgorithmforcontextualbanditswithlatentconfounders,which reducestoamulti-armedbanditproblemwherethereward matrixislow-rank. TheyuseanNMF-basedapproachand requirethattherewardmatrixobeysavariantoftherestricted isometryproperty. Wemakenosuchassumptions.Also,our learningagentcontrolsboththerowandcolumnwhileinthe abovepapers,therowsarecontrolledbytheenvironment.
Rank1ElimKLismotivatedbythestructureofthePBM [Richardsonetal.,2007]. Lagreeetal.[2016]proposed abanditalgorithmforthismodelbuttheyassumethatthe examinationprobabilitiesareknown.Rank1ElimKLcanbe usedtosolvethisproblemwithoutthisassumption.Thecascademodel[Craswelletal.,2008]isanalternativewayofexplainingthepositionbiasinclickdata[Chuklinetal.,2015]. Banditalgorithmsforthisclassof modelshavebeenproposedinseveralrecentpapers[Kvetonetal.,2015a;Combes etal.,2015;Kvetonetal.,2015b;Katariyaetal.,2016; Zongetal.,2016;Lietal.,2016].
7 Conclusions
Inthiswork,weproposedRank1ElimKL,aneliminationalgorithmthatusesKL-UCBconfidenceintervalstofindthe maximumentryofastochasticrank-1matrixwithBernoulli rewards. ThealgorithmisamodificationofRank1Elim [Katariyaetal.,2017],wherethesubgaussianconfidenceintervalsarereplacedbytheoneswithKLdivergences.Aswe demonstratebothempiricallyandanalytically,thischangeresultsinasignificantimprovement.Asaresult,weobtainthe firstalgorithmthatisabletoexploittherank-1structurewithoutpayingasignificantpenaltyoninstanceswheretherank-1 structurecannotbeexploited.
Wenotethat Rank1ElimKLusestherank-1structureof theproblemandthattherearenoguaranteesbeyondrank1. WhilethedependenceoftheregretofRank1ElimKLon∆ isknowntobetight[Katariyaetal.,2017],thequestionabout theoptimaldependenceonµisstillopen.Finally,wepoint outthatTSandKL-UCBperformbetterthanRank1ElimKL inourexperiments,especiallyforsmallLandK.ThisisbecauseRank1ElimKLisaneliminationalgorithm.Elimination algorithmstendtohavehigherregretinitiallythanUCB-style algorithmsbecausetheyexploremoreaggressively.Itisnot inconceivabletohaveTSalgorithmsthatleveragetherank-1 structureinthefuture.
@inproceedings{ijcai2017p278,
  title     = {Bernoulli Rank-1 Bandits for Click Feedback},
  author    = {Katariya, Sumeet and Kveton, Branislav and Szepesvári, Csaba and Vernade, Claire and Wen, Zheng},
  booktitle = {Proceedings of the Twenty-Sixth International Joint Conference on
               Artificial Intelligence, {IJCAI-17}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Carles Sierra},
  pages     = {2001--2007},
  year      = {2017},
  month     = {8},
  note      = {Main track},
  doi       = {10.24963/ijcai.2017/278},
  url       = {https://doi.org/10.24963/ijcai.2017/278},
}
TY - CPAPER TI - Bernoulli Rank-1 Bandits for Click Feedback AU - Katariya, Sumeet AU - Kveton, Branislav AU - Szepesvári, Csaba AU - Vernade, Claire AU - Wen, Zheng T2 - Proceedings of the Twenty-Sixth International Joint Conference on Artificial Intelligence, IJCAI-17 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2017 SP - 2001 EP - 2007 DO - 10.24963/ijcai.2017/278 UR - https://doi.org/10.24963/ijcai.2017/278 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





