
Learning a Ground Truth Ranking Using Noisy Approval Votes
Proceedings of the Twenty-Sixth International Joint Conference on Artificial Intelligence. Main track. Pages 149-155.
https://doi.org/10.24963/ijcai.2017/22
Keywords
- Agent-based and Multi-agent Systems: Social Choice Theory
- Agent-based and Multi-agent Systems: Economic paradigms, auctions and market-based systems
Abstract
We consider a voting scenario where agents have opinions that are estimates of an underlying common ground truth ranking of the available alternatives, and each agent is asked to approve a set with her most preferred alternatives. We assume that estimates are implicitly formed using the well-known Mallows model for generating random rankings. We show that k-approval voting --- where all agents are asked to approve the same number k of alternatives and the outcome is obtained by sorting the alternatives in terms of their number of approvals --- has exponential sample complexity for all values of k. This negative result suggests that an exponential (in terms of the number of alternatives m) number of agents is always necessary in order to recover the ground truth ranking with high probability. In contrast, by just asking each agent to approve a random number of alternatives, the sample complexity improves dramatically: it now depends only polynomially on m. Our results may have implications on the effectiveness of crowdsourcing applications that ask workers to provide their input by approving sets of available alternatives.
- Arrow, 1953
- Kenneth J. Arrow. Social Choice and Individ- ual Values. Cowles Foundation, 1953.
- [Brams and Fishburn, 2007] Steven J. Brams and Peter C. Fishburn. Approval Voting. Springer, 2007.
- [Braverman and Mossel, 2008] Mark Braverman and Elchanan Mossel. Noisy sorting without resampling. In Proceedings of the 19th Annual ACM-SIAM Symposium on Discrete Algorithms (SODA), pages 268-276, 2008.
- [Caragiannis et al., 2016] Ioannis Caragiannis, Ariel D. Pro- caccia, and Nisarg Shah. When do noisy votes reveal the truth? ACM Transactions on Economics and Computation, 4(3):15, 2016.
- [Caragiannis et al., 2017] Ioannis Caragiannis, Xenophon Chatzigeorgiou, George A. Krimpas, and Alexandros A. Voudouris. Optimizing positional scoring rules for rank aggregation. In Proceedings of the 31st AAAI Conference on Artificial Intelligence (AAAI), 2017.
- [Chierichetti and Kleinberg, 2014] Flavio Chierichetti and Jon M. Kleinberg. Voting with limited information and many alternatives. SIAM Journal on Computing, 43(5):1615-1653, 2014.
- [Chierichetti et al., 2014] Flavio Chierichetti, Anirban Das- gupta, Ravi Kumar, and Silvio Lattanzi. On reconstruct- ing a hidden permutation. In Approximation, Random- ization, and Combinatorial Optimization. Algorithms and Techniques, APPROX/RANDOM, pages 604-617, 2014.
- [Conitzer and Sandholm, 2005] Vincent Conitzer and Tuo- mas Sandholm. Common voting rules as maximum like- lihood estimators. In Proceedings of the 21st Conference on Uncertainty in Artificial Intelligence (UAI), pages 145- 152, 2005.
- [Critchlow et al., 1991] Douglas E. Critchlow, Michael A. Fligner, and Joseph S. Verducci. Probability mod- els on rankings. Journal of Mathematical Psychology, 35(3):294-318, 1991.
- [de Weerdt et al., 2016] Mathijs M. de Weerdt, Emrico H. Gerding, and Sebastian Stein. Minimising the rank ag- gregation error. In Proceedings of the 2016 International Conference on Autonomous Agents & Multiagent Systems, pages 1375-1376, 2016.
- [Dey and Bhattacharyya, 2015] Palash Dey and Arnab Bhat- tacharyya. Sample complexity for winner prediction in elections. In Proceedings of the 14th International Confer- ence on Autonomous Agents and Multiagent Systems (AA- MAS), pages 1421-1430, 2015.
- [Doignon et al., 2004] Jean-Paul Doignon, Aleksandar Pakeč, and Michel Regenwetter. The repeated insertion model for rankings: Missing link between two subset choice models. Psychometrika, 69(1):33-54, 2004.
- [Fligner and Verducci, 1988] Michael A. Fligner and Joseph S. Verducci. Multi-stage ranking models. Journal of the American Statistical Association, 83:892-901, 1988.
- [Gibbard, 1973] Allan Gibbard. Manipulation of voting schemes: A general result. Econometrica, 41:587-601, 1973.
- [Hoeffding, 1963] Wassily Hoeffding. Probability inequali- ties for sums of bounded random variables. Journal of the American Statistical Association, 58(301):13-30, 1963.
- [Laslier and Sanver, 2010] Jean-Francois Laslier and M. Remzi Sanver, editors. Handbook on Approval Voting. Springer, 2010.
- [Lebanon and Lafferty, 2002] Guy Lebanon and John Laf- ferty. Cranking: Combining rankings using conditional probability models on permutations. In Proceedings of the 19nd International Conference on Machine Learning (ICML), pages 363-370, 2002.
- [Lee et al., 2014] Jeehyung Lee, Wipapat Kladwang, Min- jae Lee, Daniel Cantu, Martin Azizyan, Hanjoo Kim, Alex Limpaecher, Snehal Gaikwad, Sungroh Yoon, Adrien Treuille, Rhiju Das, and EteRNA participants. RNA de- sign rules from a massive open laboratory. Proceedings of the National Academy of Sciences, 111(6):2122-2127, 2014.
- [Lu and Boutilier, 2014] Tyler Lu and Craig Boutilier. Ef- fective sampling and learning for Mallows models with pairwise-preference data. Journal of Machine Learning Research, 15:3963-4009, 2014.
- [Mallows, 1957] C. L. Mallows. Non-null ranking models. Biometrika, 44:114-130, 1957.
- [Mitzenmacher and Upfal, 2005] Michael Mitzenmacher and Eli Upfal. Probability and Computing -Randomized Algorithms and Probabilistic Analysis. Cambridge University Press, 2005.
- [Procaccia and Shah, 2015] Ariel D. Procaccia and Nisarg Shah. Is approval voting optimal given approval votes? In Advances in Neural Information Processing Systems 28: Annual Conference on Neural Information Processing Sys- tems, pages 1801-1809, 2015.
- [Rubinstein and Vardi, 2017] Aviad Rubinstein and Shai Vardi. Sorting from noisier samples. In Proceedings of the 28th Annual ACM-SIAM Symposium on Discrete Al- gorithms (SODA), pages 960-972, 2017.
- [Satterthwaite, 1975] Mark A. Satterthwaite. Strategy proof- ness and Arrow's conditions: Existence and correspon- dence theorems for voting procedures and social welfare functions. Journal of Economic Theory, 10:187-217, 1975.
- [Shah et al., 2015] Nihar B. Shah, Dengyong Zhou, and Yu- val Peres. Approval voting and incentives in crowdsourc- ing. In Proceedings of the 32nd International Conference on Machine Learning (ICML), pages 10-19, 2015.
- [Young, 1988] H. Peyton Young. Condorcet's theory of vot- ing. American Political Science Review, 82(4):1231-1244, 1988.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
How should preferences of different individuals be aggregated into a collective decision? This is the central question that social choice theory aims to answer. In a well-known model, there is a set of available alternatives and each individual preference is expressed as a ranking over these alternatives. Given such a profile of preferences, a voting rule outputs either a winning alternative or a ranking of all the alternatives as a collective decision.
Social choice theory has extensively studied the different voting rules that can be defined, following two main approaches. The first one, which is the most common, is axiomatic. It assumes that voting rules should satisfy some desirable social choice axioms and aims to characterize voting rules in terms of the axioms they satisfy. Well-known impossibility results - e.g. the results by Arrow [1953], Gibbard [1973], and Satterthwaite [1975] - indicate the challenges of this approach. The second approach assumes that there is
Evi Micha
University of Patras michap@ceid.upatras.gr
a ground truth (i.e., an underlying objective ranking over the alternatives) and views votes as noisy estimates of the ground truth. Then, a voting rule is better than another if it is more likely to output the ground truth; the best such rule is a maximum likelihood estimator (MLE) of the ground truth.
Even though it originates from Marquis de Condorcet - the founder of social choice theory - more than two centuries ago, the MLE approach became popular only very recently, due to the work of Young [1988], Conitzer and Sandholm [2005], and others. Interestingly, Marquis de Condorcet proposed a very simple process as a model of the mental process with which voters decide their individual rankings: each voter decides the relative ranks of every pair of alternatives a and b correctly (i.e., consistently to the relative ranks of a and b in the ground truth) with probability p and incorrectly with probability 1-p. The process is repeated until these decisions define a ranking. This model was rediscovered by Mallows [1957] and today is known as the Mallows noise model.
When voting rules are viewed as estimators of a ground truth, an important measure of their effectiveness is their sample complexity. How many votes do we need in a profile so that the application of a voting rule recovers the ground truth with high probability? Caragiannis et al. [2016] proved that maximum likelihood estimators are the voting rules that have optimal sample complexity and presented positive and negative sample complexity results for Mallows. See also [Braverman and Mossel, 2008; Chierichetti et al., 2014; Rubinstein and Vardi, 2017] for results of similar flavour in slightly different (non-voting) contexts. Chierichetti and Kleinberg [2014] and Dey and Battacharyya [2015] present sample complexity results for voting rules that return a winning alternatives (instead of a complete ranking, which is our main focus here).
In this paper, we study the sample complexity of approval voting on profiles that are generated using the Mallows noise model. Approval voting is simultaneously a simplified format of voters' preferences and a voting rule. With an approval vote, a voter just approves some of the alternatives (and disapproves the rest). The approval voting rule takes a profile with approval votes as input, ranks the alternatives in monotone non-increasing order in terms of their number of approvals, and returns this ranking as output. Besides its simplicity, approval voting has many interesting properties; the books by Brams and Fishburn [2007] and Laslier and Sanver [2010] are devoted to its study. It also seems to be ideal for several crowdsourcing tasks, as it provides a very simple interface through which workers can provide their input; see [Shah et al., 2015; Lee et al., 2014]. A concrete scenario could be the evaluation of alternative projects that a local government considers for implementation. Adapting the recent trend of participatory democracy, the local government can ask a "crowd" of citizens to approve a given number of preferred projects each, in order to come up with an ordering of them in terms of their approval score.
Here, our assumptions are that there is a ground truth ranking and each voter uses the Mallows model to form an internal opinion (i.e., a ranking) over the alternatives. Then, her approval vote consists of the top alternatives in her internal opinion. What is the sample complexity of approval voting in this setting? In other words, how many noisy approval votes do we need in order to recover (learn) the ground truth ranking with high probability?
As Procaccia and Shah [2015] show, approval voting is the maximum likelihood estimator for approval votes that have been produced using Mallows. Then, by the result of Caragiannis et al. [2016] mentioned above, we can conclude - after some adaptation of their proof - that approval voting has optimal sample complexity in the setting we consider. Is this a positive result? Not necessarily, as we will show in Section 3. In particular, we first consider profiles with approval votes that consist of k alternatives. We show that approval voting has exponential sample complexity for all possible values of k. This result extends a negative result from [Caragiannis et al., 2016] for plurality. Is that all we can hope for with approval votes? Surprisingly, as we show in Section 4, in profiles where each voter approves a random number of alternatives, approval voting has only polynomial sample complexity. We use the term randomized approval voting to refer to this voting rule.
We have also conducted experiments with randomized approval (and with a deterministic variant of it) that verify our positive theoretical result; these are also presented in Section 4 together with a discussion on possible extensions of our proof. Actually, the Mallows sample complexity is experimentally observed to be even better than our theoretical bound. We conclude in Section 5, with a short discussion on open problems and an interesting (and somewhat surprising) observation about an alternative definition of the model of building Mallows approval votes.
2 Preliminaries
We begin with preliminary definitions. We consider settings with n voters (or agents) and m alternatives. We denote by A = {a1, a2, ..., am} the set of alternatives and by N = {1, ..., n} the set of agents. We use L(A) to denote the set of rankings of the alternatives in A. For a ranking σ ∈ L(A), we denote by σ(a) the rank (or position, taking values between 1 to m) of alternative a ∈ A in σ.
An approval vote is the set of alternatives approved by an agent; we use Aℓ to denote the approval vote of agent ℓ. A kapproval vote has exactly k alternatives. We consider voting profiles in which each agent submits an approval vote. A voting profile is a collection of approval votes of the agents, i.e., {Aℓ|ℓ ∈ N}. The approval score of an alternative a ∈ A in a profile is simply the number of its appearances in approval votes, i.e., |{ℓ ∈ N|a ∈ Aℓ}|.
The well-known approval voting rule computes a final ranking by sorting the alternatives in monotone nonincreasing order in terms of their approval score. Ties (i.e., deciding the ranks of alternatives that have equal approval scores) can be broken either randomly or deterministically. The approval voting rule can be applied to profiles in which agents have approval votes of different sizes or to profiles in which all agents' preferences are restricted to k-approval votes for some fixed k. As a convention, approval votes are always non-empty and exclude at least one alternative.
We assume that there is an unknown ground truth ranking σ∗ ∈ L(A) of the alternatives. Each agent ℓ ∈ N has an opinion πℓ ∈ L(A), which is a noisy estimate of σ∗ . The noisy estimate of agent ℓ is computed using a noise model that takes as input the ground truth ranking σ∗ and returns a random ranking σ ∈ L(A) with a probability that depends on σ and σ∗ . So, when agent ℓ is asked to submit a k-approval vote, it returns the first k alternatives in πℓ; we use topk to denote the k top alternatives in ranking σ.
We assume that the agents decide their opinions by (implicitly) applying the Mallows noise model. This model uses a noise parameter p ∈ [1/2, 1] (or, equivalently, noise parameter φ = 1-p p ) and produces the (random) ranking σ by deciding the relation of each pair of alternatives separately: for alternatives a and b from A with σ∗ (a) < σ∗ (b), it is decided that a beats b (i.e., a ≻ b) with probability p and that b ≻ a with probability 1 - p. This is continued for each pair of alternatives; this process defines a round. If the relation ≻ induces a ranking, the round is successful and this ranking is the noisy estimate returned by the Mallows process; otherwise, the whole process is repeated from scratch (with a new round that uses new randomness). We denote by Mallows(φ, σ∗ ) the random ranking returned by the Mallows process with noise parameter φ and ground truth σ∗ .
It is well-known - e.g., see [Caragiannis et al., 2016] - that the Mallows probabilities are defined as
where d(σ1, σ2) is the Kendall-tau distance between rankings σ1 and σ2 defined as the number of pairwise relations between alternatives that differ in σ1 and σ2, i.e.,
3 The Mallows Sample Complexity of k-Approval Voting
We begin with a negative result for k-approval voting, extending a negative result of Caragiannis et al. [2016] for plurality. Namely, we will show that, for all values of k, k-approval voting has exponential sample complexity for almost all values of noise parameters (Theorem 1).
Let us give some intuition for the result, for the two extreme values of the noise parameter. As the noise parameter approaches 1/2, the votes are selected almost uniformly at random from L(A). Then, it should be clear that a huge number of votes is required in order to detect any bias towards the ground truth. In contrast, when the votes have no noise at all, all agents submit the same set of alternatives and there is no way to recover the ground truth ranking.
We begin with the following technical lemma; note that the assumption about σ∗ is without loss of generality.
Lemma 1. Let σ∗ be a ground truth ranking that has alternatives ai ranked i-th and let S = topk (Mallows(φ, σ∗ )) be a k-approval set that is produced using Mallows with noise parameter φ. Then,
Proof. Due to lack of space, we prove only (1) here. First, observe that a round of the Mallows process is successful if the pairwise relations among the alternatives in A \ {am-1, am} induce a (partial) ranking σ and there are different integers i, j ∈ [m] so that the pairwise relations involving alternatives am-1 and am are as follows:
- either 1 ≤ i < j ≤ m and alternative am-1 is beaten by the top i-1 alternatives in σ, beats the rest including am, and alternative am is beaten by the top j -2 alternatives in σ (and by am-1) and beats the rest,
- or 1 ≤ j < i ≤ m and alternative am-1 is beaten by the top i - 2 alternatives in σ and by alternative am, beats the rest, and alternative am is beaten by the top j - 1 alternatives in σ and beats the rest including am-1.
In both cases, the integers i and j denote the ranks of am-1 and am in the ranking produced.
So, assuming that the round of the Mallows process has decided the pairwise relations among the alternatives in A \ {am-1, am} so that they induce a partial ranking σ, the probability that the remaining pairwise relations that involve am-1 and am are decided so that a full ranking is produced with alternatives am-1 and am ranked i-th and jth, respectively, is pi+j-2 (1 - p)2m-i-j-1 if i < j and pi+j-3 (1 - p)2m-i-j if i > j. To see why, observe that the probability that alternative am-1 (or am) is decided to be beaten by any of m- 2 alternatives in σ is p while the probability that am-1 is decided to beat am is p as well. Clearly, these probabilities do not depend on the ranking σ.
Hence, the probability that a round of the Mallows process, that has decided the pairwise relations among the alternatives in A \ {am-1, am} so that they induce a partial ranking, decides the remaining pairwise relations that involve am-1 and am so that a full ranking is induced and neither am-1 nor am occupies some of the t top position (i.e., i, j ≥ t + 1) is
The first (respectively, the second) sum in the first equality above runs over all pairs of positions i, j such that t + 1 ≤ i < j ≤ m (respectively, t + 1 ≤ j < i ≤ m) and sums up the probabilities that alternatives am-1 and am occupy these positions at the end of the round. The parameter t can take any value from 0 to m - 2.
In order to simplify notation, set λ = p 1-p (i.e., λ = 1/φ) and define f(t) = ∑m-1 i=t+1 ∑mj=i+1 λi+j for any nonnegative integer t. Then, (3) becomes
By simple calculations, we have
Using (4) and (5), we have that the probability that the Mallows process returns a ranking with some alternative among am-1 and am in the top k positions is equal to
The two inequalities follow since λ ≥ 1 and k ≤ m-1. This completes the proof of inequality (1).
In order to distinguish between two alternatives and learn their relative positions in the ground truth ranking using approval voting, we need at least one approval vote in which the one alternative is approved and the other is not. Therefore, the useful (for our purposes) information in the statement of Lemma 1 is that the probability that a Mallows k-approval vote can distinguish between the top two (if k is large) or the bottom two (if k is small) alternatives in the ground truth ranking σ∗ is exponentially small. Then, it follows that an exponential number of Mallows approval votes is necessary just in order to distinguish between the top or the bottom two alternatives of σ∗ .
Theorem 1. For every integer k ∈ [m- 1] and ϵ ∈ [0, 1/4], at least Ω(φ-m/2 ) Mallows k-approval votes are necessary in order to obtain the ground truth ranking among m alternatives with probability at least 1 - ϵ.
Proof. Assuming that the number of agents is strictly smaller than 14 φ1-m/2 , we will show that the probability that we can correctly decide the position of two particular alternatives in the ground truth ranking is less that 3/4 ≤ 1 - ϵ. We distinguish between two cases:
When k ≤ m/2, using inequality (1) from Lemma 1 and the union bound, we have that the probability that some kapproval set in the profile contains either alternative am-1 or alternative am (or both) is less than 14 φ1-m/2 × 2φm-1-k ≤ 1/2; the inequality follows since k ≤ m/2. Hence, the probability that am-1 gets strictly more approvals than am or their tie is resolved in favour of am-1 is less than 3/4.
For k > m/2, we use inequality (2) from Lemma 1 and the union bound to obtain that the probability that some kapproval set in the profile does not contain alternatives a1 and a2 is less than 14 φ1-m/2 × 2φk-1 ≤ 1/2 as well. So, we obtain that the probability that a1 gets strictly more approvals than a2 or their tie is resolved in favour of a1 is less than 3/4.
Hence, in order to get the ground truth with probability at least 1- ϵ, at least 14 φ1-m/2 agents are necessary.
4 Randomized Approval Voting Has Only Polynomial Mallows Sample Complexity
The negative result in Section 3 is certainly disappointing. Still, there is a surprisingly simple way to recover the ground truth using only polynomially many Mallows approval votes. The main idea is to ask agents to approve different numbers of alternatives. In particular, let us define the randomized approval voting rule, which, for every agent, picks an integer r uniformly at random from [m- 1] and asks the agent to approve r alternatives. Then, it ranks the alternatives in decreasing order of approvals, breaking ties uniformly at random.
Before proving our sample complexity bound for randomized approval, we give some intuition. Let us identify the agents that are asked to approve r alternatives as the ones belonging to the r-th group. Now observe that if we have sufficiently many (say, Θ(m2 )) agents in total, then, almost surely, all the m- 1 possible groups of agents will be non-empty. If there is no noise at all, each agent in the r-th group will correctly approve the top r alternatives in the ground truth ranking and, as we have agent groups and sets of approved alternatives of all possible sizes, sorting the alternatives in terms of their number of approvals will reveal the ground truth.
This intuition is valid in the presence of noise as well. If we have sufficiently many agents in the first group, they will most probably give the highest approval score to the top alternative in the ground truth. Similarly, a sufficiently large number of agents in the second group will distinguish the two top alternatives in the ground truth. Combined with the information from the first group of agents, we will have the correct ranking for the two top alternatives. The intuition proceeds this way and indicates that, most probably, the whole information that is needed in order to recover the ground truth ranking is in the approved sets of alternatives.
We are now ready to formally prove our positive result. An interesting feature in the statement of Theorem 2 is that it involves agents with different noise levels.
Theorem 2. For every ϵ > 0, when the Mallows agents have possibly different noise parameters with average value p∗ = 1n ∑ℓ∈N pℓ and their number is
randomized approval returns the ground truth ranking of m alternatives with probability at least 1 - ϵ.
Proof. Without loss of generality, we assume that the ground truth ranking σ∗ has alternative ai of A at position i. For alternative ai ∈ A, let qi be the random variable that denotes the number of approvals ai gets from all agents under the randomized approval voting rule. We will show that the probability that qi ≤ qi+1 for some i ∈ [m-1] is very small, proving the theorem.
Let ℓ ∈ N be an agent and define Dℓ depending on whether ℓ approves alternatives ai and ai+1 as follows:
Hence,
We would like to show that Pr[qi - qi+1 ≤ 0] ≤ ϵ/m. The theorem will then follow by summing over all i ∈ [m- 1].
Observe that the quantity qi - qi+1 is the sum of n independent random variables, one per agent, taking values in {-1, 0, 1}. We will use the following well-known inequality:
Lemma 2. [Hoeffding, 1963] Let X1,X2, ...,Xt be independent random variables so that Pr[aj ≤ Xj ≤ bj] = 1 for j ∈ [t]. Then, the expectation of the random variable X = ∑tj=1 Xj is E[X] = ∑tj=1 E[Xj] and, futhermore, for every ν ≥ 0,
We apply Lemma 2 to the random variable qi - qi+1 = ∑nℓ=1 Dℓ with ν = E[qi - qi+1]. Observe that t = n, and aℓ = -1, bℓ = 1 for ℓ ∈ [n]. Hence, we have
It remains to bound E[Dℓ] from below. Let ℓ ∈ N be any agent. By the definition of Dℓ, we have that
Clearly, the event Dℓ = 1 happens when the Mallows process returns a ranking σ in which alternative ai has better rank than ai+1. Then, alternative ai is approved and alternative ai+1 is not approved when agent ℓ is asked to approve the r top alternatives with r lying between σ(ai) (the rank of ai in σ) and σ(ai+1) -1. Since r is selected uniformly at random, we have that the probability that r lies in this particular range is σ(ai+1)-σ(ai) m-1 .
Similarly, the event Dℓ = -1 happens when the Mallows process returns a ranking σ in which alternative ai has worse rank than ai+1. Then, alternative ai+1 is approved and alternative ai is not approved when agent ℓ is asked to approve the r top alternatives with r lying between σ(ai+1) and σ(ai) - 1. The probability that r lies in this particular range is σ(ai)-σ(ai+1) m-1 .
Denote by ˜σ the ranking obtained by swapping alternatives ai and ai+1 in σ and abbreviate Pr[Mallows(φℓ, σ∗ ) = σ] by Pr[σ]. By the discussion above, (8) yields
The first two equalities follow by the discussion above while the inequality uses the trivial fact that σ(ai+1) - σ(ai) ≥ 1 when alternative ai is ranked higher than ai+1 in σ. We need to justify the property Pr[˜σ] = φℓ · Pr[σ] which is used to obtain the third equality in the derivation above. This follows by the definition of the Mallows probabilities by observing that d(˜σ, σ∗ ) = d(σ, σ∗ ) + 1. To see why, recall the definition of the Kendall-tau distance from Section 2 and notice that every pair of alternatives aj and aj ′ with j, j ′ different than i and i+1 have the same contribution to the quantities d(˜σ, σ∗ ) and d(σ, σ∗ ). Also, for j different than i and i+1, the contribution of the pair of alternatives ai and aj to d(˜σ, σ∗ ) (respectively, to d(σ, σ∗ )) is equal to the contribution of the pair of alternatives ai+1 and aj to d(σ, σ∗ ) (respectively, to d(˜σ, σ∗ )). It remains to consider the contribution of the pair of alternatives ai and ai+1. Clearly, this contributes (one) to d(˜σ, σ∗ ) but not to d(σ, σ∗ ).
Using again the fact Pr[˜σ] = φℓ · Pr[σ], we also have
and (9) now yields
and, hence,
Using (7) and the bound on the number of agents n, we get
An advantage of randomization is that it guarantees that the r-th group of agents will have size very close to n/(m- 1) for every possible value of r in [m- 1]. 1 Alternatively, this can be enforced deterministically, e.g., in a round-robin fashion; in this way, each group of agents will have size equal to either ⌈n/(m- 1)⌉ or ⌊n/(m- 1)⌋ for all values of k. Let us call this variant balanced approval voting. We do not see how the proof of Theorem 2 can be adapted to work in this case since our proof exploits the fact that a Mallows agent is asked to approve a random number of alternatives in order to avoid a detailed reasoning about the outcome of the Mallows distribution. Still, we strongly believe that balanced approval has polynomial sample complexity at least in the scenario of agents with identical Mallows parameters. Experimental results that are presented below fully justify this belief.
On the other hand, if agents have very different Mallows parameters, the bound of Theorem 2 should not be expected to hold for balanced approval voting. Indeed, it might happen that low-noise agents are the ones that are asked to approve either very few or too many alternatives. Then, all such an agent can do is to contribute towards distinguishing between the few alternatives at the top or the few alternatives in the bottom. At the same time, the agents who are asked to contribute the most (i.e., the ones who are asked to approve, say, half of the alternatives) might happen to be the high-noise ones. A possible solution for avoiding this correlation would be to keep the balancedness restriction but partition the agents into different groups randomly. Then, a statement similar to the one in Theorem 1 certainly holds but its proof would be more complicated, making use of martingale arguments (Azuma instead of Hoeffding bound; see e.g., the classical textbook on probabilistic analysis by Mitzenmacher and Upfal [2005]) in order to handle subtle dependencies between the random variables involved due to the balancedness restriction.
We conclude this section by presenting experimental results with randomized and balanced approval voting on 50 alternatives. We have used profiles with homogeneous Mallows agents with three different parameter values, namely p = 0.95, 0.75, and 0.6. The results are depicted in Figure 1
1 Our intuition suggests that uniform selection of the number of alternatives to be approved is best possible. We do not have a formal proof of this though.
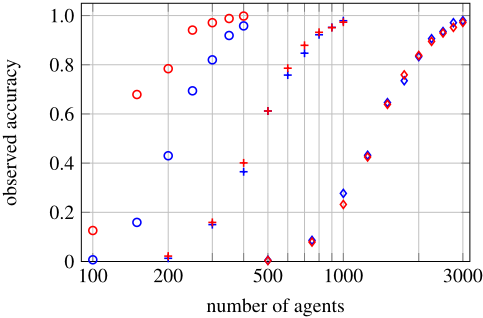
and show a threshold phenomenon: as the number of agents increases in a short range of values, the accuracy jumps very steeply from 0 to almost 1. The results indicate that randomized approval is considerably better in practice compared to our theoretical bound. For example, in order to achieve accuracy of 90%, profiles with 250, 800, and 2250 agents with Mallows parameters 0.95, 0.75, and 0.6, respectively, are sufficient. The theoretical bounds are approximately 37000, 120000, and 750000. Balanced approval voting is considerably more accurate for high values of the Mallows parameter (p = 0.95). This is due to the fact that the profiles considered in this scenario have very few agents compared to the number of alternatives and, in contrast to balanced approval, randomized approval leaves many agents groups empty. This advantage vanishes and there is essentially no statistical difference between the accuracy of balanced and randomized approval for higher noise levels (lower values of p).
5 Discussion
Let us attempt to define a seemingly different model that is inspired by Mallows but instead builds k-approval votes directly. In particular, consider the alternative random process altMallowsk(φ, σ∗ ) which takes as input the ground truth ranking σ∗ among the m alternatives in A and the noise parameter φ (and, consequently, p = 1 φ+1 ) and works as follows. Like Mallows, it first decides the relation ≻ between every pair of alternatives separately: for every pair of alternatives a and b with σ∗ (a) < σ∗ (b), it is decided that a ≻ b with probability p and b ≻ a with probability 1 - p. Now, if there is a set of k alternatives S so that each of them beats (according to ≻) all alternatives in A\S, the current round is successful and the set S is returned. If no such set exists, the whole process is repeated from scratch with a new round.
Interestingly, this turns out to be equivalent to the model for building Mallows approval votes that we have used throughout the paper. We will present the formal statement shortly (omitting the proof, due to lack of space). Before doing so, let us define the quantity
for a non-empty set of alternatives S ⊆ A of size at most m- 1. In a sense, δ(S, σ∗ ) is a "distance function" between a set of approved alternatives S and the ground truth ranking σ∗ . For example, δ(S, σ∗ ) is equal to 0 if S consists of the top alternatives in σ∗ while it takes its maximum value when S consists of alternatives at the bottom of σ∗ .
Theorem 3. Given a ground truth ranking σ∗ of the alternatives in A, noise parameter φ, and integer k ∈ [m- 1], the processes altMallowsk(φ, σ∗ ) and topk (Mallows(φ, σ∗ )) return random subsets of A of size k according to the same probability distribution. In particular, the probability that the k-sized set S ⊆ A is returned is proportional to φδ(S,σ∗ ) .
We believe that this alternative view of Mallows approval votes could be useful in future theoretical investigations. Furthermore, it can be used for the implementation of the Mallows approval noise model without building a Mallows ranking first. Compared to the naive implementation of Mallows that mimics its definition (of deciding the pairwise relations between alternatives independently in rounds until these relations induce a ranking), the alternative implementation is clearly faster since it is less restrictive. Actually, it is considerably faster than several implementations in the literature such as the "multistage ranking method" of Fligner and Verducci [1988]. But Mallows has an extremely fast implementation using the "repeated insertion method" of Doignon et al. [2004] (see also [Lu and Boutilier, 2014]). In our experiments, we have used this implementation and obtain the approval votes after building Mallows rankings first. Whether the alternative process can yield an even improved implementation is an interesting open problem.
Besides Mallows, there are many other important noise models over rankings that can be combined with approval voting, e.g., see [Critchlow et al., 1991; Lebanon and Lafferty, 2002; Lu and Boutilier, 2014]. What is the sample complexity of randomized approval voting when such models are used to form the internal agent opinions? Another direction for future research is to replace the requirement to learn the ground truth with high probability with the requirement to recover it approximately. This objective has been studied very recently in slightly different contexts in [de Weerdt et al., 2016] and [Caragiannis et al., 2017]. Adapting the terminology in these papers to our case, the accuracy parameter 1 - ϵ would refer to the expected fraction of pairwise relations of the ground truth ranking that are recovered correctly when applying approval voting. Finally, regardless of whether the objective is to learn the ground truth exactly or approximately, experimentation with real-world data could shed more light on the suitability of (randomized) approval voting in crowdsourcing environments.
@inproceedings{ijcai2017p22,
  title     = {Learning a Ground Truth Ranking Using Noisy Approval Votes},
  author    = {Caragiannis, Ioannis and Micha, Evi},
  booktitle = {Proceedings of the Twenty-Sixth International Joint Conference on
               Artificial Intelligence, {IJCAI-17}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Carles Sierra},
  pages     = {149--155},
  year      = {2017},
  month     = {8},
  note      = {Main track},
  doi       = {10.24963/ijcai.2017/22},
  url       = {https://doi.org/10.24963/ijcai.2017/22},
}
TY - CPAPER TI - Learning a Ground Truth Ranking Using Noisy Approval Votes AU - Caragiannis, Ioannis AU - Micha, Evi T2 - Proceedings of the Twenty-Sixth International Joint Conference on Artificial Intelligence, IJCAI-17 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2017 SP - 149 EP - 155 DO - 10.24963/ijcai.2017/22 UR - https://doi.org/10.24963/ijcai.2017/22 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





