
Hidden Parameter Markov Decision Processes: A Semiparametric Regression Approach for Discovering Latent Task Parametrizations
Proceedings of the Twenty-Fifth International Joint Conference on Artificial Intelligence. Pages 1432-1439.
© 2016 International Joint Conferences on Artificial Intelligence
Abstract
Control applications often feature tasks with similar, but not identical, dynamics. We introduce the Hidden Parameter Markov Decision Process (HiP-MDP), a framework that parametrizes a family of related dynamical systems with a low-dimensional set of latent factors, and introduce a semiparametric regression approach for learning its structure from data. We show that a learned HiP-MDP rapidly identifies the dynamics of new task instances in several settings, flexibly adapting to task variation.
- [Álvarez and Lawrence, 2011] M.A. Álvarez and N.D. Lawrence. Computationally efficient convolved multiple output Gaussian processes. Journal of Machine Learning Research, 12:1459-1500, 2011.
- [Ammar et al., 2014] H.B. Ammar, E. Eaton, P. Ruvolo, and M.E. Taylor. Online multi-task learning for policy gradient methods. In Proceedings of the 31st International Confer- ence on Machine Learning, pages 1206-1214, 2014.
- [Ferguson and Mahadevan, 2006] K. Ferguson and S. Ma- hadevan. Proto-transfer learning in Markov decision pro- cesses using spectral methods. In The ICML Workshop on Structural Knowledge Transfer for Machine Learning, June 2006.
- [Fern and Tadepalli, 2010] Alan Fern and Prasad Tadepalli. A computational decision theory for interactive assistants. In Advances in Neural Information Processing Systems 23, pages 577-585, 2010.
- [Ferrante et al., 2008] E. Ferrante, A. Lazaric, and M. Restelli. Transfer of task representation in re- inforcement learning using policy-based proto-value functions. In Autonomous Agents and Multiagent Systems, pages 1329-1332, 2008.
- [Griffiths and Ghahramani, 2011] T.L. Griffiths and Z. Ghahramani. The Indian buffet process: An in- troduction and review. Journal of Machine Learning Research, 12:1185-1224, 2011.
- [Guez et al., 2012] A. Guez, D. Silver, and P. Dayan. Efficient Bayes-adaptive reinforcement learning using sample-based search. In Advances in Neural Information Processing Systems 25, 2012.
- [Kaelbling et al., 1998] L.P. Kaelbling, M.L. Littman, and A.R. Cassandra. Planning and acting in partially observ- able stochastic domains. Artificial Intelligence, 101:99- 134, 1998.
- [Kober et al., 2012] J. Kober, A. Wilhelm, E. Oztop, and J. Peters. Reinforcement learning to adjust parametrized motor primitives to new situations. Autonomous Robots, 33(4):316-379, 2012.
- [Konidaris et al., 2011] G.D. Konidaris, S. Osentoski, and P.S. Thomas. Value function approximation in reinforce- ment learning using the Fourier basis. In Proceedings of the Twenty-Fifth Conference on Artificial Intelligence, pages 380-385, 2011.
- [Kurniawati et al., 2008] H. Kurniawati, D. Hsu, and W.S. Lee. Sarsop: Efficient point-based POMDP planning by approximating optimally reachable belief spaces. In Pro- ceedings of Robotics: Science and Systems, 2008.
- [Lawrence, 2004] N.D. Lawrence. Gaussian process latent variable models for visualisation of high dimensional data. In Advances in Neural Information Processing Systems 16, 2004.
- [Mahmud et al., 2014] M.M.H Mahmud, B. Rosman, S. Ra- mamoorthy, and P. Kohli. Adapting interaction environ- ments to diverse users through online action set selection. In Proceedings of the AAAI 2014 Workshop on Machine Learning for Interactive Systems, 2014.
- [Poupart et al., 2006] P. Poupart, N. Vlassis, J. Hoey, and K. Regan. An analytic solution to discrete Bayesian re- inforcement learning. In Twenty-Third International Con- ference in Machine Learning, pages 697-704, 2006.
- [Randlov and Alstrom, 1998] J. Randlov and P. Alstrom. Learning to Drive a Bicycle Using Reinforcement Learn- ing and Shaping. In Proceedings of the Fifteenth Interna- tional Conference on Machine Learning, pages 463-471, 1998.
- [Rasmussen and Williams, 2005] C.E. Rasmussen and C.K.I Williams. Gaussian Processes for Machine Learning. The MIT Press, 2005.
- [Rosman et al., 2016] B. Rosman, M. Hawasly, and S. Ra- mamoorthy. Bayesian policy reuse. Machine Learning, 2016. To appear.
- [Ross et al., 2008] S. Ross, B. Chaib-draa, and J. Pineau. Bayesian reinforcement learning in continuous POMDPs with application to robot navigation. In The IEEE Inter- national Conference on Robotics and Automation, pages 2845 -2851, 2008.
- [Silver and Veness, 2010] D. Silver and J. Veness. Monte- Carlo planning in large POMDPs. In Advances in Neu- ral Information Processing Systems 23, pages 2164-2172, 2010.
- [Snelson and Ghahramani, 2005] E. Snelson and Z. Ghahra- mani. Sparse Gaussian processes using pseudo-inputs. In Advances in Neural Information Processing Systems 18, 2005.
- [Sutton and Barto, 1998] R.S. Sutton and A.G. Barto. Rein- forcement Learning: An Introduction. MIT Press, Cam- bridge, MA, 1998.
- [Taylor and Stone, 2007] M.E. Taylor and P. Stone. Rep- resentation transfer for reinforcement learning. In AAAI 2007 Fall Symposium on Computational Approaches to Representation Change during Learning and Develop- ment, November 2007.
- [Teh et al., 2005] Y. W. Teh, M. Seeger, and M. I. Jordan. Semiparametric latent factor models. In International Workshop on Artificial Intelligence and Statistics, 2005.
- [Titsias, 2009] M. Titsias. Variational Learning of Inducing Variables in Sparse Gaussian Processes. In Proceedings of The 12th International Conference on Artificial Intelli- gence and Statistics, 2009.
- [Williams and Young, 2005] J. Williams and S. Young. Scal- ing up POMDPs for dialogue management: The "sum- mary POMDP" method. In Proceedings of the IEEE ASRU Workshop, 2005.
- [Wilson et al., 2012a] A. Wilson, A. Fern, and P. Tadepalli. Transfer learning in sequential decision problems: A hier- archical Bayesian approach. Journal of Machine Learning Research -Proceedings Track, 27:217-227, 2012.
- [Wilson et al., 2012b] A.G. Wilson, D.A. Knowles, and Z. Ghahramani. Gaussian process regression networks. In Proceedings of the 29th International Conference on Ma- chine Learning, 2012.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Background
Bayesian Reinforcement Learning The reinforcement learning (RL) setting consists of a series of interactions between an agent and an environment. From some state s, the agent chooses an action a which transitions it to a new state s0 and provides reward r. Its goal is to maximize its expected sum of rewards, E[Pt γ t rt], where γ 2 [0↪ 1) is a discount factor that weighs the relative importance of nearterm and long-term rewards. This series of interactions can be modeled as a Markov Decision Process (MDP), a 5-tuple ¶S↪ A↪ T↪ R↪ γ♦ where S and A are sets of states s and actions a, the transition function T(s0 ♣s↪ a) gives the probability of the next state being s0 after performing action a in state s, and the reward function R(s↪ a) gives the reward r for performing action a in state s. We refer to the transition function T(s0 ♣s↪ a) as the dynamics of a system.
The transition function T or the reward function R must be learned from experience. Bayesian approaches to reinforcement learning [Poupart et al., 2006; Ross et al., 2008; Silver and Veness, 2010] place a prior over the transition function T (and sometimes also R), and refine this prior with experience. Thus, the problem of learning an unknown MDP is transformed into a problem of planning in a known partially-observable Markov Decision Process (POMDP). A POMDP [Kaelbling et al., 1998] consists of a 7-tuple ¶Y↪A↪O↪ ⌧↪⌦↪R↪ γ♦, where Y↪A↪ and O are sets of states y, actions a, and observations o; ⌧(y0 ♣y↪ a) and R(y↪ a) are the transition and reward functions; and the observation function ⌦(o♣y0 ↪ a) is the probability of receiving an observation o when taking action a to state y0 . Bayesian RL learns an MDP by planning in a POMDP with states yt = ¶st↪ T♦: the fully-observed "world-state" st and the hidden dynamics T .
However, despite recet advances [Silver and Veness, 2010; Kurniawati et al., 2008; Guez et al., 2012], solving POMDPs in high-dimensional, continuous state spaces remains challenging. Our approach simplifies the Bayesian RL challenge by using instances of related tasks to find a low-dimensional representation of the transition function T .
Indian Buffet Processes and Gaussian Processes Our specific instantiation of the HiP-MDP uses two models from Bayesian nonparametric statistics. The first is the Indian Buffet Process (IBP). The IBP is a prior on 0-1 matrices M(n↪ k) with a potentially unbounded number of columns k. To generate samples from the prior, we first use a Beta process to assign a probability pk to each column k such that Pk pk is bounded. Then, each entry M(n↪ k) is set to 1 independently with probability pk. We use the IBP as a prior on which latent parameters are relevant for predicting each state transition.
The second model we use is the Gaussian Process (GP). A GP is a prior over continuous functions y = f(x) where the prior probability of outputs ¶y1↪ ▷▷▷↪ yt♦ given a set of inputs ¶x1↪ ▷▷▷↪ xt♦ is a multivariate Gaussian N(m↪ K), where m(xi) is the mean function of the Gaussian process and the covariance matrix has elements K(xi↪ xj) for some positive definite kernel function K. We will use Gaussian processes as priors over the basis functions for our transition functions.
2 Hidden Parameter Markov Decision Processes
We focus on learning the dynamics T and assume that the reward function r = R(s↪ a) is fixed across all instances. Let b denote each instance of a domain. The Hidden Parameter Markov Decision Process (HiP-MDP) posits that the variation in the dynamics of different instances can be captured through a set of hidden parameters ✓b.
A HiP-MDP is described by a tuple: ¶S↪A↪⇥↪ T↪R↪ γ↪ P⇥♦, where S and A are the sets of states s and actions a, and R(s↪ a) is the reward function. The dynamics T for each instance b depends on the value of the hidden parameters ✓b: T(s0 ♣s↪ ✓b↪ a). We denote the set of all possible parameters as ⇥ and let P⇥(✓) be the prior over these parameters. Thus, a HiP-MDP describes a class of tasks; a particular instance b of that class is obtained by fixing the parameter vector ✓b 2 ⇥.
As pointed out by Bai et al. [2013] in a similar setting, we can consider the HiP-MDP a type of POMDP where the hidden state is the parameter vector ✓b. However, a HiPMDP makes two assumptions that are stronger than those of a POMDP. First, each instance of a HiP-MDP is an MDPconditioned on ✓b, there is no hidden state. Thus, we could always learn to solve each HiP-MDP instance as its own distinct MDP. Second, the parameter vector ✓b is fixed for the duration of the task, and thus the hidden state has no dynamics. This assumption considerably simplifies the procedure for inferring the hidden parametrization.
In special cases, we may be able to derive analytic expressions for how ✓b affects the dynamics T(s0 ♣s↪ ✓b↪ a): for example, in a manipulation domain we might be able to derive an equation for how the cup will respond to a force given a particular mass of liquid. However, in most situations, the simplifications required to derive these analytical forms for the dynamics will be brittle at best. The IBP-GP prior for the HiP-MDP, presented next, describes a semiparametric approach for modeling the dynamics that places few assumptions on the form of the transition function T (s0 ♣s↪ ✓b↪ a) while still maintaining computational tractability.
3 The IBP-GP HiP-MDPModel
Let the state s be some d-dimensional vector in Rd . We propose a transition model T of the form:
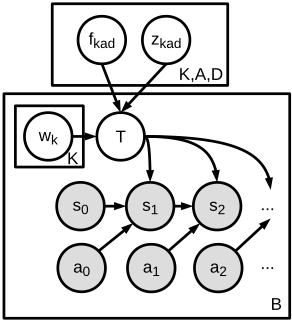
that is, we model the transition distribution as the difference between the current and next state. The transition distribution has two parts (as also illustrated in figure 1): one that is shared among all instances and one that is specific to the particular instance b. The functions fkad(s) can be thought of as a basis from which we will construct the transition function, and the filter parameters zkad 2 ¶0↪ 1♦ denote whether the kth latent parameter is relevant for predicting dimension d under action a-effectively switching fkad on or off. These global basis functions zkadfkad(s) are multiplied by task-instancespecific weights wkb (e.g., the effect of torque on velocity depends on the weight of the bat). The task instance dynamics are therefore obtained by setting wkb, the only elements of the model that vary across instances.
The generative process for the hidden variables wkb↪ zkad, and fkad is given by
where ↵ and are the hyper-parameters of the IBP and GP. We set w1b↪ z1ad = 1 to fix the scale of the latent parameters and have the basis function f1ad be the mean dynamics.
The IBP-GP prior encodes the assumption that we have an infinite number of possible basis functions fkad that we could use to construct the transition functions, while using an IBP prior on the filter parameters zkad implies that we expect a few latent factors to be relevant for making most predictions. That is, given a finite number of instances, we will only need a finite number of basis functions to construct the dynamics. Specifically, we cannot have seen more than B different transition functions in a batch of B instances. Thus, when making predictions about a specific state dimension d given action a, only a few of these infinite possible latent parameters will be relevant-and we only need to infer weights wkb corresponding to situations where zkad is nonzero. Moreover, additional prediction tasks-such as a new action, or a new dimension to the state space-can be incorporated in a statistically consistent manner. As a regression model, IBP-GP model is an infinite version of the Semiparametric Latent Factor Model [Teh et al., 2005].
4 Inference in the IBP-GP HiP-MDP
We focus on scenarios in which the agent is given a large amount of batch observational data from several domain instances (perhaps solved as independent MDPs) and tasked with quickly performing well on new instances. Our batch inference procedure uses the observational data to fit the filter parameters zkad and basis functions fkad, which are independent of any particular instance, and compute a posterior over the weights wkb, which depend on each instance. These settings of zkad↪ fkad, and P(wkb) will used to infer the instance-specific weights wkb efficiently in the online setting when given a new instance.
4.1 Batch Inference
Given a batch of data containing multiple instances, we infer the filter parameters zkad, the weights wkb, and an approximation to the basis functions fkad(S⇤ ) using a blocked Gibbs sampler.
Representing andResampling fkad The posterior over the weights wkb is Gaussian given the filter settings zkad and means θwk ; the basis functions fkad can be marginalized out. Thus, in theory, it is not necessary to instantiate the basis functions fkad.
However, marginalization over the basis functions fkad requires computing inverses of matrices of size N = Pb Nb, where Nb is the number of data collected in instance b. To avoid this computational cost, we choose to represent each function fkad by a set of (s⇤ ↪ fkad(s⇤ )) pairs for states s⇤ in a set of support points S⇤ . Various optimization procedures exist for choosing the support points [Snelson and Ghahramani, 2005; Teh et al., 2005]; we found that iteratively choosing support points from existing points to minimize the maximum reconstruction error within each batch was best for a setting in which a few large errors can result in poor performance.
Given a set of tuples (s↪ a↪ s0 ↪ r) from a task instance b, we first created tuples (s⇤ ↪ a↪∆b(s⇤ )) for all s⇤ 2 S⇤ and all actions a, all dimensions d, and all instances b. The tuple (sd⇤↪ a↪ ∆b(sd⇤)) can be predicted based on all other data available for that action a, dimension d pair using standard Gaussian process prediction:
where Sab is the collection of tuples (s↪ a↪ s0 ↪ r) with action a from instance b, Ks⇤ Sab is the vector K(s⇤ ↪ s) for every s 2 Sab, KSabSab is the matrix K(s↪ s), and ∆b(Sabd) is the vector of differences s0d - sd. This procedure was repeated for every task instance b.
Now, we can proceed to sample new values for the basis function fkad at the chosen support points S⇤ . Given zkad and wkb, the posterior over the outputs fkad(S⇤ ) is Gaussian. Let fad(S⇤ ) be a column vector of concatenated fkad(S⇤ ) vectors, and let ∆(S⇤ ) be a column vector of concatenated ∆b(S⇤ ) vectors. The mean and covariance of fad(S⇤ ) is given by
where
where ⌦ is the Kronecker product, KS⇤ S⇤ is the matrix K(s⇤ ↪ s⇤ ) for every s⇤ 2 S⇤ , and we write wb(zkad) to be a B ⇥ k0 matrix of elements wkb such that zkad = 1. We repeat this process for each action a and each dimension d.
The update equations for zkad and wkb follow directly from the properties of Gaussian distributions and Indian Buffet Processes.
Resampling wkb Given zkad and fkad(S⇤ ), the posterior over wkb is also Gaussian. For each instance b, the mean and covariance of wb(zkad) (that is, the weights not set to zero) are given by:
for k > 1, where Fb is matrix with k0 - 1 columns concatenating values for fkad for all actions a and all dimensions d and excluding k = 1, and ∆b(S⇤ ) is a column vector concatenating the differences for all actions a and all dimensions d.
Resampling zkad To sample zkad for an already-initialized feature k, we note that the likelihood of the model given z, w, and f with some zk0 ad = 0 is Gaussian with mean and variance
If zkad = 1, then the likelihood is again Gaussian with the same mean (here we assume that the GP prior on f is zeromean) but with covariance
where wk0 is a vector of latent parameter values for all instances b. We combine these likelihoods with the prior to sample zkad.
Initializing a new latent parameter k0-that is, a k0 for which we do not already have values for the weights wk0 b-involves computing the marginal likelihood P (∆(S⇤ )♣zk0 ad↪ wkb↪ fkad), which is intractable. We approximate the likelihood by sampling Nw sets of new weights wk0 b. Given values for the weights wk0 b for each instance b, we can compute the likelihood with the new basis function fk0 ad marginalized out. We average these likelihoods to estimate the marginal likelihood of zk0 ad = 1 for the new k0 . (For the zk0 ad = 0 case, we can just use the variance from the prior.) If we do set zk0 ad = 1 for the new k0 , then we can sample a set of weights wk0 b from our Nw samples based on their importance weight (marginal likelihood).
Finally, given the values of the weights wkb for a set of instances b, we can update the posterior over θwk with a standard conjugate Gaussian update:
We use this posterior over the weight means θwk when we encounter a new instance b0 .
4.2 Online Filtering
Given values for the filter parameters zkad and the basis functions fkad, the posterior on the weights wkb is Gaussian. Thus, we can write the parametrized belief bt(wkb) at time t with (hw↪ Pw), where Pw is the inverse covariance ⌃-1 w and hw is the information mean θwPw. Then the update given an experience tuple (s↪ a↪ s0 ↪ r) is given by
where Fa is a d ⇥ k matrix of basis values fkad(s), ⌃na is a d ⇥ d noise matrix with σ2nad on the diagonal (note that therefore the inverse ⌃-1 na is trivially computed), and ∆(s) is a d-dimensional vector of s0d - sd. If updates are performed only every n time steps, we can simply extend F , ⌃, and ∆(s) to be nd ⇥ k, nd ⇥ nd, and nd respectively.
Computing Fa requires computing the values of the basis functions at the point s. Since we only have the values computed at pseudo-input points s⇤ 2 S⇤ , we use standard GP prediction to interpolate the value for this new point:
where KsS⇤ is the vector K(s↪ s⇤ ) for every s⇤ 2 S⇤ , KS⇤ S⇤ is the matrix K(s⇤ ↪ s⇤ ), and fkad(S⇤ ) is the vector fkad(s⇤ ). Using only the mean value fkad(s⇤ ) ignores the uncertainty in the basis function fkad. While incorporating this variance is mathematically straight-forward-all updates remain Gaussian-it adds additional computation to the online calculation, and we found that using the means already provided significant gains in learning in practice.
5 Results
In this section, we describe results on three benchmark problems: cartpole, acrobot [Sutton and Barto, 1998], and bicycle [Randlov and Alstrom, 1998]. Cartpole has a relatively simple policy; we use it to visualize how HiP-MDPs compress the dynamics across different parameter settings into a latent space. Acrobot and bicycle are challenging domains when the agent must rapidly learn a control strategy for a new set of parameters. All of our tests use an anisotropic squaredexponential kernel with length and scale parameters approximated for each action a and state dimension d.
5.1 Cartpole
In the cartpole domain, an agent must apply forces either to the left or right of a cart to keep a pole balanced on top of it. It has a four-dimensional state space s = ¶x↪ ˙x↪ ✓↪ ˙ ✓♦ consisting of the cart's position x, the cart's velocity ˙x, the pole's angle ✓, and the pole's angular velocity ˙ ✓. At each time step of length ⌧ , the system evolves according to:
where v = f+ml ˙✓2 t sin✓ M ↪ ✓ = (g sin✓-v cos ✓) (l( 43 -mcos ✓2 ◁M) , f is the applied force, g is gravity, M is the mass of both the cart and the pole, and m and l are the mass and length of the pole.
We varied the pole mass m and the pole length l. In each (m↪ l) setting, we ran Sarsa [Sutton and Barto, 1998] (using a 3rd order Fourier basis [Konidaris et al., 2011]) for 5 repetitions of 30 episodes, where each episode was run for 300 steps or until the pole fell down. Data from seven (m↪ l) settings ¶ (.1,.4) , (.3,.4) , (.15,.45) , (.2,.55) , (.25,.5) , (.3,.4) , (.3,.6) ♦ were reduced to 750 support points and then the batch inference procedure was repeated 5 times for 250 iterations. We set σw = 4, ↵ = 2, and optimized the Gaussian process parameters.
| Batch + Train | Batch Only | Train Only | IBP-GP HIP-MDP | |
|---|---|---|---|---|
| ˙x | 4.8e-06 (1.7e-08) | 4.8e-06 (1.7e-08) | 9.1e-05 (2.3e-07) | 4.7e-06 (1.7e-08) |
| x | 1.1e-07 (1.0e-08) | 1.1e-07 (1.1e-08) | 7.6e-07 (1.4e-07) | 3.3e-08 (2.9e-09) |
| ˙ ✓ | 1.1e-03 (3.2e-06) | 1.1e-03 (3.2e-06) | 3.4e-02 (1.4e-04) | 1.0e-03 (3.2e-06) |
| ✓ | 1.5e-05 (1.5e-06) | 1.5e-05 (1.6e-06) | 3.7e-05 (2.8e-06) | 2.5e-06 (1.1e-07) |
| All | 2.7e-04 (8.9e-04) | 2.7e-04 (8.9e-04) | 8.4e-03 (2.8e-02) | 2.6e-04 (8.8e-04) |
Next, 50 training points were selected from each run of (m↪ l) settings with m 2 ¶▷1↪ ▷15↪ ▷2↪ ▷25↪ ▷3♦ and l 2 ¶▷4↪ ▷45↪ ▷5↪ ▷55↪ ▷6♦. The online inference procedure was used to estimate the weights wkb given the filter parameters zkad and basis functions fkad from the batch procedure. The quality of the predictions ∆(s) on 50 unseen test points are shown in Table 1, which compares standard regression using different combinations of input data to the HiP-MDP model. Standard regression using only the batch points, and using both batch and training, is equivalent to treating all of the task instances as a single MDP, while regression using the training points for each (m↪ l) setting performs no transfer and results in the highest error. Our IBP-GP model uses both the batch data and the training points for each (m↪ l) setting, modeling both the commonalities and differences between MDPs in the task family. It performs similarly to a single batch-trained GP for predicting the change in outputs x and ✓, since these state variables do not depend on m or l (see equation 4). It significantly outperforms the other settings for outputs ˙x and ˙ ✓, whose changes do depend on the parameters of system. Visualizations interpreting the latent parameters are included in the appendix.
5.2 Acrobot
Cartpole is simple enough that changing m and l does not change the optimal policy-if the pole is falling to the left, the cart should be moved left, and similarly to the right. Acrobot, in which the agent must swing up a double pendulum only through applying a positive, neutral, or negative torque to the joint between the two poles, is much more challenging. The state space consists of the angle ✓1 and angular velocity ˙ ✓1 of the first segment (with mass m1) and of the second segment (✓2 and ˙ ✓2, with mass m2). Small changes in mass can substantially impact the policy.
For batch training, we used mass settings (m1↪m2) settings of ¶ (.7,.7) , (.7,1.3) , (.9,.7) , (.9,1.1) , (1.1,.9) , (1.1,1.3) , (1.3,.7) , (1.3, 1.3) ♦, again employing Sarsa (this time with a 5th order Fourier Basis). 1000 support points were chosen to minimize the maximum prediction error within each batch. Next, we inferred the filter parameters zkad and obtained approximate MAP-estimates for the basis functions fkad.
Table 2 shows mean-squared prediction errors using the same evaluation procedure as cartpole, with (m1↪m2) settings of m1 2 ¶▷7↪ ▷9↪ 1▷1↪ 1▷3♦ and m2 2 ¶▷7↪ ▷9↪ 1▷1↪ 1▷3♦. The HiP-MDP predicts better overall, with slightly higher mean-squared errors on the angle predictions and lower errors on the angular velocity predictions. Predicting angular velocities is critical to planning in acrobot; inaccurate predictions will make the agent believe it can reach the swing-up position more quickly than is physically possible.
| Batch + Train | Batch Only | Train Only | IBP-GP HIP-MDP | |
|---|---|---|---|---|
| ˙ ✓1 | 5.1e-05 (3.1e-06) | 5.4e-05 (3.3e-06) | 3.8e-04 (3.1e-05) | 5.5e-05 (8.3e-06) |
| ˙ ✓2 | 1.4e-04 (1.2e-05) | 1.5e-04 (1.2e-05) | 8.8e-04 (9.6e-05) | 1.3e-04 (2.1e-05) |
| ✓1 | 7.0e-04 (4.5e-05) | 7.2e-04 (4.8e-05) | 1.6e-03 (1.5e-04) | 3.6e-04 (4.0e-05) |
| ✓2 | 4.2e-04 (2.5e-05) | 4.3e-04 (2.7e-05) | 9.1e-04 (1.0e-04) | 2.3e-04 (2.1e-05) |
| All | 3.3e-04 (3.8e-05) | 3.4e-04 (3.9e-05) | 9.4e-04 (8.1e-05) | 2.0e-04 (2.1e-05) |
In acrobat, a policy learned with one mass setting will generally perform poorly on another. To evaluate our HiPMDP approach in a control setting, we ran 30 trials in each of the 16 settings above, filtered the weight parameters wk during an episode, and updated the policy at the end of each episode. As finding the full Bayesian RL solution is PSPACE-complete [Fern and Tadepalli, 2010] and offline approximation techniques are an active area of research [Bai et al., 2013], we performed planning using Sarsa with dynamics based on the mean weight parameters wk. We first obtained an initial value function using the prior mean weights, and then interleaved model-based planning and reinforcement learning, using 5 episodes of planning for each of interaction.
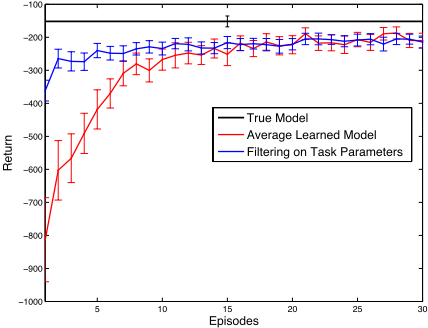
Results on acrobot are shown in Figure 2. We compare performance (averaged over weight settings) to planning using the true model, and to planning using an average model (learned using all the batch data at once) to obtain an initial value function. Both the average and HiP-MDP model reach performance near, but not quite as high as, using the true model. However, the HiP-MDP model is already near that performance by the 2nd episode. Using the learned bases from the batches, as well as learning the weights from the first episode, lets it quickly "snap" very near to the true dynamics. Our HiP-MDP model reaches near-optimal performance in 5 episodes, compared to 15 for the average model.
5.3 Bicycle
The bicycle domain [Randlov and Alstrom, 1998] requires the agent to keep a bicycle traveling at a constant speed upright for as long as possible within a bounded 60x60m area. The agent has three torque actions on the handlebars-¶-2N↪ 0↪ 2N♦-and three mass-displacement actions-¶-2cm↪ 0↪ 2cm♦-for a total of nine possible actions. To simulate imperfect balance, a random displacement between [-2cm↪ 2cm] is added to the agent's displacement action. The dynamics of the bicycle depend on several parameters, and here we vary the bicycle's height and mass, physical parameters to which a real-life bicycle-riding agent should be robust.
Our batch training data consisted of two trials of 10 episodes for the bicycle height ranging from 0.74 to 1.24 meters in increments of 0.15 and weight ranging from 10 to 20 kilograms in increments of 5. These batch data were used to infer the filter parameters zkad and approximate MAPestimates for the basis functions fkad for the HiP-MDP.
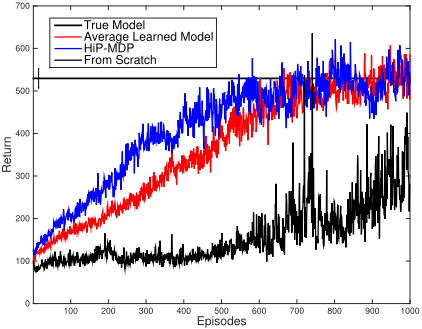
At test time, we ran 25 trials for each setting of the two task parameters. For each trial, we first used the mean model parameter values to compute an initial value function; we then mixed learning and planning-one episode of planning for each 10 episodes of real data, up to 200 episodes of real data-while filtering the weight parameters wk. Both learning and planning was performed using Sarsa(λ) with ↵ = 0▷05 and λ = 0▷95, an epsilon-greedy exploration policy with ✏ = 0▷05, and reward discount γ = ▷99, using tile coding with the boundaries used in the original paper [Randlov and Alstrom, 1998] and then continued with Sarsa. The average model computed a single set of bicycle dynamics from all of the batch data. We applied 1500 episodes of Sarsa on this model to learn a value function to initialize the learner in a new setting. Figure 3 compare the HiP-MDP and averaged approaches to learning each bicycle parameter configuration from scratch, averaged over all height and mass configurations. Both approaches show positive transfer, but the HiP-MDP has a much faster learning trajectory, reaching near-optimal performance nearly 150 episodes before the average-initialized approach. The slow rate of the learner that starts from scratch demonstrates the overall difficulty of the bicycle problem.
6 Discussion and RelatedWork
Bai et al. [2013] use a very similar hidden-parameter setting treated as a POMDP to perform Bayesian planning; they assume the model is given, whereas our task is to learn it. The HiP-MDP is similar to other POMDPs with fixed hidden states, for example, POMDPs used for slotfilling dialogs [Williams and Young, 2005]. The key difference, however, is that the objective of the HiP-MDP is not simply to gather information (e.g., simply learn the transition function T); it is to perform well on the task (e.g., drive a new car). Transfer learning-the goal of the HiPMDP-has received much attention in reinforcement learning. Most directly related in spirit to our approach are Hidden-Goal MDPs [Fern and Tadepalli, 2010], hidden-type MDPs and bandits [Azar et al., 2013; Brunskill and Li, 2013; Mahmud et al., 2014; Rosman et al., 2016] and hierarchical model-based transfer [Wilson et al., 2012a]. In these settings the agent must determine its current MDP from a discrete set of MDPs. However, note that in the discrete setting the agent switches between distinct MDPs (or, in the case of Wilson et al. [2012a], a finite set of distributions over discrete MDPs), rather than learning how a continuous parametrization modifies the dynamics of the entire family. Representation transfer approaches [Ferguson and Mahadevan, 2006; Taylor and Stone, 2007; Ferrante et al., 2008] typically focus on learning a set of basis functions sufficient for representating any value function defined in a specific state space, or on transfer between two different representations of the same task. By contrast, the HiP-MDP focuses on modeling the dimensions of variation of a family of related tasks.
A recent series of papers [Ammar et al., 2014; Bou Ammar et al., 2015b; 2015a] transfer learned policy parameters across families of related tasks using policy gradient methods. These papers synthesize new policies as linear combinations of policy components from previously solved instances. They are complementary to our approach, which focuses on parametrizing the environmental model rather than the policy. However, the supervised nature of transition models means that our approach is not limited to policy gradients; we can also infer the number of parameters in the environmental model from data.
The IBP-GP prior itself relates to a body of work on multiple-output Gaussian processes (e.g. [ ´Alvarez and Lawrence, 2011; Teh et al., 2005; Wilson et al., 2012b]), though most of these are focused on learning a convolution kernel to model several related outputs on a single task, rather than parameterizing several related tasks. Gaussian process latent variable models [Lawrence, 2004] have been used for dimensionality reduction in dynamical systems. As with other multi-output GP models, however, GP-LVMs find a time-varying, low-dimensional representation for a single system, while we characterize each instance in a set of systems by a stationary, low-dimensional vector. The focus of these efforts has also been on modeling rather than control.
The extensive work on scaling inference in these Gaussian process models [ ´Alvarez and Lawrence, 2011; Titsias, 2009; Damianou et al., 2011] provides avenues for relaxing the approximations made in this work (while adding new ones). In settings where one may not have an initial batch of data from several instances, a fully Bayesian treatment of the filter parameters zkad and the basis functions fkad might allow the agent to more accurately navigate its exploration-exploitation trade-offs. Exploring which uncertainties are important to model-and which are not-is an important question for future work. Other extensions within this particular model include applying clustering or more sophisticated hierarchical methods to group together basis functions fkad and thus share statistical strength. For example, one might expect that "opposing actions," such as in cartpole, could share similar basis functions.
Another interesting direction is allowing for some timevarying dynamics within the problem, but in structured ways that still make inference relatively easy. For example, we may place priors on the weights wk that allow them to shift-but slowly. Or we may believe that abrupt changes are possible but unlikely-such as an agent moving from one kind of surface to another. Finally, it would be interesting to explore the limit of what kind of transfer is possible: given data from two differing domains, will we just learn two sets of basis functions with non-overlapping filter parameters zkad? What kind of modeling hierarchies might allow for more sharing between only somewhat-related tasks?
7 Conclusion
Machine learning approaches for control generally expect repeated experiences in the same domain. However, in practice agents are more likely to experience repeated domains that vary in limited and specific ways. In this setting, traditional planning approaches that rely on exact models may fail due to the large inter-instance variation. By contrast, reinforcement learning approaches, which often assume that the dynamics of a new instance are unknown, may fail to leverage information across related instances.
The HiP-MDP model explicitly captures this inter-instance variation, providing a compromise between these two standard paradigms for control. It should prove useful when the family of domains has a parametrization that is small relative to its model and where objectives remain similar across domains. Many applications-such as handling similar objects, driving similar cars, even managing similar network flows-fit this scenario, where batch observational data from related tasks are easy to obtain in advance. In such cases, being able to generalize dynamics from only a few interactions with a new operating regime (using data from many prior interactions with similar systems) is a key step in building controllers that exhibit robust and reliable decision-making while gracefully adapting to new situations.
Acknowledgments
This research was supported in part by DARPA under agreement number D15AP00104, and by the National Institutes of Health under award number R01MH109177. The U.S. Government is authorized to reproduce and distribute reprints for Governmental purposes notwithstanding any copyright notation thereon. The content is solely the responsibility of the authors and does not necessarily represent the official views of the National Institutes of Health or DARPA.
A Visualizing Latent Features for Cartpole
In all 5 of the MCMC runs, a total of 4 latent parameters were inferred. The output dimensions x and ✓ consistently only used the first (baseline) feature-that is, our IBP-GP's predictions were in fact the same as using a single GP. This observation is consistent with the cartpole dynamics and the observed prediction errors in figure 4. The second feature was used by both ˙x and ˙ ✓ and was positively correlated with both the pole mass m and the pole length l (figures 6, 5, and 5). In the cartpole dynamics equations, both ˙x and ˙ ✓ have many ml terms. The third consistently discovered feature was used only by ˙x and was positively correlated with the pole mass m and not correlated with the pole length l; the equations for ˙x have several terms that depend only on m. The fourth feature (used only to predict ˙x) had the highest variability; it generally has higher values for more extreme length settings, suggesting that it might be a correction for more complex nonlinear effects.
@inproceedings{ijcai2016p206,
  title     = {Hidden Parameter Markov Decision Processes: A Semiparametric Regression Approach for Discovering Latent Task Parametrizations},
  author    = {Doshi-Velez, Finale and Konidaris, George Dimitri},
  booktitle = {Proceedings of the Twenty-Fifth International Joint Conference on
               Artificial Intelligence, {IJCAI-16}},
  publisher = {AAAI Press / International Joint Conferences on Artificial Intelligence},
  editor    = {Subbarao Kambhampati},
  pages     = {1432--1439},
  year      = {2016},
  month     = {7},
  url       = {https://ijcai.org/proceedings/2016/206},
}
TY - CPAPER TI - Hidden Parameter Markov Decision Processes: A Semiparametric Regression Approach for Discovering Latent Task Parametrizations AU - Doshi-Velez, Finale AU - Konidaris, George Dimitri T2 - Proceedings of the Twenty-Fifth International Joint Conference on Artificial Intelligence, IJCAI-16 PB - AAAI Press / International Joint Conferences on Artificial Intelligence PY - 2016 SP - 1432 EP - 1439 UR - https://ijcai.org/proceedings/2016/206 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





