
Direct Policy Iteration with Demonstrations
Proceedings of the Twenty-Fourth International Joint Conference on Artificial Intelligence. Special Track on Machine Learning. Pages 3380-3385.
© 2015 International Joint Conferences on Artificial Intelligence
Abstract
We consider the problem of learning the optimal policy of an unknown Markov decision process (MDP) when expert demonstrations are available along with interaction samples. We build on classification-based policy iteration to perform a seamless integration of interaction and expert data, thus obtaining an algorithm which can benefit from both sources of information at the same time. Furthermore, we provide a full theoretical analysis of the performance across iterations providing insights on how the algorithm works. Finally, we report an empirical evaluation of the algorithm and a comparison with the state-of-the-art algorithms.
- [Abbeel and Ng, 2004] Peter Abbeel and Andrew Ng. Ap- prenticeship learning via inverse reinforcement learning. In Proceedings of the 21st International Conference on Machine Learning, 2004.
- [Archibald et al., 1995] TW Archibald, KIM McKinnon, and LC Thomas. On the generation of markov decision processes. Journal of the Operational Research Society, pages 354-361, 1995.
- [Bagnell and Ross, 2010] J Andrew Bagnell and Stephane Ross. Efficient Reductions for Imitation Learning. In Pro- ceedings of the 13th International Conference on Artificial Intelligence and Statistics, pages 661-668, 2010.
- [Bertsekas and Tsitsiklis, 1996] Dimitri P Bertsekas and John N Tsitsiklis. Neuro-Dynamic Programming. Athena Scientific, 1st edition, 1996.
- [Bhatnagar et al., 2009] Shalabh Bhatnagar, Richard S Sut- ton, Mohammad Ghavamzadeh, and Mark Lee. Natural actor-critic algorithms. Automatica, 45(11):2471-2482, 2009.
- [Chang and Lin, 2011] Chih-Chung Chang and Chih-Jen Lin. LIBSVM: A library for support vector machines. ACM Transactions on Intelligent Systems and Technology, 2:27:1-27:27, 2011. Software available at http://www. csie.ntu.edu.tw/ ∼ cjlin/libsvm. Link
- [Doshi-Velez et al., 2010] Finale Doshi-Velez, David Wingate, Nicholas Roy, and Joshua B Tenenbaum. Nonparametric bayesian policy priors for reinforcement learning. In Advances in Neural Information Processing Systems, pages 532-540, 2010.
- [Farahmand et al., 2009] Amir M Farahmand, Mohammad Ghavamzadeh, Shie Mannor, and Csaba Szepesvári. Regu- larized policy iteration. In Advances in Neural Information Processing Systems, pages 441-448, 2009.
- [Grant and Boyd, 2014] Michael Grant and Stephen Boyd. CVX: Matlab software for disciplined convex program- ming, version 2.1. http://cvxr.com/cvx, March 2014. Link
- [Kakade and Langford, 2002] Sham Kakade and John Lang- ford. Approximately optimal approximate reinforcement learning. In Proceedings of the Nineteenth International Conference on Machine Learning, ICML '02, pages 267- 274, San Francisco, CA, USA, 2002.
- [Kim et al., 2013] Beomjoon Kim, Amir massoud Farah- mand, Joelle Pineau, and Doina Precup. Learning from limited demonstrations. In Advances in Neural Informa- tion Processing Systems, pages 2859-2867, 2013.
- [Lagoudakis and Parr, 2003] Michail G Lagoudakis and Ronald Parr. Reinforcement learning as classification: Leveraging modern classifiers. In ICML, volume 3, pages 424-431, 2003.
- [Lazaric et al., 2010] Alessandro Lazaric, Mohammad Ghavamzadeh, Rémi Munos, et al. Analysis of a classification-based policy iteration algorithm. In ICML- 27th International Conference on Machine Learning, pages 607-614, 2010.
- [Munos, 2003] R. Munos. Error bounds for approximate policy iteration. In International Conference on Machine Learning, pages 560-567, 2003.
- [Ng and Russell, 2000] A. Ng and S. Russell. Algorithms for inverse reinforcement learning. In Proceedings of the 17th International Conference on Machine Learning, pages 663-670, 2000.
- [Piot et al., 2014] Bilal Piot, Matthieu Geist, and Olivier Pietquin. Boosted Bellman Residual Minimization Han- dling Expert Demonstrations. In European Conference on Machine Learning and Principles and Practice of Knowl- edge Discovery in Databases (ECML/PKDD). Springer, 2014.
- [Ross and Bagnell, 2014] Stephane Ross and J Andrew Bag- nell. Reinforcement and imitation learning via interactive no-regret learning. arXiv:1406.5979, 2014.
- [Ross et al., 2010] Stéphane Ross, Geoffrey J Gordon, and J Andrew Bagnell. A reduction of imitation learning and structured prediction to no-regret online learning. arXiv preprint arXiv:1011.0686, 2010.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
We study the problem of learning the optimal policy of an unknown Markov decision process (MDP) by reinforcement leaning (RL) when expert samples (limited in number and/or quality) are available. In particular, we identify in approximate policy iteration (API) [Bertsekas and Tsitsiklis, 1996] the most suitable learning scheme to integrate expert demonstrations. API is an iterative learning scheme where one has access to batch data (i.e., RL samples) obtained by a sampling policy. Starting at an arbitrary policy, API goes through two stages at every iteration: 1) policy evaluation first computes the value function of the current policy, 2) policy improvement computes the greedy policy w.r.t. the value function. At any of the two steps, API may introduce errors that depend on the use of a finite number of samples and the choice of a specific approximation space (e.g., linear regression). Because of such errors, API is not guaranteed to improve policies monotonically at each iteration and, in general, it only converges to a set of policies with bounded performance loss w.r.t. the optimal policy [Munos, 2003]. In this work, we propose to improve such learning scheme by modifying the policy improvement step to bias it towards policies that agree, to some degree, with demonstrated expert actions.
Related work. While most of past literature focused on learning from either RL or expert samples [Ng and Russell, 2000; Abbeel and Ng, 2004; Bagnell and Ross, 2010], there is a recent surge of interest in combining expert demonstrations in RL algorithms [Kim et al., 2013; Piot et al., 2014] or cost functions in imitation learning [Ross and Bagnell, 2014].
Kim et al. [2013] proposed API with demonstrations (APID) which modifies regularized-LSPI [Farahmand et al., 2009] by adding linear soft max-margin constraints in the policy evaluation step; the constraints require value functions for which expert actions are greedy. Kim et al. [2013] upper bound the Bellman error of APID at any iteration and empirically show that it outperforms both LSPI and imitation learning algorithms. Although the empirical results are a convincing proof of concept, the theoretical analysis is limited to single-iteration errors and does not provide a clear understanding on how effectively RL and expert data are integrated. In fact, while the objective of LSPI is to compute the value function of the current policy, the constraints favor functions with greedy actions equivalent to the expert's. These two requirements may be contrasting (e.g., the greedy policy of the exact value function may not be similar to the expert) and may point towards solutions which are neither good to estimate the target value nor in satisfying the desired constraints.
Piot et al. [2014] build on a similar idea but integrate expert constraints directly into the minimization of the optimal Bellman residual. This integration is very appealing since it "regularizes" the global objective of approximating the optimal value function rather than constraining each iteration of API, in which the constraints and the objective over iterations may not always be coherent. Unfortunately, the resulting optimization problem is non-convex, non-differentiable and biased, and so they have to resort to a non-parametric method where the conditional transition matrix is embedded in RKHS and the minimization is carried out by a boosting algorithm. Although the resulting algorithm, called RLED, outperforms APID in practice, the complexity of the optimization prevents from deriving theoretical guarantees on its performance.
Finally, the integration of expert demonstrations has been investigated in Bayesian model-based RL in [Doshi-Velez et al., 2010], where a non-parametric Bayesian approach is employed to combine model knowledge from the expert trajectories and RL samples obtained from independent exploration.
In this paper, we build on classification-based policy iteration [Lagoudakis and Parr, 2003], notably the direct policy iteration (DPI) [Lazaric et al., 2010] algorithm, where policy improvement is replaced by a classification problem. Since imitating the expert policy is intrinsically a classifica-
Algorithm 1 Direct Policy Iteration with Demonstrations
1: Input: policy space Π, state distribution ρ, expert weight α 2: Initialize: arbitrary policy ̂ π0 ∈ Π 3: for k = 1 to K do 4: Construct the rollout set Dk roll = {xi}NRL i=1 , xi iid ∼ ρ 5: for xi ∈ Dk roll and actions a ∈ A do 6: for j = 1 to M do 7: Perform a rollout according to policy ̂ πk 8: Rπk j (xi, a) = r(xi, a) + ∑Ht=1 γ t r(xt , πk(xt )), 9: end for 10: ̂Qπk (xi, a) = 1M ∑Mj=1 Rπk j (xi, a) 11: Build RL training set DkRL = DkRL ∪ {xi, a∗i , wi} 12: end for 13: Build expert training set DkE = {zj, aj, α}NE j=1 14: Build training set Dk = DkE ∪DkRL 15: ̂ πk+1 = arg min π∈Π ̂ Lπk ( ˆ ρ, ˆµ, π) (Classification) 16: end fortion problem, the integration of the expert and RL data sums up to merging the two datasets. Thanks to its simple form, the resulting algorithm (DPID) (Sect. 3) does not increase the complexity of DPI and its performance across iterations can be theoretically analyzed (Sect. 4). Experimental results in two simulated domains show the potential of DPID compared to existing methods (Sect. 5).
2 Preliminaries
We consider a discounted MDP defined by the tuple (X,A, p, r, γ), where the state space X is bounded in Rd , the action space A is finite 1 , the kernel p : X × A → X defines the transition probabilities, the reward r : X ×A → [-Rmax; Rmax] is bounded, and γ ∈ [0, 1) is a discount factor. A deterministic policy π is a mapping X → A and Π is a set of policies. We denote by V π : X → R and Qπ : X ×A → R the value and action value functions of policy π. V π is the unique fixed-point of the Bellman operator T π defined as (T π V )(x) = r(x, π(x)) + γ ∫X p(dy|x, π(x))V (y), while Qπ (x, a) = r(x, a) + γ ∫X p(dy|x, a)V π (y). The optimal policy π⋆ maximizes V π over all states and we denote by V ⋆ and Q⋆ its corresponding functions. V ⋆ is also the unique fixed-point of the optimal Bellman operator T defined as (TV )(x) = maxa[r(x, a) + γ ∫X p(dy|x, a)V (y)], while Q⋆ (x, a) = r(x, a) + γ ∫X p(dy|x, a)V ⋆ (y). We say that π is greedy with respect to an action value function Q, if in any state x, π(x) ∈ argmaxa∈AQ(x, a). Finally, we introduce the greedy policy operator G mapping policies to greedy policies as (Gπ)(x) = arg maxa∈A Qπ (x, a).
3 Direct Policy Iteration with Demonstrations
Building on direct policy iteration (DPI) [Lazaric et al., 2010], we introduce DPI with demonstration (DPID), where demonstrations from an expert policy ξ are available. In the original DPI, at each iteration k, a rollout set {xi}NRL i=1 is sampled from a given sampling distribution ρ over X and the value of the current policy ̂ πk is estimated on those states using M rollouts truncated to H steps. The resulting estimates ̂Q̂ πk (xi, a) are then used to build a (cost sensitive) training set DkRL = {xi, a∗i , wi}NRL i=1 , where a∗i is the best estimated action (i.e., a∗i = argmaxa ̂Q̂ πk (xi, a)) and wi = ̂Q̂ πk (xi, a∗i ) - ̂Q̂ πk (xi, a+) is the cost of misclassifying the sample with a+ the other action in A. Since A is finite, a∗i can be interpreted as the label of xi and thus DPI reduces to solving a (binary) cost-sensitive classification problem using a given policy space Π (e.g., a linear classifier) and it returns a policy ̂ πk+1 approximating the greedy policy G(̂ πk). In DPID we further assume access to a training set DkE = {zj , ξ(zj)}NE j=1 , where states zj are drawn from a distribution µ over X and ξ is an expert policy (not necessarily optimal). The basic idea of DPID is then to define a suitable integration of DkRL and DkE and solve a classification problem on the joint training set. We introduce the following elements.
1 In order to simplify the theoretical analysis we will consider the case |A| = 2 throughout the rest of the paper.
Definition 1. At each iteration k, we define the state and average empirical RL losses of a policy π as
where ̂Q̂ πk is the rollout estimate of Q̂ πk (see Alg. 1) and ̂ ρ is the empirical counterpart of ρ (i.e., average of Dirac distributions at observed states). We also define the state and average empirical expert losses of a policy π as
where ̂ µ is the empirical counterpart of µ. Finally, the average empirical joint loss is
where α ≥ 0 is a parameter of the algorithm.
While the RL loss ˆ ℓRL ̂ πk (x; π) depends on the policy at iteration k, the expert loss does not change through iterations since it only measures the "similarity" w.r.t. ξ using a 0/1 loss. In the following we will also use LEα (̂ µ, π) = αLE (̂ µ, π).
As reported in Alg. 1, DPID turns the expert training set to a cost-sensitive set by adding a constant penalty α, which allows to move from DPI (α = 0) to a full imitation learning algorithm (α = ∞). Once the policy ̂ πk+1 is computed by minimizing the joint loss ̂ L̂ πk , the whole process is repeated over iterations. With DPID we propose a seamless integration of RL and expert data in a common training set, which does not affect the complexity of the original DPI algorithm. This is in contrast with APID and RLED, where the integration of expert data in the form of explicit constraints leads to optimization problems which are more complex and potentially computationally challenging (e.g., RLED needs solving a regularized non-convex optimization problem and APID defines a non-classical constrained convex optimization).
4 Finite Sample Analysis
In this section we provide a complete analysis of the performance of DPID. We first define the expected counterparts of the losses introduced in Def. 1.
Definition 2. At each iteration k, we define the state and average RL losses of any policy π as
Similarly, the expert loss of any policy π is
Finally, the joint loss is defined as
While the difference of RL loss LRL ̂ πk (ρ, π) w.r.t. its empirical counterpart ̂ LRL ̂ πk (̂ ρ, π) is in both the sampling distribution and use of estimated Q-values, LE only differs in using samples from µ. We also introduce a series of policies of interest:
These policies are the minimizers within the policy space Π of the losses defined above and thus they are the best policies in approximating the greedy policy G(̂ πk), the expert policy ξ, and the mixture obtained by averaging the two losses respectively. In the following, we assume that Π has a finite VC-dimension h = VC(Π) and we prove a bound on the loss of the policy returned by DPID at each iteration.
Theorem 1. Let ̂ πk+1 be the policy returned by DPID and
Then with probability (1 - 6δ)
with ϵall = ϵRL + αϵE. Furthermore,
Remark (the bound). The first statement refers to the quality of ̂ πk+1 in minimizing the joint loss and, as usual, two sources of error appear. The first is the approximation error related to the best policy in Π minimizing the loss L̂ πk , while the second term is the estimation error due to the limited number of samples. To reduce the estimation error, both RL and expert sample sizes should increase. The second and third statements bound the RL and expert losses of ̂ πk+1 and compare it to the best possible policy in Π minimizing LRL and LE respectively. In both cases, besides the approximation and estimation errors, ̂ πk+1 suffers from an error depending on the errors of πRL k+1 and πE k+1 measured w.r.t. the expert and RL losses respectively. This means that the RL loss of ̂ πk+1 will approach the smallest loss possible within Π whenever πRL k+1 is indeed similar to the expert policy ξ, i.e., when LEα (µ, πRL k+1 ) is small (similar for the third statement). As expected, the behavior of DPID strictly depends also on the parameter α. First, the relevance of different estimation errors in ϵall depends on α, so that for, e.g., small α, RL errors are more relevant. Similarly, whenever α is small, ̂ πk+1 tends to have a performance very similar to the best approximation of the greedy policy (i.e., πRL k+1 ), while when α is large ̂ πk+1 will approach the performance of πE .
Remark (comparison with APID). While the periteration error reported in [Kim et al., 2013] is measured w.r.t. the policy Bellman error, here we consider different losses. While the estimation errors are similar in their dependency on NRL and NE and α, the rest of the bounds cannot be easily compared. In fact, in [Kim et al., 2013] the impact of terms such as α, the similarity of ξ and ̂ πk, and the approximation space Π on the performance of APID is not clearly understandable, while in DPID, thanks to its simple integration of RL and expert data, their impact is relatively straightforward.
Before deriving a full propagation analysis for DPID, we report an intermediate lemma showing how the performance loss of ̂ πk+1 (i.e., the difference w.r.t. the optimal policy) can be upper-bounded simultaneously by the quality of the expert policy and the standard propagation of error.
Lemma 1. Let V E be the expert value function and P π the transition kernel induced by any policy π, then at the end of iteration k + 1, we have the state-wise bounds
This lemma shows that the performance loss of DPID is related to two terms. The first (standard) term links the performance of ̂ πk+1 with the previous iteration and accounts for the RL loss, measuring how well ̂ πk+1 approximates the greedy policy G(̂ πk). The second term reveals that the performance is also related to the performance of the expert and the actual difference between ̂ πk+1 and ξ. Thus, the actual performance loss of ̂ πk+1 will be the minimum between these bounds, suggesting that at any iteration k DPID will benefit from either the quality of the expert or the policy improvement depending on which of the two performs the best. This means that whenever the expert is nearly optimal, ̂ πk+1 is likely to perform as well as ξ plus the expert loss. On the other hand, if the expert is suboptimal, the standard approximate policy iteration guarantee holds.
To bound the performance loss bound over iterations, we introduce standard assumptions on the concentrability coefficients of the MDP and distributions ρ and µ, w.r.t. to the target distribution η (see [Lazaric et al., 2010] for a discussion).
Assumption 1. For any policy π and non-negative integers s and t, there exists a constant Cη,ρ(s, t) such that η(P ⋆ )s (P π )t ≤ Cη,ρ(s, t)ρ and Cη,ρ = (1 - γ)2 ∑∞s=0 ∑∞t=0 γ s+tCη,ρ(s, t) < ∞. For the expert policy ξ, there exists C E η,µ (s, t) such that η(P ⋆ )s (P ξ )t ≤ C E η,µ (s, t)µ and C E η,µ = ∑∞t=0 γ s+tC E η,µ (s, t) < ∞.
Theorem2. Let ∆k = V ⋆ -V ̂ πk and ∆E = V ⋆ -V E be the performance loss of the algorithm and the expert respectively. Under Assumption 1, if DPID is run over K iterations then
with
Remark (propagation bound). The performance loss is the minimum over three terms. The term CK is the same as in the propagation error of DPI and it depends on the largest policy improvement error over iterations. The term AK depends on the quality of the expert and the expert loss of the last policy ̂ πK. The most interesting term is BK, which gives an important insight on how DPID can actually benefit from the repeated balancing of expert and RL data. In fact, whenever there is an iteration j in which the combined RL and expert losses are small, this will lead to an overall small performance loss. Finally, combining Thm. 1 and 2, we can obtain the global finite-sample bound. The resulting bound (omitted for the sake of space) shows the critical impact of α and the quality of ξ in the final performance. In fact, whenever the ξ is optimal (i.e. ∆E = 0) and α is large, the second statement in Thm. 1 guarantees that DPID performs almost as well as the policy πE which approximates ξ the best within the policy space Π (termAK is the bound). On the other hand, if ξ is highly suboptimal and α is small, then DPID would approach the performance of DPI (term CK in the bound). In all other intermediate cases, DPID could still effectively take advantage of both the DPI process and the imitation of ξ to achieve a nearly optimal performance (term BK in the bound).
5 Experiments
We compare the performance of DPID 2 to DPI, which uses only RL data, and to DAGGER [Ross et al., 2010] when the expert can be queried at arbitrary states or pure imitation learning when batch expert data are available. We also compare to APID (implemented using CVX [Grant and Boyd, 2014]) and RLED (implemented using decision trees as weak learners).
2 The implementation of DPID is available at https://www.dropbox.com/s/jj4g9ndonol4aoy/dpid.zip?dl=0
Garnet domain. The Garnet framework [Archibald et al., 1995; Bhatnagar et al., 2009; Piot et al., 2014] allows to generate random finite MDPs characterized by 3 parameters: number of states Ns, number of actions Na, and maximum branching factor Nb. We construct the transition function p(x, a, x′ ) to mimic dynamical systems where an action moves the state to states that are close by. Given a state x, next states are generated by sampling Nb times from a Gaussian distribution centered at x. The probabilities of going to each of the next states are chosen uniformly at random from [0, 1] and then normalized to 1. For every action a, we construct the reward r(x, a) by sampling at random 20% of the states and randomly assigning them rewards of 1 or -1. Everywhere else the reward is 0. For such MDPs, we compute π⋆ and V ⋆ using exact policy iteration and we measure the performance of the policy πalg returned by any of the algorithms as the normalized average error Erralg = E[V ∗-V πalg ] E[V ∗ ] . In the following, we use Ns = 15, Na = 3, Nb(s) ∈ [3, 6] and we estimate Erralg over 100 independent runs, while error bars are computed as 95% Gaussian confidence intervals.
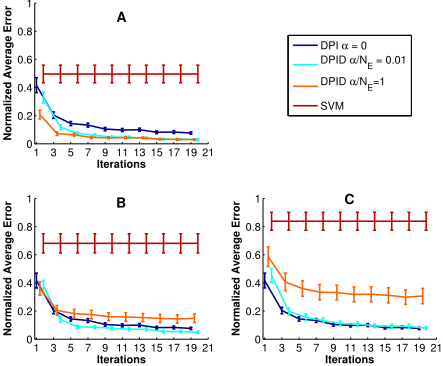
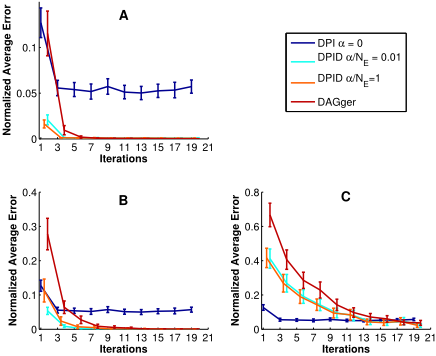
We start with a set of experiments where the exact state representation is used (i.e., no approximation error). This means that all algorithms have the potential to reach a zero error as the number of samples increases thus avoiding confounding effects due to the specific choice of feature design. In Fig.1A we compare DPID with DPI and pure imitation learning (implemented with SVM [Chang and Lin, 2011]) when the expert is optimal and number of demonstrations is small (NE = 15) and fixed, while the RL samples are increased at every iteration by 50. While DPI and DPID both perform better than imitation learning, DPID achieves the best performance thanks to the positive bias provided by the expert demonstrations. As expected, the greater the weight of expert demonstrations the stronger the bias in initial iterations, although they later converge to the same performance. In Fig.1B and C, we replace the optimal expert with a suboptimal one by sampling random non-optimal actions 25% and 50% of the time respectively. Since α rules the trade-off between RL and expert losses, we can see that depending on α, DPID performs either better (B, α small), similarly (C, α small), or worse (B and C, α large) than DPI. In Fig.2A we fix the total number of samples N = NRL + NE = 1500, but change the proportion of expert to RL samples, starting from NE = 50 up to 1000. As the number of expert samples increases, DPID and DAGGER converge to the optimal policy, however DPI reaches a plateau due to the variance caused by the limited number of samples. In Fig. 2B and C we replace the optimal expert with a suboptimal one. All algorithms have errors that decrease with increasing expert samples. However, DAGGER performs the worst and DPID with a small α converges the best. In B the expert is good enough to guide towards the optimal policy, while in C it induces a bias and slows down the convergence.
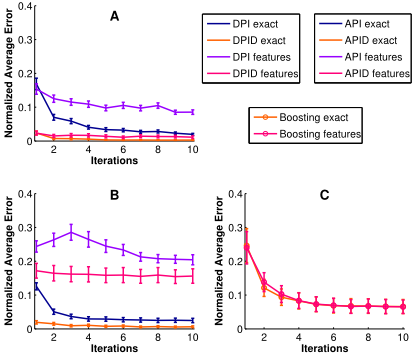
We now introduce an approximate representation such that for every state, we construct a binary feature vector of length d = 6 < Ns. The number of ones in the representation is set to l = 3 and their locations are chosen randomly as in [Bhatnagar et al., 2009]. Fig. 3A compares the performance of DPI and DPID with or without features in the same setting as Fig. 1A. We notice that DPI is significantly affected by the bias introduced by the features, but DPID is barely so and converges to the optimal policy. In B we compare LSPI (which corresponds to APID with α = 0) and APID. Here both algorithms are affected by the bias, but APID is still better than LSPI in both cases. In C we show the performance of RLED, which does not use our representation since it constructs features automatically even in the exact representation case. We note the different effect that feature design had on the different algorithms, with DPID being the most robust.
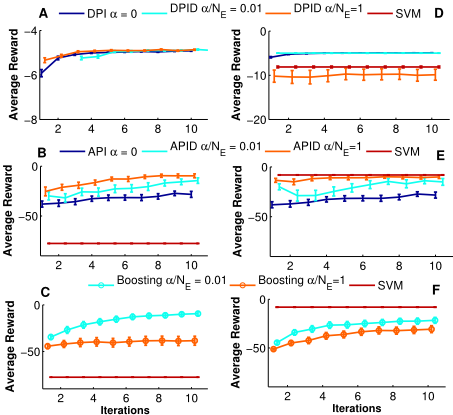
Vehicle Brake Control domain. In this domain, the state space is continuous and consists of a 4-dimensional vector representing the current velocity, the acceleration pedal value, the brake pedal value, and the target velocity. The goal of the agent is to reach the target velocity and maintain it. There are 5 actions available: acceleration up, acceleration down, brake up, brake down, do nothing. The reward equals -10 times the absolute difference between the current and the target velocity. As in [Kim et al., 2013] the expert is implemented using the dynamics of the pedal pressure and the velocity output with the addition of random noise. We compare the performances of DPID, APID, and RLED. As in [Kim et al., 2013] we use Radial Basis Functions to represent the state in APID. Fig. 4A and D are the DPID experiments and show the results of using an optimal and suboptimal expert respectively. This domain turns out to be easy for our classificationbased algorithm which converges quickly to a very good policy. In D, a larger α hurts the performance possibly because the expert biases the sampling process and renders RL useless. B and E show the results of APID, which seems to be less suited to this problem and converge very slowly. Expert samples help in both cases, with larger α performing better. Finally, C and F are the results of RLED. The performance is similar to that of APID which is unsurprising because they are both estimating the same quantity. Surprisingly, a larger α leads to worse performance in both cases. Although the comparison among these methods is partially biased by the difference in the underlying learning schemes (classificationbased vs projected Bellman residual minimization vs optimal Bellman residual minimization), these results show that DPID is very effective in integrating RL and expert data and it is relatively robust to expert sub-optimality and poor choice of α.
6 Conclusion
In this paper, we introduced DPID that naturally integrates RL and expert data. We provided a full analysis of the propagation error which resulted in insightful bounds. In particular, the impact of α suggests that a natural improvement on DPID would be to adapt α over iterations depending on the quality of the current policy compared to the expert policy. A principled solution may take inspiration from conservative policy iteration [Kakade and Langford, 2002], where monotonic policy improvement is guaranteed at each iteration. Finally, we showed empirically that even a few or suboptimal expert demonstrations can lead to significant improvements and that DPID compares favorably to APID and RLED.
Acknowledgments
This work was supported by the French Ministry of Higher Education and Research and the French National Research Agency (ANR) under project ExTra-Learn n.ANR-14-CE24-0010-01.
A Proofs
We first introduce two technical lemma whose proofs follow exactly the same steps as in Lemma 1 of [Lazaric et al., 2010].
Lemma 2. Let {xi}NRL i=1 be a rollout set sampled from ρ. If in each state we simulate M truncated rollouts, then
Proof of Theorem 1.
where ϵall = ϵ1RL + ϵ1E + ϵ2RL . The last inequality holds for any policy π, in particular πRL k+1 or πE k+1 which completes the proof.
Proof of Lemma 1. The second statement is proved in Section 4.2 of [Lazaric et al., 2010], while the first statement is obtained from
Proof of Theorem 2. We rewrite the right-hand side of the first statement of Lem. 1 as
and we introduce
Then Lem. 1 can be written in a more compact way as
̂πk (̂
Now we can apply Lem. 1 recursively and obtain
At each application of Lem. 1, we generate additional elements similar to the second term in the previous equation, and thus
As a direct application of the previous inequality, we bound the absolute value of the performance loss of DPID after K iterations and then take the η-norm, thus concluding the proof.
@inproceedings{ijcai2015p476,
  title     = {Direct Policy Iteration with Demonstrations},
  author    = {Chemali, Jessica and Lazaric, Alessandro},
  booktitle = {Proceedings of the Twenty-Fourth International Joint Conference on
               Artificial Intelligence, {IJCAI-15}},
  publisher = {International Joint Conferences on Artificial Intelligence},
  editor    = {Qiang Yang and Michael Wooldridge},
  pages     = {3380--3385},
  year      = {2015},
  month     = {7},
  note      = {Special Track on Machine Learning},
  url       = {https://ijcai.org/proceedings/2015/476},
}
TY - CPAPER TI - Direct Policy Iteration with Demonstrations AU - Chemali, Jessica AU - Lazaric, Alessandro T2 - Proceedings of the Twenty-Fourth International Joint Conference on Artificial Intelligence, IJCAI-15 PB - International Joint Conferences on Artificial Intelligence PY - 2015 SP - 3380 EP - 3385 UR - https://ijcai.org/proceedings/2015/476 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





