
Three Generalizations of the FOCUS Constraint
Proceedings of the Twenty-Third International Joint Conference on Artificial Intelligence. Pages 630-635.
Abstract
The FOCUS constraint expresses the notion that solutions are concentrated. In practice, this constraint suffers from the rigidity of its semantics. To tackle this issue, we propose three generalizations of the FOCUS constraint. We provide for each one a complete filtering algorithm as well as discussing decompositions.
- FILTERING(X, yc , len, k , h): Set of variables 1 pre := MINCARDS(X, len, k, h) ; 2 Integer lb := min(pre-1]
- if min(yc ) < lb then D(yc ) := D(yc ) \ [min(yc ), lb[; (yc )
- [Dasgupta et al., 2006] S. Dasgupta, C.H. Papadimitriou, and U.V. Vazirani. Algorithms. McGraw-Hill, 2006.
- [De Clercq et al., 2011] A. De Clercq, T. Petit, N. Beldiceanu, and N. Jussien. Filtering algorithms for discrete cumulative problems with overloads of resource. In Proc. CP, pages 240-255, 2011.
- [Narodytska et al., 2013] N. Narodytska, T. Petit, M. Siala, and T. Walsh. Three generalizations of the focus con- straint. Technical report, Avalaible online from CoRR, 2013.
- [Pesant and Régin, 2005] G. Pesant and J.-C. Régin. Spread: A balancing constraint based on statistics. In Proc. CP, pages 460-474, 2005.
- [Petit and Poder, 2008] T. Petit and E. Poder. Global propa- gation of practicability constraints. In Proc. CPAIOR, vol- ume 5015, pages 361-366, 2008.
- [Petit and Régin, 2011] T. Petit and J.-C. Régin. The ordered distribute constraint. International Journal on Artificial Intelligence Tools, 20(4):617-637, 2011.
- [Petit, 2012] T. Petit. Focus: A constraint for concentrating high costs. In Proc. CP, pages 577-592, 2012.
- [Régin, 1996] J.-C. Régin. Generalized arc consistency for global cardinality constraint. In Proceedings of the 14th National Conference on Artificial intelligence (AAAI'98), pages 209-215, 1996.
- [Schaus et al., 2007] P. Schaus, Y. Deville, P. Dupont, and J-C. Régin. The deviation constraint. In Proc. CPAIOR, volume 4510, pages 260-274, 2007.
- [and thus some harder ones) should be penalized. Schaus et al., 2009] P. Schaus, P. Van Hentenryck, and J-C. Régin. Scalable load balancing in nurse to patient assign- ment problems. In Proc. CPAIOR, volume 5547, pages 248-262, 2009.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Many discrete optimization problems have constraints on the objective function. Being able to represent such constraints is fundamental to deal with many real world industrial problems. Constraint programming is a promising approach to express and filter such constraints. In particular, several constraints have been proposed for obtaining well-balanced solutions [Pesant and R´egin, 2005; Schaus et al., 2007; Petit and R´egin, 2011]. Recently, the FOCUS constraint [Petit, 2012] was introduced to express the opposite notion. It captures the concept of concentrating the high values in a sequence of variables to a small number of intervals. We recall its definition. Throughout this paper, X = [x0, x1, . . . , xn-1] is a sequence of variables and si,j is a sequence of indices of consecutive variables in X, such that si,j = [i, i + 1, . . . , j], 0 ≤ i ≤ j < n. We let |E| be the size of a collection E.
Definition 1 ([Petit, 2012]). Let yc be a variable. Let k and len be two integers, 1 ≤ len ≤ |X|. An instantiation of X ∪ {yc} satisfies FOCUS(X, yc, len, k) iff there exists a set SX of disjoint sequences of indices si,j such that three conditions are all satisfied: (1) |SX| ≤ yc (2) ∀xl ∈ X, xl > k ⇔ ∃si,j ∈ SX such that l ∈ si,j (3) ∀si,j ∈ SX, j -i+1 ≤ len
FOCUS can be used in various contexts including cumulative scheduling problems where some excesses of capacity can be tolerated to obtain a solution [Petit, 2012]. In Thierry Petit LINA-CNRS Mines-Nantes, INRIA Nantes, France thierry.petit@mines-nantes.fr Toby Walsh NICTA and UNSW Sydney, Australia toby.walsh@nicta.com.au a cumulative scheduling problem, we are scheduling activities, and each activity consumes a certain amount of some resource. The total quantity of the resource available is limited by a capacity. Excesses can be represented by variables [De Clercq et al., 2011]. In practice, excesses might be tolerated by, for example, renting a new machine to produce more resource. Suppose the rental price decreases proportionally to its duration: it is cheaper to rent a machine during a single interval than to make several rentals. On the other hand, rental intervals have generally a maximum possible duration. FOCUS can be set to concentrate (non null) excesses in a small number of intervals, each of length at most len.
Unfortunately, the usefulness of FOCUS is hindered by the rigidity of its semantics. For example, we might be able to rent a machine from Monday to Sunday but not use it on Friday. It is a pity to miss such a solution with a smaller number of rental intervals because FOCUS imposes that all the variables within each rental interval take a high value. Moreover, a solution with one rental interval of two days is better than a solution with a rental interval of four days. Unfortunately, FOCUS only considers the number of disjoint sequences, and does not consider their length.
We tackle those issues here by means of three generalizations of FOCUS. SPRINGYFOCUS tolerates within each sequence in si,j ∈ SX some values v ≤ k. To keep the semantics of grouping high values, their number is limited in each si,j by an integer argument. WEIGHTEDFOCUS adds a variable to count the length of sequences, equal to the number of variables taking a value v > k. The most generic one, WEIGHTEDSPRINGYFOCUS, combines the semantics of SPRINGYFOCUS and WEIGHTEDFOCUS. Propagation of constraints like these complementary to an objective function is well-known to be important [Petit and Poder, 2008; Schaus et al., 2009]. We present and experiment with filtering algorithms and decompositions therefore for each constraint.
2 Springy FOCUS
In Definition 1, each sequence in SX contains exclusively values v > k. In many practical cases, this property is too strong. Consider one simple instance of the problem in the introduc-
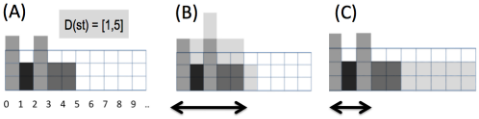
tion, in Figure 1, where one variable xi ∈ X is defined per point in time i (e.g., one day), to represent excesses of capacity. Inintialy, 4 activities are fixed and one activity a remains to be scheduled (drawing A), of duration 5 and that can start from day 1 to day 5. If FOCUS(X, yc = 1, 5, 0) is imposed then a must start at day 1 (solution B). We have one 5 day rental interval. Assume now that the new machine may not be used every day. Solution (C) gives one rental of 3 days instead of 5. Furthermore, if len = 4 the problem will have no solution using FOCUS, while this latter solution still exists in practice. This is paradoxical, as relaxing the condition that sequences in the set SX of Definition 1 take only values v > k deteriorates the concentration power of the constraint. Therefore, we propose a soft relaxation of FOCUS, where at most h values less than k are tolerated within each sequence in SX .
Definition 2. Let yc be a variable and k, len, h be three integers, 1 ≤ len ≤ |X|, 0 ≤ h < len-1. An instantiation of X ∪{yc} satisfies SPRINGYFOCUS(X, yc, len, h, k) iff there exists a set SX of disjoint sequences of indices si,j such that four conditions are all satisfied: (1) |SX| ≤ yc (2) ∀xl ∈ X, xl > k ⇒ ∃si,j ∈ SX such that l ∈ si,j (3) ∀si,j ∈ SX, j - i + 1 ≤ len, xi > k and xj > k. (4) ∀si,j ∈ SX, |{l ∈ si,j , xl ≤ k}| ≤ h
Bounds consistency (BC) on SPRINGYFOCUS is equivalent to domain consistency: any solution can be turned into a solution that only uses the lower bound min(xl) or the upper bound max(xl) of the domain D(xl) of each xl ∈ X (this observation was made for FOCUS [Petit, 2012]). Thus, we propose a BC algorithm. The first step is to traverse X from x0 to xn-1, to compute the minimum possible number of disjoint sequences in SX (a lower bound for yc), the focus cardinality, denoted fc(X). We use the same notation for subsequences of X. fc(X) depends on k, len and h.
Definition 3. Given xl ∈ X, we consider three quantities. (1) p(xl, v≤) is the focus cardinality of [x0, x1, . . . , xl], assuming xl ≤ k, and ∀si,j ∈ S[x0,x1,...,xl], j ̸= l. (2) pS(xl, v≤) is the focus cardinality of [x0, x1, . . . , xl], assuming xl ≤ k and ∃i, si,l ∈ S[x0,x1,...,xl]. (3) p(xl, v>) is the focus cardinality of [x0, x1, . . . , xl] assuming xl > k .
Any quantity is equal to n + 1 if the domain D(xl) of xl makes not possible the considered assumption.
1 pre := new Integer[|X|][4][] ; 2 for l ∈ 0..n- 1 do 3 pre[l][0] := new Integer[2]; 4 for j ∈ 1..3 do pre[l][j] := new Integer[1]; 5 ; 6 Initialization Lemma 1,; 7 for l ∈ 1..n- 1 do Lemmas 2, 3, 4 and Propositions 1 and 2.; 8 ; 9 return pre;To compute the quantities of Definition 3 for xl∈X we use plen(xl), the minimum length of a sequence in S[x0,x1,...,xl] containing xl among instantiations of [x0, x1, . . . , xl] where the number of sequences is fc([x0, x1, . . . , xl]). plen(xl)=0 if ∀si,j ∈ S[x0,x1,...,xl], j ̸= l. card(xl) is the minimum number of values v ≤ k in the current sequence in S[x0,x1,...,xl], equal to 0 if ∀si,j ∈ S[x0,x1,...,xl], j ̸= l. card(xl) assumes that xl > k. It has to be decreased it by one if xl ≤ k. For sake of space, the proofs of the next four lemmas are given in a technical report [Narodytska et al., 2013].
Lemma 1 (initialization). p(x0, v≤) = 0 if min(x0) ≤ k, and n + 1 otherwise; pS(x0, v≤) = n + 1; p(x0, v>) = 1 if max(x0) > k and n + 1 otherwise; plen(x0) = 1 if max(x0) > k and 0 otherwise; card(x0) = 0.
Lemma 2 (p(xl, v≤)). If min(xl) ≤ k then p(xl, v≤) = min(p(xl-1, v≤), p(xl-1, v>)), else p(xl, v≤) = n + 1.
Lemma 3 (pS(xl, v≤)). If min(xi)>k, pS(xi, v≤)=n+1. Otherwise, if plen(xi-1) ∈ {0, len - 1, len} ∨ card(xi-1) = h then pS(xi, v≤) = n + 1, else pS(xi, v≤) = min(pS(xi-1, v≤), p(xi-1, v>)).
Lemma 4 (p(xl, v>)). If max(xl) ≤ k then p(xl, v>)=n+1. Otherwise, If plen(xl-1) ∈ {0, len}, p(xl, v>) = min(p(xl-1, v>) + 1, p(xl-1, v≤) + 1), else p(xl, v>) = min(p(xl-1, v>), pS(xl-1, v≤), p(xl-1, v≤) + 1).
Proposition 1 (plen(xl)). (by construction) If min (pS(xl-1, v≤),p(xl-1, v>))<p(xl-1,v≤)+1∧plen(xl-1)< len then plen(xl) = plen(xl-1) + 1. Otherwise, if p(xl, v>)) < n + 1 then plen(xl) = 1, else plen(xl) = 0.
Proposition 2 (card(xl)). (by construction) If plen(xl) = 1 then card(xl) = 0. Otherwise, if p(xl, v>) = n + 1 then card(xl) = card(xl-1) + 1, else card(xl) = card(xl-1).
Algorithm 1 implements the lemmas with pre[l][0][0] = p(xl, v≤), pre[l][0][1] = pS(xl, v≤), pre[l][1] = p(xl, v>), pre[l][2] = plen(xl), pre[l][3] = card(xl).
The principle of Algorithm 2 is the following. First, lb = f c(X) is computed with xn-1. We execute Algorithm 1 from x0 to xn-1 and conversely (arrays pre and suf ). We thus
Algorithm 2: FILTERING(X, yc, len, k, h): Set of variables
1 pre :=MINCARDS(X, len, k, h) ; 2 Integer lb :=min(pre[n- 1][0][0], pre[n- 1][1]); 3 if min(yc) < lb then D(yc) :=D(yc) \ [min(yc), lb[; 4 ; 5 if min(yc) = max(yc) then 6 suf :=MINCARDS([xn-1, xn-2, . . . , x0], len, k, h) ; 7 for l ∈ 0..n - 1 do 8 if pre[l][0][0] + suf [n - 1 - l][0][0] > max(yc) then 9 Integer regret :=0; Integer add :=0; 10 if pre[l][1] ≤ pre[l][0][1] then add :=add+1; 11 ; 12 if suf [n- 1 - l][1] ≤ suf [n- 1 - l][0][1] then add:=add+1; 13 ; 14 if pre[l][2] + suf [n - 1 - l][2] - 1 ≤ len ∧ pre[l][3] + suf [n - 1 - l][3] + add - 1 ≤ h then regret := 1; 15 ; 16 if pre[l][0][1] + suf [n - 1 - l][0][1] - regret > max(yc ) then D(xi) :=D(xi)\ [min(xi), k]; 17 ; 18 Integer regret :=0; 19 if pre[l][2] + suf [n - 1 - l][2] - 1 ≤ len ∧ pre[l][3] + suf [n- 1 - l][3] - 1≤ h then regret :=1; 20 ; 21 if pre[l][1] + suf [n - 1 - l][1] - regret > max(yc ) then 22 D(xi) :=D(xi)\ ]k,max(xi)]; 23 returnX ∪ {yc};have for each quantity two values for each variable xl. To aggregate them, we implement regret mechanisms directly derived from Propositions 2 and 1, according to the parameters len and h. Line 4 is optional but it avoids some work when the variable yc is fixed, thanks to the same property as FOCUS (see [Petit, 2012]). Algorithm 2 performs a constant number of traversals of the set X. Its time complexity is O(n), which is optimal.
3 Weighted FOCUS
We present WEIGHTEDFOCUS, that extends FOCUS with a variable zc limiting the the sum of lengths of all the sequences in SX, i.e., the number of variables covered by a sequence in SX. It distinguishes between solutions that are equivalent with respect to the number of sequences in SX but not with respect to their length, as Figure 2 shows.
Definition 4. Let yc and zc be two integer variables and k, len be two integers, such that 1 ≤ len ≤ |X|. An instantiation of X ∪ {yc} ∪ {zc} satisfies WEIGHTEDFOCUS(X, yc, len, k, zc) iff there exists a set SX of disjoint sequences of indices si,j such that four conditions are all satisfied: (1) |SX| ≤ yc (2) ∀xl ∈ X, xl > k ⇔ ∃si,j ∈ SX such that l ∈ si,j (3) ∀si,j ∈ SX, j -i+1 ≤ len (4) ∑si,j∈SX |si,j | ≤ zc .
Definition 5 ([Petit, 2012]). Given an integer k, a variable xl ∈ X is: Penalizing, (Pk), iff min(xl) > k. Neutral, (Nk), iff max(xl) ≤ k. Undetermined, (Uk), otherwise. We say xl ∈ Pk iff xl is labeled Pk, and similarly for Uk and Nk.
Dynamic Programming (DP) Principle Given a partial instantiation IX of X and a set of sequences SX that covers all penalizing variables in IX, we consider two terms:
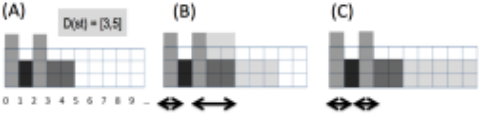
the number of variables in Pk and the number of undetermined variables, in Uk, covered by SX. We want to find a set SX that minimizes the second term. Given a sequence of variables si,j, the cost cst(si,j) is defined as cst(si,j) = {p|xp ∈ Uk, xp ∈ si,j}. We denote cost of SX, cst(SX), the sum cst(SX) = ∑si,j∈SX cst(si,j). Given IX we consider |Pk| = |{xi ∈ Pk}|. We have: ∑si,j∈S |si,j| = ∑si,j∈S cst(si,j ) + |Pk|.
We start with explaining the main difficulty in building a propagator for WEIGHTEDFOCUS. The constraint has two optimization variables in its scope and we might not have a solution that optimizes both variables simultaneously.
Example 1 suggests that we need to fix one of the two optimization variables and only optimize the other one. Our algorithm is based on a dynamic program [Dasgupta et al., 2006]. For each prefix of variables [x0, x1, . . . , xj] and given a cost value c, it computes a cover of focus cardinality, denoted Sc,j, which covers all penalized variables in [x0, x1, . . . , xj] and has cost exactly c. If Sc,j does not exist we assume that Sc,j =∞. Sc,j is not unique as Example 2 demonstrates.
Example 2. Consider X = [x0, x1, . . . , x7] and WEIGHTEDFOCUS(X, [2, 2], 5, 0, [7, 7]), with D(xi) = {1}, i ∈ I, I = {0, 2, 3, 5, 7} and D(xi) = {0, 1}, i ∈ {0, 1, . . . 7} \ I. Consider the subsequence of variables [x0, . . . , x5] and S1,5. There are several sets of minimum cardinality that cover all penalized variables in the prefix [x0, . . . , x5] and has cost 2, e.g. S1 1,5 = {s0,2, s3,5} or S2 1,5 = {s0,4, s5,5}. Assume we sort sequences by their starting points in each set. We note that the second set is better if we want to extend the last sequence in this set as the length of the last sequence s5,5 is shorter compared to the length of the last sequence in S1 1,5 , which is s3,5.
Example 2 suggests that we need to put additional conditions on Sc,j to take into account that some sets are better than others. We can safely assume that none of the sequences in Sc,j starts at undetermined variables as we can always set it to zero. Hence, we introduce a notion of an ordering between sets Sc,j and define conditions that this set has to satisfy.
Ordering of sequences in Sc,j. We introduce an order over sequences in Sc,j. Given a set of sequences in Sc,j we sort them by their starting points. We denote last(Sc,j) the last sequence in Sc,j in this order. If xj ∈ last(Sc,j) then |last(Sc,j)| is, naturally, the length of last(Sc,j), otherwise |last(Sc,j )| = ∞.
Ordering of sets Sc,j , c ∈ [0, max(zc)], j ∈ {0, 1, . . . , n1}. We define a comparison operation between two sets Sc,j and Sc′ ,j ′ . Sc,j ≤ Sc′ ,j ′ iff |Sc,j| < |Sc′ ,j ′ | or |Sc,j| = |Sc′ ,j ′ | and last(Sc,j) ≤ last(Sc′ ,j ′). Note that we do not take account of cost in the comparison as the current definition is sufficient for us. Using this operation, we can compare all sets Sc,j and S′c,j of the same cost for a prefix [x0, . . . , xj ]. We say that Sc,j is optimal iff satisfies the following 4 conditions.
Proposition 3 (Conditions on Sc,j ).
- Sc,j covers all Pk variables in [x0, x1, . . . , xj],
- cst(Sc,j) = c,
- ∀sh,g ∈ Sc,j, xh /∈ Uk,
- Sc,j is the first set in the order among all sets that satisfy conditions 1-3.
As can be seen from definitions above, given a subsequence of variables x0, . . . , xj, Sc,j is not unique and might not exist. However, if |Sc,j| = |Sc′ ,j ′ |, c = c′ and j = j ′ , then last(Sc,j) = last(Sc′ ,j ′ ).
Example 3. Consider WEIGHTEDFOCUS from Example 2. Consider the subsequence [x0, x1]. S0,1 = {s0,0}, S1,1 = {s0,1}. Note that S2,1 does not exist. Consider the subsequence [x0, . . . , x5]. We have S0,5 = {s0,0, s2,3, s5,5}, S1,5 = {s0,4, s5,5} and S2,5 = {s0,3, s5,5}. By definition, last(S0,5) = s5,5, last(S1,5) = s5,5 and last(S2,5) = s5,5. Consider the set S1,5. Note that there exists another set S′1,5 = {s0,0, s2,5} that satisfies conditions 1-3. Hence, it has the same cardinality as S1,5 and the same cost. However, S1,5 < S′1,5 as |last(S1,5)| = 1 < |last(S′1,5 )| = 3.
Bounds disentailment Each cell in the dynamic programming table fc,j, c ∈ [0, z U c ], j ∈ {0, 1, . . . , n - 1}, where z U c = max(zc) - |Pk|, is a pair of values qc,j and lc,j, fc,j = {qc,j, lc,j}, stores information about Sc,j. Namely, qc,j = |Sc,j|, lc,j = |last(Sc,j)| if last(Sc,j) ̸= ∞ and ∞ otherwise. We say that fc,j/qc,j/lc,j is a dummy (takes a dummy value) iff fc,j = {∞,∞}/qc,j = ∞/lc,j = ∞. If y1 = ∞ and y2 = ∞ then we assume that they are equal. We introduce a dummy variable x-1, D(x-1) = {0} and a row f-1,j , j = -1, . . . , n - 1 to keep uniform notations.
Algorithm 3 gives pseudocode for the propagator. The intuition behind the algorithm is as follows. Again, by cost we mean the number of covered variables in Uk.
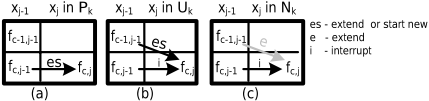
If xj ∈ Pk then we do not increase the cost of Sc,j compared to Sc,j-1 as the cost only depends on xj ∈ Uk. Hence, the best move for us is to extend last(Sc,j-1) or start a new
Algorithm 3: Weighted FOCUS(x0, . . . , xn-1)
1 for c ∈ -1..z U c do 2 for j ∈ -1..n - 1 do 3 fc,j ← {∞, ∞}; 4 f0,-1 ← {0, 0} ; 5 for j ∈ 0..n- 1 do 6 for c ∈ 0..j do 7 if xj ∈ Pk then /* penalizing */ 8 if (lc,j-1 ∈ [1, len)) ∨ (qc,j-1 = ∞) then 9 fc,j ← {qc,j-1, lc,j-1 + 1}; 10 else fc,j ← {qc,j-1 + 1, 1}; 11 ; 12 if xj ∈ Uk then /* undetermined */ 13 if (lc-1,j-1 ∈ [1, len) ∧ qc-1,j-1 = qc,j-1) ∨ (qc,j-1 = ∞) then fc,j ← {qc-1,j-1, lc-1,j-1 + 1} ; 14 else fc,j ← {qc,j-1,∞} ; 15 if xj ∈ Nk then /* neutral */ 16 fc,j ← {qc,j-1, ∞} 17 return f;sequence if it is possible. This is encoded in lines 9 and 10 of the algorithm. Figure 3(a) gives a schematic representation of these arguments.
If xj ∈ Uk then we have two options. We can obtain Sc,j from Sc-1,j-1 by increasing cst(Sc-1,j-1) by one. This means that xi will be covered by last(Sc,j). Alternatively, from Sc,j-1 by interrupting last(Sc,j-1). This is encoded in line 13 of the algorithm (Figure 3(b)).
If xj ∈ Nk then we do not increase the cost of Sc,j compared to Sc,j-1. Moreover, we must interrupt last(Sc,j-1), line 16 (Figure 3(c), ignore the gray arc).
First we prove a property of the dynamic programming table. We define a comparison operation between fc,j and fc′ ,j ′ induced by a comparison operation between Sc,j and Sc′ ,j ′ : fc,j ≤ fc′ ,j ′ if (qc,j < qc′ ,j ′) or (qc,j = qc′ ,j ′ and lc,j ≤ lc′ ,j ′ ). In other words, as in a comparison operation between sets, we compare by the cardinality of sequences, |Sc,j| and |Sc′ ,j ′ |, and, then by the length of the last sequence in each set, last(Sc,j) and last(Sc′ ,j ′). See [Narodytska et al., 2013] for the proofs of the next two lemmas.
Lemma 5. Consider WEIGHTEDFOCUS(X, yc, len, k, zc). Let f be dynamic programming table returned by Algorithm 3. Non-dummy elements fc,j are monotonically nonincreasing in each column, so that fc′ ,j ≤ fc,j , 0 ≤ c < c′ ≤ z U c , j = [0, . . . , n-1].
Lemma 6. Consider WEIGHTEDFOCUS(X, yc, len, k, zc). The dynamic programming table fc,j = {qc,j, lc,j} c ∈ [0, z U c ], j = 0, . . . , n - 1, is correct in the sense that if fc,j exists and it is non-dummy then a corresponding set of sequences Sc,j exists and satisfies conditions 1-4. The time complexity of Algorithm 3 is O(nmax(zc)).
Example 4. Table 1 shows an execution of Algorithm 3 on WEIGHTEDFOCUS from Example 2. Note that |P0| = 5. Hence, z U c = max(zc) - |P0| = 2. As can be seen from the table, the constraint has a solution as there exists a set S2,7 = {s0,3, s5,7} such that |S2,7| = 2.
Bounds consistency To enforce BC on variables x, we compute an additional DP table b, bc,j, c ∈ [0, z U c ], j ∈
| c | D(x0)D(x1)D(x2) [1, 1] [0, 1] [1, 1] | D(x3) [1, 1] | D(x4) [0, 1] | D(x5) [1, 1] | D(x6) [0, 1] | D(x7) [1, 1] |
| 0 1 z U c = 2 | {1, 1}{1,∞}{2, 1} {1, 2} {1, 3} | {2, 2} {1, 4} | {2,∞} {1,∞} {1, 5} | {3, 1} {2, 1} {2, 1} | {3,∞} {2,∞} {2, 2} | {4, 1} {3, 1} {2, 3} |
[-1, n - 1] on the reverse sequence of variables x.
Lemma 7. Consider WEIGHTEDFOCUS(X, yc, len, k, zc). Bounds consistency can be enforced in O(nmax(zc)) time.
Proof. (Sketch)We build dynamic programming tables f and b. We will show that to check if xi = v has a support it is sufficient to examine O(z U c ) pairs of values fc1,i-1 and bc2,n-i-2, c1, c2 ∈ [0, z U c ] which are neighbor columns to the ith column. It is easy to show that if we consider all possible pairs of elements in fc1,i-1 and bc2,n-i-2 then we determine if there exists a support for xi = v. There are O(z U c × z U c ) such pairs. The main part of the proof shows that it sufficient to consider O(z U c ) such pairs. In particular, to check a support for a variable-value pair xi = v, v > k, for each fc1,i-1 it is sufficient to consider only one element bc2,n-i-2 such that bc2,n-i-2 is non-dummy and c2 is the maximum value that satisfies inequality c1 +c2 +1 ≤ z U c . To check a support for a variable-value pair xi = v, v ≤ k, for each fc1,i-1 it is sufficient to consider only one element bc2,n-i-2 such that bc2,n-i-2 is non-dummy and c2 is the maximum value that satisfies inequality c1 + c2 ≤ z U c .
We observe a useful property of the constraint. If there exists fc,n-1 such that c < max(zc) and qc,n-1 < max(yc) then the constraint is BC. This follows from the observation that given a solution of the constraint SX, changing a variable value can increase cst(SX) and |SX| by at most one.
Alternatively we can decompose WEIGHTEDFOCUS using O(n) additional variables and constraints.
Proposition 4. Given FOCUS(X, yc, len, k), let zc be a variable and B=[b0, b1, . . . , bn-1] be a set of variables such that ∀bl∈B,D(bl)={0, 1}. WEIGHTEDFOCUS(X, yc, len, k, zc) ⇔ FOCUS(X, yc, len, k) ∧ [∀l, 0 ≤ l < n, [(xl ≤ k)∧(bl = 0)] ∨ [(xl > k ) ∧ (bl = 1)]] ∧ ∑l∈{0,1,...,n-1} bl ≤ zc .
Enforcing BC on each constraint of the decomposition is weaker than BC on WEIGHTEDFOCUS. Given xl ∈ X, a value may have a unique support for FOCUS which violates ∑l∈{0,1,...,n-1} bl ≤ zc, and conversely. Consider n=5, x0=x2=1, x3=0, and D(x1)=D(x4)={0, 1}, yc=2, zc=3, k=0 and len=3. Value 1 for x4 corresponds to this case.
4 Weighted Springy FOCUS
We consider a further generalization of the FOCUS constraint that combines SPRINGYFOCUS and WEIGHTEDFOCUS. We prove that we can propagate this constraint in O(nmax(zc)) time, which is same as enforcing BC on WEIGHTEDFOCUS.
Definition 6. Let yc and zc be two variables and k, len, h be three integers, such that 1 ≤ len ≤ |X| and 0 < h < len - 1. An instantiation of X ∪ {yc} ∪ zc satisfies WEIGHTEDSPRINGYFOCUS(X, yc, len, h, k, zc) iff there exists a set SX of disjoint sequences of indices si,j such that five conditions are all satisfied: (1) |SX| ≤ yc (2) ∀xl ∈ X, xl > k ⇒ ∃si,j ∈ SX such that l ∈ si,j (3) ∀si,j ∈ SX, |{l ∈ si,j, xl ≤ k}| ≤ h (4) ∀si,j ∈ SX, j - i + 1 ≤ len, xi > k and xj > k. (5) ∑si,j∈SX |si,j| ≤ zc.
We can again partition cost of S into two terms. ∑si,j∈S |si,j| = ∑si,j∈S cst(si,j) + |Pk|. However, cst(si,j) is the number of undetermined and neutral variables covered si,j , cst(si,j) = {p|xp ∈ Uk ∪ Nk, xp ∈ si,j} as we allow to cover up to h neutral variables.
The propagator is again based on a dynamic program that for each prefix of variables [x0, x1, . . . , xj] and given cost c computes a cover Sc,j of minimum cardinality that covers all penalized variables in the prefix [x0, x1, . . . , xj] and has cost exactly c. We face the same problem of how to compare two sets S1 c,j and S2 c,j of minimum cardinality. The issue here is how to compare last(S1 c,j ) and last(S2 c,j ) if they cover a different number of neutral variables. Luckily, we can avoid this problem due to the following monotonicity property. If last(S1 c,j ) and last(S2 c,j ) are not equal to infinity then they both end at the same position j. Hence, if last(S1 c,j ) ≤ last(S2 c,j ) then the number of neutral variables covered by last(S1 c,j ) is no larger than the number of neutral variables covered by last(S2 c,j ). Therefore, we can define order on sets Sc,j as we did in Section 3 for WEIGHTEDFOCUS.
Our bounds disentailment detection algorithm for WEIGHTEDSPRINGYFOCUS mimics Algorithm 3. We omit the pseudocode due to space limitations but highlight two not-trivial differences between this algorithm and Algorithm 3. The first difference is that each cell in the dynamic programming table fc,j, c ∈ [0, z U c ], j ∈ {0, 1, . . . , n - 1}, where z U c = max(zc) - |Pk|, is a triple of values qc,j, lc,j and hc,j, fc,j = {qc,j, lc,j, hc,j}. The new parameter hc,j stores the number of neutral variables covered by last(Sc,j). The second difference is in the way we deal with neutral variables. If xj ∈ Nk then we have two options now. We can obtain Sc,j from Sc-1,j-1 by increasing cst(Sc-1,j-1) by one and increasing the number of covered neutral variables by last(Sc,j-1) (Figure 3(c), the gray arc). Alternatively, we can obtain Sc,j from Sc,j-1 by interrupting last(Sc,j-1) (Figure 3(c), the black arc). BC can enforced using two modifications of the corresponding algorithm for WEIGHTEDFOCUS (a proof is given in [Narodytska et al., 2013]).
Lemma 8. Consider WEIGHTEDSPRINGYFOCUS(X, yc, len, h, k , zc). BC can be enforced in O(nmax(zc)) time.
WEIGHTEDSPRINGYFOCUS can be encoded using the cost-REGULAR constraint. The automaton needse 3 counters to compute len, yc and h. Hence, the time complexity of this encoding is O(n4 ). This automaton is non-deterministic as on seeing v ≤ k, it either covers the variable or interrupts the last sequence. Unfortunately the non-deterministic costREGULAR is not implemented in any constraint solver to our knowledge. In contrast, our algorithm takes just O(n2 ) time. WEIGHTEDSPRINGYFOCUS can also be decomposed using the GCC constraint [R´egin, 1996]. We define the following variables for all i ∈ [0,max(yc)-1] and j ∈ [0, n-1]: Si the start of the ith sub-sequence. D(Si) = {0, .., n+max(yc)}; Ei the end of the ith sub-sequence. D(Ei) = {0, .., n + max(yc)}; Tj the index of the subsequence in SX containing xj. D(Tj) = {0, ..,max(yc)}; Zj the index of the subsequence in SX containing xj s.t. the value of xj is less than or equal to k. D(Zj) = {0, ..,max(yc)}; lastc the cardinality of SX. D(lastc) = {0, ..,max(yc)}; Card, a vector of max(yc) variables having {0, .., h} as domains. WEIGHTEDSPRINGYFOCUS(X, yc , len, h, k , zc) ⇔
5 Experiments
We used the Choco-2.1.5 solver on an IntelXeon 2.27GHz for the first benchmarks and IntelXeon 3.20GHz for last ones, both under Linux. We compared the propagators (denoted by F) of WEIGHTEDFOCUS and WEIGHTEDSPRINGYFOCUS against two decompositions (denoted by D1 and D2), using the same search strategies, on three different benchmarks. The first decomposition, restricted to WEIGHTEDFOCUS, is shown in proposition 4, while the second one is shown in Section 4. In the tables, we report for each set the total number of solved instances (#n), then we average both the number of backtracks (#b) and the resolution time (T) in seconds.
✷ Sports league scheduling (SLS). We extend a single roundrobin problem with n = 2p teams. Each week each team plays a game either at home or away. Each team plays exactly once all the other teams during a season. We minimize the number of breaks (a break for one team is two consecutive home or two consecutive away games), while fixed weights in {0, 1} are assigned to all games: games with weight 1 are important for TV channels. The goal is to group consecutive weeks where at least one game is important (sum of weights > 0), to increase the price of TV broadcast packages. Packages are limited to 5 weeks and should be as short as possible. Table 2 shows results with 16 and 20 teams, on sets of 50 instances with 10 random important games and a limit of 400K backtracks. max(yc) = 3 and we search for one solution with h ≤ 7 (instances n-1), h ≤ 6 (n-2) and h ≤ 5 (n-3). In our model, inverse-channeling and ALLDIFFERENT constraints with the strongest propagation level express that each team plays once against each other team. We assign first the sum of breaks by team, then the breaks and places.
✷ Cumulative Scheduling with Rentals. Given a horizon of n days and a set of time intervals [si, ei], i ∈ {1, 2, . . . , p}, a company needs to rent a machine between li and ui times within each time interval [si, ei]. We assume that the cost of the rental period is proportional to its length. On top of this, each time the machine is rented we pay a fixed cost. The problem is then defined as a conjunction of one WEIGHTEDSPRINGYFOCUS(X, yc, len, h, 0, zc) with a set of AMONG constraints. The goal is to build a schedule for rentals that satisfies all demand constraints and minimizes simultaneously the number of rental periods and their total length. We build a Pareto frontier over two cost variables, as Figure 4 shows for one of the instances of this problem. We generated instances having a fixed length of sub-sequences of size 20 (i.e., len = 20), 50% as a probability of posting an Among constraint for each (i, j) s.t. j ≥ i+5 in the sequence. Each set of instances corresponds to a unique sequence size ({40, 43, 45, 47, 50}) and 20 different seeds. We summarize these tests in table 3. Results with decomposition are very poor. We therefore consider only the propagator in this case. ✷ Sorting Chords. We need to sort n distinct chords. Each chord is a set of at most p notes played simultaneously. The goal is to find an ordering that minimizes the number of notes changing between two consecutive chords. The full description and a CP model is in [Petit, 2012]. The main difference here is that we build a Pareto frontier over two cost variables. We generated 4 sets of instances distinguished by the numbers of chords ({14, 16, 18, 20}). We fixed the length of the subsequences and the maximum notes for all the sets then change the seed for each instance.
| 16 1 | 16 2 | 16 3 | |||||||
|---|---|---|---|---|---|---|---|---|---|
| #n | #b | T | #n | #b | T | #n | #b | T | |
| F | 50 | 0.9K | 0 | 50 | 4.1K | 2 | 47 | 18.1K | 7 |
| D1 | 50 | 3.4K | 1 | 49 | 8.1K | 3 | 44 | 21.8K | 8 |
| 20 1 | 20 2 | 20 3 | |||||||
| #n | #b | T | #n | #b | T | #n | #b | T | |
| F | 49 | 11.8K | 7 | 45 | 24.9K | 14 | 39 | 36.5K | 23 |
| D1 | 43 | 30.8K | 13 | 35 | 27.2K | 12 | 29 | 29.6K | 17 |
| 40 | 43 | 45 | ||||||||
|---|---|---|---|---|---|---|---|---|---|---|
| h | #n | #b | T | #n | #b | T | #n | #b | T | |
| 0 | F | 20 | 349K | 55.4 | 20 | 1M | 192.2 | 20 | 1M | 233.7 |
| 0 | D1 | 20 | 529K | 74.7 | 20 | 1M | 251.2 | 20 | 1M | 328.6 |
| 1 | F | 20 | 827M | 120.4 | 20 | 2M | 420.9 | 19 | 3M | 545.9 |
| 2 | F | 20 | 826K | 115.7 47 | 20 | 2M | 427.3 | 19 | 3M | 571.3 |
| 50 | ||||||||||
| h | #n | #b | T | #n | #b | T | ||||
| 0 F | 19 | 1M | 354.5 | 18 | 2M | 553.7 | ||||
| 0 | D1 | 18 | 2M | 396.8 | 17 | 3M | 660 | |||
| 1 F | 16 | 4M | 725.4 | 4 | 6M | 984.5 | ||||
| 2 | F | 15 | 4M | 763.9 | 4 | 5M | 944.8 | |||
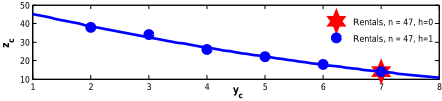
Tables 2, 3 and 4 show that best results were obtained with our propagators (number of solved instances, average backtracks and CPU time over all the solved instances 1 ). Figure 4
1 While the technique that solves the largest number of instances
| 14 | 16 | 18 | 20 | ||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| h | #n | #b | T | #n | #b | T | #n | #b | T | #n | #b | T | |
| 0 | F | 30 | 70K | 2.8 | 30 | 865K | 14.6 | 28 | 10M | 182.9 | 16 | 14M | 270.4 |
| 0 | D1 | 30 | 94K | 3.2 | 30 | 2M | 41 | 28 | 12M | 206.9 | 13 | 10M | 206.8 |
| 0 | D2 | 30 | 848K | 34.9 | 24 | 3M | 122.3 | 13 | 8M | 285.6 | 7 | 902K | 38.7 |
| 1 | F | 30 | 97K | 3.5 | 30 | 1K | 27.2 | 28 | 12K | 214.2 | 14 | 13M | 288.2 |
| 1 | D2 | 30 | 851M | 41.5 | 23 | 2M | 116.3 | 11 | 5M | 209.9 | 7 | 868K | 41.5 |
| 2 | F | 30 | 97K | 3.4 | 30 | 1M | 25.9 | 28 | 13M | 217.4 | 13 | 12M | 245.5 |
| 2 | D2 | 30 | 844K | 40.9 | 24 | 3M | 145.1 | 12 | 6K | 251.6 | 7 | 867K | 42.8 |
confirms the gain of flexibility illustrated by Figure 1 in Section 2: allowing h = 1 variable with a low cost value into each sequence leads to new solutions, with significantly lower values for the target variable yc.
6 Conclusion
We have presented flexible tools for capturing the concept of concentrating costs. Our contribution highlights the expressive power of constraint programming, in comparison with other paradigms where such a concept would be very difficult to represent. Our experiments have demonstrated the effectiveness of the proposed new filtering algorithms.
@inproceedings{ijcai2013p100,
  title     = {Three Generalizations of the FOCUS Constraint},
  author    = {Narodytska, Nina and Petit, Thierry and Siala, Mohamed and Walsh, Toby},
  booktitle = {Proceedings of the Twenty-Third International Joint Conference on
               Artificial Intelligence, {IJCAI-13}},
  publisher = {AAAI Press / International Joint Conferences on Artificial Intelligence},
  editor    = {Francesca Rossi},
  pages     = {630--635},
  year      = {2013},
  month     = {8},
  url       = {https://ijcai.org/proceedings/2013/100},
}
TY - CPAPER TI - Three Generalizations of the FOCUS Constraint AU - Narodytska, Nina AU - Petit, Thierry AU - Siala, Mohamed AU - Walsh, Toby T2 - Proceedings of the Twenty-Third International Joint Conference on Artificial Intelligence, IJCAI-13 PB - AAAI Press / International Joint Conferences on Artificial Intelligence PY - 2013 SP - 630 EP - 635 UR - https://ijcai.org/proceedings/2013/100 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





