
An Analysis of Laplacian Methods for Value Function Approximation in MDPs
Proceedings of the Twentieth International Joint Conference on Artificial Intelligence. Pages 2574-2578.
© 2007 International Joint Conferences on Artificial Intelligence
Abstract
Recently, a method based on Laplacian eigenfunctions was proposed to automatically construct a basis for value function approximation in MDPs. We show that its success may be explained by drawing a connection between the spectrum of the Laplacian and the value function of the MDP. This explanation helps us to identify more precisely the conditions that this method requires to achieve good performance. Based on this, we propose a modification of the Laplacian method for which we derive an analytical bound on the approximation error. Further, we show that the method is related the augmented Krylov methods, commonly used to solve sparse linear systems. Finally, we empirically demonstrate that in basis construction the augmented Krylov methods may significantly outperform the Laplacian methods in terms of both speed and quality.
- [Bertsekas and Tsitsiklis, 1996] Dimitri P. Bertsekas and John N. Tsitsiklis. Neuro-dynamic programming. Athena Scientific, 1996.
- [Chung, 1997] Fang Chung. Spectral graph theory. Ameri- can Mathematical Society, 1997.
- [Golub and Loan, 1996] Gene H. Golub and Charles F. Van Loan. Matrix computations. John Hopkins University Press, 3rd edition, 1996.
- [Ipsen and Meyer, 1998] Ilse C. F. Ipsen and Carl D. Meyer. The idea behind Krylov methods. American Mathematical Monthly, 105(10):889-899, 1998.
- [Maggioni and Mahadevan, 2006] Mauro Maggioni and Sridhar Mahadevan. Fast direct policy evaluation using multiscale analysis of markov diffusion processes. In Proceedings of the International Conference on Machine Learning, pages 601-608. ACM Press, 2006.
- [Mahadevan and Maggioni, 2005] Sridhar Mahadevan and Mauro Maggioni. Value function approximation with dif- fusion wavelets and Laplacian eigenfuctions. In Proceed- ings of Advances in Neural Information Processing Sys- tems, 2005.
- [Mahadevan et al., 2006] Sridhar Mahadevan, Mauro Mag- gioni, Kimberly Ferguson, and Sarah Osentoski. Learning representation and control in continuous Markov decision processes. In Proceedings of the National Conference on Artificial Intelligence, 2006.
- [Mahadevan, 2005] Sridhar Mahadevan. Samuel meets Amarel: Automating value function approximation using global state space analysis. In Proceedings of the National Conference on Artificial Intelligence, 2005.
- [Munos, 2003] Remi Munos. Error bounds for approximate policy iteration. In Proceedings of the International Con- ference on Machine Learning, pages 560-567, 2003.
- [Poupart and Boutilier, 2002] Pascal Poupart and Craig Boutilier. Value-directed compression of POMDPs. In Proceedings of Advances in Neural Information Processing Systems, pages 1547-1554, 2002.
- [Puterman, 2005] Martin L. Puterman. Markov decision pro- cesses: Discrete stochastic dynamic programming. John Wiley & Sons, Inc., 2005.
- [Saad, 1995] Yosef Saad. Preconditioned Krylov subspace methods for CFD applications. In W. G. Hasbashi, editor, Solution Techniques for Large Scale CFD Problems, page 141. Wiley, 1995.
- [Saad, 1997] Yousef Saad. Analysis of augmented Krylov subspace methods. SIAM Journal on Matrix Analysis and Applications, 18(2):435-449, April 1997.
- [Saad, 2003] Yousef Saad. Iterative methods for sparse lin- ear systems. SIAM, 2nd edition, 2003.
- [Sutton and Barto, 1998] Richard S. Sutton and Andrew Barto. Reinforcement learning. MIT Press, 1998.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Markov Decision Processes (MDP) [Puterman, 2005] are a widely-used framework for planning under uncertainty. In this paper, we focus on the discounted infinite horizon problem with discount γ such that 0 < γ < 1. We also assume finite state and action spaces. While solving this problem requires only polynomial time, many practical problems are too large to be solved precisely. This motivated the development of approximate methods for solving very large MDPs that are sparse and structured.
Value Function Approximation (VFA) is a method for finding approximate solutions for MDPs, which has received a lot of attention [Bertsekas and Tsitsiklis, 1996]. Linear approximation is a popular VFA method, because it is simple to analyze and use. The representation of the value function in linear schemes is a linear combination of basis vectors. The optimal policy is usually calculated using approximate value iteration or approximate linear programming [Bertsekas and Tsitsiklis, 1996].
The choice of the basis plays an important role in solving the problem. Usually, the basis used to represent the space is hand-crafted using human insight about some topological properties of the problem [Sutton and Barto, 1998]. Recently, a new framework for automatically constructing the basis was proposed in [Mahadevan, 2005]. This approach is based on analysis of the neighborhood relation among the states. The analysis is inspired by spectral methods, often used in machine-learning tasks. We describe this framework in more detail in Section 2.
In the following, we use v to denote the value function, and r to denote the reward vector. The matrix I denotes an identity matrix of an appropriate size. We use n to denote the number of states of the MDP.
An important property of many VFA methods is that they are guaranteed to converge to an approximately optimal solution. In methods based on approximate policy iteration the maximal distance of the optimal approximate value function ˆ v from the optimal value function v∗ is bounded by [Munos, 2003]:
where vk and ˜ vk are true and approximated value at step k given the current policy. The norm ‖ · ‖μ denotes a weighted quadratic norm with distribution μ. The distribution μ is arbitrary, and μk depends on μ and the current transition matrix [Munos, 2003]. Similar bounds hold for algorithms based on Bellman residual minimization, when ‖vk - ˜ vk‖ is replaced by ‖r - (I - γPπk ) ˜ vk‖, where Pπk is a transition matrix of the current policy. In addition, these bounds hold also for the max norm [Bertsekas and Tsitsiklis, 1996]. In the following, we refer to the value function vk and its approximation ˜ vk as v and ˜ v respectively, without using the index k.
The main focus of the paper is the construction a good basis for algorithms that minimize ‖v - ˜ v‖2 in each iteration. We focus only on the quadratic approximation bound, because the other bounds are related. Notice that ‖ · ‖∞ ≤ ‖ · ‖2.
The paper is organized as follows. Section 2 describes the spectral methods for VFA in greater detail. The main contribution of the paper is an explanation of the good performance of spectral methods for VFA and its connection to methods for solving sparse linear systems. This is described in Section 3, where we also propose two new alternative algorithms. In Section 4, we show theoretical error bounds of one of the methods, and then in Section 6 we demonstrate that our method may significantly outperform the previously proposed spectral methods.
2 Proto-Value Functions
In this section, we describe in greater detail the proto-value function methods proposed in [Mahadevan, 2005]. These methods use the spectral graph framework to construct a basis for linear VFA that respects the topology of the problem. The states of the MDP for a fixed policy represent nodes of an undirected weighted graph (N,E). This graph may be represented by a symmetric adjacency matrix W, where Wxy represents the weight between the nodes. A diagonal matrix of the node degrees is denoted by D and defined as Dxx = ∑y∈N Wxy. There are several definitions of the graph Laplacian, with the most common being the normalized Laplacian, defined for W as L = I -D12 WD12 . The advantage of the normalized Laplacian is that it is symmetric, and thus its eigenvectors are orthogonal. Its use is closely related to the random walk Laplacian Lr = I - D-1W and the combinatorial Laplacian Lc = D -W, which are commonly used to motivate the use of the Laplacian by making a connection to random walks on graphs [Chung, 1997].
A function f on a graph (N,E) is a mapping from each vertex to R. One well-defined measure of smoothness of a function on a graph is its Sobolev norm. The bottom eigenvectors of Lc may be seen as a good approximation to smooth functions, that is, functions with low Sobolev norm [Chung, 1997].
The application of the spectral framework to VFA is straightforward. The value function may be seen as a function on the graph of nodes that correspond to states. The edge weight between two nodes is determined by the probability of transiting either way between the corresponding states, given a fixed policy. Usually, the weight is 1 if the transition is possible either way and 0 otherwise. Notice that these weights must be symmetric, unlike the transition probabilities. If we assume the value function is smooth on the induced graph, the spectral graph framework should lead to good results. While the adjacency matrix with edge weights of 1 was usually used before, [Mahadevan, 2005] also discusses other schemes.
While the approach is interesting, it suffers from some problems. In our opinion, the good performance of this method has not been sufficiently well explained, because the construction of the adjacency matrix is not well motivated. In addition, the construction of the adjacency matrix makes the method very hard to analyze. As we show later, using the actual transition matrix instead of the adjacency matrix leads to a better motivated algorithm, which is easy to derive and analyze.
The requirement of the value function being smooth was partially resolved by using diffusion wavelets in [Mahadevan and Maggioni, 2005; Maggioni and Mahadevan, 2006]. Briefly, diffusion wavelets construct a low-order approximation of the inverse of a matrix. An disadvantage of using the wavelets is the high computational overhead needed to construct the inverse approximation. The advantage is, however, that once the inverse is constructed it may be reused for different rewards as long as the transition matrix is fixed. Thus, we do not compare our approach to diffusion wavelets due to the different goals and computational complexities of the two methods.
3 Analysis
In this section we show that if we use the actual transition matrix instead of the random walk Laplacian of the adjacency matrix, the method may be well justified and analyzed. We assume in the following that the transition matrix P and the reward function r are available.
It is reasonable to explain the performance using P instead of Lr, because in the past applications P was usually very similar to I -Lr. This is because the transition in these problems were symmetric, and the adjacency matrix was based on a random policy. Notice that the eigenvectors of Lr and I -Lr are the same. Moreover, if λ is an eigenvalue of Lr, then 1 - λ is an eigenvalue of I - Lr.
3.1 Spectral Approximation
Assuming that P is the transition matrix for a fixed Markov policy, we can express the value function as [Puterman, 2005]:
The second equality follows from the Neumann series expansion. In fact, synchronous backups in the modified policy iteration calculate this series adding one term in each iteration.
We assume that the transition matrix is diagonalizable. The analysis for non-diagonalizable matrices would be similar, but would have to use Jordan decomposition. Let x1 . . . xn be the eigenvectors of P with corresponding eigenvalues λ1 . . . λn. Moreover, without loss of generality, ‖xj‖2 = 1 for all j. Since the matrix is diagonalizable, x1 . . . xn are linearly independent, and we can decompose the reward as:
for some c1 . . . cn. Using P ixj = λij xj , we have
Considering a subset U of eigenvectors xj as a basis will lead to the following bound on approximation error:
Therefore, the value function may be well approximated by considering those xj with greatest |dj|. Assuming that all cj are equal, then the best choice to minimize the bound (3.2) is to consider the eigenvectors with high λj. This is identical to taking the low order eigenvectors of the random walk Laplacian, as proposed in the spectral proto-VFA framework, only that the transition matrix is used instead. Using the analysis above, we propose a new algorithm in Subsection 3.3.
3.2 KrylovMethods
There are also other well-motivated base choices besides the eigenvectors. Another choice is to use some of the vectors in the Neumann series (3.1). We denote these vectors as yi = P i r for all i ∈ 〈0,∞). Calculating the value function by progressively adding all vectors in the series, as done in the modified policy iteration, potentially requires an infinite number of iterations. However, since the linear VFA methods consider any linear combination of the basis vectors, we need at most n linearly independent vectors from the sequence {yi}∞i=0 . Then it is preferable to choose those yi with small i, since these are simple to calculate.
Interestingly, it can be shown that we just need y0 . . . ym-1 to represent any value function, where m is the degree of the minimal polynomial [Ipsen and Meyer, 1998] of (I - γP). Moreover, even taking fewer vectors than that may be a good choice in many cases. To show that y0 . . . ym-1 vectors are sufficient to precisely represent any value function, let the minimal polynomial be: p(A) = ∑mi=0 αiAi . Then let
By algebraic multiplication, we have BA = I. Having this, the value function may be represented as:
for some βi. A more rigorous derivation may be found for example in [Ipsen and Meyer, 1998; Golub and Loan, 1996]. The space spanned by y0 . . . ym-1 is known as Krylov space (or Krylov subspace), denoted as K(P, r). It has been previously used in a variety of numerical methods, such as GMRES, or Lancoz, and Arnoldi [Golub and Loan, 1996]. It is also common to combine the use of eigenvectors and Krylov space, what is known as an augmented Krylov methods [Saad, 1997]. These methods actually subsume the methods based on simply considering the largest eigenvectors of P. We discuss this method in Subsection 3.3.
3.3 Algorithms
In this section we propose two algorithms based on the previous analysis for constructing a good basis for VFA. These algorithms deal only with the selection of the basis and they can be arbitrarily incorporated into any algorithm based on approximate policy iteration.
The first algorithm, which we refer to as the weighted spectral method, is to form the basis from the eigenvectors of the transition matrix. This is in contrast with the method presented in [Mahadevan, 2005], which uses any of the Laplacians. Moreover, we propose to choose the vectors with greatest |dj | value, in contrast to choosing the ones with largest λj . The reason is that this leads to minimization of the bound in (3.2).
A practical implementation of this algorithm faces some major obstacles. One issue is that there is no standard eigenvector solver that can efficiently calculate the top eigenvectors with regard to |dj| of a sparse matrix. However, such a method may be developed in the future. In addition, when the transition matrix is not diagonalizable, we need to calculate the Jordan decomposition, which is very time-consuming and unstable. Finally, some of the eigenvectors and eigenvalues may contain complex numbers, what would require a revision of the approximate policy iteration algorithms. If these issues were resolved, this may be a viable alternative to other methods.
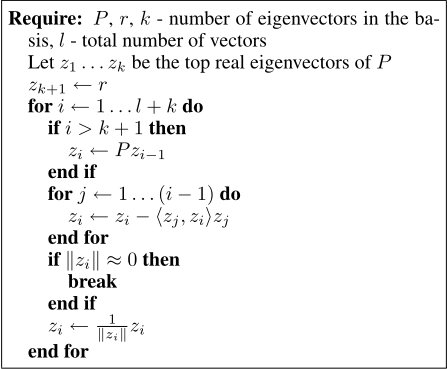
The second algorithm we propose is to use the vectors from the augmented Krylov method, that is, to combine the vectors in the Krylov space with a few top eigenvectors. A pseudocode of the algorithm is in Figure 1. The algorithm calculates an orthonormal basis of the augmented Krylov space using a modified Gram-Schmidt method.
Using the Krylov space eliminates the problems with nondiagonalizable transition matrices and complex eigenvectors. Another reason to combine these two methods is to take advantage of approximation properties of both methods. Intuitively, Krylov vectors capture the short-term behavior, while the eigenvectors capture the long-term behavior. Though, there is no reliable decision rule to determine the right number of augmenting eigenvectors, it is preferable to keep their number relatively low. This is because they are usually more expensive to compute than vectors in the Krylov space.
4 Approximation Bounds
In this section, we briefly present a theoretical error bound guaranteed by the augmented Krylov methods. The bound characterizes the worst-case approximation error of the value function, given that the basis is constructed using the current transition matrix and reward vector. We focus on bounding the quadratic norm, what also implies the max norm.
We show the bound for ‖r - ˜ v + γP ˜ v‖2. This bound applies directly to algorithms that minimize the Bellman residual [Bertsekas and Tsitsiklis, 1996], and it also implies:
This follows from the Neumann series expansion of the inverse and from ‖P‖∞ = 1.
In the following, we denote the set of m Krylov vectors as Km and the chosen set of top eigenvectors of P as U. We also use E(c, d, a) to denote an ellipse in the set of complex numbers with center c, focal distance d, and major semi-axis a. The approximation error for a basis constructed for the current policy may be bounded as the following theorem states.
Theorem 4.1. Let (I -γP) = XSX-1 be a diagonalizable matrix. Further, let
where T is a diagonal matrix with 1 in place of eigenvalues of eigenvectors in |U|. The approximation error using the basis Km ∪ U is bounded by:
where Cm is the Chebyshev polynomial of the first kind of degree m, and κ(X) = ‖X‖2‖X-1 ‖2. The parameters a, c, d and a1, c1, d1 are chosen such that E(c1, d1, a1) includes the lower n-|U| eigenvalues of (I-γP ), and E(c, d, a) includes all its eigenvalues.
The value of φ depends on the angle between the invariant subspace U and the other eigenvectors of P. If they are perpendicular, such as when P is symmetric, then φ = 0.
Proof. To simplify the notation, we denote A = (I - γP). First, we show the standard bound on approximation by a Krylov space [Saad, 2003], ignoring the additional eigenvectors. In this case, the objective is to find such w ∈ Km that minimizes the following:
where w(0) = -1. Notice that this defines a polynomial in A multiplied by r with the constant factors determined by w. Let Pm denote the set of polynomials of degree at most m such that every p ∈ Pm satisfies p(0) = 1. The minimization problem may be then expressed as finding a polynomial p ∈ Pm that minimizes ‖p(A)r‖2. This is related to the value of the polynomial on complex numbers as [Golub and Loan, 1996]:
where λi are the eigenvalues of A. A more practical bound may be obtained using Chebyshev polynomials, as for example in [Saad, 2003], as follows:
where the ellipse E(c, d, a) covers all eigenvalues of A.
In the approximation with eigenvectors, the minimization may be expressed as follows:
where PU is the least squares projection matrix to U. Note that ‖p(A)PUr - AUy‖ = 0, since U is an invariant space of A. Moreover, (I - PU) ∗ r is perpendicular to U. The theorem then follows from the approximation by Chebyshev polynomials as described above, and the definition of matrixvalued function approximation [Golub and Loan, 1996].
This bound shows that it is important to choose an invariant subspace that corresponds to the top eigenvalues of P. It also shows that U should be chosen to be to the highest degree perpendicular to the remaining eigenvectors. Finally, the bound also implies that the approximation precision increases with lower γ, as this decreases the size of the ellipse to cover the eigenvalues.
5 Experiments
In this section we demonstrate the proposed methods on the two-room problem similar to the one used in [Mahadevan, 2005; Mahadevan and Maggioni, 2005]. This problem is a typical representative of some stochastic planning problems encountered in AI.
The MDP we use is a two-room grid with a single-cell doorway in the middle of the wall. The actions are to move in any of the four main direction. We use the policy with an equal probability of taking any action. The size of each room is 10 by 10 cells. The problem size is intentionally small to make explicit calculation of the value function possible. Notice that because of the structure of the problem and the policy, the randomwalk Laplacian has identical eigenvectors as the transition matrix in the same order. This allows us to evaluate the impact of choosing the eigenvectors in the order proposed by the weighted spectral method.
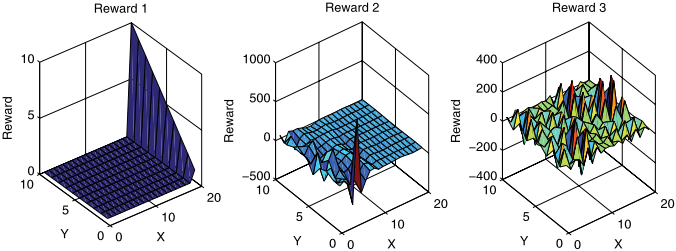
We used the problem with various reward vectors and discount factors, but with the same transition structure. The reward vectors are synthetically constructed to show possible advantages and disadvantages of the methods. They are shown projected onto the grid in Figure 2. Vector "Reward 1" represents an arbitrary smooth reward function. Vectors "Reward 2" and "Reward 3" are made perpendicular to the top 40 and the top 190 eigenvectors of the random walk Laplacian respectively.
A lower discount rate is generally more favorable to Krylov methods, because the value is closer to the value of the reward received in the state. This can also be seen from Theorem 4.1, because γ shrinks the eigenvalues. Therefore, we use problems that are generally less favorable to Krylov methods, we evaluate the approach using two high discount rates, γ = 0.9 and γ = 0.99.
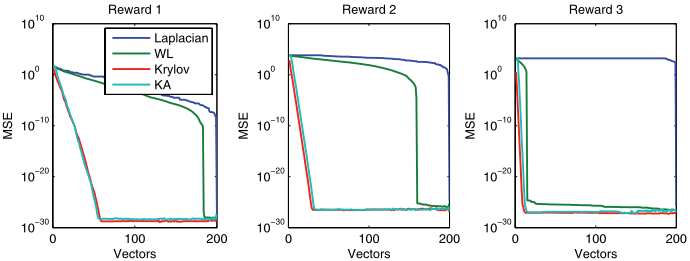
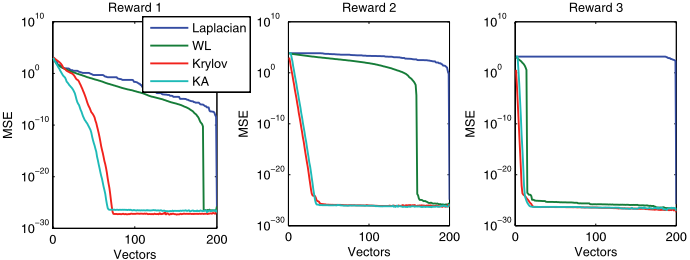
In our experiments, we evaluate the Mean Squared Error (MSE) of the value approximation with regard to the number of vectors in the basis. The basis and the value function were calculated based on the same policy with equiprobable action choice. We obtained the true value function by explicitly evaluating (I - γP)-1 r. Notice, however, that the true value does not need to be used in the approximation, it is only required to determine the approximation error. We compared the following 4 methods:
Laplacian The technique of using the eigenvectors of the random walk Laplacian of the adjacency matrix, as proposed in [Mahadevan, 2005]. The results of the normalized Laplacian are not shown because they were practically identical to the randomwalk Laplacian.
- WL This is the weighted spectral method, described in Subsection 3.3, which determines the optimal order of the eigenvectors to be used based on the value of dj .
Krylov This is the augmented Krylov method with no eigenvectors, as described in Subsection 3.3.
- KA This is the augmented Krylov method with 3 eigenvectors, as proposed in Figure 1. The number of eigenvectors was chosen before running any experiments on this domain.
The results for γ = 0.9 are in Figure 3 and for γ = 0.99 are in Figure 4. "Reward 3" intentionally violates the smoothness assumption, but it is the easiest one to approximate for all methods except the Laplacian. In the case of "Reward 1" and γ = 0.99, the weighted spectral method and the random walk Laplacian outperform the ordinary Krylov method for the first 10 vectors. However, with additional vectors, both Krylov and augmented Krylov methods significantly outperform them.
Our results suggest that Krylov methods may offer superior performance compared to using the eigenvectors of the Laplacian. Since these methods have been found very effective in many sparse linear systems [Saad, 2003], they may perform well for basis construction also in other MDP problems. In addition, constructing a Krylov space is typically faster than constructing the invariant space of eigenvectors. Using Matlab on a standard PC, it took 2.99 seconds to calculate the 50 top eigenvectors, while it took only 0.24 second to calculate the first 50 vectors of the Krylov space for "Reward 1".
6 Discussion
We presented an alternative explanation of the success of Laplacian methods used for value approximation. This explanation allows us to more precisely determine when the method may work. Moreover, it shows that these methods are closely related to augmented Krylov methods. We demonstrated on a limited problem set that basis constructed from augmented Krylov methods may be superior to one constructed from the eigenvectors. In addition, both the weighted spectral method and the augmented Krylov method do not assume the value function to be smooth. Moreover, calculating vectors in the Krylov space is typically cheaper than calculating the eigenvectors.
An approach for state-space compression of Partially Observable MDPs (POMDP) that also uses Krylov space was proposed in [Poupart and Boutilier, 2002]. While POMDPs are a generalization of MDPs, the approach is not practical for large MDPs since it implicitly assumes that the number of observations is small. This is not true for MDPs, because the number of observations is equivalent to the number of states. In addition, the objectives of this approach are somewhat different, though the method is similar.
One important issue that we did not address is an application to state spaces that are too large to be enumerated, such as factored MDPs. Because the vectors in Krylov space are as large as the whole state space, they cannot be enumerated either. However, the approach may be extended along similar lines as discussed in [Poupart and Boutilier, 2002].
In reinforcement learning, the MDP needs to be solved using only an estimation of the transition matrix from sampling. An additional problem is that the basis is not defined for states that were not sampled. This was addressed for eigenvectors for example in [Mahadevan et al., 2006]. Thus augmenting the Krylov space by the eigenvectors also has the advantage that these methods may be directly applied.
We focused mainly on the VFA for a fixed policy without explicitly considering the control part of the problem. While these methods may be combined arbitrarily, a future challenge is to determine an efficient combination.
Our results suggest that exploring the connection between the basis construction in VFA and sparse linear solvers may bring about interesting advances in the future.
Acknowledgements
The author was supported by the National Science Foundation under Grant No. IIS-0328601. I also thank Sridhar Mahadevan, Hala Mostafa, Shlomo Zilberstein, and the anonymous reviewers for valuable comments.
@inproceedings{ijcai2007p414,
  title     = {An Analysis of Laplacian Methods for Value Function Approximation in MDPs},
  author    = {Petrik, Marek},
  booktitle = {Proceedings of the Twentieth International Joint Conference on
               Artificial Intelligence, {IJCAI-07}},
  publisher = {International Joint Conferences on Artificial Intelligence},
  editor    = {Manuela M. Veloso},
  pages     = {2574--2578},
  year      = {2007},
  url       = {https://ijcai.org/proceedings/2007/414},
}
TY - CPAPER TI - An Analysis of Laplacian Methods for Value Function Approximation in MDPs AU - Petrik, Marek T2 - Proceedings of the Twentieth International Joint Conference on Artificial Intelligence, IJCAI-07 PB - International Joint Conferences on Artificial Intelligence PY - 2007 SP - 2574 EP - 2578 UR - https://ijcai.org/proceedings/2007/414 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





