
Updates for Nonlinear Discriminants
Proceedings of the Twentieth International Joint Conference on Artificial Intelligence. Pages 660-664.
© 2007 International Joint Conferences on Artificial Intelligence
Abstract
A novel training algorithm for nonlinear discriminants for classification and regression in Reproducing Kernel Hilbert Spaces (RKHSs) is presented. It is shown how the overdetermined linear least-squares-problem in the corresponding RKHS may be solved within a greedy forward selection scheme by updating the pseudoinverse in an order-recursive way. The described construction of the pseudoinverse gives rise to an update of the orthogonal decomposition of the reduced Gram matrix in linear time. Regularization in the spirit of Ridge regression may then easily be applied in the orthogonal space. Various experiments for both classification and regression are performed to show the competitiveness of the proposed method.
- [Ben-Israel and Greville, 1977] A. Ben-Israel and T. N. E. Greville. Generalized Inverses: Theory and Applications. Wiley, 1977.
- [Billings and Lee, 2002] S. A. Billings and K. L. Lee. Non- linear fisher discriminant analysis using a minimum squared error cost function and the orthogonal least squares algorithm. Neural Networks, 15:263-270, 2002.
- [Chen et al., 1991] S. Chen, C. F. N. Cowan, and P. M. Grant. Orthogonal least squares learning for radial ba- sis function networks. IEEE Transactions on Neural Net- works, 2(2):302-309, 1991.
- [De Kruif and De Vries, 2003] B. J. De Kruif and T. J. A. De Vries. Pruning error minimization in least squares support vector machines. IEEE Transactions on Neural Networks, 14(3):696-702, 2003.
- [Duda and Hart, 1973] R. O. Duda and P. E. Hart. Pattern classification and scene analysis. John Wiley and Sons, 1973.
- [G. Cauwenberghs, 2000] T. Poggio G. Cauwenberghs. In- cremental and decremental support vector machine learn- ing. In Advance in Neural Information Processing Systems (NIPS 2000), 2000.
- [Gu and Wahba, 1991] C. Gu and G. Wahba. Minimizing gcv/gml scores with multiple smoothing parameters via the newton method. SIAM Journal on Scientific and Sta- tistical Computing, 12(2):383-398, 1991.
- [Hoegaerts et al., 2004] L. Hoegaerts, J. A. K. Suykens, J. Vanderwalle, and B. De Moor. A comparison of prun- ing algorithms for sparse least squares support vector ma- chines. In Proceedings of the 11th International Confer- ence on Neural Information Processing (ICONIP 2004), Calcutta, India, Nov 2004.
- [Ma et al., 2003] J. Ma, J. Theiler, and S. Perkins. Accurate on-line support vector regression. Neural Computation, 15:2683-2703, 2003.
- [MacKay, 1992] D. J. C. MacKay. Bayesian interpolation. Neural Computation, 4(3):415-447, 1992.
- [Mallat and Zhang, 1993] S. Mallat and Z. Zhang. Matching pursuit in a time-frequency dictionary. IEEE Transactions on Signal Processing, 41:3397-3415, 1993.
- [Mercer, 1909] J. Mercer. Functions of positive and negative type and their connections to the theory of integral equa- tions. In Philos. Trans. Roy. Soc., pages A 209:415-446, London, 1909.
- [Mika, 2002] S. Mika. Kernel Fisher Discriminants. PhD thesis, Technical University Berlin, 2002.
- [Nair et al., 2002] P. Nair, A. Choudhury, and A. J. Keane. Some greedy learning algorithms for sparse regression and classification with mercer kernels. Journal of Machine Learning Research, 3:781-801, 12 2002.
- [Natarajan, 1995] B. K. Natarajan. Sparse approximate so- lutions to linear systems. SIAM Journal of Computing, 25:227-234, 1995.
- [Orr, 1995] M. Orr. Regularisation in the selection of radial basis function centres. Neural Computation, 7:606-623, 1995.
- [Rifkin et al., 2003] R. Rifkin, G. Yeo, and T. Poggio. Regu- larized least squares classification. In J. A. K. Suykens, G. Horvath, S. Basu, C. Micchelli, and J. Vandewalle, editors, Advances in Learning Theory: Methods, Models and Applications, volume 190 of NATO Science Series III: Computer and Systems Sciences, chapter 7, pages 131- 154. IOS Press, Amsterdam, 2003.
- [Schölkopf and Smola, 2002] B. Schölkopf and A. J. Smola. Learning with Kernels. MIT Press, 2002.
- [Smola and Schölkopf, 2000] A. J. Smola and B. Schölkopf. Sparse greedy matrix approximation for machine learn- ing. In Proceedings of the 17th International Conference on Machine Learning, pages 911-918.
- Morgan Kaufmann, 2000.
- [Suykens and Vandewalle, 1999] J. A. K. Suykens and J. Vandewalle. Least squares support vector machine clas- sifiers. Neural Processing Letters, 9:293-300, 1999.
- [Van Gestel et al., 2002] T. Van Gestel, J. A. K. Suykens, G. Lanckriet, A. Lambrechts, B. De Moor, and J. Van- dewalle. A bayesian framework for least squares sup- port vector machine classifiers, gaussian processes and kernel fisher discriminant analysis. Neural Computation, 14(5):1115-1147, May 2002.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Models for regression and classification that enforce square loss functions are closely related to Fisher discriminants [Duda and Hart, 1973]. Fisher discriminants are Bayesoptimal in case of classification with normally distributed classes and equally structured covariance matrices [Duda and Hart, 1973][Mika, 2002]. However, in contrast to SVMs, Least Squares Models (LSMs) are not sparse in general and hence may cause overfitting in a supervised learning scenario. One way to circumvent this problem is to incorporate regularization controlled by a continuous parameter into the model. For instance, Ridge regression [Rifkin et al., 2003] penalizes the norm of the solution yielding flat directions in the RKHS, which are robust against outliers caused by e. g. noise. In [Suykens and Vandewalle, 1999] Least-Squares SVMs (LSSVMs) are introduced which are closely related to Gaussian processes and Fisher discriminants. A linear set of equations in the dual space is solved using e. g. the conjugate gradient methods for large data sets or a direct method for a small number of data. The solution is pruned [De Kruif and De Vries, 2003][Hoegaerts et al., 2004] in a second stage. The close relation between the LS-SVM and the Kernel Fisher Discriminant (KFD) was shown in [Van Gestel et al., 2002]. It follows from the equivalence between the KFD and a least squares regression onto the labels [Duda and Hart,
1973][Mika, 2002] that the proposed method is closely related to the KFD and the LS-SVM. However, the proposed method imposes sparsity on the solution in a greedy fashion using subset selection like in [Billings and Lee, 2002][Nair et al., 2002]. For the SVM case similar greedy approaches exist [G. Cauwenberghs, 2000][Ma et al., 2003].
Especially in case of large data sets subset selection is a practical method. It aims to eliminate the most irrelevant or redundant samples. However, finding the best subset of fixed size is an NP-hard combinatorial search problem. Hence, one is restricted to suboptimal search strategies. Forward selection starts with an empty training set and adds sequentially one sample that is most relevant according to a certain criterion (e. g. the mean square error). In [Nair et al., 2002] an external algorithm which is based on elementary Givens rotations is used to update the QR-decomposition of the reduced Gram matrix in order to construct sparse models. The Gram Schmidt orthogonalization is used in [Billings and Lee, 2002] and [Chen et al., 1991] for the orthogonal decomposition of the Gram matrix. They also apply forward selection in a second step to obtain sparse models. This method is known as Orthogonal Least Squares (OLS). However, the OLS algorithm requires the computation and the storage of the full Gram matrix which is prohibitive for large datasets.
In this paper a very simple and efficient way for constructing LSMs in a RKHS within a forward selection rule with much lower memory requirements is presented. The proposed method exploits the positive definiteness of the Gram matrix for an order-recursive thin update of the pseudoinverse, which reveals to the best of our knowledge a novel kind of update rule for the orthogonal decomposition. The solution is regularized in a second stage using the Generalized Cross Validation to re-estimate the regularization parameter.
The remainder of this paper is organized as follows. In section 2, computationally efficient update rules for the pseudoinverse and the orthogonal decomposition are derived. In section 3, it is shown how the solution may be regularized. In section 4 some experimental results on regression and classification datasets are presented. Finally, a conclusion is given in section 5.
2 Update of the Orthogonal Decomposition
In a supervised learning problem one is faced with a training data set D = {xi, yi}, i = 1 . . .M. Here, xi denotes an input vector of fixed size and yi is the corresponding target value which is contained in R for regression or in {1, -1} for binary classification. It is assumed that xi ̸= xj, for i ̸= j.
We focus on sparse approximations of models of the form
The use of Mercer kernels k(·, x) [Mercer, 1909] gives rise to a symmetric positive definite Gram Matrix K with elements Kij = k(xi, xj) defining the subspace of the RKHS in which learning takes place. The weight vector α = {b, α1, . . . , αM} contains a bias term b with a corresponding column 1 = {1, . . . , 1} in the Gram matrix.
Consider the overdetermined least-squares-problem
in the m-th forward selection iteration with the reduced Gram matrix Km = [1 k1 . . . km] ∈ RM×(m+1) where ki = (k(·, x1), . . . , k(·, xM))T , i ∈ {1, . . . ,m} denotes one previously unselected column of the full Gram matrix. We denote the reduced weight vector as αm = {b, α1, . . . , αm} ∈ Rm+1 and the target vector as y = (y1, . . . , yM)T . Among all generalized inverses of Km the pseudoinverse
is the one that has the lowest Frobenius norm [Ben-Israel and Greville, 1977]. Thus, the corresponding solution
has the lowest Euclidean norm.
Partitioning Km and αm in the form
and setting αm = αm0 = const, the square loss becomes
The minimum of (7) in the least-squares-sense is given by
Inserting (8) into (7) yields
with I denoting the identity matrix of appropriate size.
Note that the vector
is the residual corresponding to the least-squares regression onto km. Hence, qm is a nullvector if and only if km is a nullvector unless K is not strictly positive definite. To ensure strictly positive definiteness of K, it is mandatory to add a small positive constant ε to the main diagonal of the full Gram matrix in the formK→K +εI. Forward selection may then be performed using this strictly positive definite Gram matrix. In the following km ̸= 0 is assumed.
The minimum of (9) is met at
Noting that the pseudoinverse of a vector is given by
equation (11) may be written as
The matrix
is an orthogonal projection matrix which implies being symmetric and idempotent and thus equation (13) simplifies to
Combining (15) with (8) the current weight vector ˆαm may be updated as
revealing the update
for the current pseudoinverse.
Since every projection qm = Pmkm lies in a subspace which is orthogonal to Km-1 it follows immediately that qTi qj = 0, for i ̸= j. Hence, an orthogonal decomposition
of the reduced Gram matrix is given by the orthogonal matrix
and the upper triangular matrix
In the m-th iteration O(Mm) operations are required for all these updates. Note that the inversion of the matrix QTmQm is trivial since this matrix is diagonal. However, the condition number of the matrix Qm increases as the number of selected columns m grows. Thus, to ensure numerical stability it is important to monitor the condition number of this matrix and to terminate the iteration if the condition number exceeds a predefined value unless another stopping criterion is reached earlier.
3 Regularization and Selection of Basis Centers
The goal of every forward selection scheme is to select the columns of the Gram matrix that provide the greatest reduction of the residual. Methods like basis matching pursuit [Mallat and Zhang, 1993], order-recursive matching pursuit [Natarajan, 1995] or probabilistic approaches [Smola and Sch¨olkopf, 2000] are several contributions to this issue. In [Nair et al., 2002], forward selection is performed by simply choosing the column that corresponds to the entry with the highest absolute value in the current residual. The reasoning is that the residual provides the direction of the maximum decrease in the cost function 0.5αT Kα-αTy, since the Gram matrix is strictly positive definite. The latter method is used in the following experiments. But note that the derived algorithm may be applied within any of the above forward selection rules. In the following we will refer to the proposed method as Order-Recursive Orthogonal Least Squares (OROLS).
Consider the residual
in the m-th iteration. The vector ˜αm contains the orthogonal weights.
The regularized square residual is given by
where λ denotes a regularization paramter. The minimum of (22) is given by
Thus, the current residual corresponding to the regularized least squares problemmay be updated as
The orthogonal weights
can be computed when the forward selection is stopped. The original weights can then be recovered by
which is an easy inversion since Um is upper triangular.
In each iteration one chooses the qi which corresponds to the highest absolute value in the current residual and adds it to Qm-1. It is possible to determine the number of basis functions using crossvalidation or one may use for instance the Bayesian Information Criterion or the Minimum Description Length as alternative stopping criteria. Following [Gu and Wahba, 1991] and [Orr, 1995] it is possible to use the Generalized Cross Validation (GCV ) as a stopping criterion. We will now summarize the results. For details see [Orr, 1995].
The GCV is given by
Minimizing the GCV with respect to λ gives rise to a reestimation formula for λ. An alternative way to obtain a re-estimation of λ is to maximize the Bayesian evidence [MacKay, 1992].
Differentiating (27) with respect to λ and setting the result to zero gives a minimum when
Noting that
equation (28) can be rearranged to obtain the re-estimation formula
where
The forward selection is stopped when λ stops changing significantly.
The computational cost for this update is O(m). The OROLOS algortihm is summarized in pseudocode in Algorithm 1.
4 Experiments
To show the usefulness of the proposed method empirically, some experiments for regression and classification are performed. In all experiments the Gaussian kernel
is used. The kernel parameter σ is optimized using a 5-fold crossvalidation in all experiments. For the classification experiments the one-vs-rest approach is used to obtain a multiclass classification hypothesis.
4.1 Classification
For classification, 5 well-known benchmark datasets were chosen. The USPS dataset contains 256 pixel values of handwritten digits as training and testing instances.
The letter dataset contains 20000 labeled samples. The character images were based on 20 different fonts and each letter within these fonts was randomly distorted to produce a dataset of unique stimuli. For this dataset no predefined split for training and testing exist. We used the first 16000 instances for training and the remaining 4000 instances for testing.
Optdigits is a database of digits handwritten by Turkish writers. It contains digits written by 44 writers. The training set is generated from the first 30 writers and digits written by the remaining independent writers serve as testing instances. The database was generated by scanning and processing forms to obtain 32 × 32 matrices which were then reduced to 8 × 8.
Algorithm 1 Order-Recursive Orthogonal Least Squares (OROLS)
while λ changes significantly and Qm is not illconditioned do
Update ˜em
find the index iopt of the entry of ˜em with the highest absolute value
Compute kiopt
Compute qiopt
Km ←
[Km-1kopt]
Update K†m and Um using kopt and qopt
Update λ
end while
return ˆαm, Iopt
Pendigits contains pen-based handwritten digits. The digits were written down on a touch-sensitive tablet and were then resampled and normalized to a temporal sequence of eight pairs of (x, y) coordinates. The predefined test set is formed entirely from written digits produced by independent writers.
The satimage dataset was generated from Landsat MultiSpectral Scanner image data. Each pattern contains 36 pixel values and a number indicating one of the six classes of the central pixel.
The caracteristics of the datasets are summarized in table 1. The results can be seen in table 2. Especially for the optdigits and pendigits datasets OROLS appears to be significantly superior compared with SVMs. The performance on the remaining 3 datasets is comparable with SVMs.
| DATA SET | # CLASSES | # TRAINING | # TESTING |
| USPS | 10 | 7291 | 2007 |
|---|---|---|---|
| LETTER | 26 | 16000 | 4000 |
| OPTDIGITS | 10 | 3823 | 1797 |
| PENDIGITS | 10 | 7494 | 3498 |
| SATIMAGE | 6 | 4435 | 2000 |
| DATA SET | SVM | OROLS |
| USPS | 4.3 | 4.4(10) |
| LETTER | 2.75 | 2.61(4.3) |
| OPTDIGITS | 2.73 | 1.11(10.2) |
| PENDIGITS | 2.5 | 1.66(1.9) |
| SATIMAGE | 7.8 | 8.2(7.5) |
4.2 Regression
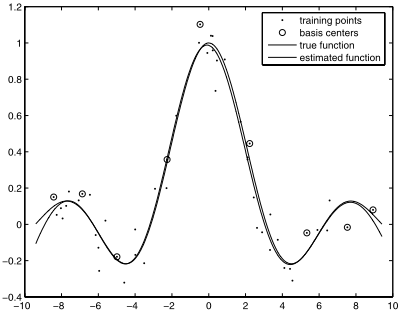
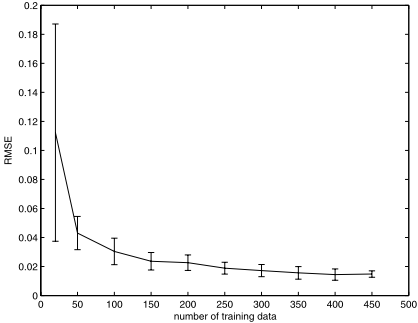
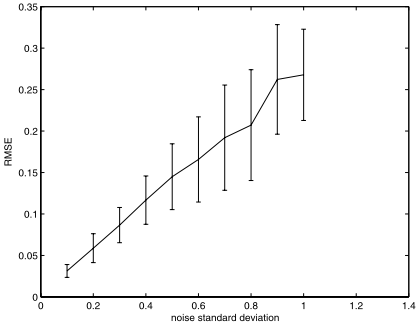
For regression, we first perform experiments on a synthetic dataset based on the function sinc(x) = sin(x)/x, x ∈ (-10, 10) which is corrupted by Gaussian noise. All training and testing instances are chosen randomly using a uniform distribution on the same interval. The results are illustrated in figures 1-3 and table 3.
Additionally, the two real world datasets Boston and Abalone, which are available from the UCI machine learning repository, are chosen. The hyperparameters are optimized in a 5-fold crossvalidation procedure. For both datasets, random partitions of the mother data for training and testing are generated (100 (10) partitions with 481 (3000) instances for training and 25 (1177) for testing for the Boston and Abalone dataset, respectively). All continuous features are rescaled to zero mean and unit variance for both Abalone and Boston. The gender encoding (male / female /infant) for the Abalone dataset is mapped into {(1, 0, 0), (0, 1, 0), (0, 0, 1)}. The Mean Squared Error (MSE) of OROLS is compared with a forward selection algorithm based on a QR-decomposition of the Gram matrix [Nair et al., 2002]. The results in table 4 show that the MSE is improved significantly by OROLS. In contrast to OROLS the QR method uses an external algorithm with reorthogonalization for the update of the orthogonal decomposition. We observed that our update scheme which is to the best of our knowledge a novel update needs not to be reorthogonalized as long as the Gram matrix has full rank. This improvement of accuracy could be one reason for the good performance of OROLS. Furthermore, it should be noted that the best performance of OROLS for the Boston dataset is quite favourable compared with the best performance of SVMs (MSE 8.7 ± 6.8) [Sch¨olkopf and Smola, 2002].
| METHOD | RMSE |
|---|---|
| SVM | 0.0519 |
| RVM | 0.0494 |
| OROLS | 0.0431 |
| DATASET | QR | OROLS |
|---|---|---|
| BOSTON | 8.35±5.67 | 7.9±3.28(26) |
| ABALONE | 4.53±0.29 | 4.32±0.17(10.8) |
5 Conclusion
A computationally efficient training algorithm for orthogonal least squares models using Mercer kernels is presented.
The pseudoinverse is updated order-recursively and reveals the current orthogonal decomposition of the reduced Gram matrix within a forward selection scheme. The Generalized Cross Validation serves as an effective stopping criterion and allows to adapt the regularization parameter in each iteration. Extensive empirical studies using synthetic and real-world benchmark datasets for classification and regression suggest that the proposed method is able to construct models with a very competitive generalization ability. The advantage of the proposed method compared with e. g. SVMs is its simplicity. Sparsity is achieved in a computationally efficient way by constuction and can hence better be controlled than in the SVM case where a optimization problem is to be solved. Furthermore, in contrast to SVMs OROLS allows an easy incorporation of multiple kernels, i e. the kernel parameters may be varied for different training instances in order to obtain more flexible learning machines. This possibility is not examined here and may be an interesting direction for future work. A further step for future work could be the development of the proposed algorithm for tasks like dimensionality reduction or online-learning.
@inproceedings{ijcai2007p105,
  title     = {Updates for Nonlinear Discriminants},
  author    = {Andelic, Edin and Schafföner, Martin and Katz, Marcel and Krüger, Sven E. and Wendemuth, Andreas},
  booktitle = {Proceedings of the Twentieth International Joint Conference on
               Artificial Intelligence, {IJCAI-07}},
  publisher = {International Joint Conferences on Artificial Intelligence},
  editor    = {Manuela M. Veloso},
  pages     = {660--664},
  year      = {2007},
  url       = {https://ijcai.org/proceedings/2007/105},
}
TY - CPAPER TI - Updates for Nonlinear Discriminants AU - Andelic, Edin AU - Schafföner, Martin AU - Katz, Marcel AU - Krüger, Sven E. AU - Wendemuth, Andreas T2 - Proceedings of the Twentieth International Joint Conference on Artificial Intelligence, IJCAI-07 PB - International Joint Conferences on Artificial Intelligence PY - 2007 SP - 660 EP - 664 UR - https://ijcai.org/proceedings/2007/105 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





