
Approximate Policy Iteration using Large-Margin Classifiers
Proceedings of the Eighteenth International Joint Conference on Artificial Intelligence. Pages 1432-1433.
© 2003 International Joint Conferences on Artificial Intelligence
Abstract
We present an approximate policy iteration algorithm that uses rollouts to estimate the value of each action under a given policy in a subset of states and a classifier to generalize and learn the improved policy over the entire state space. Using a multiclass support vector machine as the classifier, we obtained successful results on the inverted pendulum and the bicycle balancing and riding domains.
- [Bertsekas and Tsitsiklis, 1996] D. Bertsekas and J. Tsitsiklis. Neuro-Dynamic Programming. Athena Scientific, Belmont, Mas- sachusetts, 1996.
- [Collobert and Bengio, 2001] Ronan Collobert and Samy Bengio. SVMTorch: Support vector machines for large-scale regres- sion problems. Journal of Machine Learning Research (JMLR), 1:143-160, 2001.
- [Dietterich and Wang, 2001] T. G. Dietterich and X. Wang. Batch value funtion approximation via support vectors. In Advances in Neural Information Processing Systems 14, 200 I. MIT Press. [Fern eta/., 2003]
- A. Fern, S. Yoon, and R. Givan. Approxi- mately policy iteration with a policy language bias: Learning control policies in relational planning domains. In Submitted to The Nineteenth International Conference on Machine Learning (ICML-2003), July 2003.
- [Jaakkola eta/., 1995] Tommi Jaakkola, Satinder P. Singh, and Michael!. Jordan. Reinforcement learning algorithm for partially observable Markov decision problems. In G. Tesauro, D. Touret- zky, and T. Leen, editors, Advances in Neural Information Pro- cessing Systems 7, Cambridge, Massachusetts, 1995. MIT Press.
- [Ng eta/., 1999] Andrew Y. Ng, Daishi Harada, and Stuart Russell. Policy invariance under reward transformations : theory and ap- plication to reward shaping. In Proc. 16th International Con/ on Machine Learning, pages 278-287.
- Morgan Kaufmann, San Francisco, CA, 1999.
- [Randlov and Alstrom, 1998] J. Randlov and P. Alstmm. Learn- ing to drive a bicycle using reinforcement learning and shaping. In The Fifteenth International Conference on Machine Learning, 1998.
- Morgan Kaufmann. [Tesauro and Galperin, 1997]
- G. Tesauro and G. R. Galperin. On- line policy improvement using monte-carlo search. In Advances in Neural Information Processing Systems (NIPS) 9, 1997.
- [Yoon eta!., 2002] S. W. Yoon, A. Fern, and B. Givan. Inductive policy selection for first-order MDPs. In Proceedings of the Eigh- teenth Conference on Uncertainty in Artificial Intelligence, 2002.
- Morgan Kaufmann.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Reinforcement learning provides an intuitively appealing framework for addressing a wide variety of planning and con trol problems. There has been significant success in tackling large-scale problems through the use of value function and/or policy approximation. The success of these methods, how ever, is contingent upon extensive and careful feature engi neering, a common problem in most machine learning meth ods.
Modern classification methods have mitigated the feature engineering problems through the use of kernel methods, but very little has been done to exploit these recent advances for the purposes of reinforcement learning. Of course, we are not the first to note the potential benefits of modern classifica tion methods to reinforcement learning. For example, Yoon et al. [2002] use inductive learning techniques, including boost ing, to generalize across similar problems. Dietterich and Wang [2001] also use a kernel-based approximation method to generalize across similar problems. The novelty in our ap proach is the application of modern learning methods within a single, noisy problem at the inner loop of a policy iteration algorithm.' By using rollouts, we avoid the sometimes prob lematic step of value function approximation. Thus, our tech nique aims to address the critiques of value function methods raised by the proponents of direct policy search, while avoid ing the confines of a parameterized policy space.
2 Definitions and Assumptions
A Markov decision process (MDP) is defined as a 6-tuple ( S, A, P, R, 1, D) where: S is the state space of the process;
1 Fem, Yoon, and Givan are also pursuing a similar approach.
A is a finite set of actions; Pis a Markovian transition model, where P( s, a, s') is the probability of making a transition to states' when taking action a in states; R is a reward (or cost) function, such that R( s, a) is the expected reward for taking action a in state s; 1 E [0, 1) is the discount factor for future rewards; and, D is the initial state distribution from which states are drawn when the process is initialized.
In reinforcement learning, it is assumed that the learner can observe the state of the process and the immediate reward at every step, however P and R are completely unknown. In this paper, we also make the assumption that our learning al gorithm has access to a generative model of the process which is a black box that takes a states and an action a as inputs and outputs a next states' drawn from Panda reward r. Note that this is not the same as having the model (P and R) itself.
A policy 1r for an MDP is a mapping 1r : S f---> A from states to actions, where 1r( s) is the action the agent takes at state s. The value V1T ( s) of a state s under a policy 1r is the expected, total, discounted reward when the process begins in state s and all decisions at all steps are made according to policy 1r:
The goal of the decision maker is to compute or learn an op timal policy 1r* that maximizes the expected total discounted reward from the initial state distribution:
It is known that for every MDP, there exists at least one opti mal deterministic policy.
3 (Approximate) Policy Iteration
Policy iteration (PI) is a method of discovering such a policy by iterating through a sequence of monotonically improving policies. Improvement at each iteration i is typically achieved by computing or learning the state-action value function Q7T, of the current policy 1ri, defined as
and then the improved policy as
In practice, policy iteration terminates in a surprisingly small number of steps, however, it relies on exact representation of value functions and policies.
Approximate methods are frequently used when the state space of the underlying MDP is extremely large and exact (solution or learning) methods fail. A general framework of using approximation within policy iteration is known as ap proximate policy iteration (API). In its most general form, A_!'l assumes approximate representations of value functions ( Q) and policies (7?) . As a result, API cannot guarantee mono tonic improvement and convergence to the optimal policy. A performance bound on the outcome of API can be constructed in terms of Loo bounds on the approximation errors [Bert sekas and Tsitsiklis, 1996]. In practice, API often finds very good policies m a few iterations, since it normally makes big steps m the space of possible policies. This is in contrast to policy gradient methods which, despite acceleration methods, are often forced to take very small steps.
4 Practical API without Value Functions
The dependence of typical API algorithms on approximate value functions places continuous function approximation m~thods at their inner loop. These methods typically mini mize L2 error, which is a poor match with the L00 bounds for API. This problem is not just theoretical. Efforts to im prove performance, such as adding new features, can some times lead to surprisingly worse performance, making feature engineering a somewhat tedious and counterintuitive task.
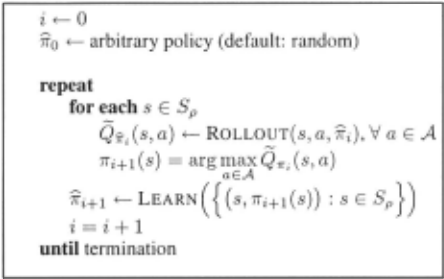
An important observation, also noted by Fern, Yoon and Givan [2003], is that a Monte-Carlo technique, called roll outs, can be used within API to avoid the problematic value function approximation step entirely. Rollouts estimate Qrr, (s, a) from a generative model by executing action a in state s .and following policy ni thereafter, while recording the tot~! d.Iscoun.ted :eward obtained during the entire trajectory. This simulatiOn IS repeated several times and the results are averaged over a large number of trajectories to obtain an accurate estimate Q rr, ( s, a) of Q rr, ( s, a). Rollouts were first used by Tesauro and Galperin [ 1997] for online improvement of a backga~mon player. For our purposes, we can choose a rep resentative set of states SP (with distribution p over the state space) and perform enough rollouts to determine which action maximizes Qrr, ( s, a) for the current policy. Rather than fitting a function approximator to the values obtained by the rollouts, we instead train a classifier on SP, where each state IS labelled with the maximizing action for the state. The al gorithm is summarized in Figure 1.
LEARN is a supervised learning algorithm that trains a clas sifier given a set of labeled training data. The termination condition is left somewhat open ended. It can be when the performance of the current policy does not exceed that of the previous one, when two subsequent policies are similar (the notion of similarity will depend upon the learner used), or when a cycle of policies is detected (also learner dependent). If we assume a fortuitous choice of S P and a sufficiently pow erful learner that can correctly generalize from S to the en-. p tire state space, the algorithm at each iteration learns the improved policy over the previous one, effectively implementing a full policy iteration algorithm, and terminating with the optimal policy. However, for large-scale problems, choosing SP and dealing with imperfect classifiers poses challenges.
We consider a number of alternative choices for the dis tribution p. A uniform distribution over the state space is a good choice for a low-dimensional state space, but it will result in poor coverage in high-dimensional spaces. A bet ter choice would be a distribution that favors certain impor tant parts of the state space over others. In classification it is widely assumed that the classifier is trained on exampies that are drawn from the same distribution it will be tested on. The:efo:e, representative states for learning policy ni+1 in it eratiOn t should be drawn from the 1 -discounted future state distribution [Jaakkola et al., 1995] of the yet unknown policy ni+l · Even though this policy is yet unknown, it is possible to closely approximate this distribution 2 . Starting in some state so drawn from D, a trajectory under ni+1 can be simulated by using rollouts repeatedly in each visited state to determine t~~ actions of ni+l · If the trajectory terminates with proba bility (1 - 1 ), then states visited along such trajectories can be viewed as samples from the desired distribution.
The main contribution of this paper is a particular em bodiment of the algorithm described in the previous section. For rollouts, we used basic statistical hypothesis testing (two sample t-test) to determine statistically significant differences between the rollout estimates of Q7r, for different actions. If action a is determined to be a clear winner for state s, then we treat ( s, a) as a positive training example for state s, and all (s , a'), a' =f. a as negative examples for s. Even if there is no cle~r winner action in some state s, negative examples can be still extracted for the clearly bad actions in s, allow ing the classifier to choose freely any of the remaining (good) actions as the winner. The only case where no examples are generated is when all actions seem to be equally good.
The most significant contribution of effort is the use of sup port vector machines (SVMs) for LEARN. In our implemen tation we used the SVMTorch package [Collobert and Ben gio, 2001] as the multi-class classifier. With the kernel trick SVMs are able to implicitly and automatically consider clas~ sifters with very complex feature spaces.
2 Special thanks to Alan Fern for sharing this observation.
5 Experimental Results
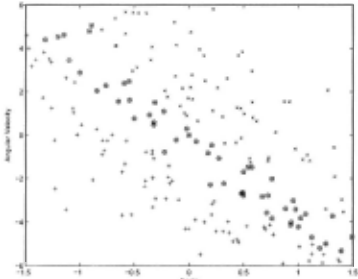
In the inverted pendulum problem the goal is to balance a pen dulum by applying forces to the left (LF), or to the right (RF), or no force (NF) at all. All actions are noisy. The state space is continuous and consists of the vertical angle and the angu lar velocity ofthe pendulum. Transitions are governed by the nonlinear dynamics of the system and the time step is 0.01 seconds. The reward is -1 when the angle exceeds 1r / 2 in absolute value (end of the episode) and 0 otherwise. The dis count factor is 0.95. Using about 200 states from p to perform rollouts, the algorithm consistently learns balancing policies in one or two iterations, starting from the random policy. The choice of p or the kernel (polynomiaVGaussian) did not affect the results significantly. Figure 2 shows the training data for the LF action with p being the uniform distribution. The num ber of support vectors was normally smaller than the number of rollout states. The constant C, the trade-off between train ing error and margin, was set to 1.
In the bicycle balancing and riding problem [Randle~v and Alstmm, 1998] the goal is to learn to balance and ride a bi cycle to a target position located 1 km away from the starting location. The state description is a six-dimensional vector ( B, iJ, w, w, w, 'If;), where B is the angle of the handlebar, w is the vertical angle of the bicycle, and 'If; is the angle of the bicycle to the goal. The actions are the torque T applied to the handlebar { -2, 0, +2} and the displacement of the rider v { -0.02, 0, +0.02}. Actions are restricted so that either T = 0 or v = 0 giving a total of 5 actions. The noise is a uniformly distributed term in [-0.02, +0.02] added to the displacement. The dynamics of the bicycle are based on the model ofRandle~v and Alstmm [1998] and the time step is set to 0.02 seconds. As is typical with this problem, we used a shaping reward [N g et a!., 1999]. The reward r t given at each time step was rt = (dt-1 - !dt), where dt is the distance of the back wheel of the bicycle to the goal position at time t and 1 is the discount factor which is set to 0.95.
Using a polynomial kernel of degree 5, we were able to solve the problem with uniform sampling of about 5000 roll out states. Sampling from the !-discounted distribution of the target policy, the problem is solved with as few as 1000 rollout states, as shown in Figure 3 which shows ten sam ple trajectories of the bicycle in the two-dimensional plane from the initial position (0, 0) (left side) to the goal position
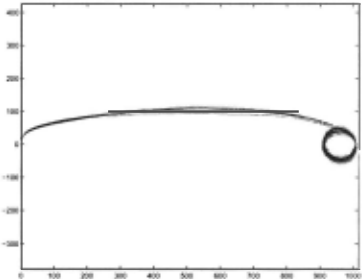
(1000, 0) (right side). The input to the SVM was simply the six-dimensional state description and the value of C was 1. Performance was sensitive to the SVM parameters. We are currently doing further experimentation with larger numbers of rollout states and different kernel parameters.
This research was supported in part by NSF grant 0209088.
@inproceedings{ijcai2003p226,
  title     = {Approximate Policy Iteration using Large-Margin Classifiers},
  author    = {Lagoudakis, Michail G. and Parr, Ronald},
  booktitle = {Proceedings of the Eighteenth International Joint Conference on
               Artificial Intelligence, {IJCAI-03}},
  publisher = {International Joint Conferences on Artificial Intelligence},
  editor    = {Georg Gottlob and Toby Walsh},
  pages     = {1432--1433},
  year      = {2003},
  url       = {https://ijcai.org/proceedings/2003/226},
}
TY - CPAPER TI - Approximate Policy Iteration using Large-Margin Classifiers AU - Lagoudakis, Michail G. AU - Parr, Ronald T2 - Proceedings of the Eighteenth International Joint Conference on Artificial Intelligence, IJCAI-03 PB - International Joint Conferences on Artificial Intelligence PY - 2003 SP - 1432 EP - 1433 UR - https://ijcai.org/proceedings/2003/226 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





