
Covariant Policy Search
Proceedings of the Eighteenth International Joint Conference on Artificial Intelligence. Pages 1019-1023.
© 2003 International Joint Conferences on Artificial Intelligence
Abstract
We investigate the problem of non-covariant behavior of policy gradient reinforcement learning algorithms. The policy gradient approach is amenable to analysis by information geometric methods. This leads us to propose a natural metric on controller parameterization that results from considering the manifold of probability distributions over paths induced by a stochastic controller. Investigation of this approach leads to a covariant gradient ascent rule. Interesting properties of this rule are discussed, including its relation with actor-critic style reinforcement learning algorithms. The algorithms discussed here are computationally quite efficient and on some interesting problems lead to dramatic performance improvement over noncovariant rules.
- [Amari and Nagaoka, 2000] S. Amari and H. Nagaoka. Methods of Information Geometry. Oxford University Press, 2000.
- [Bagnell and Schneider, 2001] J. Bagnell and J. Schneider. Autonomous helicopter control by policy-search based re- inforcement learning. In Proceedings of the 2001 IEEE Int. Conference on Robotics and Automation. IEEE, 200 I. [Baxteretal., 1999]
- J. Baxter, L. Weaver, and P. Bartlett. Direct-gradient-based reinforcement learning I: Gradient estimation algorithms. Technical report, Computer Sci- ences Lab, Australian National University, 1999.
- [Bertsekas and Tsitsiklis, 1996] D. Bertsekas and J. Tsitsik- lis. Neuro-Dynamic Programming. Athena Scientific, 1996.
- [Chentsov, 1980] N.N. Chentsov. Statistical Decision Rules and Optimal Inference. American Mathematical Society, 1980.
- [DeGroot, 1970] M. DeGroot. Optimal Statistical Decisions. McGraw-Hill, 1970.
- [Kakade, 2002] S. Kakade. A natural policy gradient. In Ad- vances in Neural Information Processing Systems (NIPS- 14), 2002.
- [Konda and Tsitsiklis, 2002] V. Konda and J. Tsitsiklis. Actor-critic algorithms. to appear in the SIAM Journal on Control and Optimization, 2002.
- [Peters et al., 2002] Jan Peters, Sethu Vijaykumar, and Ste- fan Schaal. Policy gradient methods for robot control. Technical Report 00-737, USC, 2002.
- [Sutton et al., 1999] R. Sutton, D. McAllester, S. Singh, and Y. Mansour. Policy gradient methods for reinforcement learning with function approximation. In Neural Informa- tion Processing Systems 12, 1999.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Much recent work in reinforcement learning and stochastic optimal control has focused on algorithms that search directly through a space of policies rather than building approximate value functions. Policy search has numerous advantages: do main knowledge may be easily encoded in a policy, the policy may require less representational power than a value-function approximation, there are simple extensions to the multi-agent domain, and convergent algorithms are known. Furthermore, policy search approaches have recently scored some encour aging successes [Bagnell and Schneider, 2001] [Baxter et at., 1999] including helicopter control and game-playing.
One interesting aspect of existing gradient search algo rithms, however, is that they are non-covariant; that is, a simple re-parameterization of the policy typically leads to a different gradient direction. (Not that found by applying the Jacobian of the re-parameterization to the gradient). This is a odd result; it is intuitively difficult to justify the gradi ent computation as actually indicating the direction of steep est descent. This problem is well recognized in the pattern recognition and statistics communities and is a very active area of research. [Kakade, 2002] was, to the best of our knowledge the first to identify this problem in reinforcement learning and to suggest that techniques from information ge ometry may prove valuable in its solution.
Inspired by the work of [Amari and Nagaoka, 2000], Kakade proposed a "natural gradient" algorithm. In particu lar, [Kakade, 2002] proposed a scheme for generating a met ric on parameter space that has interesting theoretical prop erties. Most convincingly, Kakade showed strong empiri cal evidence for the algorithm's usefulness. In particular, [Kakade, 2002] applies the algorithm to the Tetris problem of [Bertsekas and Tsitsiklis, 1996]. This problem is partic ularly interesting as value function methods (as for example described in [Bertsekas and Tsitsiklis, 1996] ) demonstrate non-monotone performance; first policy iteration improves the policy dramatically, but after a small number of iterations the policy gets much worse. Normal gradient methods, in cluding second-order and conjugate methods also prove very ineffective on this problem; even after a tremendous number of rounds they only mildly increase the performance of the game-player. The method presented in [Kakade, 2002] shows rapid performance improvement and achieves a significantly better policy than value-function methods (at their peak) in comparable time.
However, despite recognizing an interesting defect in the general approach and intuiting an apparently powerful algo rithm, Kakade concludes that his method also fails to be co variant leaving the problem open. We present here what we believe to be an appropriate solution.
In Kakade's work, there is no proper probability manifold, but rather a collection of such (one for each state) based on the policy. As such, Kakade must rely on an ad-hoc method for generating a metric. Here instead we take a proper mani fold, the distribution over paths induced by the controller, and compute a metric based on that. In the special case appropri ate to the average reward RL formulation, Kakade's scheme is shown to give rise to a bona-fide natural metric, despite the observation in the paper that the learning was non-covariant. We believe this is an artifact- perhaps of step-length. Fur ther, we note that parametric invariance does not require this metric- there are numerous covariant metrics. Rather, a stronger probabilistically natural invariance demands the metric used. We describe this result to motivate our method.
Importantly, the notion of the metric on the path distribution allows us to provide very simple and natural ex tensions to Kakade's algorithm that cover the finite horizon, discounted start-state, and partially-observed reinforcement learning problems as well as the average reward one. Finally, for completeness, we describe the result discovered by Kakade relating the invariant metric and compatible actor critic methods [Sutton eta!., 1999].
1.1 Problem Setup and Notation
A stochastic control problem consists of paths ~ (also called system trajectories) in a space 3, a distribution over path space, p(~), that is a function of a sequence of (finite) controls (at)tE{O, .. . ,T}· indexed by time, from a space A. Throughout this paper we will be considering Partially Observed Markov Decision Problems, in which there are state-variables (xt) of the system that compose a path ~ and render the past and fu ture independent. In a POMDP, p(~) is defined by an initial state and next state transition probabilities p(xt lxt-l, at-1) . We also typically have a sequence of outputs (observations) (Yt)tE{O ... T} measurable with respect to Xt. A controller (or policy), 1r, usually parameterized by B, is a feedback-type strategy that maps the history of observations (Yt)tE{O .. r} to a distribution over controls ar . Most of the derivations will be given in terms of memoryless stochastic controllers that map the current state to a distribution over actions, although they can be easily extended to finite window or recurrent rep resentations that operate on only the observations. The goal in a control problem is to maximize the expected reinforce ment J(B) = l::=:Po(~)r(~) with respect to B. The sum is always assumed to exist for all controllers. The reward func tion on paths in a POMDP is additive in time (or in the infi nite time case, discounted or averaged), and a function R(x) of state, although the algorithms discussed here are not neces sarily predicated on that assumption. Reinforcement learning is the adaptive version of the control problem where we at tept to maximize the expected reinforcment by sampling tra jectories and then improving our policy. We use the notation 8; throughout to denote a~, where the parameter B should be clear from context. For vectors x andy, we use the notation (xllY)M to denote the inner product with respect to metric M. The notation (f(x))p(x) indicates the expected value of the function f with respect to the distribution p.
2 Covariance and Riemannian manifolds
2.1 Meaning of steepest ascent
For direct policy search methods, we are interested in finding the direction of steepest ascent with respect to our current pa rameters. That is, we wish to maximize the reward function J(B + 6.B) subject to (6.BJJ6.B) = E, an infinitesimal. If we reparameterize our controller in terms of, e.g. (,and express the same effective infinitesimal policy change in terms of these parameters, 6.J will of course remain the same. How ever, if we measure lengths using the naive dot product, the same effective change will not have the same size. It is this problem that leads to the odd behavior of "steepest descent" rules.
2.2 Non-covariant learning rule
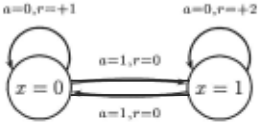
To demonstrate the problem we first consider a simple two state, two action MDP described in [Kakade02]. (Figure 1) In state 0 executing action 0 returns to the same state and gets a reward of 1. Executing action 1 get no reward but transits to state 1. In state 1, action 0 returns to state 1 and gets reward 2. Action 1 transits to state 0 and achieves no reward.
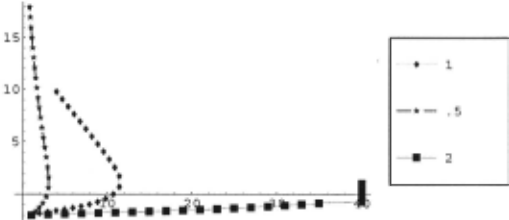
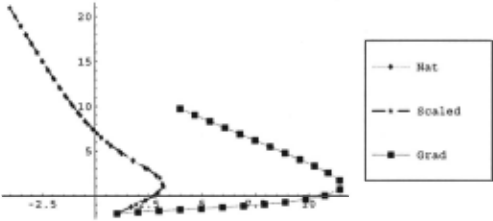
Consider parameterized probabilistic ~olicies ~f the form 1r(a = OJx; B) = l+ex90o. o+e 1 s. 1 . ,\IS an arbitrary scale parameter that we use to demonstrate that even mildly differ ent parameterization lead to dramatically different behavior. Below we plot the resulting track through the space of poli cies using the log ratio of probabilities of the actions for each of the possible states. We start from a policy that makes it somewhat more likely to choose action 0 in state 0 and action 1 in state 1. We then scale ,\ to 1, .5, and 2 and plot the log odds of the policy from state 1 (Figure 2).
The non-covariant behavior is quite clear in this graph. Further, we note that it is very difficult to achieve a good policy using this algorithm from this starting point as the wrong action becomes overwhelmingly likely to be chosen from state 0. If sampling were used to compute the gradient, we would nearly never get samples from state 1- which we need to improve the policy.
2.3 Path distribution manifolds
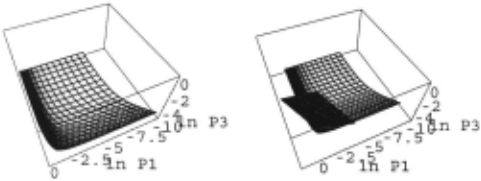
The control problem is essentially a coupled one of optimiza tion and integration over the space of possible paths, 3 . This motivates the idea that instead of considering the (arbitrary) distance in terms of parameterization of the policy, we may consider distance in terms of the change in distribution over paths resulting from the policy change. We may view the distribution over paths p(~; B) as a parameterized manifold (nominally embedded in Rl 2 1 ) of dimension JBJ. This takes some work to visualize; as an example consider a space of three possible paths. All possible distributions over these three paths can be smoothly represented with two parameters. In Figure 3 (left) we see one visualization with the embedding log p(~; B)) :
With n parameters, assuming no redundancy, we generate an n dimensional manifold. In the case pictured, it is the set of all distributions on 3 paths, but in general, the dimension ality of the path probability manifold will be tremendously less than the number of possible paths. It is important to un derstand the manifold under consideration is that of the prob ability distribution over paths and not of paths themselves.
The study of parameterized manifolds like that pictured above is the domain of differential geometry. Here we are interested in establishing a Riemannian structure on the man ifold of paths. By that we mean we wish to establish a metric on the tangent space (the local linear approximation to the manifold at a point D, so we can measure small parameter changes. We do this with the metric (X!IY)P 9 (€) on the tan gent space (which is spanned by the partials with respect to each parameter) as Li,j�ii(~)X;}j, where G is a positive definite matrix. This is a very natural thing to do- instead of just the standard dot product, we have a dot product that allows us to represent rotations and scalings (exactly what a positive definite matrix can represent) and that can vary throughout the manifold. In Figure 3 (right) we depict the tangent space at a point in our parameterization as the local linear approximation at that point.
2.4 Steepest ascent on Riemannian manifold
There are two questions that then naturally arise- what is steepest descent on a function defined over a Riemannian space, and is there a Riemannian metric on the manifold of the paths that is in some sense natural. We quickly answer the first question, and pursue the second in the next two sec tions. A Lagrange multiplier argument (given schematically here) makes it easy to see the form of the steepest descent direction.
Form the Lagrangian:
and take derivatives with respect to each t5B, then set to zero to solve for the optimal direction:
This implies that (since G is positive definite and hence invertible), giving us:
That is, the direction of steepest descent is simply the nor mal gradient times the inverse of the metric evaluated at the point of tangency. We call this the "natural gradient" for the Reimannian manifold. [Amari and Nagaoka, 2000]
3 Invariance and Chentsov's Theorem
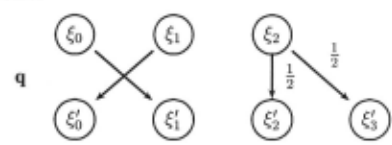
Some confusion seems to surround the choice of metric on probability manifolds. There is no unique answer for this metric, even under the supposition of parametric invariance as suggested by some authors. The issue is rather more sub tle. Any metric that transforms under parameter change ac cording to the Jacobian of the function connecting parameters meets this requirement. This type of parametric covariance is a minimum requirement for us. It is natural to suggest a met ric that preserves essential probabilistic aspects of the mani fold. Consider, for example, functions q (Markov mappings, congruent embeddings, or sufficient statistics, depending on your viewpoint) that carry one distribution over paths to an other in a natural and recoverable way. For example, con sider the mapping between the two distributions P(paths) and P(paths')given by congruent embedding q depicted below:
Paths
Paths'
The mapping q above interchanges the role of two paths and splits one path into two (with probability l/2 for each split). In a probabilistically fundamental way, the mani folds P(path) and P(path') (where we imagine P(path) is a smoothly parameterized set of distributions) are similar to each other. For each path' we can uniquely recover the original probability. In this way, a parameterized distribu tion over paths can be embedded into a different path space. (This equivalence can actually be phrased in a category the oretic way where the morphisms are these congruent embed dings.) [Chentsov, 1980] General congruent embeddings can be thought of as simply generalizations of the example de picted above to allow arbitrary permutations and arbitrary probabilities for different paths stemming from a single path, as well as compositions of these two. In the control problem this could arise by simple permutation of the state variables or change of co-ordinates to ones with redundant information. It is natural to require that with our metric the congruent em bedding is an isometry on the tangent space. (i.e. preserves the length of the vectors). That is, if we make a change of size t: (under the metric Go) to the distribution Po (paths)then carrying that change through q we should measure the same change t: using G q(Pe). Adding the requirement of invariance with respect to congruent em beddings leads to a unique (up to scale) metric on the manifold. [Chentsov, 1980] This metric is well-known in statistical inference as the Fisher-Rao metric and it can be written as the Fisher information matrix [DeG root, 1970]:
Another way to derive the metric is to think about "dis tances" on probability spaces. The KL-divergence (or rel ative entropy) between two distributions is a natural diver gence on changes in a distribution. It is also manifestly in variant to re-parameterization. If we think about derivatives as small changes in parameters (differentials) then we dis cover that we also get a unique metric as the second-order Taylor expansion of the KL-divergence. This too agrees with the Fisher information (up to scale). We note that the di rection of the KL-divergence is irrelevant as to second-order KL(p, q) = KL(q,p) [Amari and Nagaoka, 2000].
4 Fisher-Rao Metric on the Path-space Manifold
The issue now becomes how to derive the Fisher metric on the space of path distributions. It turns out in the case of processes with underlying Markovian state to be rather easy, and involves only computations we already make in the likeli hood ratio approach standard in gradient-based reinforcement learning.
4.1 Derivation of finite-time path metric
The Fisher information metric involves computing (8; Iogp(~; B)8jlogp(~; B))p({;O) · Fortunately, this is easy to do. The essential algorithm within gradient methods like REINFORCE and GPOMDP is a clever method of computing (8;logp(~; B))p({;O)' the expected score function. Thus, while the expected score is the gradient, the correlation of the score is the Fisher matrix. The following simple algorithm is unbiased and converges almost surely (under the same regularity conditions as in [Baxter et al., 1999] as the number of sample paths m goes to infinity:
Algorithm 1 (Finite-horizon metric computation) For i in 1 tom:
- Sample a path using the policy 1r(B): ~i (xl,al,x2,a2,··· ,xn)
- For t in 1 to n:
We use the Markov property and the invariance of the tran sition probabilities (given the actions) in the algorithm above to compute 8;logp(~; B) simply. These details can be ex tracted from the proofs below, as well as other, potentially better ways to sample.
To compute the natural gradient, we simply invert this ma trix and multiply it with the gradient computed using standard policy search methods.
4.2 Limiting metric for infinite horizon problems
A well-known result in statistics [DeGroot, 1970] gives a dif ferent form for the Fisher metric under appropriate regularity conditions. We quickly derive that result, and then show how this gives us a simple form for the path probability metric as t -t 00.
The third line follows from the second by integrating by parts and the fifth follows by observing that the total proba bility is constant.
Now we show that in the limit this leads to a simple metric for the infinite horizon case. To get a convergent metric, we must normalize the metric, in particular by the total length of the path denoted t. Since the metric is defined only up to scale, this is perfectly justified.
Theorem 1 (Infinite-Horizon Metric) For an ergodic Markov process the Fisher information matrix limits to the expected Fisher information of the policy for each state and control under stationary distribution of states and actions. Proof" We use �~ to indicate the t-step finite-horizon metric.
For a Markov process we can write the likelihood ratio a,p({;O) p({;O) as
Using the chain rule we continue the derivation with dtr (x) indicating the stationary distribution:
where the second equality follows by noting that the like lihood ratio is independent of transition probability matrix given the action probability, and by application of the ergodic theorem. The last line follows (with Gx;ll the Fisher informa tion for the policy at a given state) as the second term in line 3 vanishes since the total probability is constant with respect w~ ·
It is also interesting to consider what happens in the start state, discounted formulation of the problem. In this case we would like our metric, using the general definition over path distributions given above, to naturally weigh the start start more than it necessarily is in the infinite horizon average case. It is well-known that a discount factor 'Y is equivalent to an undiscounted problem where each trajectory terminates with probability 1 - 'Y at each step. We can use this fact to derive a metric more appropriate for the discounted formalism.
Theorem 2 (Start-State Metric) For a discounted Markov process the Fisher information matrix equals the Fisher in formation of the policy for each state and control under the limiting distribution of states and actions. Proof The proof is very similiar to the infinite horizon case and so we simply sketch it:
·
where dtr ( x) = I:t 'Yt Prtr ( Xt = x) is the limiting distri bution of states. Thus the infinite horizon (undiscounted) and start-state metrics give essentially the same metric, with only the effective weighting by states differing.
4.3 Metrics for Partially Observed Problems
For policies that map the observation space of a partially observed markov decision process into distributions over ac tions, it is just as easy to derive appropriate metric using our approach. The tuple (xt, at, Yt) is also a markov chain, and with only subtle changes to the arguments above we end up with the same metric except using the limiting distribution of observations instead of states.
5 Relation to Compatible Value Function Actor Critic
Kakade noticed a fascinating connection between the limit ing metric given in Theorem 1 and the improvement direction computed by a class of actor-critic methods that use a special compatible function approximation technique.[Sutton et al., 1999; Konda and Tsitsiklis, 2002] Following Kakade we let '1/J(s, a) = o;logp(aix; e) and let the compatible function ap proximator be linear in '1/J:
This type of value function approximator was initially sug gested as it may be used to compute the true gradient. In prac tice, it has not been clear what advantage this brings over the gradient estimation routines of [Baxter et al., 1999]. How ever, "folk-wisdom" has it that performing an that infinitesi mal policy iteration (moving in the direction of the best policy according to r(x,a;w)) using this approximation has very good properties and often significantly outperforms standard gradient methods. The natural gradient provides insight into this behavior. Let w minimize the squared value-function er ror:
where Q(x, a; e) is the exact advantage function. [Sutton et al., 1999] It is easy to check that ([Kakade, 2002], Theo rem 1) w <X G II -l o;J (e). That is, the direction of maximum policy improvement is exactly the natural gradient direction. This can be seen by simply differentiating t:.(w;e) to minimize it with respect to w and noting the result of [Sutton et al., 1999] that
6 Demonstration
As a consequence of the results of section 5 and [Kakade, 2002], experimental results already exist demonstrating the effectiveness of the natural gradient method. That is, all re sults using policy improvement with compatible function ap proximators are implicitly computing this result. As a demon stration, we computed analytically the natural gradient for the problem given in Section 2.2. This problem is interesting as it reveals some of the properties of the natural gradient method. First it is easily checked that for a complete Boltzmann policy in an MDP the natural gradient computes:
This means that it is very similiar to the standard gradient except that it removes the weighting of states by the stationary distribution. Rather, each state is treated equally. This leads to much more reasonable results in the problem discussed as the partial derivative component for state 1 does not shrink as the policy changes initially.
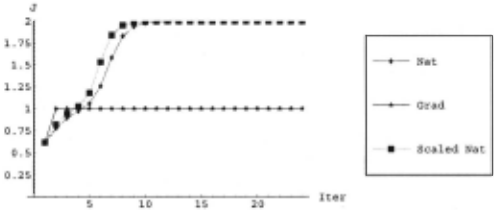
In Figure 4 we plot the performance of the natural gradi ent (using two different scalings) and the standard gradient methods in optimizing the policy for this problem.
It is interesting to note that in this graph the behavior of the natural gradient descent algorithm appears to be non covariant. This is simply due to the step size heuristic not computing equivalent steps in the policy space. The direction however is constant as illustrated in Figure 5.
7 Conclusions
[Kakade, 2002] suggested that covariant behavior of gradient algorithms is an important desiderata in reinforcement learning. Unfortunately, working in the space of policies, it was difficult to generate such an algorithm. Here we proposed considering the induced path-distribution manifold and used notions from information geometry to propose a natural co variant algorithm. This leads to interesting insight and a prac tical algorithm. Fortunately, it agrees with the heuristic sug gested by Kakade (despite the suggestion in the paper that the algorithm there was actually not covariant) in the infinite horizon case and extends to cover new problems. [Peters et al., 2002] independently developed theory related to ours (in particular the theorems in Section 4.2) and presented results in the context of robot dynamic control.
Further work will provide more investigation into the ex perimental behavior of the algorithms presented. Future ef fort may also yield deeper insight into the relationship be tween the method presented here and value-function approx imations.
@inproceedings{ijcai2003p145,
  title     = {Covariant Policy Search},
  author    = {Bagnell, J. Andrew and Schneider, Jeff G.},
  booktitle = {Proceedings of the Eighteenth International Joint Conference on
               Artificial Intelligence, {IJCAI-03}},
  publisher = {International Joint Conferences on Artificial Intelligence},
  editor    = {Georg Gottlob and Toby Walsh},
  pages     = {1019--1023},
  year      = {2003},
  url       = {https://ijcai.org/proceedings/2003/145},
}
TY - CPAPER TI - Covariant Policy Search AU - Bagnell, J. Andrew AU - Schneider, Jeff G. T2 - Proceedings of the Eighteenth International Joint Conference on Artificial Intelligence, IJCAI-03 PB - International Joint Conferences on Artificial Intelligence PY - 2003 SP - 1019 EP - 1023 UR - https://ijcai.org/proceedings/2003/145 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





