
Latent Class Models for Collaborative Filtering
Proceedings of the Sixteenth International Joint Conference on Artificial Intelligence. Machine Learning. Pages 688-692.
© 1999 International Joint Conferences on Artificial Intelligence
Abstract
This paper presents a statistical approach to collaborative filtering and investigates the use of lat e nt class mod els for predicting individual choices and preferences based on observed preference behavior . Two models are discussed and compared: the aspect model, a probabilistic latent space model which models individual preferences as a convex combination of preference factors , and the two-sided clustering model, which simultaneously partitions persons and objects into clusters. We present EM algorithms for different variants of the aspect model and derive an approximate EM algorithm based on a variational principle for the two-sided clustering model. The benefits of the different models are experimentally investigated on a large movie data set.
- [Dempster et al., 1977] A.P. Dempster, N.M. Laird, and D.B. Rubin. Maximum likelihood from incomplete data via the EM algorithm. J. Royal Statist. Soc. B, 39:1-38, 1977 .
- [Geiger and Heckerman, 1996] D. Geiger and D. Heck- erman . Knowledge representation and inference in similarity networks and Bayesian multinets. Artifical Intelligence, 82(1):45-74, 1996.
- [Goldberg et a/., 1992] D. Goldberg, D. Nichols, B.M. Oki , and D. Terry. Using collabrorative filtering to weave an information tapestry. Communications of the ACM, 35(12):61-70 , 1992.
- [Hofmann and Puzicha, 1998] T. Hofmann and J. Puzicha. Statistical models for co-occurrence data. Technical report, Artifical Intelligence Labora- tory Memo 1625, M.I.T. , 1998.
- [Hofmann et al., 1999] T. Hofmann, J. Puzicha, and M. I. Jordan . Learning from dyadic data. In Advances in Neural Information Processing Systems 11, 1999.
- [Jordan et a/. , 1998] M.l . Jordan, Z. Ghahramani, T.S. Jaakkola, and L.K . Saul. An introduction to varia- tional methods for graphical models. In M.l. Jordan, editor, Learning in Graphical Mode is, pages 105-161. Kluwer Academic Publishers, 1998.
- [Resnik et al. , 1994] P. Resnik, N. Iacovou, M. Suchak, P. Bergstrom , and J. Riedl. Grouplens: An open archi- tecture for collaborative filtering of netnews. In Pro- ceedings of the ACM, Conference on Computer Sup- ported Cooperative Work, pages 175-186, 1994.
- [Ungar and Foster, 1998] L. Ungar and D. Foster. A formal statistical approach to collaborative filtering . In Conference on Automated Learning and Dicovery, CONALD'98, CMU, 1998.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
The rapid growth of digital data repositories and the overwhelming supply of on-line information provided by today's communication networks bears the risk of con stant information overload. Information filtering refers to the general problem of separating useful and impor tant information from nuisance data. In order to support individuals with possibly different preferences, opinions, judgments, and taste, in their quest for information, an automated filtering system has to take into account the diversity of preferences and the relativity of information value. One commonly distinguishes between (at least) two major approaches [Resnik et al., 1994]: (i) content based filtering organizes information based on properties of the object of preference or the carrier of information such as a text document , while (ii) collaborative filtering [Goldberg et a/., 1992] (or social filtering) aims at ex ploiting preference behavior and qualities of other per sons in speculating about the preferences of a particular individual.
1.1 Information Filtering
Most information filtering systems have been designed for a particular application domain, and a large fraction of the research in this area deals with problems of sys tem architecture and interface design. In contrast, this paper will take a more abstract viewpoint in order to clarify some of the statistical foundations of collaborative filtering . In particular, the presupposition is made that no external knowledge beyond the observed preference or selection behavior is available, neither about proper ties of the objects (such as documents, books, messages, CDs, movies, etc.) nor about the involved persons (such as computer users , customers, cineasts, etc.). This work ing hypothesis is not as unrealistic as it may seem on first sight since, for example, many computer systems which interact with humans over the Web do not collect much personal data for reasons of privacy or to avoid time consuming questionnaires. The same is often true for properties of objects where it is sometimes difficult to ex plicitly determine those properties that make it relevant to a particular person. Moreover , one might integrate information from both sources in a second step, e.g., by deriving prior probabilities from person/object features and then updating predictions in the light of observed choices and preferences.
1.2 Dyadic Data
We thus consider the following formal setting: Given are a set of persons X = { x1, . .. , x N} and a set of objects Y = {Yl, . .. , YM} . We assume that observations are available for person/object pairs (x, y), where x EX and y E Y; this setting has been called dyadic data in [Hof mann et a/., 1999]. In the simplest case, an observation will just be the co-occurrence of x and y , representing events like "person x buys product y" or "person x par ticipates in y" . Other cases may also provide some addi tional preference value v with an observation. Here, we will only consider the simplest case, where v E { -1, +1} corresponds to either a negative or a positive example of preference, modeling events like "person x likes/dislikes object y".
Two fundamental learning problems have to be ad dressed : (i) probabilistic modeling and (ii) structure discovery. As we will argue, different statistical models are suitable for either task. The aspect model presented in Section 2 is most appropriate for prediction and recom mendation, while the two-sided clustering model intro duced in Section 3 pursues the goal of identifying mean ingful groups or clusters of persons and objects. All discussed models belong to the family of mixture mod els , i.e., they can be represented as latent variable mod els with discrete latent variables. The main motivation behind the introduction of latent variables in the con text of filtering is to expla\n the observed preferences by some smaller number of (typical) preference patterns which are assumed to underly the data generation pro cess. In probabilistic modeling, this is mainly an attempt to overcome the omnipresent problem of data sparseness. Models with a reduced number of parameters will in gen eral require less data to achieve a given accuracy and are less sensitive to overfitting. In addition, one might also be interested in the structural information captured by the latent variables, for example, about groups of people and clusters of objects .
2 The Aspect Model
2.1 Model Specification
In the aspect model [Hofmann eta/. , 1999], a latent class variable z E Z = { z1 , ... , ZK} is associated with each ob servation (x, y). The key assumption made is that x and y are independent , conditioned on z. The probability model can thus simply be written as
where P(xl z) and P(yi z) are class-conditional multi nominal distributions and P(z) are the class prior prob abilities. Notice that the model is perfectly symmet ric with respect to the entities x and y. Yet, one may also re-parameterize the model in an asymmetric man ner, e.g., by using the identity P(z)P(xi z) = P(x , z) = P(x)P(zlx) which yields
A dual formulation can be obtained by reversing the role of x and y. Eq. (3) is intuitively more appealing than (1) since it explicitly states that conditional probabilities P(ylx) are modeled as a convex combination of aspects or factors P(yi z). In the case of collaborative filtering, this implies that the preference or selection behavior of a person is modeled by a combination of typical pref erence patterns, represented by a distribution over ob jects. Notice that it is neither assumed that persons form 'groups', nor is stipulated that objects can be pa~t~t~on~d into 'clusters'. This offers a high degree of ftextbthty m modeling preference behavior: Persons may have a mul titude of different interests, some of which they might share with some people, some with others , a fact which can be expressed perfectly well in the aspect model. It is also often the case that objects are selected by different people for different reasons . In this case, one might have a number of aspects with high probability P(yiz) for a particular object y.
2.2 Model Fitting by EM
The standard procedure for maximum likelihood estima tion in latent variable models is the Expectation Max imization (EM) algorithm [Dempster et a/. , 1977). EM alternates two steps: (i) an expectation (E) step where posterior probabilities are computed for the latent vari ables z, based on the current estimates of the parame ters , (ii) an maximization (M) step, where parameters are updated for given posterior probabilities computed in the previous E-step.
For the aspect model in the symmetric parameteriza tion Bayes' rule yields the E- step
By standard calculations one arrives at the following M step re-estimation equations
where n(x, y) denotes the number oftimes the pair (x, y) has been observed. Alternating (4) with (5) and (6) defines a convergent procedure that approaches a local maximum of the log- likelihood .
Implicit in the above derivation is a multinomial sam pling model, which in particular implies the possibility of multiple observations. This may or may not be appro priate and one might also consider hypergeometric sam pling without replacement, although according to sta tistical wisdom both models are expected to yield very similar results for large populations.
2.3 Extension to Preference Values
Let us now focus on extending the aspect model to cap ture additional binary preferences v E { -1, +1}. 1 We distinguish two different cases: (1.) situations where the selection of an object is performed by the person, which then announces her or his preference in retrospect, (II.) problems where the selection of y is not part of the be havior to be modeled, for instance because it is controlled or triggered by some other external process.
1 The presented models can be further generalized to han dle arbitrary preference values, but this requires to specify an appropriate likelihood function based on assumptions on the preference scale.
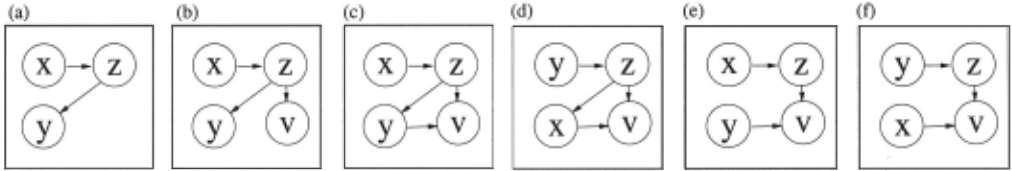
Case I. In the first case, there are three different ways to integrate the additional random variable v into the model, as shown by Figure 1 (b)-(d) . In (b) v is con ditionally independent of x and y given z, which is a very strong assumption. One implication is that aspects are typically employed to either model positive or nega tive preferences. In variant (c) and (d), v also depends on either x or y which offers considerably more flexibil ity, but also requires to estimate more parameters. It is straightforward to modify the EM equations appropri ately. We show the equations for model (c) , the other variants require only minor changes. For the E-step one obtains
while the M-step equations can be summarized into
where n(x, y, v) denotes the number of times a particu lar preference has been observed (typically n(x , y, v) E {0, 1}). From P(y,viz) one may also derive P(yiz) and P(vly, z), if necessary. TheM-step equation for P(xlz) does not change. Effectively the state space of Y has been enlarged to Y' = Y x { -1, + 1}.
Notice that one might also consider to combine the model variants in Figure 1 by making different condi tional independence assumptions for different values of z . The resulting combined model corresponds to a Bayesian multinet [Geiger and Heckerman, 1996].
Case II. In the second case, the multinomial sampling model of selecting y or a (y, v) pair conditioned on z is no longer adequate. We thus propose a modification of the aspect model starting from (3) and replace multinomials P(yiz) with Bernoulli probabilities P(vly, z), assuming that y is always conditioned on ( cf. Figure 1 (e)). This modification results in the E-step
and a M -step re-estimation formula
Comparing (9) with (7) one observes that P(y, viz) is now replaced by P (vI y, z) since y is treated as a fixed (observation-dependent) conditioning variable. Note that by conditioning on both, x and y, one gets P(vlx , y) = L z P(vly, z)P(zlx) which reveals the asym metry introduced into the aspect model by replacing one of the class-conditional multinomials with a vector of Bernoulli probabilities. The presented version is the "collaborative" model. Reversing the role of x and y yields the dual counterpart in Figure 1 (f), where the prediction of v depends directly on x and only indirectly on y (through z). Again combining both type of depen dency structures in a multiriet might be worth consider ing.
3 The Two-Sided Clustering Model
3.1 Model Specification
In the two-sided clustering model the strong assump tion is made that each person belongs to exactly one group of persons and that each object belongs to exactly one group of objects. Hence we have latent mappings c(x) E C = {c1 , .. . ,cK} and d(y) E V = {d1, ... ,dL} which partition X into [( groups and Y into L groups, respectively. This is very different in spirit from the as pect model, where the leitmotif was to use convex com binations of prototypical factors . While we expect the clustering model to be less flexible in modeling prefer ences and less accurate in prediction (a fact which could be verified empirically), it might nevertheless be a valu able model for structure discovery which has applications of its own right . To formalize the model, let us intro duce the following sets of parameters: P(x) and P(y) for the marginal.probabilities of persons and objects, P( c) and P( d) for the prior probabilities of assigning persons/objects to the different clusters, and, most im portantly, cluster association parameters ¢(c, d) E JRt between pairs of cluster (c, d) . Now we may define a probabilistic model by
A factorial prior on the latent class variables
| Star Trek IV 0.024 Star Trek II 0.023 Star Trek VI 0.023 Star Trek III 0.021 The Fifth Element 0.018 | Dr. Strangelove 0.029 A Clockwork Orange 0.020 Delicatessen 0.018 Cinema Paradiso 0.018 Brazil 0.017717 | Pinocchio 0.281 The Aristocats 0.213 Snow White and the Seven Dwarfs 0.211 The Jungle Book 0.049 The Lion King 0.020 | Richard III 0.160 Les Miserables 0.124 The Madness of King George 0.113 In the Name of the Father 0.076 The Visitors (Les Visiteurs) 0.043 |
| The Rock 0.553 Eraser 0.232 Independence Day (ID4) 0.089 Mission: Impossible 0.077 Trainspotting 0.021 | The Piano 0.288 The Remains of the Day 0.077 In the Name of the Father 0.067 Forrest Gump 0.052 Shadowlands 0.047 | Ready to Wear 0.097 What's Love Got To Do With It? 0.091 Circle of Friends 0.070 Dolores Claiborne 0.037 When a Man Loves a Woman: 0.030 | Como Agua Para Chocolate 0.132 Three Colors: Red: 0.086 Three Colors: Blue: 0.079 Three Colors: White: 0.068 The Piano: 0.064 |
completes the specification of the model. The associa tion parameters ¢; increase or decrease the probability of observing a person/object pair (x, y) with associated cluster pair ( c, d) relative to the unconditional indepen dence model P(x, y) = P(x)P(y). In order for (11) to define a proper probabilistic model, we have to ensure a correct global normalization, which constrains the choice of admissible values for the association parameters ¢;.
3.2 Variational EM for Model Fitting
The main difficulty in the two-sided clustering model is the coupling between the latent mappings c( x) and d(y) via the cluster association parameters ¢;(c, d). An additional problem is that the admissible range of¢; also depends on c( x) and d(y). Since an exact EM algorithm seems to be out of reach, we propose an approximate EM procedure. First, since c(x) and d(y) are random variables we define the admissible range of ¢; to be the set of values for which
where the expectation is taken w.r.t. the posterior class probabilities
Secondly, the posteriors P:'J ( ¢;) are approximated by a variational distribution of factorial form,
where the Q distributions are free parameters to be de termined. In the (approximate) M-step one has to max imize [Hofmann and Puzicha, 1998)
with respect to ¢;. Technically, one introduces a La grange multiplier to enforce (13) and after some rather lengthy calculations arrives at the equation
where P: and P:J are marginals of the posteriors P:'J and n(x), n(y) are marginal counts. Eq. (16) can be given a very intuitive interpretation by considering the hard clustering case of P:'J E {0, 1}, where it reduces to the expected mutual information between pairs of classes c and din either spaces: the numerator in (17) then sim ply counts the number of times a person x belonging to a particular cluster c has been observed in conjunction with an object y from cluster d, while the denominator reduces to the product of the probabilities to (indepen dently) observe a person from cluster c and an object from d.
It remains to perform the variational approximation and to determine values for the Q-distributions by choosing Q in order to minimize the KL-divergence to the true posterior distribution. Details on this method also known as mean-field approximation - can be found in [Jordan eta/., 1998; Hofmann and Puzicha, 1998). For brevity, we report only the final form of the variational E-step equations:
Notice that these equations form a highly non-linear, coupled system of transcendental equations. A solu tion is found by a fixed-point iteration which alternates the computation of the latent variables in one space (or more precisely their approximate posterior probabilities) based on the intermediate solution in the other space, and vice versa. However, the alternating computation has to be interleaved with a re-computation of the ¢ parameters, because certain term cancelations have been exploited in the derivation of (18,19). The resulting al ternation scheme optimizes a common objective function and always maintains a valid probability distribution. To initialize the model we propose to perform one-sided clustering, either in the X or the Y space.
| Four Weddings and a Funeral Home Alone Sleepless in Seattle Dave Pretty Woman The Piano | Apollo 13 Batman Batman Forever Star Trek: Generations Stargate Goldeneye | E.T.: The Extraterrestrial Alice in Wonderland Cinderella Old Yeller Mary Poppins The Fox and the Hound | M*A*S*H Full Metal Jacket The Bridge on the River Kwai Apocalypse Now Chinatown The Shining | Kalifornia Short Cuts Smoke Red Rock West Romeo is Bleeding Crumb |
3.3 Clustering with Preference Values
Like the basic aspect model, the two-sided clustering model is based on multinomial sampling, i.e., it models independently generated occurrences of (x, y) pairs. To model preference values v conditioned on (x, y) pairs, we modify the model by replacing the association parame ters¢ with Bernoulli parameters P(vlc, d),
The assumption is that v is independent of x and y, given their respective cluster memberships. 2 Although the latent mappings c and d are coupled, this model is somewhat simpler than the model in (11), since there is no normalization constraint one needs to take care of. The conditional log-likelihood is thus simply
where of course P(-1lc,d) = 1- P(+1lc,d). ~n the M-step we have to maximize E[£], the expected log likelihood under the posterior distribution of the latent mappings c(x) and d(y) which yields the formula
In the hard clustering limit , this simplifies to counts of how many persons in cluster c like ( v = + 1) or dis like (v = -1) objects from cluster d (ignoring missing values). The denominator then corresponds to the to tal number of votes available between x's belonging to c and y's belonging to d. A factorial approximation of the posterior probabilities P;J along the same lines as discussed above, yields '
2 Refined models may also consider additional weights to account for individual preference averages.
| K(L) | Aspect Co-occ. (a) | Cluster Co-occ. | Aspect Pref. (d) |
| 1 (1) | 442 | 442 | 827 |
| 8 (8) | 255 | 349 | 475 |
| 16 (16) | 241 | 335 | 442 |
| 32 (32) | 237 (228) | 308 | 434 (401) |
| 64 (64) | 234 (224) | 341(301) | 425 (395) |
| 128(128) | 231 (219) | 380(298) | 418 (388) |
These equations are very similar to the ones derived in [Ungar and Foster, 1998]. The clustering model they present is identical to the Bernoulli model in (20), but the authors propose Gibbs sampling for model fitting, while we have voted for the computationally much faster variational EM algorithm. 3
4 Experimental Results
To demonstrate tl;le utility of latent class models for col laborative filtering, we have performed a series of ex periments with the EachMovie dataset which consists of data collected on the internet (almost 3 million prefer ence votes on a 0-5 scale which we have converted to -1/ + 1 preferences by thresholding). 4 Table 1 summarizes perplexity results 5 obtained with the aspect model and the two-sided clustering model for different number of latent classes. As expected the performance of the as pect model is significantly better than the one obtained with the clustering model. The aspect model achieves a reduction of roughly a factor 2 over the marginal inde pendence model (baseline at J( = 1). By using anneal ing techniques ( cf. [Hofmann and Puzicha, 1998]) slightly better results can be obtained (numbers in brackets).
3 For example, on the Each Movie database used in the experiments we were not able to train models with Gibbs sampling because of the immense computational complexity.
4 For more information on this dataset see www / research.digital.com/SRC /EachMovie.
| Data #1 | Recommendations | Data #2 | Recommendations |
|---|---|---|---|
| Star Trek: The Motion Picture Star Trek: Generations Star Trek II Star Trek III Star Trek V Star Trek VI | The Empire Strikes Back Star Trek: First Contact Raiders of the Lost Ark Stargate The Terminator Return of the Jedi | Pulp Fiction Fargo Smoke Three Colors: Blue Four Weddings and a Funeral A2001: A Space Odyssey | The Silence of the Lambs Toy Story Dead Man Walking Batman Leaving Las Vegas The Piano |
To give an impression of what the extracted movie aspects and movie clusters look like, we have displayed some aspects of a J{ = 128 model in Figure 2 and clus ters of a J{ = L = 32 solution represented by their members with highest posterior probability in Figure 3. Notice that some movies appear more than once in the aspects (e.g. 'The Piano'). Both authors have also been subjected to a test run with the recommendation sys tem. The result - which was perfectly satisfying from our point of view - is shown in Figure 4. We hope the reader might also spot one or another valuable recom mendation.
5 Conclusion
We have systematically discussed two different types of latent class models which can be utilized for collabora tive filtering. Several variants corresponding to different sampling scenarios and/or different modeling goals have been presented, emphasizing the flexibility and richness of latent class models for both, prediction and struc ture discovery. Future work will address alternative loss functions and will have to deal with a more detailed per formance evaluation.
Acknowledgments
This work has been supported by a DAAD postdoctoral fellowship (TH) and the German Research Foundation (DFG) under grant #BU 914/3-1 (JP). The EachMovie preference data is by courtesy of Digital Equipment Cor poration and was generously provided by Paul Melones.
5 The perplexity P is the log- scale average of the inverse probability 1/ P(yix) on test data.
@inproceedings{ijcai1999p98,
  title     = {Latent Class Models for Collaborative Filtering},
  author    = {Hofmann, Thomas and Puzicha, Jan},
  booktitle = {Proceedings of the Sixteenth International Joint Conference on
               Artificial Intelligence, {IJCAI-99}},
  publisher = {International Joint Conferences on Artificial Intelligence},
  editor    = {Thomas Dean},
  pages     = {688--692},
  year      = {1999},
  note      = {Machine Learning},
  url       = {https://ijcai.org/proceedings/1999/98},
}
TY - CPAPER TI - Latent Class Models for Collaborative Filtering AU - Hofmann, Thomas AU - Puzicha, Jan T2 - Proceedings of the Sixteenth International Joint Conference on Artificial Intelligence, IJCAI-99 PB - International Joint Conferences on Artificial Intelligence PY - 1999 SP - 688 EP - 692 UR - https://ijcai.org/proceedings/1999/98 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





