
Hierarchical Bayesian Clustering for Automatic Text Classification
Proceedings of the Fourteenth International Joint Conference on Artificial Intelligence. Natural Language. Pages 1322-1326.
© 1995 International Joint Conferences on Artificial Intelligence
Abstract
Text classification, the grouping of texts into several clusters, has been used as a means of improving both the efficiency and the effectiveness of text retrieval/categorization. In this paper we propose a hierarchical clustering algorithm that constructs a set of clusters having the maximum Bayesian posterior probability, the probability that the given texts are classified into clusters. We call the algorithm Hierarchical Bayesian Clustering (HBC). The advantages of HBC are experimentally verified from several viewpoints. (1) HBC can re-construct the original clusters more accurately than do other non probabilistic algorithms. (2) When a probabilistic text categorization is extended to a cluster-based one, the use of HBC offers better performance than does the use of non probabilistic algorithms.
- [Akaike, 1974] H. Akaike. A new look at the statisti- cal model identification. IEEE Trans. on Automatic Control, 19(6) :716-723, 1974.
- [Anderberg, 1973] M. R. Anderberg. Cluster Analysis for Applications. Academic Press, 1973.
- [Cormack, 1971] R. M. Cormack. A review of classifica- tion. Journal of the Royal Statistical Society, 134:321- 367, 1971.
- [Croft, 1980] W. B. Croft. A model of cluster searching based on classification. Information Systems, 5:189- 195, 1980.
- [Croft, 1981] W. B. Croft. Document representation in probabilistic models of information retrieval. Jour- nal of the American Society for Information Science, 32(6) :451-457, 1981.
- [Dubes and Jain, 1979] R. Dubes and A. K. Jain. Valid- ity studies in clustering methodologies. Pattern Recog- nition, 11 :235-254, 1979.
- [Fuhr, 1989] N. Fuhr. Models for retrieval with proba- bilistic indexing. Information Processing fj Retrieval, 25(1):55-72, 1989.
- [Griffiths et a/., 1984] A. Griffiths, L. A. Robinson, and P. Willett . Hierarchic agglomerative clustering meth- ods for automatic document classification. Journal of Documentation, 40(3) :175-205, 1984.
- [lwayama and Tokunaga, 1994] M. lwayama and T. Tokunaga. A probabilistic model for text cat- egorization: Based on a single random variable with multiple values. In Proceedings of 4th Conference on Applied Natural Language Processing, pages 162-167, 1994.
- [Jardine and Van Rijsbergen, 1971] N. Jardine and C. J. Van Rijsbergen. The use of hierarchic cluster- ing in information retrieval. Information Storage and Retrieval, 7:217-240, 1971.
- [Jiyukokuminsya, 1992] Jiyukokuminsya. Gendai yogo no kisotisiki. Jiyukokuminsya, 1992. (in Japanese).
- [Kwok, 1990] K. L. Kwok . Experiments with a com- ponent theory of probabilistic information retrieval based on single terms as document components. ACM Transactions on Information Systems, 8( 4):363-386, 1990.
- [Lewis, 1992] D. D. Lewis. An evaluation of phrasal and clustered representation on a text categorization task. In Proceedings of the Annual International A CM SI- GIR Conference on Research and Development in In- formation Retrieval, pages 37-50, 1992.
- [Masand et a/., 1992] B. Masand, G. Linoff, and D. Waltz . Classifying news stories using memory based reasoning. In Proceedings of the Annual In- ternational ACM SIGIR Conference on Research and Development in Information Retrieval, pages 59-65, 1992.
- [Matsumoto, 1993] Y. Matsumoto. JUMAN Users Man- ual. Kyoto University and Nara Institute of Science and Technology, 1993.
- [Rissanen, 1989] J. Rissanen. Stochastic Complexity in Statistical Inquiry. World Scientific Publishing, 1989.
- [Stanfill and Waltz, 1986] C. Stanfill and D. Waltz. To- ward memory-based reasoning. Communications of the ACM, 29(12):1213-1228, 1986.
- [Tokunaga et a/., 1995] T. Tokunaga, M. lwayama, and H. Tanaka. Automatic thesaurus construction based on grammatical relations. In Proceedings of the Inter- national Joint Conference on Artificial Intelligence, 1995. IJCAI
- [van Rijsbergen and Croft, 1975] C. J. van Rijsbergen and W. B. Croft. Document clustering: An evaluation of some experiments with the granfield 1400 collection. Information Processing fj Management, 11:171-182, 1975.
- [Willett, 1983] P. Willett. Similarity coefficients and weighting functions for automatic document classifi- cation: an empirical comparison. International Clas- sification, 10(3):138-142, 1983.
- [Willett, 1988] P. Willett. Recent trends in hierarchic document clustering: A critical review. Information Processing fj Management, 24(5):577-597, 1988.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Text classification, the grouping of texts into sev eral clusters, has been used as a means of improv ing both the efficiency and the effectiveness of text retrieval/categorization [Jardine and Van Rijsbergen, 1971; van Rijsbergen and Croft, 1975; Croft, 1980; Willett, 1983]. For example, to retrieve texts relevant to a user's request, a simple strategy would be to search all the texts in a database by calculating a measure of the relevance of each text to the request. This exhaus tive search, however, would require more computation for larger databases. Text classification helps to reduce the number of comparisons in an exhaustive search by clustering (grouping) similar texts into clusters in ad vance and comparing the request with the representative of each cluster. Clustering is also assumed to improve the accuracy of retrieval, but this assumption has not been verified. The retrieval/categorization model that incorporates text classification as a preliminary process is often called cluster-based text retrieval/ categorization.
In this paper we propose a probabilistic algorithm of hierarchical clustering and compare it with other cluster ing algorithms. Almost all previous algorithms, such as single-link method and Ward's method , use the measure
Takenobu TOKUNAGA
Department of Computer Science Tokyo Institute of Technology Ookayama, Meguro Tokyo 152, Japan
take~cs.titech.ac.jp
of distance between two objects and merge the closer ones [Cormack, 1971; Anderberg, 1973; Griffiths et a/., 1984; Willett, 1988], our algorithm, though, constructs a set of clusters that has the maximum Bayesian posterior probability, the probability that the given objects are classified into clusters. This maximization is a general form of the well known Maximum Likelihood estimation, and we call the algorithm Hierarchical Bayesian Clus tering (HBC).
Probabilistic models are becoming popular in the field of text retrieval/categorization owing to their solid formal grounding in probability theory [Croft, 1981; Fuhr, 1989; Kwok, 1990; Lewis, 1992] . They retrieve those texts that have larger posterior probabilities of being relevant to a request. When these models are extended to cluster-based text retrieval/ categorization, however, the algorithm used for text clustering has still been a non probabilistic one [Croft, 1980] . We think that better performance could be obtained by using exactly the same criterion in both clustering and re trieval/ categorization, that is, searching for the maxi mum posterior probability. In this paper we verify this assumption through preliminary experiments where we compare a probabilistic text categorization using HBC and the same categorization using non probabilistic clus tering algorithms.
The term "categorization" in this paper refers to the assignment of documents to predefined categories, whereas "classification" and "clustering" refers to only grouping of documents without identifying the meaning of groups.
2 Hierarchical Bayesian Clustering
Like most agglomerative clustering algorithms [Cor mack, 1971; Anderberg, 1973; Griffiths et a/., 1984; Willett, 1988], HBC constructs a cluster hierarchy (also called dendrogram) from bottom to top by merging two clusters at a time. At the begining (i.e., at the bottom level in a dendrogram), each datum belongs to a cluster whose only member is the datum itself. For every pair of clusters, HBC calculates the probability of merging the pair and selects for the next merge the best one for which this probability is highest. This merge step takes place N - 1 times for a collection of N data. The last merge produces a single cluster containing the entire data set.
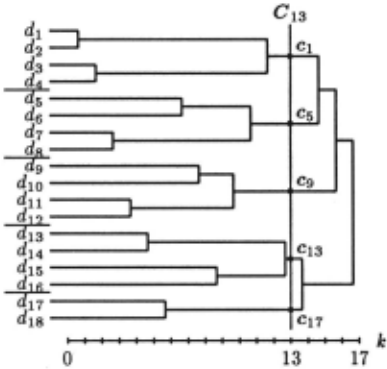
Figure 1 shows an example of a dendrogram.
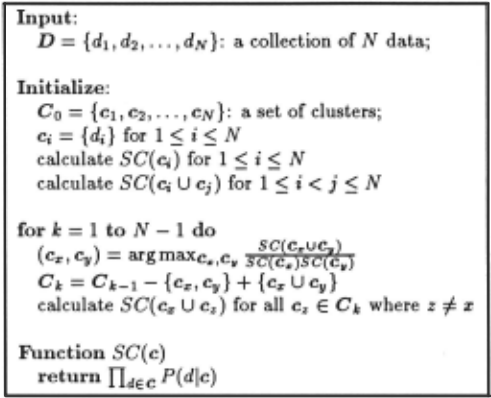
Formally, HBC selects the cluster pair whose merge results in the maximum value of the posterior proba bility P( CiD) , where D is a collection of data (i.e. , D = {d1, d2, . . . , dN }) and C is a set of clusters (i.e., C = {c1 , c2, . . . }). Each cluster ci E Cis a set of data and the clusters being mutually exclusive. At the initial stage, each cluster is a singleton set; c; = { di} for all i. P( CiD) defines the probability that a collection of data D is classified into a set of clusters C. Maximiz ing P(CiD) is a generalization of Maximum Likelihood estimation.
To see the details of merge process, consider a merge step k + 1 (0 ~ k ~ N- 1). By the step k + 1, a data collection D has been partitioned into a set of clusters Ck. That is each datum d E D belongs to a cluster c E C k . The posterior probability at this point becomes
Here PC( C l:) corresponds to the prior probability that N random data are classified into a set of clusters C~: . This probability is defined as follows:
SC(c) defines the probability that all the data in a cluster c are produced from the cluster and is defined as
When the algorithm merges two clusters Cz , ey E C l: , the set of clusters C~: is updated as follows:
After the merge, the posterior probability is inductively updated as
Note that this updating is local and can be done effi ciently since all we have to recalculate from the previous step is the probability for the merged new cluster; that is, SC(cz Ucy)· As for the factor of PC(CC+tl, we use a PC( ·) well known estimate1: the prior probability of a model (in this case, a cluster) is a decreasing function of the model size. For instance, P( c) <X A -lei for some con stant A > 1. According to this estimate,
Since the number of clusters iCi decreases one by one as the merge step proceeds, PC(CC+d reduces to a conPC( ·) stant value A -l regardless of the merged pair. This means that we can drop the facter for a maximization task. HBC calculates the updated P( C l:+dD) for every merge candidate and merges the one that offers the max imum P(C~:+liD) . The HBC algorithm is summarized in Figure 2.
Lastly, we will show an example of calculating the el emental probability P(dic) that a cluster c produces its member d. Depending on the data representation form and available information for data, there could be various methods for calculating this probability. In this paper we use Iwayama and Tokunaga's method [Iwayama and Tokunaga, 1994].
In [Iwayama and Tokunaga, 1994], each datum dis a document, and is represented as a set of terms (usually only nouns are used for terms). Because a cluster c is a set of documents, it is also represented as a set of terms that all the documents in c have. Consider here an event T = t, that a randomly extracted term T from a set of terms is equal to t . Conditioning P( die) on each possible event gives
If we assume conditional independence between c and d given T = t, we obtain
1 We have devised a more formal estimate based on the MDL principle [Rissanen, 1989] and have used the estimate to determine the best set of clusters in dendrogram, but this topic is outside the scope of this paper.
Using Bayes' theorem, we can write this as
Since each P(d) appears in every estimation of P(CiD) only once, P( d) can be excluded for maximization pur pose. Other probabilities P(T = tid), P(T = tic), and P(T = t) are estimated from the given data by using the simple estimations described below.
- P(T =tid) : relative frequency of a term t in a doc ument d
- P(T =tic): relative frequency of a term tin a clus ter c
- P(T = t): relative frequency of a term tin the entire data set
The general framework of HBC is similar to Ward's method, a well known hierarchical clustering algorithm (see [Anderberg, 1973; Griffiths et al., 1984; Cormack, 1971] for the algorithm). Whereas Ward's method merges two clusters whose merge causes the least in crease in the sum of the distances from each datum to the centroid of its cluster, HBC maximizes the probabil ity that all the members of a cluster actually belong (or are categorized) to the cluster. We think that in applica tion domains like text categorization, HBC would work better than Ward's method because the cluster construc tion strategy of HBC is more directly related to the task of such applications. Before we verify this assumption in section 4, we make some general comparisons between HBC and other clustering algorithms.
3 Comparison to Other Clustering Algorithms
Comparing different clustering algorithms is very dif ficult, but plenty of criteria have been proposed (see [Dubes and Jain, 1979] for a good survey). In this section we compare HBC with other two representative hierar chical clustering algorithms [Anderberg, 1973] (single link method and Ward's method) from the viewpoint that how accurately the original (i.e., true in a sense) classification can be reconstructed from scratch.
The data set we used was a dictionary of contempo rary words (in Japanese), called Gendai yogo no Kiso tisiki(GK) [Jiyukokuminsya, 1992]. It contains 18,476 word entries, each of which is classified into one of 149 categories. The length of texts explaining each word varies from 13 to 1,938 characters (in kanji) and aver ages 287 characters. To eliminate the effect. of noise, .we excluded smaller entries and smaller categones accordmg to two thresholds 2 :
- For an entry, the number of terms in the entry should be more than 100.
- For a category, the number of entries that belong to the category should be more than 20.
There remained 1,072 entries classified into 39 categories. All texts were tagged by a Japanese morphological ana lyzer called JUMAN [Matsumoto, 1993], and each entry became a set of terms (i.e., nouns) with relative frequen Cies.
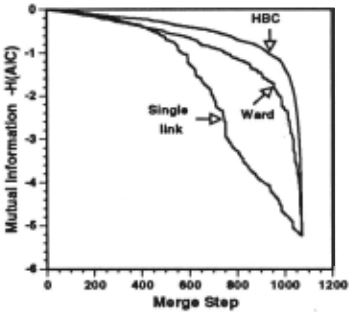
From these 1,072 entries, we constructed three clus ter hierarchies using single-link method, Ward's method, and HBC, and we compared these hierarchies. First we calculated the mutual information I( C; A) between a set of constructed clusters C and the set of the original categories A. For each entry d, a category a E A had been assigned by GK's editors beforehand and a cluster c E C is assigned by a clustering algorithm. So there are two classifications: one by human experts and the other by a clustering algorithm. Since mutual informa tion I(C; A) defines the amount of information that is commonly contained in C and A, the larger the value I ( C; A) has, the more closely the set of clusters C ap proximates the original set of categories A. Formally, I( C; A) is defined as
2 In preliminary experiments, variations of the two thresh olds had little affect on the overall results. We set the thresh old values because the memory available to run the program was limited.
| yes a |
| no c |
where H(A) is the entropy of A and H(AIC) is the conditional entropy of A given C. Since H(A) is inde pendent of C, to compare different C's we have only to calculate -H(AIC):
The value of -H(AIC) at every merge step of each clustering algorithm is plotted in Figure 3, where we can see that the value is always higher for HBC than for the other two algorithms. This means that HBC could re construct the original categories more precisely than the other two. We see that for all the algorithms -H(AIC) decreases monotonically as the merging proceeds (i.e., as the number of clusters decreases). This is because a larger number of clusters can express the original cat egories more precisely owing to the larger number of model parameters. Since in the most extreme case, when no merge has occurred, every cluster needs to express only one entry for each, this set of clusters can directly encode the original categories without noise. Note, how ever that a larger set of small clusters generally has less predictability for unseen new data because of overspeci fication to the given data.
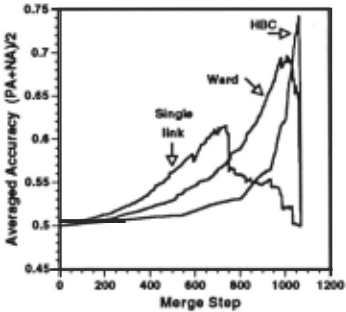
We also calculated the accuracy of a set of constructed clusters. If two entries d; and dj have the same category attached beforehand and an algorithm assigns both to the same cluster, we say that clustering is positively cor rect with respect to the pair. If d; and di have different categories and an algorithm assigns two of them differ ent clusters, we say that clustering is negatively correct. Counting the correctness for every pair of entries yields the positive accuracy (PA) (also called sensitivity) and the negative accuracy (N A) (also called specificity) . Re ferring to Table 1, we define P A and N A as follows:
The averaged accuracy ( P A1N A) at each merge step of each clustering algorithm is shown in Figure 4. Un like -H(AIC) in Figure 3, the averaged accuracy reaches a maximum value at some step between the beginning and the end. At the beginning, since every entry is dis tributed to a unique cluster for each, N A becomes 1 but P A becomes 0. As the merging steps proceed, N A de creases and P A increases monotonically. At the end, since all the entries are contained in the single cluster, PA becomes 1 but N A becomes 0. Usually, the best point for both N A and PA lies between the beginning and the end. From the figure, we see that HBC offers the best upper bound of the averaged accuracy. In addition, since the optimal set of clusters obtained by HBC is the smallest, HBC could construct a set of clusters that has the most generality (i.e, the highest predictive power) for unseen data - from the standpoint of the MDL prin ciple [Rissanen, 1989] stating that smaller models are better.
4 Evaluation m Text Categorization
Text categorization is the classification of documents with respect to a set of predefined categories. We use text clustering to improve the efficiency of a text catego rization based on Memory Based Reasoning (MBR) (a k-nearest neighbor search) [Masand et al., 1992]. MBR solves a new task by looking up examples of tasks sim ilar to the new task [Stanfill and Waltz, 1986]. For ex ample, to attach categories to a new document, MBR searches the nearest k documents in a large set of al ready categorized documents (called training data) and uses the categories attached to the searched k documents to determine categories of the new document. Although this strategy offers promising performance [Masand et al., 1992], MBR requires a large amount of computa tional power for calculating a measure of the similarity between a new document and every example and for sort ing the similarities. For practical applications, parallel computing is usually necessary.
We use a clustering algorithm for preliminary process ing to reduce the number of comparisons by partition ing a large amount of training data into several clus ters [Jardine and Van Rijsbergen, 1971; van Rijsbergen and Croft, 1975; Croft, 1980; Willett, 1983]. The original MBR searches the k nearest documents, but the cluster based MBR searches the k nearest clusters of documents. The documents in the searched k clusters are used to at tach categories to a new document . This pre-clustering procedure could eliminate a great deal of computation if the number of clusters is relatively small. In addition, if the accuracy of the cluster-based MBR is compara ble to that of the original MBR, the cluster-based ver sion would be an efficient approximation of the original MBR. This section describes our experimental investi gate of how well HBC and Ward's method can help to approximate the performance of the original MBR.
In experiments we used the GK data set described in section 3. To divide the data set into two sets, one for examples with categories (training data) and the other for evaluation (test data), we used 4-fold cross validation. The 1,072 above-threshold entries were ran domly divided into four sets, one used for test data and the remaining three used for training data. For each entry in the test data, an text categorization model as signed a category using the training data. If the category assigned by the model was the same as the category as signed by GK's editors, we said that the categorization was correct. We used the accuracy of categorization to measure the performance of a model. Since there were four variations of test data depending on which set of the four we select, we did four series of experiments and averaged the results.
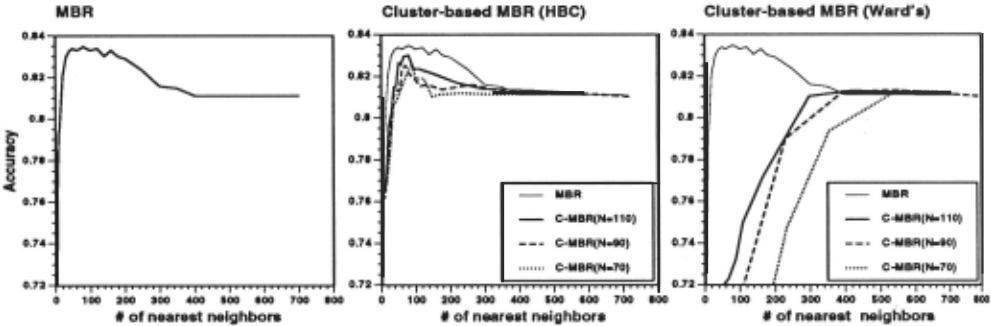
To see the performance of the original MBR, we cal culated the probability P( { dtrain} ldte·t) for every pair consisting of a test entry dteot and a training entry dtrain by using a method similar to that used in deducing the Eq. (9) (see [Iwayama and Tokunaga, 1994] for more de tails). To assign a category to each test entry dte·t, we searched the k nearest entries besed on the calculated probabilities. Each dtrain in the k nearest entries voted on the originally assigned category when the weight of the voting was logP({dtrain}ldte·t) · The category with the most votes was assigned to the test entry dte·t. Fig ure 5 shows the result of the accuracy obtained when varying k from 1 to the maximum value (i.e., the num ber of the given training data). We can see that more correct categories are attached as k, the number of near est neighbors, increases but also that there is more noise after k reaches some value.
For cluster-based MBR we first constructed a cluster hierarchy from the given training data by using each of the two clustering algorithms, HBC and Ward's method. From a constructed hierarchy we selected a set of clus ters C = { c1, c2 , .. . , CN} at some merge step. For each pair consisting of a test entry dte·t and a cluster c; E C we calculated P( c; ldte·t) by using the same method as in the original MBR and extracted the nearest k clusters from C . All the members in the nearest k clusters be come the approximated nearest entries of the test entry. Using the same voting strategy as in the original MBR, a category was assigned to each test entry. Figure 5 shows the results when the number of selected clusters (N) was set to 70, 90, and 110. The original MBR curve is also plotted for reference. We can see that the accuracy of the cluster-based MBR with HBC approaches that of the original MBR as the number of constructed clusters in creases. Note that the original MBR corresponds to the extreme case where N is the maximum value (i.e., the number of training data). We can also see the advantage of HBC over Ward's method. Cluster-based MBR with HBC approximates the original MBR sufficiently well whereas the cluster-based MBR with Ward's method provides poor performance, especially when the number of nearest neighbors is small .
5 Discussion
We have proposed a new hierarchical clustering algo rithm that is based on maximizing the Bayesian posterior probability. The advantages of this algorithm have been experimentally verified from several viewpoints, includ ing its performance within an actual application of text categorization. In summary,
- From the standpoints of the mutual information and the classification accuracy, HBC can re-construct the original clusters more accurately than do the single-link method and Ward's method.
- When a probabilistic text categorization is extended to a cluster-based one, the use of HBC offeres better performance than does the use of non probabilistic algorithm like Ward's method.
Since the HBC algorithm itself is general and not re stricted to text clustering, it could be easily applied to various applications, such as automatic thesaurus con struction. We have in fact used the algorithm to con struct noun hierarchies (a kind of thesaurus) using gram matical relations and have verified their contribution to disambiguation tasks [Tokunaga et a/., 1995].
One issue we have not discussed in this paper is the selection of an appropriate set of clusters from a con structed dendrogram. For a collection of N data there are N possibilities of the set, each of which corresponds to a merge step. Generally, a larger set of clusters (at earlier merge step) can express the given data more pre cisely but has poorer predictability for unseen data. On the other hand, a smaller set (at later merge step) has the opposite characteristics. Selecting the optimal set of clusters is a crucial issue for applications. In an ap plication of cluster-based MBR (described in section 4), the amount of computation is also affected by the size of the set: larger sets needs more comparisons than do smaller sets. For this general issue of model selection, several statistical measures, such as AIC [Akaike, 1974] and MDL [Rissanen, 1989], have been proposed. Since our algorithm is based on probability theory, it would be easy to introduce these statistical measures into our algorithm.
Acknowledgments
The authors are grateful to Hiroshi Motoda for beneficial discussions.
@inproceedings{ijcai1995p170,
  title     = {Hierarchical Bayesian Clustering for Automatic Text Classification},
  author    = {Iwayama, Makoto and Tokunaga, Takenobu},
  booktitle = {Proceedings of the Fourteenth International Joint Conference on
               Artificial Intelligence, {IJCAI-95}},
  publisher = {International Joint Conferences on Artificial Intelligence},
  editor    = {Chris S. Mellish},
  pages     = {1322--1326},
  year      = {1995},
  note      = {Natural Language},
  url       = {https://ijcai.org/proceedings/1995/170},
}
TY - CPAPER TI - Hierarchical Bayesian Clustering for Automatic Text Classification AU - Iwayama, Makoto AU - Tokunaga, Takenobu T2 - Proceedings of the Fourteenth International Joint Conference on Artificial Intelligence, IJCAI-95 PB - International Joint Conferences on Artificial Intelligence PY - 1995 SP - 1322 EP - 1326 UR - https://ijcai.org/proceedings/1995/170 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





