
ZMOB: A New Conputing Engine for AI
Proceedings of the Seventh International Joint Conference on Artificial Intelligence. Hardware. Pages 955-959.
© 1981 International Joint Conferences on Artificial Intelligence
Abstract
A new research multiprocessor named ZMOB is described, and its si~nificance to AI research is surveyed and character1zed. ZMOB, under current construction and scheduled for completion late Fall 1981 is a 256 processor machine with a high speed interprocessor communications system called the "cqnveyor belt", a non-blocking, 20 megabyte/second message switcher. Because of its large number of processors, high computational throughput (100 million ins~ructions/ s ecl, lar Ge cumulative high speed memor.y {16 megabytes , high interprocessor communications bandwidt , and external communications and sensing channels, ZMOB opens some new areas of exploration in objectoriented modeling, knowledge-based and domain expert systems, intelligent sensin6 and robotics, ana distributed perceptual and cogn1tive modeling. The paper attempts to blend a description of ZMOB'e hardware with ideas about where and how it fits into various types of AI research.
- Akl 1 s. G., D. T. Barnardf and R. J. Doran, Des1gn, AnalysiR, and mplementation of a Parullel Alpha-Deta Algorithm Queen's Univer- sity, Technical Report 80-98, 1980.
- Albus, J. S., A. J. Barbera, M. L. Fitzgerald, R. N. Nagel, G. J. Vanderbrug, and T. g, When tley, A ~:easurement and Control Model for Adaptive Robots, in Proceedin~e of the 10th Internationul SymposiUm on I !Su"!F tffal Rotiote, 1980.
- - --- AllenA John, The TLC LISP User's Manual, Lisp ~ompany, 1980;--------- The
- Baudet G. M., The Design and Analysis of Algorithms for Asynchronous Nicroproceesor~, Carnegie-Mellon Univerei ty CHU-CS-78-11 o, 1978.
- Bobrow, D.G. and T. Winograd 1 An Overview of KRL, a Knowledge R~fresentation Language, Cognitive Science .!_, \ } , 1977.
- Chang, C. L. and R. c. T. Lee, Sbmbolic ~g~~g and Hechanical Theorem Provi g, Aca . Press, New iork, 19/9.
- Dude,, Hart, and llilseon, et al, Development of a Computer-Based Consultant for ~lineral I<:xploration 1 Annual Report, Stanford Research Institute, 977.
- Hshburn, J. P., H. A. Finkel, and S. A. Law- lees, Parallel Alpha-Beta Search on Arachne, pp. 235-243 in Proceedings of the 1980 Inter- national Conference on Pa~l~ ~e~ 1 ')00. ------ ~'ort;
- Y C. L., A Production System l• lonitor for Paraliel Computers, CMU 161, April, 1977.
- Goldstein, I.P. and D.G. Bobrow, Descriptions for a Programming Environment, in Proceedings of the First Annual National Conference n ~t~c~~gence, StanfOriS, CA., Au~ 1980.
- Hewitt, C., Viewing Control Structures as 960
- Patterns of Passing Messages~ Artificial Intelligence~. pp. 323-364, 197t.
- Ingell's, D.H.ii., The Srr.alftalk-76 Programrrling System Design and Implementation,_ in Confer- ence Record of the Fifth Annual A~M Symposium on PrT'iiC'1piesolPrOijF!iiiim1"iiif"'tiinguiiges, 19/8.
- Jones, A. K. and P. Schwarz, ~xRerience Using Multiprocessor Systems -A "tatue Heport, Computing Surveys~. 2, June 1980.
- Kay, A., The Reactive Bngine, Ph.D. thesis, University of Utah, 1969.
- Kowalski! R. A. 19 7~gic for Problem Solving, North-Ho land, • --
- Kushner Todd, Angela Y. Wu, and Azriel Rosenfeld, Image Processing on ZNOll, Univer- sity of Maryland, TR-987, Dec. 1980.
- Kushner Todd, Parallel Using ~witching Networks Communicatio~, University {forthcoming}, March 1981. Image Processing for Interproceseor of Maryland, TR
- Minker, J., A Set-Oriented Predicate Logic Progrwnming Language, TR-922, University of lr.aryland, J980.
- Rashid, R. F., An Inter-Process Cornn.unication Facility for UNIX, C~IU-CS-130-124, Carnegie- ~lellon University, Jun. 1980.
- Rie($er, C., The Commonsense Algorithm as a Bas1s for Com.~>uter Hodels of Human Memory, Inference, llel1ef and Contextual Languase Comprehension, University of Haryland TH-375, ~:ay 1975.
- Rieger, c. and 11. Grinberg, A system for Cause-Effect Representation and Simulation in Computer-Aided Design, in Proceedings of the IFIP Workin~ Conference on Artific1al-rnteT= ~nee and attern Recognft1on 1n Computer= A1 ed De81gn, 19/8. - Rieger, C. and S. Small, Word Expert Parsing, PP• 723-728 in IJCAI-79, 1979.
- Rieger, C., ZMOB: A Mob of 256 Cooperative Z80A-Based Microcomputers, in Proceedings of the ARPA Vision Workshop, Los Angeles, ex; T'nrr.---
- Rieger, C. 1 R. Wood, and E. Allen, Large Human-Mach1ne Informs tion Sfacee 1 Uni v. of Maryland CS TR-102~, Mar. 198 • ~also sub- mi tt'ed to IJCAI-81)
- Rosenfeld, Azriel and Angela Y. Wu, Reconfi- gurable Cellular Computers, University of Maryland, TR-963, Oct. 1980.
- Schank, R. and C. Riesbeck, Inside Computer Understanding, L. Erlbaum, 1981.
- Shortliffe, E., Computer-Based Medical Con- sultations -~iYCIN, Afuerican-Elsev1er, 19~
- Small, S., Word Expert Parsing: A Theory of Distributed Word-Based Natural Language Understanding, University of ~laryland TR-954, Sept. 1980.
- 29j Trigg, Randall H., A Parallel Approach to the Interactive Design and Simulation of Mechan- isms, University of Maryland, ~H-992, Dec. 1980.
- 30j Warren, D. H. D., Implementing PHOLOG: Com- piling Predicate Logic Program, University of Edinburgh, Research Reports 39 & 40, 1979.
- Wa terrnan, D. and F. Hayes-Roth, An Overview of Pattern-Directed Inference Systems, in Pattern-Directed Inferenc~ Sistema, ed.
- Waterman a Hayes-ROth, Academ c Press, New Yodc, 1978.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1. Introduction
AI is not in need of new computing hardware to solve its basic questions. However new hardware cannot be dismissed as being irrelevant to progress in AI, because:
- 1 · Beliefs about the nature of computing hardware available influence a researcher's ability to conceptualize data and process models of intelligence. While a researcher can certainly imagine methods of modeling which require unusual hardware, he may never discover the intereet1ng issues because of his inabil ity to sec beyond the first round of ideas. Like it or not, AI is an experi mental science which relies heavily on feedback from the implementation level to the conceptual model level.
- Certain AI methods requiring heavy sym bolic computation have not been ade quately explored simply because the architecture or computational capacity of the supporting computers is not adequate. Examples are large pattern-directed rule systems, and certain low and high level vision techniques, amon1: many others.
- Certain wall researched AI methodsi recognized as fruitful conceptus approaches to various classes of prob lema, are inherently not designed for conventional machines, and would become practical, real-worla systems if imple mented on hardware better suited to their needs. Distributed and "expert" systems
* The research described here is funded by the Air Force Office of Scientific Research under Contract AFOSR-80-0270. As of March 1981, all ZMOD design and debugging was completed, and a two processor prototype was running. The full machine, budgeted at approximately $120K hardware coat, is expected to be running by late Fall 1981.
Chuck Rieger, Handy Trigg, Bob Bane
~laryland Artificial Intelligence Group Department of Conputer Science University of Naryland College Park, Maryland 20742
which rely on object-oriented progranu.dnc styles are generally good examples of th1s category.
This paper is about a new research computer designed to help stimulate new ways of thinking about AI modeling, and to help advance certain existin~ computing methods by removing some of the computational barriers that limit these methods' usefulness. \:e offer this research not as a source, but rather a gateway to some new ideas about AI model building. In writing a paper about hardware's role in higher level model building, we run the risk of overselling the hardware per sei without demonstrating its usefulness to mode building and theory development. To minimize this risk, we have attempted to blend a description of the machine's architecture, including enough detail to give the reader a complete picture of the machine, with brief tours through the various realms of AI model building which may profit from this architecture. Our hope is to show that new machine architectures, if developed in a way that is sensitive to current modeling directions in the field, can be an important link in the larger basic research feedback loop that gradually con verges on good AI theories.
2. Zmll and Distributed AI
ZMOB is a 256 processor multiprocessor which taxonom~caJly falls into the same general category as cr.* L13 , but which also has appearl}nces of high epee ring networks. Each of its 25b proces sors is a completely autonomouu computer with enough memory to do significant independent hieh level computation asynchronously from other pro cessors. However, each processor is intimately linked to all other processors by an interconnec tion system of such high speed relative to the individual processor that all 255 of a processor's companion processors appear to be equidistant from it, and, in fact, accessible in what amounts to unit time from its point of view. ~~OD is thus a mob of 256 reasonably powerful processors organ ized in a manner that superimposes no actual 1 or even preferred, geometry on theu logical inter connectivity. As such, it is close to the ideal for systems of experts whose intercommunication geometry is governed by domain problem solvers rather than by a priori domain structure.
ZMOD differs fron CH* in three significant ways. First it possesses a larger number of pro cessors, each roughly equivalent in power to a c~:* processor. (To our knowledge, its 256 proceasors comprise the largest research multiprocessor yet des1gned and built.) Second, all memory is unif ormly distributed equally among the processors there is no hich speed shared memory}, giving ZMOB its network flavor. Third 1 the interproces sor communications strategy 1s completely non blockin6, with no possibility for hardware-level content1on in messace passing. ZMOD will support 128 pairwise processor conversations, and broad casts from one processor to all others or a subset of others equally well.
In the next section we describe ZMOD's hardware architecture and operating systems, which will include C, LISP, PASCAL, PROLOG, and special ized vision systems. Then we survey ZHOll's conceptual and pragmatic usefulness to several areas of AI.
2· Hang on: Here'~ the Hardw~!
ZMOB is a large, experimental research mul tiprocessor under construction by the Artificial Intelligence Group within the Computer Science Department at the University of Maryland. The machine's architecture is 256 autonomous micropro cessors, each with 64K bytes of 300 ns memory and capable of approximately 400,000 instructions per second, connected together via a high speed com munications ring called "the conveyor belt". The conveyor belt, a 48-bit wide, 10 mhz shift regis teri comprises 257 "mail stops". Each 48-bi t-wide IJlBi stop is aosociated with a Z~lOB processor ~except for the 257th, whicll is aosociated wi til ZHOIJ's external interface), and represents one stage in th~ conveyor belt. Because of the con veyor belt s high speed relative to the needs of any individual processor, and because of each mail stop's high speed message pattern matchers, the conveyor belt is a nearly perfect interprocessor communications medium. In particular, the conveyor belt gives prompt enou~h service for every proces sor to be given "unl.t time" message delivery to another arbitrary processor or set of processors.
In addition to its conveyor belt interface, each processor has a high speed parallel and a serial interface to the outside worla for applica tions involving remote sensing, control, or com munications. A special 257th processor interfaces the ZMOD conveyor belt to a PDP Unibus.
At large, ZMOB executes approximately 100 million instructions per second on a 256-way distributed 1G million byte high speed memory. Its conveyor belt switches interprocessor and external messages at a rate of 20 million bytes per second.
2·.!..· Kail Stops and Bins
Physically, each mail stop is a printed cir cuit board which occupies one slot of the conve.yor belt backplane, a 48-bit wide circular bus wh1ch passes throu~h all mail stops. Incom}ne conveyor belt sig~als ~those from a mail sto~ s u~stream neighbor) arrive via the mail stop s 48 19bound lines, and outgoing conveyor belt sl.gnals ~thos~ being sent to the mail stop s downstream neighbor) leave via the mail stop's 48 outbound lin~s. One 48-bi t "bin" (i.e. 1 one message) passes through the mail stop each 100 ns, as directed b;y the 10 mhz synchronous master system clock wh1ch is distributed to each mail stop over precisely matched cables.
Each ZMOD processor occupies a oecond printed circuit board which is physically adjacent to a mail stop board. Each mail stop communicates with its associated ZMOB processor Vl.B a 20 line inter face that allows the processor to view its mail stop as a collection of 8-bit registers whicht when read from and written to, cause mail ana status informs tion to flow to and from the con veyor belt.
Logically, the conveyor belt is thought of as a collection of bins which move around the loop through all mailstops each revolution. Bins carry messages, and each processor permanently owns one bin. Once, per conveyor belt revolution, every processors bin simultaneously arrives bacK at the processor's mail stop. This event is signaled to all mail stops by a master "index pulse", gen erated by the master clock circuitry and distri buted to each mail stop as with the master shift clock.
The mail stops are analogous to the ola freight train mal.l hooks. When the processor wishes to send a message, it giveo it to l.ts mail stop, which holds it until the proper moment for inje~tion on the conveyor belt (i.e. 1 index pulse time). When the conveyor belt bl.n permanently owned by a processor arrives back at that processor's mail stop empty, and if the mail stop has been given a message to send, then the message will be injected onto the conveyor belt in the processor's bin. During all other moments (i.e., when processQrs' bins are in transit around the conveyor belt) each mail stop performs high speed pattern matc~ing to detect arriving . meosages l.ntended for its processor. The mail stop can extract one message from the conveyor belt and hold it until its processor has taken it.
Bach mail stop (hen9e pro~essor) has a unique conveyor belt adaress ~0-256), ¥h~ch can be used to identify the intended receiver(s) of a message. In addition, each mail stop can be instructed by its processor to watch for a specific pattern of 1 's, O's, and "don't care's" in messages' destina tions fields, and to receive any messages matching that pattern. This is a basic mechanism upon which more elaborate pattern-directed invocatl.on techniques and hierarchical processor organiza tions can be realized.
l·~· 11essages
When a message is tain the address of information describing There are four modes receiverts): sent, it will always con the sender the data, a~d the intended receiver(sJ. for describing the intended
SEND TO PROCBSSOR BY ADDRESS
SEND TO PHOCJ!:SSOR BY PATTERN
SEND TO ALL PHOCESSORS
SEND TO S~r OF PROCESSORS BY PATTEHN
Each message is sent under exactly one of these four modes. In the first two cases, where there is only one intended r~ceiver, the receiving mail stop will "consume' the messaee. In the last two cases, a receiving mail stop will make a copy of the message, but allow it to continue for all to see. In this latter case, it is incumbent on the sending processor to consume its own message after one complete conveyor belt revolution. Doing so is called "readback".
Bach mail stop is capable of byffering one message in the outbouna direction ~processor to conveyor belt), and one message in tpe inbound direction (conveyor belt to proceosor). Messages will be received by a mail stop only if its pat tern matchers are enabled and deem the message appropriate, and its inbound buffer is empty. A received message will generate a proce~sor inter rupt, then remain in the mail stop s inbouQd buffer until explicitly read by the mail stop s processor. Messages on the conveyor belt intenaed for a processor whose mail stop's inbound buffer is full will simply continue circulating on the conveyor belt until the mail stop finally reads and consumes them, or until their senders consume and remove them. 'o'hen the mail stop's outbound buffer is emptied as the result of inJecting the message it contains onto the conveyor belt, a second type of processor interrupt is generated. The mail stop is therefore a full-duplex protocol,. where separate meosaee streams can be in progress both inbound and outbound.
A mail stop's receiving pattern matchers can be further conditioned to accept only messages from a specific source proceosor, identified b~ its conveyor belt address. This "exclusive source mode allows for the uninterrupted transmission of data streams between two processors, or between one source and a group of receivers.
In order for apsolute control commands from the conveyor belt s Unibus interface to have guaranteed delivery to any or all processors, each mail stop has a separate lo~ic section that is capable of detecting special control" messages from the mail stop associated with the Unibus interface processor, the only mail stop capable of sending control messages. Control messages are subject to the same inbound patte{n matchers as normal messages, except that {1 they cannot be selectiyely excluded the way norma messaees can, and {2) they do not interact with the mal.l stop's inbound buffer. This transparency allows absolute access to any or all processors from the external conveyor belt interface, while not interfering with the flow of normal conveyor belt messages.
l·l· Conveyor belt Format
The 48 bits of a conveyor belt messaee are appropriated into four fields:
+------------------------------------------------+
+------------------------------------------------+
| 1 CONTROL ! 8 bits | 1 DATA ! 16 bits | 1 SOUHC~ ! 1 2 bits | 1 DESTIHATION ! 1 2 bits |
The CONTHOL bits are defined as follows:
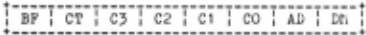
+---------------------------------------+ : BF : CT : C3 : C2 : C1 : CO : AD : Dl 'i : +---------------------------------------+
BF - Bin ~'ull CT - Control Message C3-CO - Control Code AD - All Destinations DM - Destination Mode
When sending a messaee, the tJrocessor has freedon in set tinB the AD and D~i b1 ts to any values. The AD and m: bits describe the mode under which the message is being transmitted, and are inspected by the inbound pattern matchers of all potential receivine mail stops:
| AD | lNT~HPRBTA'l'ION | |
| 0 | 0 | SJ::ND •ro PHOCJ::S:::OH BY ADDRJ::SS The message is intended only for the processor whose address is in the destination field. |
| 0 | SEND TO PROCESSOR BY PAT'i'.t:;RN The message is intended for the first processor whose posted pattern matches the destination field. | |
| 0 | SEND •ro ALL PHOCESSOHS The message i~ intended for all processors. \The desti~ation field is to be ignored.) | |
| !.Jl!:N D ·ro SJ::r OF PHOCI!:!.J:..iOlW BY PA'r'l'l::Hr; The message is intended for all processors whose posted pattern matches the destination field. |
The BF' and CT bits are not controllable by the processor. The BF flag is generated entirely by mall stop hardware logic and the CT bit can only be generated by the 25~th mail stop.
The 16-bit DATA field provides for single or double byte messages. If CT is set then bits C3CO are interpreted as a control code. Otherwise they can be uned as extra data bits. The SOUHCl:: and D~STINATION fields have been allocated 12 bits for possible future increases in the number of processors.
Processor Interface
The processor views iti mail stop as a group of 16 8-b1 t memory-mapped I 0 ports, each of whiyh accesses part or all of one of the mail stop s re~isters. All reading and conditioning of the mall stop's current state, and all data movement between the mail stop and processor occurs by reading and writing to these registers via the 1b 8-bit ports. The mail stop can also generate four types of interupt to signal the processor that it requires service: INBOUND DUFFER FULL, OUTBOUUD BUFF~R EMPTY, R~ADDACK, and COliTROL.
2·2· ZMOB Processors
Each ZMOD processor is a Z80 microprocessor with the follow1ng support hardware:
- 63K bytes of high speed compute memory
- 1K bytes of resident bootstrap operating system read-only memory
- Interface logic to conveyor belt
- A high speed hardware intege r multiplier
- A 32 bit floating point processor chip
- A high speed 8-bit parallel and a serial external interface.
When Z~OB is first powered on, all processors 11;0 throur,h identical reset sequences which ini tialize all processor and associated mail stop logic. Bach processor then enters its resident bootstrap kernel, which awaits commands from the Unibus interface. Support software on the VAX then sends operatine software to each processor indivi dually, or to all at one~. in case all will be running identical operating systerus.
4. ZT·IOli Soft~: .!!.!£'! Level Strat!<t;ies
4.1. Concep tual Oreanizations
The particular operating system regin.e under which zr.:ou processors are coordinated de!Jends lan.;ely on the domain. 'lie see five conceptuully different control ret;imes for AI modeling:
- 1 . ACTUAL SYriC!lkONY. In this most rudimen tary system, each processor performs fixed functions in precise (e.g., con veyor belt revolut1on time precision) locks tep with all others, but on dif ferent data points. This is an architec turally uninteresting use of the machine, but is applicable in such ureas as cellu lar automata modelint; and neurul simula tion, certain numerical methods in per ceptual modeling, and so forth. In these applications 1 either high efficienc1, or h1gh precis1on in simulation t1ming requires precise synchronization.
- LOGICAL SYNCIIHONY. Each processor runs an identical operating system capable of performing a fixed set of functions in logical (but not necessarily actual) syn chrony with all others, each workinc on a piece of a large datu space distr1buted amont; proces:Jors in advance. l!:xum!Jleu of this mode are models of low level vision or speech (where edge detectors or acous tic processors all proceed in parallel on different data), ana in parallel database storage and retri~vul, where all proceu-) sors carry out ~possibly intelligent hashing and puttern 1;1atchin~: on d~f(ereut segment~ of the database \see L9J for example).
- UT;IFOR~; HULTIPROCE!.JSi iJC. ~ach processor runs an identical operating system, but one capable of general computing or prob lem solving. t:uch processor is statically or dynamically a ss1gne<l a subtask, which it then solves asynchronousl,y from all others. A large number of AI methods falls into this category, since each pro cessor is, in effect, a general problem solving agent.
- AH'!'ICULATED ~1ULTIPHOCI!:!.iSI!'iC. Distinct domain experts reside in various proces sors, or sets of processors. Each expert is capable of autonomous solution of problems in its domain, which mal have been . sent to it via a pattern-d1rected invocation scheme. Systems of experts such as those encouraged by MicroPlanner and :..imalltalk fall into this category.
- J· JIYllHID SYSTEI·l!J. 1'he machine is logically segmented to support any or all of the above modes simultaneously. Because of the nature of the conveyor belt, one quarter of the muchine could be devoted to processes requiring actual synchrony, one-fourth to those runnin~ logical syn chrony, one-fourth to un1fon.1 mul tipro cessing, and one-fourth to articulated multiprocessing. Illustrations of hybrid use can be taken fr01~ nearly every area
of AI, including robotics, expert sys tems, speech systems, natural language systems, and game playinG systems. In a typical seg11tenta tion, some processors would handle sensory and perceptual infortllation, others the logical database, others the domain problem solving, and others the effector or response control.
4.2. Four Processor-Resident Operating Systems
In anticipation of such variety of modeling needs, we are developing four hieher level processor-resident environments, all of which rely on a single, lower level kernel system. At poweron~. the kernel system will be broadcast fro~ the VA.\ to all processors. Then, at user request, various processors will receive one of the four higher level environments:
- C. In this system, the processor supports a C runtime environ~ent, and runs C code which has been developed and cross compiled on the VAX.
- LI~P. The prqcessor runs a full Z80 LISP system L3J, and communicates viaS expressions passed as ASCII strings among processors. The issue of pointer passing on a completely distributed CONS node space will have to be addressed before other forms of interprocessor LISP com munication can be achieved.
- PA~CAL. The processor supports a PAS~untime environment and either runs cross-co~piled PASCAL code, or interprets P-codes.
- D+D. The processor runs a dedicated -aatabase and demonfl" operating system. 1'his special-purpose system allows the processor to participate as .a piece of a larger pattern-directed, intelligent database, which store9 information in LISPS-expression fonn talthough encoded differently for efficiency. The D+D sys tem will store both constant S expressions (fact~) and schematic S expressions (demons), and will respond to fetch, store, and trir,ger commands sent to it via the conveyor belt.
The C, LISP and PASCAL systems already exist for Zl'.OB, since each :processor is capable of run ning CP/r. (a nearly un1versal m~chine-independent operating system for the Z80). D+D is under current development in ZSO assembler, using the VAX ZUO assembler and simulator and the VAX process-oriented conveyor belt simulator specially written for ZMOD development.
The resident low level operating system ker nel common to all higher level environments is in effect an event-driven task management system which carries out all low level interprocessor handshaking and data transfers. The interrupt driven task qqeues at this low level support a success/failure/contingency communication system similar in some respects to SAIL's process manage ment. We have not yet cornpleted[th~s system, and are looking at Rashid's !PC 19J as an eventual augmentation of the present kernel.
\'ie turn now to some specific AI modeling where Ztr.OB will have impact. We have organized this discussion around AI areas, but point out specific systems where appropriate.
Where ZMOB Fits: Areas and Issues ------ --- -- ---
5. 1. Object-Oriented Programming and Experts.
'!'he concept of object-oriented pro~rajmine daten utlest . fro~theworkofAlanKay 14 und Carl llcwi tt r 11] and rnore recently is the orn1nan t syntemnl o~eaniza tion paradiem of the !>mall talk nyuter:~ 12j. In this style of progrun.tnint.;, active knowl etl ce is oreani?.cd around cooperating experts Co'll led oh~ccts . '!'he hierurchical orgunization of objc~ts 1nto classes, subclasses and instances both 11ids the user in creatine new objects and f11cili tates elegant communication amone: objects in the fon.t of message passing.
Zf.IOB' s distributed, geometry-independent nature makes it an ideal parallel mach1ne for implementing systems organized in such a manner. The localized processing required for the object oriented approach is encouraged by Zl·!OB' s d istri buted memory. At the same time, its ability to dynamically link arbitrary pairs of processors in direct communication allows for soph1sticated mes sage passing capabilities.
\le are currently in the process of designing and implementing a system for computer ~ided desien[an4 simulation of mechanisms lCADSOf.l) on Zl-!OB 29 J. 1'his sys tern possesses many of the features outlined above including separute proces sors as experts for different parts of ~ user defined mechanism and message passing as a means for real-time graphical si~ulation of the kinem!lt ics of the mechan1sm.
Briefly the operation of our CADSOH system is as foliows. 'i'he user, S!I:J a mechanical engineer, begins with a rough design of a mechan isr.t in mind. He or she then interactively identi fies parts from a frame-like database of primitive part descriptions. 1'hese can then be further specified as to size, weight, shape, etc. while v1ewing the object oq a graphics terminal. As a part is described it is assiened to a processor and as the links between parts are described by the user, communication paths are est11blished among the processors. Finully, when the user has <!esc ri bed the complete assembly, he or she may specify !In ini hal velocity or force upon some part at which point the system perfonns a eruphi cal simulation in real-time of the kinetna tics of the mechanism. It is durine the simulation phase that truly parallel ob~ect-oriented processing occurs with part experts 1nteracting both to com pute velocity, acceler11tion, and force vectors for the next increment11l time step and to detect obstructions to their motion.
5.2. Parallel Pattern Matching and Production RuTe "ystems
Though the production rule system has been popular and successful as a design methodology especially for large-syale [knqwl~d~e [~ngin~ering tasks for some t1me lsee 27J L7J, 31JJ 1t has only been recently that the problem of implement ing such systems in par~l~el has been confronted. In particular, Forgy 1n 9J has designed a ·produc tion rule system based n part on ideas froo ·data flow theory. Though to our knowledge, his system has not yet been implemented on a par11llel machine 1 Diany of his algorithms including those for pat~ern oatching are inherently parallel.
A fertile area of study for ZMOB is this topic of parallel pattern matching specifically addressing ways of avoiding the need for a large global database of patterns. Distributing the large database over many processors r11ises addi tional problems. One 1n particular is that of bottleneckine at processors who have a dispropor tionate share of requests on their portion of the database. Thus the design of algorithms for effi ciently and d;ynrunically reconfiguring the dutabase organization 1s an important area of research on ZMOB.
i·l· Cognitive Modeling
Many of the past and prebent theories advanced as plausible cognitive models of natural language understanding! causal reasonin~, infer ence, and problem so ving directly or 1ndirectly posit distribution of functions in ways appropr~ ate to ZIIOB. Parallel matching of KRL frame~ L5J, scripts in FRUHP and related systems i.2(jj are examples where theoretically quantized knowledge units could be experimentally distributed across processors. The actors in ~ieehan's story genera tor, amJ entities in complex social or political si~ulation ~otlels are examples where independent !Jroblem solvint al?ents could be run b;y separ11te ~rocessors. pd1~iduall wqrd experts 1n the Word ~xpert Parser L22j and 28j) are a perfect fit for ZMOB. In that theory, each word is modeled by a self-contained word expert, LISP code that interacts with other experts during the comprehen sion of ~ sejtence ~n ~Qntext. Our CSA represen tation \[21 and 20J) and its simulation system directly segment he world of causality into events and event clusters which could be parHllel ized directly into autonomous agents. In fact the whole area of causal reasoning in the physical world seems directly suited to distributed model ing. In all these cases, ZMOB could be playing the dual role of helping shape theories about ois tribution of cognitive function and of making experimentation more reasonable. Experience with the WBP and CSA systems, for example, is that interesting research has sometimes not been attempted because of our beliefs and frustrations about computational limits of the conventional machines we are using .
2·i· Robotics and Re~ Time Sensing Systems
ZMOB's real-time perfonnance and external serial and parallel channels per processor make it ideal for applications involv1ng coo~dinated and articulated control of effectors and/or synthesis pf sensory information · . As the NBS robotics lab l2] and others have foundl multiple fixed-function processors can bring soph sticated visioni sens ing, and joint control to nearly any evel of desired motor performance. In an automated shop, for example 1 where a number of tools and the1r associated v1sion and manipulator systems must run in coordination, ZMOB processors could be assigned in modular clusters that communicate both at the intra- and inter-group levels. In one module, for example, several processors would perform region wise feature extraction in parallel, feeding results to a separate scene-constructing proces sor, which then directed the team of manipulator traJeC·tory computine and joint controlline proces sors. Another processor in the cluster could scan for certain error or contingenc~ conditions, and a final processor could coord1nate its group's efforts with other group coordinators. In a large job shop, human operator stations could be tied in by other processors.
In sensing environments, ZMOB could assign processors to fixed sensor clusters in a complex environmenti such as Three Mile Island. Each pro cessor wou d contain both physical and causal models of the segment of the environment it sensed, and the relation of that environment to the site at large. Given powerful enough causal models (and the current operating context and user intent e.g., during dynamic maneuvers such as peak load power up). individual processors could intelligently coord1nate their environment with the larger environment 1 report abnormalities with annotations about probaole causes, and even take local corrective procedures, then inform superior processors of the changes. Distributed intelli gence in a complex sensor/effector system like TMI is an attractive solution to real-time critical decision makin~, and Zf·IOB seems ideally sui ted for such distribut1on. A central research topic here is to develop the common language of causality through which processors communicate. With its effective interprocessor communications bandwidth of 160 megabaud, ZMOB's potentials for distributed real-time decision making are considerably higher than even the fastest traditional networks. Also, because of the large number of proceasora, redun dancy either at the decision making or sensory level is feasible.
2·2· Management of Large Information !>paces
In· [24] we have described the concept of an I-SPACE, and an I-SPACE project in progress at Maryland. An I-SPACE is an information hub for large societal or institutional organizations wheJ;e there is a large quantity of 1nfonnation and/or e. large number of tools for manipulating that information, as well as a need to interface a wide variety of users to both the information and tools in real time. The Goddard I-SPACE is perhaps the archetype of all !-SPACEs, in that the user group is qu1te diverse {administrators, scie{ltists, . engineers, technicians, schedulers, etc.), and in that the information content of the system at.lar~e is both tremendous and highly dis tributed {sc1ence and engineering databases, real-time data acquisition systems, real-time con trol systems, Qlann~ng and admin1strative data bases, and so forth). The keys to the 1-SPACI!: con cept are uniformity in information presentH tion on high resolution TV screens, and flexibility in synthesizing inforutation in user-idiosyncratic ways from all parts of the I-SPACE for simultane ous display on his screen.
While the user interface in the Goddard l ~PA�E system is reminiscent of the PI!!: system L10J the real-time requirements of accessing and synthesizing information from remote hosts, administrators' desktop computers, real-time satellite links, and local planning databasea call for much more computational power than PIE, or, indeed, than rnost computing facilities possess. Because of this Z~lOB will play a prominent role, called the I-BAlK, in the Goddard I-SPACE. In this role, ZMOB's processors will run ded}cated, intel ligent links to the outside world l remot{l hostsi telephone links satellite linfB, etc.) tha comprise the !-~PACE. The system s VAX-based user interfaces, running frame-like packets which put out real-time control and information requests into the I-SPACJ; 1 make demands on Zf40B as a gate way t9 the outs1de, thus distributing most of the system s time-critical scheduling to Z~IOB s pro cessors. We see this type of architecture as man datory for large-scale information systems.
5.6. Distributed rresearc Databases and Formal AI
Preliminary design of a predicate logic sys tem to be implemented on ZNOB is currently in pro gress at the University of ~llry;l.aqd. Based on such foundational work as [15 1 L6J, and the set oriented extensions of l18]f t 1s system features a distributed relational atjbase and the predi cate logic language PHOLOG 30 used as an lnter face to the database for querying and other pur poses.
Initinlly, three types of processes are envision?d: the search space process which accepts the user s database query, divides it into prob lems and starts up several problem solving processes to handle them; the problem solving processes which run PROLOG and build tasks for the aatabas~ processe~; and the database processes which tinitially) handle one relation of the entire database apiece and perfonn lookup, updat ing, and unification. In the future the ab1lity to perform efficient reorganization ot the data base will be added in order to spread an overused relatiop among several processors and to grovp several relations in the same processor. ZROB s architecture allows complete freedom to effect such a reorganization while its message passing protocols allow problem solving processes to com municate by capability with data base processes, a necessity for efficient database lookup.
2·1· Heuristic Search
The problem of searching a large state space has long begged for a parallel solution. Several algorithms f9( loin~ jhl~ bave appeared in the literature l 1 , l4 , l8]J but most have not yet been implemen e on true parallel hardware. Those that have been implemented are not fS useful as they could be. For example 1 Baudet s parallel version of alpha-beta exhioit& a better than linear speed-up with two or three processors~ but improves very little with more than five. ~MOB's flexibility makes it easy to implement these algo rithms, compare their performance, and develop new methods from that experience.
2·~· Computer Vision
Some preliminary work has already been doqe in the area of image processing on ZMOB. In l23J, a vision system running on ZMOB is described which divides the 512 by 512 pixel ima~e into 32 b¥ ~2 regions, one per processor. Tim1ng simulat1ons showed that a simple 3 by 3 averaging of the entire image could be performed in about 2 fifths of a second while elabordte relaxation algorithms involving 10 labels per point could com~lete an iteration in about 100 seconds. Such tim1ng esti mates show that orders of magnitude s~edup cap bj achieved using ZMOB in the vision donaln. L16 provides further timing estimates for picture pro cessine al~orithms including image loading and unload1ne t1mee and notes that for most non trivial alr,ori thms Z~lOll effects as much as a tenf old speedup over execution on tQe host cqmputer in this case, a VAX 11/700). In f17j these results arc compared with those of possible imple mentutions on other parallel archi tecture2, in particular, switching networks.
Other Areas
In [25] the appropriateness of ZMOB for research in cellular automata is discussed, specifically addressing the problems of reconfi gurable parallel computers. Other future applica tion areas include numerical analysis, network topology and performance evaluation, and neural modeling. Finally, ZMOD could also function as a microprocessor instructional machine for students or as a message switching station for large com puter networks.
6. Summary
ZMOB is scheduled to become fully operational in late Fall 1981. As we emphasized in the intro duction, it will directly solve no theoretical AI problems. But it will, we hope, encourage deeper research into existing areas where computational limitations have traditionally posed serious bar riers, and stimulate new and more ambitious ways of thinking about AI and cognitive processes. It will, we ho~e, represent a new, important link in the design/1mplement/test feedback loop that is so important to AI.
RI<:FfiR~:liCES
- [ 1 ] Akl 1 s. G., D. T. Barnardf and R. J. Doran, Des1gn, AnalysiR, and mplementation of a Parullel Alpha-Deta Algorithm Queen's Univer sity, Technical Report 80-98, 1980.
- Albus, J. S., A. J. Barbera, M. L. Fitzgerald, R. N. Nagel, G. J. Vanderbrug, and T. g, When tley, A ~:easurement and Control Model for Adaptive Robots, in Proceedin~e of the 10th Internationul SymposiUm on I !Su"!F tffal Rotiote, 1980. - ---
- AllenA John, The TLC LISP User's Manual, Lisp ~ompany, 1980;- -------- The
- Baudet G. M., The Design and Analysis of Algorithms for Asynchronous Nicroproceesor~, Carnegie-Mellon Univerei ty CHU-CS-78-11 o, 1978.
- Bobrow, D.G. and T. Winograd 1 An Overview of KRL, a Knowledge R~fresentation Language, Cognitive Science .!_, \ } , 1977.
- Chang, C. L. and R. c. T. Lee, Sbmbolic ~g~~g and Hechanical Theorem Provi g, Aca . Press, New iork, 19/9.
- [ 7] Dude,, Hart, and llilseon, et al, Development of a Computer-Based Consultant for ~lineral I<:xploration 1 Annual Report, Stanford Research Institute, 977.
- ls] Hshburn, J. P., H. A. Finkel, and S. A. Law lees, Parallel Alpha-Beta Search on Arachne, pp. 235-243 in Proceedings of the 1980 Inter national Conference on Pa~l~ ~e~ 1 ')00. ----- -
- ~'ort;Y C. L., A Production System l·lonitor for Paraliel Computers, CMU 161, April, 1977.
- lto] Goldstein, I.P. and D.G. Bobrow, Descriptions for a Programming Environment, in Proceedings of the First Annual National Conference n ~t~c~~gence, StanfOriS, CA., Au~ 1980.
- Hewitt, C., Viewing Control Structures as
- Patterns of Passing Messages~ Artificial Intelligence~. pp. 323-364, 197t.
- Ingell's, D.H.ii., The Srr.alftalk-76 Programrrling System Design and Implementation,_ in Conference Record of the Fifth Annual A~M Symposium on PrT'iiC'1piesolPrOijF!iiiim1"iiif"'tiinguiiges, 19/8.
- Jones, A. K. and P. Schwarz, ~xRerience Using Multiprocessor Systems - A "tatue Heport, Computing Surveys~. 2, June 1980.
- Kay, A., The Reactive Bngine, Ph.D. thesis, University of Utah, 1969.
- Kowalski! R. A. 19 7~gic for Problem Solving, North-Ho land, · --
- Kushner Todd, Angela Y. Wu, and Azriel Rosenfeld, Image Processing on ZNOll, Univer sity of Maryland, TR-987, Dec. 1980.
- Kushner Todd, Parallel Using ~witching Networks Communicatio~, University {forthcoming}, March 1981. Image Processing for Interproceseor of Maryland, TR
- Minker, J., A Set-Oriented Predicate Logic Progrwnming Language, TR-922, University of lr.aryland, J980.
- [ 19] Rashid, R. F., An Inter-Process Cornn.unication Facility for UNIX, C~IU-CS-130-124, Carnegie ~lellon University, Jun. 1980.
- Rie($er, C., The Commonsense Algorithm as a Bas1s for Com.~>uter Hodels of Human Memory, Inference, llel1ef and Contextual Languase Comprehension, University of Haryland TH-375, ~:ay 1975.
- Rieger, c. and 11. Grinberg, A system for Cause-Effect Representation and Simulation in Computer-Aided Design, in Proceedings of the IFIP Workin~ Conference on Artific1al-rnteT= ~nee and attern Recognft1on 1n Computer= A1 ed De81gn, 19/8. -
- Rieger, C. and S. Small, Word Expert Parsing, PP· 723-728 in IJCAI-79, 1979.
- Rieger, C., ZMOB: A Mob of 256 Cooperative Z80A-Based Microcomputers, in Proceedings of the ARPA Vision Workshop, Los Angeles, ex; T'nrr.---
- Rieger, C. 1 R. Wood, and E. Allen, Large Human-Mach1ne Informs tion Sfacee 1 Uni v. of Maryland CS TR-102~, Mar. 198 · ~also sub mi tt'ed to IJCAI-81)
- Rosenfeld, Azriel and Angela Y. Wu, Reconfi gurable Cellular Computers, University of Maryland, TR-963, Oct. 1980.
- Schank, R. and C. Riesbeck, Inside Computer Understanding, L. Erlbaum, 1981.
- Shortliffe, E., Computer-Based Medical Con sultations - ~iYCIN, Afuerican-Elsev1er, 19~
- Small, S., Word Expert Parsing: A Theory of Distributed Word-Based Natural Language Understanding, University of ~laryland TR-954, Sept. 1980.
- [29j Trigg, Randall H., A Parallel Approach to the Interactive Design and Simulation of Mechan isms, University of Maryland, ~H-992, Dec. 1980.
- [30j Warren, D. H. D., Implementing PHOLOG: Com piling Predicate Logic Program, University of Edinburgh, Research Reports 39 & 40, 1979.
- Wa terrnan, D. and F. Hayes-Roth, An Overview of Pattern-Directed Inference Systems, in Pattern-Directed Inferenc~ Sistema, ed. Waterman a Hayes-ROth, Academ c Press, New Yodc, 1978.
@inproceedings{ijcai1981p182,
  title     = {ZMOB: A New Conputing Engine for AI},
  author    = {Rieger, Chuck and Trigg, Randall H. and Bane, Bob},
  booktitle = {Proceedings of the Seventh International Joint Conference on
               Artificial Intelligence, {IJCAI-81}},
  publisher = {International Joint Conferences on Artificial Intelligence},
  editor    = {Patrick J. Hayes},
  pages     = {955--959},
  year      = {1981},
  month     = {8},
  note      = {Hardware},
  url       = {https://ijcai.org/proceedings/1981/182},
}
TY - CPAPER TI - ZMOB: A New Conputing Engine for AI AU - Rieger, Chuck AU - Trigg, Randall H. AU - Bane, Bob T2 - Proceedings of the Seventh International Joint Conference on Artificial Intelligence, IJCAI-81 PB - International Joint Conferences on Artificial Intelligence PY - 1981 SP - 955 EP - 959 UR - https://ijcai.org/proceedings/1981/182 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





