
Unsupervised Representation Learning by Predicting Random Distances
Proceedings of the Twenty-Ninth International Joint Conference on Artificial Intelligence. Main track. Pages 2950-2956.
https://doi.org/10.24963/ijcai.2020/408
Keywords
- Data Mining: Feature Extraction, Selection and Dimensionality Reduction
- Machine Learning: Unsupervised Learning
- Machine Learning: Deep Learning
Abstract
Deep neural networks have gained great success in a broad range of tasks due to its remarkable capability to learn semantically rich features from high-dimensional data. However, they often require large-scale labelled data to successfully learn such features, which significantly hinders their adaption in unsupervised learning tasks, such as anomaly detection and clustering, and limits their applications to critical domains where obtaining massive labelled data is prohibitively expensive. To enable unsupervised learning on those domains, in this work we propose to learn features without using any labelled data by training neural networks to predict data distances in a randomly projected space. Random mapping is a theoretically proven approach to obtain approximately preserved distances. To well predict these distances, the representation learner is optimised to learn genuine class structures that are implicitly embedded in the randomly projected space. Empirical results on 19 real-world datasets show that our learned representations substantially outperform a few state-of-the-art methods for both anomaly detection and clustering tasks. Code is available at: \url{https://git.io/RDP}
- [Agrawal et al., 2015] Pulkit Agrawal, Joao Carreira, and Ji- tendra Malik. Learning to see by moving. In Proc. IEEE Int. Conf. Comp. Vis., pages 37-45, 2015.
- [Beyer et al., 1999] Kevin Beyer, Jonathan Goldstein, Raghu Ramakrishnan, and Uri Shaft. When is "nearest neighbor" meaningful? In Proc. Int. Conf. Database Theory, 1999.
- [Bingham and Mannila, 2001] Ella Bingham and Heikki Mannila. Random projection in dimensionality reduc- tion: applications to image and text data. In Proc. ACM SIGKDD Int. Conf. Know. Disco. & Data Mining, 2001.
- [Burda et al., 2019] Yuri Burda, Harrison Edwards, Amos Storkey, and Oleg Klimov. Exploration by random net- work distillation. In Proc. Int. Conf. Learn. Repre., 2019.
- [Chen et al., 2016] Xi Chen, Yan Duan, Rein Houthooft, John Schulman, Ilya Sutskever, and Pieter Abbeel. Info- gan: Interpretable representation learning by information maximizing generative adversarial nets. In Proc. Adv. Neu- ral Inf. Process. Syst., pages 2172-2180, 2016.
- [Demšar, 2006] Janez Demšar. Statistical comparisons of classifiers over multiple data sets. J. Mach. Learn. Res., 2006.
- [Doersch et al., 2015] Carl Doersch, Abhinav Gupta, and Alexei A Efros. Unsupervised visual representation learn- ing by context prediction. In Proc. IEEE Int. Conf. Comp. Vis., pages 1422-1430, 2015.
- [Donoho and Grimes, 2003] David L Donoho and Carrie Grimes. Hessian eigenmaps: Locally linear embedding techniques for high-dimensional data. Proceedings of the National Academy of Sciences, 100(10):5591-5596, 2003.
- [Gidaris et al., 2018] Spyros Gidaris, Praveer Singh, and Nikos Komodakis. Unsupervised representation learning by predicting image rotations. In Proc. Int. Conf. Learn. Repre., 2018.
- [Hartigan and Wong, 1979] John A Hartigan and Manchek A Wong. Algorithm as 136: A k-means clustering algorithm. J. Royal Stat. Society, 1979.
- [Hinton and Roweis, 2003] Geoffrey E Hinton and Sam T Roweis. Stochastic neighbor embedding. In Proc. Adv. Neural Inf. Process. Syst., pages 857-864, 2003.
- [Hinton and Salakhutdinov, 2006] Geoffrey E Hinton and Ruslan R Salakhutdinov. Reducing the dimensionality of data with neural networks. Science, 313(5786):504-507, 2006.
- [Johnson and Lindenstrauss, 1984] William B Johnson and Joram Lindenstrauss. Extensions of lipschitz mappings into a hilbert space. Contemporary Math., 1984.
- [Le and Mikolov, 2014] Quoc Le and Tomas Mikolov. Dis- tributed representations of sentences and documents. In Proc. Int. Conf. Mach. Learn., pages 1188-1196, 2014.
- [Lee et al., 2017] Hsin-Ying Lee, Jia-Bin Huang, Maneesh Singh, and Ming-Hsuan Yang. Unsupervised represen- tation learning by sorting sequences. In Proc. IEEE Int. Conf. Comp. Vis., pages 667-676, 2017.
- [Li et al., 2006] Ping Li, Trevor J Hastie, and Kenneth W Church. Very sparse random projections. In Proc. ACM SIGKDD Int. Conf. Know. Disco. & Data Mining, 2006.
- [Liu et al., 2008] Fei Tony Liu, Kai Ming Ting, and Zhi-Hua Zhou. Isolation forest. In Proc. IEEE Int. Conf. Data Min- ing, pages 413-422. IEEE, 2008.
- [Mikolov et al., 2013] Tomas Mikolov, Kai Chen, Greg Cor- rado, and Jeffrey Dean. Efficient estimation of word rep- resentations in vector space. arXiv:1301.3781, 2013.
- [Misra et al., 2016] Ishan Misra, C Lawrence Zitnick, and Martial Hebert. Shuffle and learn: unsupervised learn- ing using temporal order verification. In Proc. Eur. Conf. Comp. Vis., pages 527-544. Springer, 2016.
- [Oord et al., 2018] Aaron van den Oord, Yazhe Li, and Oriol Vinyals. Representation learning with contrastive predic- tive coding. arXiv:1807.03748, 2018.
- [Pang et al., 2018] Guansong Pang, Longbing Cao, Ling Chen, and Huan Liu. Learning representations of ultrahigh-dimensional data for random distance-based out- lier detection. In Proc. ACM SIGKDD Int. Conf. Know. Disco. & Data Mining, pages 2041-2050. ACM, 2018.
- [Pathak et al., 2016] Deepak Pathak, Philipp Krahenbuhl, Jeff Donahue, Trevor Darrell, and Alexei A Efros. Context encoders: Feature learning by inpainting. In Proc. IEEE Conf. Comp. Vis. Patt. Recogn., pages 2536-2544, 2016.
- [Radford et al., 2015] Alec Radford, Luke Metz, and Soumith Chintala. Unsupervised representation learning with deep convolutional generative adversarial networks. In Proc. Int. Conf. Learn. Repre., 2015.
- [Rahimi and Recht, 2008] Ali Rahimi and Benjamin Recht. Random features for large-scale kernel machines. In Proc. Adv. Neural Inf. Process. Syst., 2008.
- [Rahmani and Atia, 2017] Mostafa Rahmani and George Atia. Coherence pursuit: Fast, simple, and robust sub- space recovery. In Proc. Int. Conf. Mach. Learn., pages 2864-2873. JMLR. org, 2017.
- [Schölkopf et al., 1997] Bernhard Schölkopf, Alexander Smola, and Klaus-Robert Müller. Kernel principal com- ponent analysis. In Proc. Int. Conf. Arti. Neur. Net., pages 583-588. Springer, 1997.
- [Vempala, 1998] Santosh Vempala. Random projection: A new approach to VLSI layout. In Proc. Ann. Symp. Found. Comp Sci., pages 389-395. IEEE, 1998.
- [Vincent et al., 2010] Pascal Vincent, Hugo Larochelle, Is- abelle Lajoie, Yoshua Bengio, and Pierre-Antoine Man- zagol. Stacked denoising autoencoders: Learning useful representations in a deep network with a local denoising criterion. J. Mach. Learn. Res., 2010.
- [Zhou et al., 2017] Tinghui Zhou, Matthew Brown, Noah Snavely, and David G Lowe. Unsupervised learning of depth and ego-motion from video. In Proc. IEEE Conf. Comp. Vis. Patt. Recogn., pages 1851-1858, 2017.
- [Zong et al., 2018] Bo Zong, Qi Song, Martin Renqiang Min, Wei Cheng, Cristian Lumezanu, Daeki Cho, and Haifeng Chen. Deep autoencoding gaussian mixture model for unsupervised anomaly detection. In Proc. Int. Conf. Learn. Repre., 2018.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Unsupervised representation learning aims to automatically extract expressive feature representations from data without any labelled data. Due to the remarkable capability to learn semantically rich features, deep neural networks have been becoming one widely-used technique to empower a broad range of machine learning tasks. One main issue with these deep learning techniques is that a massive amount of labelled data is typically required to successfully learn these expressive features. As a result, their transformation power is largely reduced for tasks that are unsupervised in nature, such as anomaly detection and clustering. This is also true to critical domains, such as healthcare and fintech, where collecting massive labelled data is prohibitively expensive and/or is impossible to scale. To bridge this gap, in this work we explore fully unsupervised representation learning techniques to enable downstream unsupervised learning methods on those critical domains.
∗Equal contribution.
† Corresponding author.
In recent years, many unsupervised representation learning methods [Mikolov et al., 2013; Le and Mikolov, 2014; Misra et al., 2016; Lee et al., 2017; Gidaris et al., 2018] have been introduced, of which most are self-supervised approaches that formulate the problem as an annotation free pretext task. These methods explore easily accessible information, such as temporal or spatial neighbourhood, to design a surrogate supervisory signal to empower the feature learning. These methods have achieved significantly improved feature representations of text/image/video data. But they are often inapplicable to tabular data since it does not contain the required temporal or spatial supervisory information. We therefore focus on unsupervised representation learning of high-dimensional tabular data. Although many approaches, such as random projection [Li et al., 2006], manifold learning [Donoho and Grimes, 2003; Hinton and Roweis, 2003] and autoencoder [Vincent et al., 2010], are readily available for handling those data, many of them [Donoho and Grimes, 2003; Hinton and Roweis, 2003; Rahmani and Atia, 2017] are often too computationally costly to scale up to large or high-dimensional data. Approaches like random projection and autoencoder are very efficient but they often fail to capture complex class structures due to its underlying data assumption or weak supervisory signal.
In this paper, we introduce a Random Distance Prediction (RDP) model which trains neural networks to predict data distances in a randomly projected space. Particularly, as distances generally carry intrinsic class structure information in the data, the representation learner is optimised to learn the class structure to minimise the prediction error. We seek to obtain distances preserved in a projected space to be the supervisory signal because distances are concentrated and become meaningless in high dimensional spaces [Beyer et al., 1999]. Random mapping is a highly efficient yet theoretical proven approach to obtain such approximately preserved distances. Therefore, we leverage the distances in the randomly projected space to learn the desired features. Intuitively, random mapping preserves rich local proximity information but may also keep misleading proximity when its underlying data distribution assumption is inexact; by minimising the random distance prediction error, RDP essentially leverages the preserved data proximity and the power of neural networks to learn globally consistent proximity and rectify the inconsistent proximity information, resulting in a substantially better representation space than the original space. We show that this simple random distance prediction enables us to achieve expressive representations without using labelled data. In addition, some task-dependent auxiliary losses can be optionally added as a complementary supervisory source to the random distance prediction, so as to learn the feature representations that are more tailored to a specific task. In summary, we make the following three main contributions.
- We propose a random distance prediction formulation, which is very simple yet offers a highly effective supervisory signal for learning expressive feature representations that optimise the distance preserving in random projection. The learned features are sufficiently generic and work well for downstream prediction tasks.
- Our formulation is flexible to incorporate taskdependent auxiliary losses that are complementary to random distance prediction to further enhance the learned features, i.e., features that are specifically optimised for a downstream task while at the same time preserving the generic proximity as much as possible.
- As a result, we show that our instantiated model termed RDP achieves substantially better performance than state-of-the-art competing methods in two key unsupervised tasks, anomaly detection and clustering.
2 RandomDistance PredictionModel
The Proposed Formulation and The Instantiated Model We propose to learn representations by training neural networks to predict distances in a randomly projected space without manually labelled data. The key intuition is that, given some distance information that faithfully encapsulates the underlying class structure in the data, the representation learner is forced to learn the class structure in order to yield distances that are as close as the given distances. Our proposed framework is illustrated in Figure 1. Specifically, given data points xi,xj ∈ RD , we first feed them into a weightshared Siamese-style neural network f(x;Q). f : RD ↦→RM is a representation learner with the parameters Q to map the data onto a M-dimensional new space. Then we formulate the subsequent step as a distance prediction task and define a loss function as:
where h is an existing projection method and l is a function of the difference between its two inputs.
Here one key ingredient is how to obtain trustworthy distances via h. Also, to efficiently optimise the model, the distance derivation needs to be computationally efficient. In this work, we use the inner products in a randomly projected space as the source of distance/similarity since it is very efficient and there is strong theoretical support of its capacity in preserving the genuine distance information. Thus, our instantiated model RDP specifies Lrdp(xi, x j) as follows 1 :
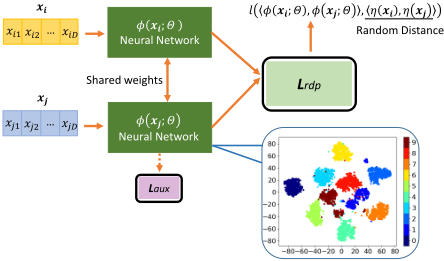
where f is implemented by multilayer perceptron for dealing with tabular data and h : RD ↦→RK is an off-the-shelf random data mapping function (see Sections 3.1 and 3.2 for detail). Despite its simplicity, this loss offers a powerful supervisory signal to learn semantically rich feature representations that substantially optimise the underlying distance preserving in h (see Section 3.3 for detail).
Flexibility to Incorporate Task-dependent Complementary Auxiliary Loss Minimising Lrdp learns to preserve pairwise distances that are critical to different learning tasks. Moreover, our formulation is flexible to incorporate a taskdependent auxiliary loss Laux, such as reconstruction loss [Hinton and Salakhutdinov, 2006] for clustering or novelty loss [Burda et al., 2019] for anomaly detection, to complement the proximity information and enhance the feature learning.
For clustering, an auxiliary reconstruction loss is used:
where f is an encoder and f ′ : RM ↦→RD is a decoder. This loss may be optionally added into RDP to better capture global feature representations.
Similarly, in anomaly detection a novelty loss may be optionally added, which is defined as:
1 Since we operate on real-valued vector space, the inner product is implemented by the dot product. The dot product is used hereafter to simplify the notation.
By using a fixed h, minimising L ad aux helps learn the frequency of underlying patterns in the data [Burda et al., 2019], which is an important complementary supervisory source for the sake of anomaly detection. As a result, anomalies or novel points are expected to have substantially larger (f(x;Q⋆ )-h(x))2 than normal points, so Eqn. (4) is used to define anomaly score for the anomaly detection task.
Note since L ad aux involves a mean squared error between two vectors, the dimension of the projected space resulted by f and h is required to be equal in this case. Therefore, when this loss is added into RDP, the M in f and K in h need to be the same. We do not have this constraint in other cases.
Overall, our loss function will then be:
where Laux is L clu aux for clustering and L ad aux for anomaly detection.
3 Theoretical Analysis of RDP
This section shows the proximity information can be well approximated using inner products in two types of random projection spaces. This is a key theoretical foundation to RDP. Also, to accurately predict these distances, RDP is forced to learn the genuine class structure in the data.
3.1 When Linear Projection Is Used
Random projection is a simple yet very effective linear feature mapping technique which has proven the capability of distance preservation. Let X ⊂ RN×D be a set of N data points, random projection uses a random matrix A ⊂ RK×D to project the data onto a lower K-dimensional space by X ′ = AX ᵀ . The Johnson-Lindenstrauss lemma [Johnson and Lindenstrauss, 1984] guarantees the data points can be mapped to a randomly selected space of suitably lower dimension with the distances between the points are approximately preserved. More specifically, let e ∈ (0, 1 2 ) and K = 20 logn e 2 . There exists a linear mapping f : RD ↦→RK such that for all xi,xj ∈X :
Furthermore, assume the entries of the matrix A are sampled independently from a Gaussian distribution N (0,1). Then, the norm of x ∈ RD can be preserved as:
Under such random projections, the norm preservation helps well preserve the inner products:
where ˆx is a normalised x such that ||ˆx|| ≤ 1.
The proofs of Eqns. (6-8) can be found in [Vempala, 1998].
Eqn. (8) states that the inner products in the randomly projected space can largely preserve the inner products in the original space, particularly when the dimension K is large.
3.2 When Non-linear Projection Is Used
Here we show that some non-linear random mapping methods are approximate to kernel functions which are a wellestablished approach to obtain reliable distance/similarity information. The key to this approach is the kernel function k : X ×X ↦→R, which is defined as k(xi, x j) = 〈y(xi),y(x j)〉, where y is a feature mapping function but needs not to be explicitly defined and 〈·, ·〉 denotes a suitable inner product. A non-linear kernel function such as polynomial or radial basis function (RBF) kernel is typically used to project linearinseparable data onto a linear-separable space.
The relation between non-linear random mapping and kernel methods is justified in [Rahimi and Recht, 2008], which shows that an explicit randomised mapping function g : RD ↦→ RK can be defined to project the data points onto a lowdimensional Euclidean inner product space such that the inner products in the projected space approximate the kernel evaluation:
Let A be the mapping matrix. Then to achieve the above approximation, A is required to be drawn from Fourier transform and shift-invariant functions such as cosine function are finally applied to Ax to yield a real-valued output. By transforming xi and xj in this manner, their inner product g(xi) · g(x j) is an unbiased estimator of k(xi, x j).
3.3 Learning Class Structure By RandomDistance Prediction
Our model using only the random distances as the supervisory signal can be formulated as:
where yi j = h(xi) · h(xj). Let Yh ∈ RN×N be the distance/similarity matrix of the N data points resulted by h. Then to minimise the prediction error in Eqn. (10), f is optimised to learn the underlying class structure embedded in Y. As shown in the properties in Eqns. (8) and (9), Yh can effectively preserve local proximity information when h is set to be either the randomprojection-based f function or the kernel method-based g function. However, those proven h is often built upon some underlying data distribution assumption, e.g., Gaussian distribution in random projection or Gaussian RBF kernel. Thus, the h-projected features can preserve misleading proximity when the distribution assumption is inexact. In this case, Yh is equivalent to the imperfect ground truth with partial noise. Then optimisation with Eqn. (10) is to leverage the power of neural networks to learn consistent local proximity information and rectify inconsistent proximity, resulting in a significantly optimised distance preserving space. The resulting space conveys substantially richer semantics than the h projected space when Yh contains sufficient genuine supervision information.
4 Experiments
This section evaluates our method through two typical unsupervised tasks: anomaly detection and clustering 2 . The nonlinear random projection is used in RDP by default throughout all our experiments.
4.1 Performance Evaluation in Anomaly Detection
Experimental Settings
Our RDP model is compared with five state-of-the-art methods, including iForest [Liu et al., 2008], autoencoder (AE) [Hinton and Salakhutdinov, 2006], REPEN [Pang et al., 2018], DAGMM [Zong et al., 2018] and RND [Burda et al., 2019]. iForest and AE are two of the most popular baselines. The other three methods learn representations specifically for anomaly detection. The RDP consists of one fully connected layer with 50 hidden units, followed by a leaky-ReLU layer 3 . It is trained using Stochastic Gradient Descent (SGD) as its optimiser for 200 epochs, with 192 samples per batch. The learning rate is fixed to 0.1.
Our RDP model uses the optional novelty loss for anomaly detection task by default. Note that the representation dimension M in the f function and the projection dimension K in the h function are set to be the same to alleviate parameter tuning. This means that M = K = 50 is used here. Similar to RND, given a data point x, its anomaly score in RDP is defined as the mean squared error between the two projections resulted by f(x;Q⋆ ) and h(x). Also, a boosting process is used to filter out 5% likely anomalies per iteration to iteratively improve the modelling of RDP. This is because the modelling is otherwise largely biased when anomalies are presented. We repeated the boosting process 30 times to obtain statistically stable results. In order to have fair comparisons, we also adapt the competing methods AE, REPEN, DAGMM and RND into ensemble methods and perform the experiments using an ensemble size of 30.
As shown in Table 1, 14 publicly available datasets taken from the literature [Liu et al., 2008; Pang et al., 2018; Zong et al., 2018], are used, which are from various domains, including network intrusion, credit card fraud detection, and disease detection. Many of the datasets contain real anomalies, including DDoS, Donors, Backdoor, Creditcard, Lung, Probe and U2R. Following [Liu et al., 2008; Pang et al., 2018; Zong et al., 2018], the rare class(es) is treated as anomalies in the other datasets to create semantically real anomalies. The Area Under Receiver Operating Characteristic Curve (AUCROC) and the Area Under Precision-Recall Curve (AUC-PR) are used as our performance metrics. The reported performance is averaged over 10 independent runs.
Comparison to the State-of-the-art Competing Methods
The AUC-ROC and AUC-PR results are respectively shown in Tables 1 and 2. RDP outperforms all the five competing methods in both of AUC-ROC and AUC-PR in at least 12 out of 14 datasets. This improvement is statistically significant at the 95% confidence level according to the two-tailed sign test [Demˇsar, 2006]. Remarkably, RDP obtains more than 10% AUC-ROC/AUC-PR improvement over the best competing method on six datasets, including Donors, Ad, Bank, Celeba, Lung and U2R. RDP can be thought as a high-level synthesis of REPEN and RND, because REPEN leverages a pairwise distance-based ranking loss to learn representations for anomaly detection while RND is built using L ad aux. In nearly all the datasets, RDP well leverages both Lrdp and L ad aux to achieve significant improvement over both REPEN and RND. In very limited cases, such as on datasets Backdoor and Census where RND performs very well while REPEN performs less effectively, RDP is slightly downgraded due to the use of Lrdp. In the opposite case, such as Probe, on which REPEN performs much better than RND, the use of L ad aux may drag down the performance of RDP a bit.
2 See an extended version at https://arxiv.org/abs/1912.12186 for the data accessing and additional results on representation learning of raw image data, computational efficiency and classification task.
3 We have also tried deeper network structures, but they worked less effectively than the shallow networks. This may be because the supervisory signal is not strong enough to support deeper networks.
| AE | REPEN | DAGMM | RND | RDP | ||
|---|---|---|---|---|---|---|
| Data DDoS Donors Backdoor Ad Apascal Bank Celeba Census Creditcard Lung Probe R8 Secom U2R | iForest 0.880 ± 0.018 0.774 ± 0.010 0.723 ± 0.029 0.687 ± 0.021 0.514 ± 0.051 0.713 ± 0.021 0.693 ± 0.014 0.599 ± 0.019 0.948 ± 0.005 0.893 ± 0.057 0.953 0.995 ± 0.001 0.841 ± 0.023 0.548 ± 0.019 0.988 ± 0.001 | 0.901 ± 0.000 0.812 ± 0.011 0.806 ± 0.007 0.703 ± 0.000 0.623 ± 0.005 0.666 ± 0.000 0.735 ± 0.002 0.602 ± 0.000 0.948 ± 0.000 ± 0.004 0.997 ± 0.000 0.835 ± 0.000 0.526 ± 0.000 0.987 ± 0.000 | 0.933 ± 0.002 0.777 ± 0.075 0.857 ± 0.001 0.853 ± 0.001 0.813 ± 0.004 0.681 ± 0.001 0.802 ± 0.002 0.542 ± 0.003 0.950 ± 0.001 0.949 ± 0.002 0.997 ± 0.000 0.910 ± 0.000 0.510 ± 0.004 0.978 ± 0.000 | 0.766 ± 0.019 0.763 ± 0.110 0.813 ± 0.035 0.500 ± 0.000 0.710 ± 0.020 0.616 ± 0.014 0.680 ± 0.067 0.502 ± 0.003 0.877 ± 0.005 0.830 ± 0.087 0.953 ± 0.008 0.760 ± 0.066 0.513 ± 0.010 0.945 ± 0.028 | 0.852 ± 0.011 0.847 ± 0.011 0.935 ± 0.002 0.812 ± 0.002 0.887 0.685 ± 0.019 0.823 0.690 ± 0.006 0.758 0.682 ± 0.029 0.860 0.661 ± 0.003 0.653 0.945 ± 0.001 0.867 ± 0.031 0.975 ± 0.000 0.883 ± 0.006 0.541 ± 0.006 0.981 ± 0.001 | 0.942 ± 0.008 0.962 ± 0.011 0.910 ± 0.021 ± 0.003 ± 0.007 ± 0.007 ± 0.006 ± 0.004 0.957 ± 0.005 0.982 ± 0.006 0.997 ± 0.000 0.902 ± 0.002 0.570 ± 0.004 0.986 ± 0.001 |
Ablation Study
This section examines the contribution of Lrdp, L ad aux and the boosting process to the performance of RDP. The experimental results in AUC-ROC are given in Table 3, where RDP\X means the RDP variant that removes the 'X' module from RDP. Similar observations can also be derived from AUC-PR results that are omitted due to page limits. In the last two columns, Org SS indicates that we directly use the distance information calculated in the original space as the supervisory signal, while SRP SS indicates that we use SRP to obtain the distances as the supervisory signal. It is clear that the full RDP model is the best performer. Using the Lrdp loss only, i.e., RDP\L ad aux, can achieve performance substantially better than, or comparably well to, the five competing methods in Table 1. This is mainly because the Lrdp loss alone can effectively force our representation learner to learn the underlying class structure on most datasets so as to minimise its prediction error. The use of L ad aux and boosting process well complement the Lrdp loss on the other datasets.
| Data | iForest | AE | REPEN | DAGMM | RND | |
|---|---|---|---|---|---|---|
| DDoS Donors Backdoor Ad Apascal Bank Celeba Census Creditcard Lung Probe R8 Secom U2R | 0.141 ± 0.020 0.124 ± 0.006 0.045 ± 0.007 0.363 ± 0.061 0.015 ± 0.002 0.293 ± 0.023 0.060 ± 0.006 0.071 ± 0.004 0.145 ± 0.031 0.379 ± 0.092 0.923 ± 0.011 0.076 ± 0.018 0.106 ± 0.007 0.180 ± 0.018 | 0.248 ± 0.001 0.138 ± 0.007 0.065 ± 0.004 0.479 ± 0.000 0.023 ± 0.001 0.264 ± 0.001 0.082 ± 0.001 0.072 ± 0.000 0.382 ± 0.004 0.565 ± 0.022 0.964 ± 0.002 0.097 ± 0.006 0.093 ± 0.000 0.230 ± 0.004 | 0.300 ± 0.012 0.120 ± 0.032 0.129 ± 0.001 0.600 ± 0.002 0.041 ± 0.001 0.276 ± 0.001 0.081 ± 0.001 0.064 ± 0.005 0.359 ± 0.014 0.429 ± 0.005 0.964 ± 0.000 0.083 ± 0.000 0.091 ± 0.001 0.116 ± 0.007 | 0.038 ± 0.000 0.070 ± 0.024 0.034 ± 0.023 0.140 ± 0.000 0.023 ± 0.009 0.150 ± 0.020 0.037 ± 0.017 0.061 ± 0.001 0.010 ± 0.012 0.042 ± 0.003 0.409 ± 0.153 0.019 ± 0.011 0.066 ± 0.002 0.025 ± 0.019 | 0.110 ± 0.015 0.201 ± 0.033 0.433 ± 0.015 0.473 ± 0.009 0.021 ± 0.005 0.258 ± 0.006 0.068 ± 0.010 0.081 ± 0.001 0.290 ± 0.012 0.381 ± 0.104 0.609 ± 0.014 0.134 ± 0.031 0.086 ± 0.002 0.096 0.217 ± 0.011 0.261 | RDP 0.301 ± 0.028 0.432 ± 0.061 0.305 ± 0.008 0.726 ± 0.007 0.042 ± 0.003 0.364 ± 0.013 0.104 ± 0.006 0.086 ± 0.001 0.363 ± 0.011 0.705 ± 0.028 0.955 ± 0.002 0.146 ± 0.017 ± 0.001 ± 0.005 |
| Decomposition | Supervision Signal | |||||
|---|---|---|---|---|---|---|
| Data | RDP | RDP\Lrdp | RDP\L ad aux | RDP\Boosting | Org SS | SRP SS |
| DDoS Donors Backdoor Ad Apascal Bank Celeba Census Creditcard Lung Probe R8 Secom U2R | 0.942 ± 0.008 0.962 ± 0.011 0.910 ± 0.021 0.887 ± 0.003 0.823 ± 0.007 0.758 ± 0.007 0.860 ± 0.006 0.653 ± 0.004 0.957 ± 0.005 0.982 ± 0.006 0.997 ± 0.000 0.902 ± 0.002 0.57 ± 0.004 0.986 ± 0.001 | 0.852 ± 0.011 0.847 ± 0.011 0.935 ± 0.002 0.812 ± 0.002 0.685 ± 0.019 0.690 ± 0.006 0.682 ± 0.029 0.661 ± 0.003 0.945 ± 0.001 0.867 ± 0.031 0.975 ± 0.000 0.883 ± 0.006 0.541 ± 0.006 0.981 ± 0.001 | 0.931 ± 0.003 0.737 ± 0.006 0.872 ± 0.012 0.718 ± 0.005 0.732 ± 0.007 0.684 ± 0.004 0.709 ± 0.005 0.626 ± 0.006 0.950 ± 0.000 0.911 ± 0.006 0.998 ± 0.000 0.867 ± 0.003 0.544 ± 0.011 0.987 ± 0.000 | 0.866 ± 0.011 0.910 ± 0.013 0.943 ± 0.002 0.818 ± 0.002 0.804 ± 0.021 0.736 ± 0.009 0.794 ± 0.017 0.661 ± 0.001 0.956 ± 0.003 0.968 ± 0.018 0.978 ± 0.001 0.895 ± 0.004 0.563 ± 0.008 0.988 ± 0.002 | 0.924 ± 0.006 0.728 ± 0.005 0.875 ± 0.002 0.696 ± 0.003 0.604 ± 0.032 0.684 ± 0.002 0.667 ± 0.033 0.636 ± 0.006 0.947 ± 0.001 0.884 ± 0.018 0.995 ± 0.000 0.830 ± 0.005 0.512 ± 0.007 0.987 ± 0.000 | 0.927 ± 0.005 0.762 ± 0.016 0.882 ± 0.010 0.740 ± 0.008 0.760 ± 0.030 0.688 ± 0.015 0.734 ± 0.027 0.560 ± 0.006 0.949 ± 0.003 0.928 ± 0.008 0.997 ± 0.001 0.904 ± 0.005 0.530 ± 0.016 0.981 ± 0.002 |
| #wins/draws/losses (RDP vs.) | 13/0/1 | 13/0/1 | 12/0/2 | 10/2/2 | 6/0/8 | |
In terms of supervisory source, RDP and SRP SS perform substantially better than Org SS on most datasets. This is because the distances in both the non-linear projection in RDP and the linear projection in SRP SS is well preserved, enabling RDP to effectively learn much more faithful class structure than that working on the original space.
4.2 Performance Evaluation in Clustering Experimental Settings
For clustering, RDP is compared with four state-of-the-art unsupervised representation learning methods in four different areas, including HLLE [Donoho and Grimes, 2003] in manifold learning, Sparse Random Projection (SRP) [Li et al., 2006] in random projection, autoencoder (AE) [Hinton and Salakhutdinov, 2006] in data reconstruction-based neural network methods and Coherence Pursuit (COP) [Rahmani and Atia, 2017] in robust PCA. These representation learning methods are first used to yield the new representations, and K-means [Hartigan and Wong, 1979] is then applied to the representations to perform clustering. In this section RDP adds the reconstruction loss L clu aux by default.
RDP uses a similar network architecture and optimisation settings as the one used in anomaly detection. Compared to anomaly detection, more semantic information is required for clustering algorithms to work well, so the network consists of 1,024 hidden units and is trained for 1,000 epochs. AE is built and trained with the same settings as RDP. Similar to anomaly detection, M = K is also used in clustering.
As shown in Table 4, five high-dimensional real-world datasets are used. Some of the datasets are image/text data. Since here we focus on the performance on tabular data, they are converted into tabular data using simple methods, i.e., by treating each pixel as a feature unit for image data or using bag-of-words representation for text data. Two widelyused clustering performance metrics, Normalised Mutual Info (NMI) score and F-score, are used. Larger NMI/F-score indicates better performance. The performance in the original feature space, denoted as Org, is used as a baseline. The reported NMI score and F-score are averaged over 30 times to address the randomisation issue in K-means clustering.
Comparison to the State-of-the-art Competing Methods
Table 4 shows the NMI and F-score performance of K-means
clustering. Our method RDP enables K-means to achieve the best performance on three datasets and ranks second in the other two datasets. RDP-enabled clustering performs substantially and consistently better than that based on AE in terms of both NMI and F-score. This demonstrates that the random distance loss enables RDP to effectively capture some class structure in the data which cannot be captured by using the reconstruction loss. RDP also consistently outperforms the random projection method, SRP, and the robust PCA method, COP. It is interesting that K-means clustering performs best in the original space on Sector. This may be due to that this data contains many relevant features, resulting in no obvious curse of dimensionality issue. Olivetti may contain complex manifolds which require extensive neighbourhood information to find them, so only HLLE can achieve this goal in such cases. Nevertheless, RDP performs much more stably than HLLE across the five datasets.
| Data Characteristics | NMI Performance | |||||||
|---|---|---|---|---|---|---|---|---|
| Data | N D | Org | HLLE | SRP | AE | COP | RDP | |
| R8 | 7,674 | 17,387 | 0.524 ± 0.047 | 0.004 ± 0.001 | 0.459 ± 0.031 | 0.471 ± 0.043 | 0.025 ± 0.003 | 0.539 ± 0.040 |
| 20news | 18,846 | 130,107 | 0.080 ± 0.004 | 0.017 ± 0.000 | 0.075 ± 0.002 | 0.075 ± 0.006 | 0.027 ± 0.040 | 0.084 ± 0.005 |
| Olivetti | 400 | 4,096 | 0.778 ± 0.014 | 0.841 ± 0.011 | 0.774 ± 0.011 | 0.782 ± 0.010 | 0.333 ± 0.018 | 0.805 ± 0.012 |
| Sector | 9,619 | 55,197 | 0.336 ± 0.008 | 0.122 ± 0.004 | 0.273 ± 0.011 | 0.253 ± 0.010 | 0.129 ± 0.014 | 0.305 ± 0.007 |
| RCV1 | 20,242 | 47,236 | 0.154 ± 0.000 | 0.006 ± 0.000 | 0.134 ± 0.024 | 0.146 ± 0.010 | N/A | 0.165 ± 0.000 |
| Data Characteristics | F-score Performance | |||||||
| Data | N D | Org | HLLE | SRP | AE | COP | RDP | |
| R8 | 7,674 | 17,387 | 0.185 ± 0.189 | 0.085 ± 0.000 | 0.317 ± 0.045 | 0.312 ± 0.068 | 0.088 ± 0.002 | 0.360 ± 0.055 |
| 20news | 18,846 | 130,107 | 0.116 ± 0.006 | 0.007 ± 0.000 | 0.109 ± 0.006 | 0.083 ± 0.010 | 0.009 ± 0.004 | 0.119 ± 0.006 |
| Olivetti | 400 | 4,096 | 0.590 ± 0.029 | 0.684 ± 0.024 | 0.579 ± 0.022 | 0.602 ± 0.023 | 0.117 ± 0.011 | 0.638 ± 0.026 |
| Sector | 9,619 | 55,197 | 0.208 ± 0.008 | 0.062 ± 0.001 | 0.187 ± 0.009 | 0.184 ± 0.010 | 0.041 ± 0.004 | 0.191 ± 0.007 |
| RCV1 | 20,242 | 47,236 | 0.519 ± 0.000 | 0.342 ± 0.000 | 0.508 ± 0.003 | 0.514 ± 0.057 | N/A | 0.572 ± 0.003 |
Ablation Study
Similar to anomaly detection, this section examines the contribution of the two loss functions Lrdp and L clu aux to the performance of RDP, as well as the impact of different supervisory sources on the performance. The F-score results of this experiment are shown in Table 5, in which the notations have exactly the same meaning as in Table 3. Similar NMI results can also be observed but omitted due to page limits. The full RDP model that uses both Lrdp and L clu aux performs more favourably than its two variants, RDP\Lrdp and RDP\L clu aux , but it is clear that using Lrdp only performs very comparably to the full RDP. However, using L clu aux only may result in large performance drops in some datasets, such as R8, 20news and Olivetti. This indicates Lrdp is a more important loss function to the overall performance of the full RDP model. In terms of supervisory source, distances obtained by the non-linear random projection in RDP are much more effective than the two other sources on some datasets such as Olivetti and RCV1. Three different supervisory sources are very comparable on the other three datasets.
| Decomposition | Supervision Signal | ||||
|---|---|---|---|---|---|
| Data | RDP | RDP\Lrdp | RDP\L clu aux | Org SS | SRP SS |
| R8 | 0.360 ± 0.055 | 0.312 ± 0.068 | 0.330 ± 0.052 | 0.359 ± 0.028 | 0.363 ± 0.046 |
| 20news | 0.119 ± 0.006 | 0.083 ± 0.010 | 0.117 ± 0.005 | 0.111 ± 0.005 | 0.111 ± 0.007 |
| Olivetti | 0.638 ± 0.026 | 0.602 ± 0.023 | 0.597 ± 0.019 | 0.610 ± 0.022 | 0.601 ± 0.023 |
| Sector | 0.191 ± 0.007 | 0.184 ± 0.010 | 0.217 ± 0.007 | 0.181 ± 0.007 | 0.186 ± 0.009 |
| RCV1 | 0.572 ± 0.003 | 0.514 ± 0.057 | 0.526 ± 0.011 | 0.523 ± 0.003 | 0.532 ± 0.001 |
4.3 Sensitivity w.r.t. the Dimensionality of Representation Space
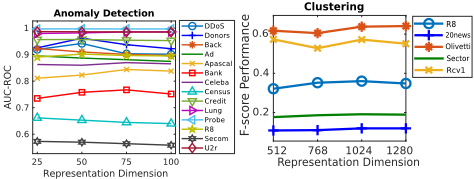
Figure 2 shows the AUC-ROC and F-score performance of RDP w.r.t. different representation dimensions in respective anomaly detection and clustering tasks. The results show RDP performs very stably w.r.t. the representation dimensionality on different datasets and downstream learning tasks. It is interesting to note that, the flat trends also indicate, as an unsupervised learning source, the random distance cannot provide sufficient supervision information to learn richer and more complex representations in a higher-dimensional space. This also explains the performance on a few datasets where the performance of RDP decreases when increasing the representation dimension. In general, the representation dimension 50 and 1024 are recommended for RDP to achieve effective anomaly detection and clustering respectively on datasets.
5 RelatedWork
Self-supervised Learning. Self-supervised learning has been recently emerging as one of the most popular and effective approaches for representation learning, especially in the scenarios where only a very limited amount of manually labelled data is available. Many of the self-supervised methods learn high-level representations by predicting some sort of 'context' information, such as spatial or temporal neighbourhood information. For example, the popular distributed representation learning techniques in NLP, such as CBOW/skipgram [Mikolov et al., 2013] and phrase/sentence embeddings in [Le and Mikolov, 2014] , learn the representations by predicting the text pieces (e.g., words/phrases/sentences) using its surrounding pieces as the context. In image processing, the pretext task can be the prediction of a patch of missing pixels [Pathak et al., 2016] or the relative position of two patches [Doersch et al., 2015]. Also, a number of studies [Misra et al., 2016; Lee et al., 2017; Oord et al., 2018] explore temporal contexts to learn representations from video data, e.g., by learning the temporal order of sequential frames. Some other methods [Agrawal et al., 2015; Zhou et al., 2017; Gidaris et al., 2018] are built upon a discriminative framework which aims at discriminating the images before and after some transformation, e.g., ego motion in video data [Agrawal et al., 2015; Zhou et al., 2017] and rotation of images [Gidaris et al., 2018]. There have also been popular to use generative adversarial networks (GANs) to learn features [Radford et al., 2015; Chen et al., 2016]. The above methods have demonstrated powerful capability to learn semantic representations. However, most of them use the supervisory signals available in image/video data only, which limits their application to other types of data, such as tabular data. Though our method may also work on image/video data, we focus on handling high-dimensional tabular data to bridge this gap.
Other Approaches. There have been several wellestablished unsupervised representation learning approaches for handling tabular data, such as random projection [Bingham and Mannila, 2001; Li et al., 2006], PCA [Sch¨olkopf et al., 1997; Rahmani and Atia, 2017], manifold learning [Donoho and Grimes, 2003; Hinton and Roweis, 2003] and autoencoder [Hinton and Salakhutdinov, 2006; Vincent et al., 2010]. One notorious issue of PCA or manifold learning approaches is their prohibitive computational cost in dealing with large-scale high-dimensional data due to the costly neighbourhood search and/or eigen decomposition. Random projection is a computationally efficient approach, supported by proven distance preservation theories such as the JohnsonLindenstrauss lemma [Johnson and Lindenstrauss, 1984]. We show that the preserved distances by random projection can be harvested to effectively supervise the representation learning. Autoencoder networks are another widely-used efficient feature learning approach which learns low-dimensional representations by minimising reconstruction errors. One main issue with autoencoders is that they focus on preserving global information only, which may result in loss of local structure information. Some feature learning methods are specifically designed for anomaly detection [Pang et al., 2018; Zong et al., 2018; Burda et al., 2019]. By contrast, we aim at generic representations learning while being flexible to incorporate optionally task-dependent losses to learn task-specific semantically rich representations.
6 Conclusion
We have introduced a novel Random Distance Prediction (RDP) model which learns features in a fully unsupervised fashion by predicting data distances in a randomly projected space. The key insight is that random mapping is a theoretically proven approach to obtain approximately preserved distances, and to well predict these random distances, the representation learner is optimised to learn preserved proximity information while at the same time rectifying inconsistent proximity, resulting in representations with optimised distance preserving. Our idea is justified by thorough experiments in two unsupervised tasks, anomaly detection and clustering, demonstrating that RDP-based anomaly detectors and clustering substantially outperform their counterparts on real-world datasets. Our empirical results also demonstrate that RDP is flexible and very effective to incorporate taskdependent complementary auxiliary losses and learns more expressive representations. We are extending RDP to other types of data, such as image/text data.
@inproceedings{ijcai2020p408,
  title     = {Unsupervised Representation Learning by Predicting Random Distances},
  author    = {Wang, Hu and Pang, Guansong and Shen, Chunhua and Ma, Congbo},
  booktitle = {Proceedings of the Twenty-Ninth International Joint Conference on
               Artificial Intelligence, {IJCAI-20}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Christian Bessiere},
  pages     = {2950--2956},
  year      = {2020},
  month     = {7},
  note      = {Main track},
  doi       = {10.24963/ijcai.2020/408},
  url       = {https://doi.org/10.24963/ijcai.2020/408},
}
TY - CPAPER TI - Unsupervised Representation Learning by Predicting Random Distances AU - Wang, Hu AU - Pang, Guansong AU - Shen, Chunhua AU - Ma, Congbo T2 - Proceedings of the Twenty-Ninth International Joint Conference on Artificial Intelligence, IJCAI-20 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2020 SP - 2950 EP - 2956 DO - 10.24963/ijcai.2020/408 UR - https://doi.org/10.24963/ijcai.2020/408 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





